Contains actual Databricks Certified Data Engineer Professional ExamDatabricks-Certified-Data-Engineer-Professional Databricks Certified Data Engineer Professional Exam questions to facilitate preparation

If you are planning to pass the Databricks-Certified-Data-Engineer-Professional exam, you can choose our Databricks-Certified-Data-Engineer-Professional practice materials as your learning material since our products are known as the most valid exam engine in the world, which will definitely be beneficial to your preparation for exams. There are many impressive advantages of our Databricks-Certified-Data-Engineer-Professional Study Guide. And our Databricks-Certified-Data-Engineer-Professional actual exam will be definitely conducive to realizing the dream of obtaining the certificate.
| Section | Weight | Objectives |
|---|
| Databricks Lakehouse Platform | 24% | - Lakehouse Architecture
- Delta Lake
- Data Management
- Unity Catalog
|
| Data Processing | 28% | - ETL Pipelines
- Spark SQL
- Data Transformation
- Structured Streaming
|
| Data Modeling and Storage | 20% | - Storage Optimization
- File Formats
- Data Modeling
|
| Monitoring and Troubleshooting | 16% | - Performance Optimization
- Troubleshooting
- Monitoring
|
| Data Quality and Governance | 12% | - Data Quality
- Data Lineage
- Governance
|
>> Valid Databricks-Certified-Data-Engineer-Professional Torrent <<
Test Databricks-Certified-Data-Engineer-Professional Engine Version, Databricks-Certified-Data-Engineer-Professional Reliable Test Duration
ValidBraindumps makes your Databricks-Certified-Data-Engineer-Professional exam preparation easy with it various quality features. Our Databricks-Certified-Data-Engineer-Professional exam braindumps come with 100% passing and refund guarantee. ValidBraindumps is dedicated to your accomplishment, hence assures you successful in Databricks-Certified-Data-Engineer-Professional Certification exam on the first try. If for any reason, a candidate fails in Databricks-Certified-Data-Engineer-Professional exam then he will be refunded his money after the refund process. Also, we offer one year free updates to our Databricks-Certified-Data-Engineer-Professional Exam esteemed user, these updates are applicable to your account right from the date of purchase. 24/7 customer support is favorable to candidates who can email us if they find any ambiguity in the Databricks-Certified-Data-Engineer-Professional exam dumps, our support will merely reply to your all Databricks Certified Data Engineer Professional Exam exam product related queries.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q239-Q244):
NEW QUESTION # 239
A junior data engineer on your team has implemented the following code block.
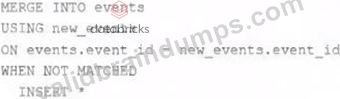
The view new_events contains a batch of records with the same schema as the events Delta table. The event_id field serves as a unique key for this table.
When this query is executed, what will happen with new records that have the same event_id as an existing record?
- A. They are ignored.
- B. They are deleted.
- C. They are updated.
- D. They are merged.
- E. They are inserted.
Answer: A
Explanation:
This is the correct answer because it describes what will happen with new records that have the same event_id as an existing record when the query is executed. The query uses the INSERT INTO command to append new records from the view new_events to the table events. However, the INSERT INTO command does not check for duplicate values in the primary key column (event_id) and does not perform any update or delete operations on existing records. Therefore, if there are new records that have the same event_id as an existing record, they will be ignored and not inserted into the table events.
NEW QUESTION # 240
Which statement describes the correct use of pyspark.sql.functions.broadcast?
- A. It caches a copy of the indicated table on all nodes in the cluster for use in all future queries during the cluster lifetime.
- B. It caches a copy of the indicated table on attached storage volumes for all active clusters within a Databricks workspace.
- C. It marks a DataFrame as small enough to store in memory on all executors, allowing a broadcast join.
- D. It marks a column as small enough to store in memory on all executors, allowing a broadcast join.
- E. It marks a column as having low enough cardinality to properly map distinct values to available partitions, allowing a broadcast join.
Answer: C
Explanation:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
NEW QUESTION # 241
A data engineering team uses Databricks Lakehouse Monitoring to track the percent_null metric for a critical column in their Delta table.
The profile metrics table (prod_catalog.prod_schema.customer_data_profile_metrics) stores hourly percent_null values.
The team wants to:
Trigger an alert when the daily average of percent_null exceeds 5% for
three consecutive days.
Ensure that notifications are not spammed during sustained issues.
- A. SELECT percent_null
FROM prod_catalog.prod_schema.customer_data_profile_metrics
WHERE window.end >= CURRENT_TIMESTAMP - INTERVAL '1' DAY
Alert Condition: percent_null > 5
Notification Frequency: At most every 24 hours - B. SELECT SUM(CASE WHEN percent_null > 5 THEN 1 ELSE 0 END) AS violation_days FROM prod_catalog.prod_schema.customer_data_profile_metrics WHERE window.end >= CURRENT_TIMESTAMP - INTERVAL '3' DAY Alert Condition: violation_days >= 3 Notification Frequency: Just once
- C. WITH daily_avg AS (
SELECT DATE_TRUNC('DAY', window.end) AS day,
AVG(percent_null) AS avg_null
FROM prod_catalog.prod_schema.customer_data_profile_metrics
GROUP BY DATE_TRUNC('DAY', window.end)
)
SELECT day, avg_null
FROM daily_avg
ORDER BY day DESC
LIMIT 3
Alert Condition: ALL avg_null > 5 for the latest 3 rows
Notification Frequency: Just once - D. SELECT AVG(percent_null) AS daily_avg
FROM prod_catalog.prod_schema.customer_data_profile_metrics
WHERE window.end >= CURRENT_TIMESTAMP - INTERVAL '3' DAY
Alert Condition: daily_avg > 5
Notification Frequency: Each time alert is evaluated
Answer: C
Explanation:
The key requirement is to detect when the daily average of percent_null is greater than 5% for three consecutive days.
Option A only checks the last 24 hours, not consecutive days. It would trigger too frequently and cause spam.
Option C calculates an average across all records in the last 3 days, but this could be skewed by one high or low day -- it does not ensure consecutive daily violations.
Option D simply counts days where the threshold was exceeded, but it does not guarantee that those days were consecutive. This could incorrectly trigger on non-adjacent violations.
Option B is correct:
It aggregates hourly values into daily averages.
It checks that the last 3 consecutive days all had averages above 5%.
It avoids redundant alerts by using Notification Frequency: Just once.
This matches Databricks Lakehouse Monitoring best practices, where SQL alerts should be designed to aggregate metrics to the correct granularity (daily here) and ensure consecutive threshold violations before triggering.
NEW QUESTION # 242
Which statement describes Delta Lake Auto Compaction?
- A. Optimized writes use logical partitions instead of directory partitions; because partition boundaries are only represented in metadata, fewer small files are written.
- B. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 128 MB.
- C. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 1 GB.
- D. Before a Jobs cluster terminates, optimize is executed on all tables modified during the most recent job.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from - E. Data is queued in a messaging bus instead of committing data directly to memory; all data is committed from the messaging bus in one batch once the job is complete.
Answer: B
Explanation:
This is the correct answer because it describes the behavior of Delta Lake Auto Compaction, which is a feature that automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones. Auto Compaction runs as an asynchronous job after a write to a table has succeeded and checks if files within a partition can be further compacted. If yes, it runs an optimize job with a default target file size of 128 MB. Auto Compaction only compacts files that have not been compacted previously.
NEW QUESTION # 243
A data engineer is using the AUTO CDC API in Lakeflow Spark Declarative Pipeline to propagate deletions from a source table (orders_source) to a target table (orders_target). The source has Change Data Feed (CDF) enabled, but some delete events arrive out of order due to upstream delays. How does the AUTO CDC API internally ensure deletions are applied correctly despite out-of-order events?
- A. It manually sorts incoming events by timestamp before applying changes.
- B. It ignores deletions if they arrive after updates for the same key.
- C. It runs VACUUM on the target table to purge conflicting records.
- D. It uses sequence_by to order events and retains tombstones for deleted rows until older sequences are processed.
Answer: D
Explanation:
AUTO CDC uses the sequence_by column to deterministically order change events for each key.
Delete operations create tombstones that are retained until all earlier sequence values have been processed, ensuring that out-of-order delete events are still applied correctly and consistently in the target table.
NEW QUESTION # 244
......
In order to meet the time requirement of our customers, our experts carefully designed our Databricks-Certified-Data-Engineer-Professional test torrent to help customers pass the exam in a lot less time. If you purchase our Databricks-Certified-Data-Engineer-Professional guide torrent, we can make sure that you just need to spend twenty to thirty hours on preparing for your exam before you take the exam, it will be very easy for you to save your time and energy. So do not hesitate and buy our Databricks-Certified-Data-Engineer-Professional study torrent, we believe it will give you a surprise, and it will not be a dream for you to pass your Databricks Certified Data Engineer Professional Exam exam and get your certification in the shortest time.
Test Databricks-Certified-Data-Engineer-Professional Engine Version: https://www.validbraindumps.com/Databricks-Certified-Data-Engineer-Professional-exam-prep.html
- Free PDF 2026 Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Useful Valid Torrent 🕌 Search on [ www.torrentvce.com ] for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ to obtain exam materials for free download 🩳Reliable Databricks-Certified-Data-Engineer-Professional Braindumps Ppt
- Pass Guaranteed 2026 Databricks Databricks-Certified-Data-Engineer-Professional: Pass-Sure Valid Databricks Certified Data Engineer Professional Exam Torrent 🕡 Search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ and download it for free immediately on ➡ www.pdfvce.com ️⬅️ 💫Databricks-Certified-Data-Engineer-Professional Free Pdf Guide
- Databricks-Certified-Data-Engineer-Professional Pass-Sure Dumps - Databricks-Certified-Data-Engineer-Professional Exam Dumps - Databricks-Certified-Data-Engineer-Professional Exam Simulator ❇ Go to website ➠ www.testkingpass.com 🠰 open and search for ▶ Databricks-Certified-Data-Engineer-Professional ◀ to download for free 🗾Databricks-Certified-Data-Engineer-Professional Latest Exam Pass4sure
- Databricks-Certified-Data-Engineer-Professional Exam Tests 🤐 Databricks-Certified-Data-Engineer-Professional Valid Test Objectives 🗺 Databricks-Certified-Data-Engineer-Professional Reliable Exam Preparation 🌽 Search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ and download it for free immediately on ➽ www.pdfvce.com 🢪 🍐Valid Databricks-Certified-Data-Engineer-Professional Test Question
- Databricks-Certified-Data-Engineer-Professional Exam Tests 🥇 New Soft Databricks-Certified-Data-Engineer-Professional Simulations 🙅 Databricks-Certified-Data-Engineer-Professional Latest Exam Pass4sure 📌 Download ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ for free by simply searching on 「 www.troytecdumps.com 」 🐀Databricks-Certified-Data-Engineer-Professional Valid Test Objectives
- Free PDF 2026 Databricks Databricks-Certified-Data-Engineer-Professional Marvelous Valid Torrent 🚺 Open ⇛ www.pdfvce.com ⇚ enter ( Databricks-Certified-Data-Engineer-Professional ) and obtain a free download 🕐Exam Dumps Databricks-Certified-Data-Engineer-Professional Pdf
- 2026 Databricks High Hit-Rate Valid Databricks-Certified-Data-Engineer-Professional Torrent 🐔 Search on ☀ www.pass4test.com ️☀️ for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 to obtain exam materials for free download 🪔Databricks-Certified-Data-Engineer-Professional Valid Exam Simulator
- 2026 Valid Databricks-Certified-Data-Engineer-Professional Torrent - Trustable Databricks Databricks Certified Data Engineer Professional Exam - Test Databricks-Certified-Data-Engineer-Professional Engine Version ♣ Enter ⏩ www.pdfvce.com ⏪ and search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ to download for free 📱Databricks-Certified-Data-Engineer-Professional New Dumps
- Valid Databricks-Certified-Data-Engineer-Professional exam dumps ensure you a high Databricks-Certified-Data-Engineer-Professional passing rate 🌘 Open ➥ www.troytecdumps.com 🡄 and search for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 to download exam materials for free 🥵Databricks-Certified-Data-Engineer-Professional Exam Tests
- Pass Guaranteed 2026 Databricks Databricks-Certified-Data-Engineer-Professional: Pass-Sure Valid Databricks Certified Data Engineer Professional Exam Torrent 🌤 Open website 「 www.pdfvce.com 」 and search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ for free download 🌞Databricks-Certified-Data-Engineer-Professional Reliable Exam Preparation
- 2026 Databricks High Hit-Rate Valid Databricks-Certified-Data-Engineer-Professional Torrent 🧃 Download ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ for free by simply searching on ➠ www.prepawaypdf.com 🠰 🕠Databricks-Certified-Data-Engineer-Professional Related Certifications
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes