What's more, part of that VCEEngine DP-100 dumps now are free: https://drive.google.com/open?id=1TnRNmdaRFQlAri6PEvs2_orvRCodkbf7
The Microsoft DP-100 dumps pdf formats are specially created for candidates having less time and a vast syllabus to cover. It has various crucial features that you will find necessary for your Designing and Implementing a Data Science Solution on Azure (DP-100) exam preparation. Each DP-100 practice test questions format supports a different kind of study tempo and you will find each DP-100 exam dumps format useful in various ways.
Languages: English, Japanese, Chinese (Simplified), Korean
Retirement date: none
This exam measures your ability to accomplish the following technical tasks: manage Azure resources for machine learning; run experiments and train models; deploy and operationalize machine learning solutions; and implement responsible machine learning.
We have seen that candidates who study with outdated DP-100 practice material don't get success and lose their resources. To save you from loss of money and time, BrainDumpsStore is offering a product that is specially designed to help you pass the Designing and Implementing a Data Science Solution on Azure (DP-100) exam on the first try. The Microsoft DP-100 Exam Dumps is easy to use and very easy to understand, ensuring that it is student-oriented. You can choose from 3 different formats available according to your needs. The 3 formats are desktop DP-100 practice test software, web-based DP-100 practice exam, and DP-100 dumps PDF format.
To nail DP-100, you will need to scrutinize the below-mentioned areas:
This objective imparts updated understanding about the concepts like creating models by using Azure ML Designer, custom code modules in Designer, defining a pipeline data flow, and an experiment running by using Azure Machine Learning SDK.
Using automated ML for the optimal model creation, hyperdrive to tune hyperparameters, model management, and knowing the crucial model explainers to interpret models are some of the key topics explained in this portion.
The first domain gives considerable attention to skills related to the Azure ML workspace. So, the test-takers have a chance to learn about workspace settings, the management of workspace using Azure ML, and registering in addition to maintaining the datastores.
The last segment is all about deployment and consumption models. Topics like evaluating compute options, creating production compute targets, batch inferencing pipeline creation, and running this pipeline efficiently are well covered within such a scope.
To prepare for the DP-100 Exam, candidates can take instructor-led training courses, self-paced online courses, and practice tests. Microsoft offers several training courses that cover the exam objectives, including "Designing and Implementing a Data Science Solution on Azure" and "Implementing an Azure Data Solution." Candidates can also access online resources such as Microsoft documentation and GitHub repositories to learn about Azure technologies and data science concepts.
NEW QUESTION # 433
You plan to implement a two-step pipeline by using the Azure Machine Learning SDK for Python.
The pipeline will pass temporary data from the first step to the second step.
You need to identify the class and the corresponding method that should be used in the second step to access temporary data generated by the first step in the pipeline.
Which class and method should you identify? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point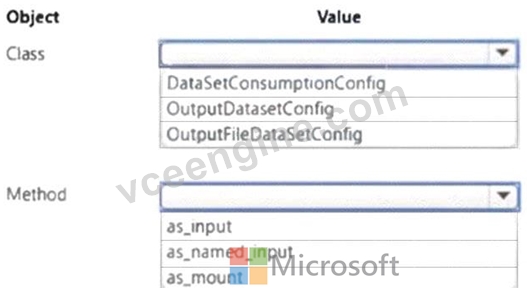
Answer:
Explanation: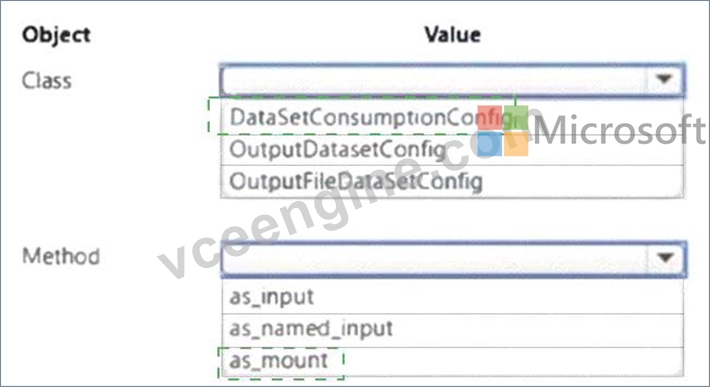
Explanation: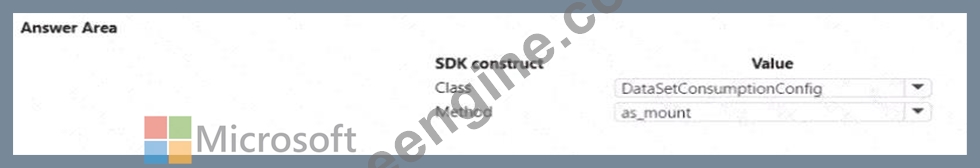
NEW QUESTION # 434 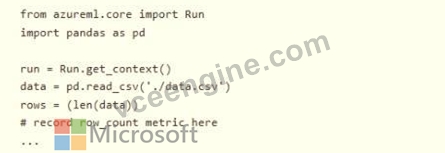
You need to record the row count as a metric named row_count that can be returned using the get_metrics method of the Run object after the experiment run completes. Which code should you use?
Answer: B
Explanation:
Log a numerical or string value to the run with the given name using log(name, value, description=''). Logging a metric to a run causes that metric to be stored in the run record in the experiment. You can log the same metric multiple times within a run, the result being considered a vector of that metric.
Example: run.log("accuracy", 0.95)
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-core/azureml.core.run
NEW QUESTION # 435
You need to configure the Feature Based Feature Selection module based on the experiment requirements and datasets.
How should you configure the module properties? To answer, select the appropriate options in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.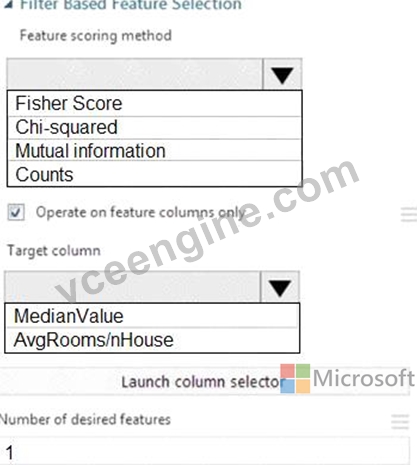
Answer:
Explanation: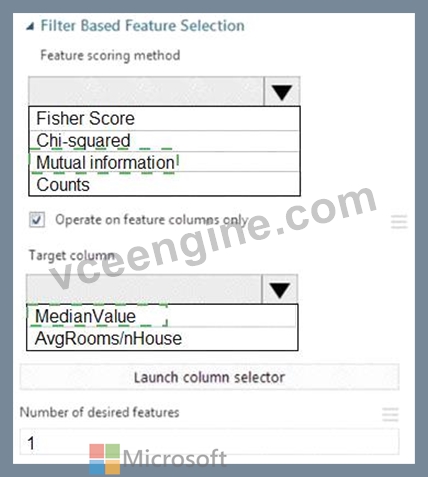
Explanation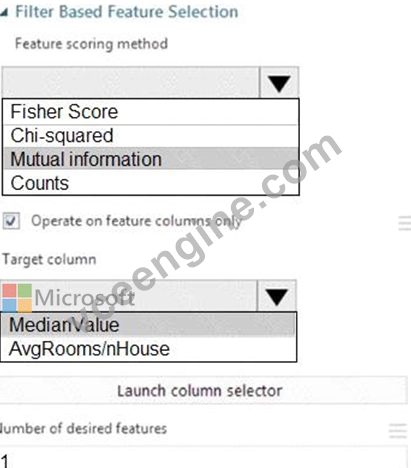
Box 1: Mutual Information.
The mutual information score is particularly useful in feature selection because it maximizes the mutual information between the joint distribution and target variables in datasets with many dimensions.
Box 2: MedianValue
MedianValue is the feature column, , it is the predictor of the dataset.
Scenario: The MedianValue and AvgRoomsinHouse columns both hold data in numeric format. You need to select a feature selection algorithm to analyze the relationship between the two columns in more detail.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/filter-based-feature-selection
NEW QUESTION # 436
You manage an Azure Machine Learning workspace That has an Azure Machine Learning datastore.
Data must be loaded from the following sources:
* a credential-less Azure Blob Storage
* an Azure Data Lake Storage (ADLS) Gen 2 which is not a credential-less datastore You need to define the authentication mechanisms to access data in the Azure Machine Learning datastore.
Which data access mechanism should you use? To answer, move the appropriate data access mechanisms to the correct storage types. You may use each data access mechanism once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.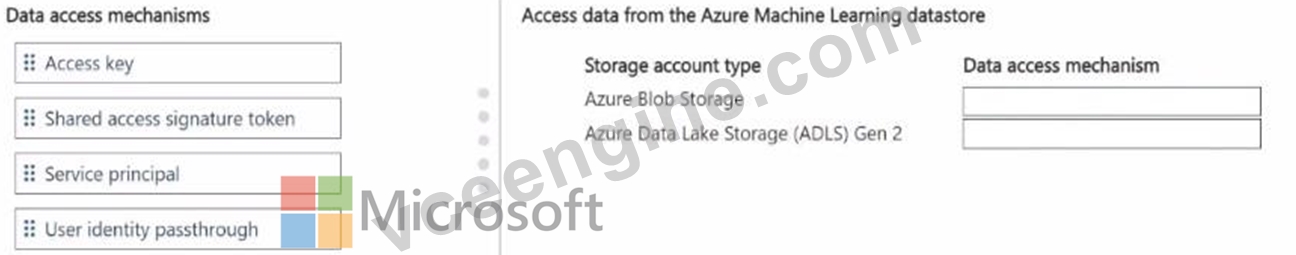
Answer:
Explanation: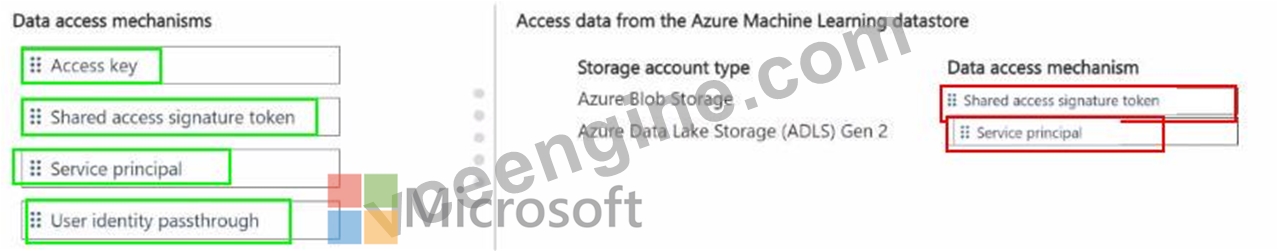
NEW QUESTION # 437
An organization uses Azure Machine Learning service and wants to expand their use of machine learning.
You have the following compute environments. The organization does not want to create another compute environment.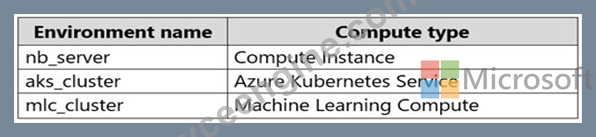
You need to determine which compute environment to use for the following scenarios.
Which compute types should you use? To answer, drag the appropriate compute environments to the correct scenarios. Each compute environment may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.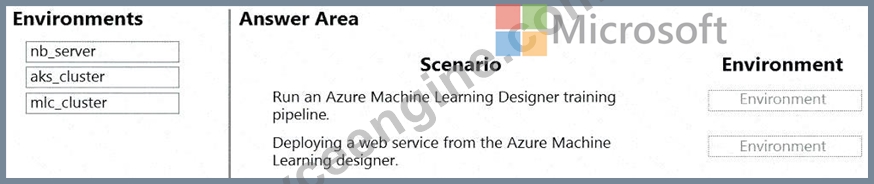
Answer:
Explanation: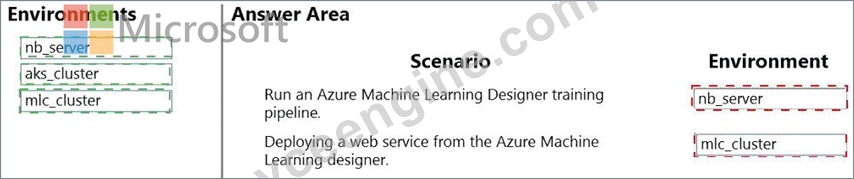
Explanation: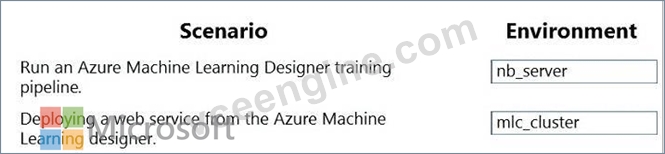
Box 1: nb_server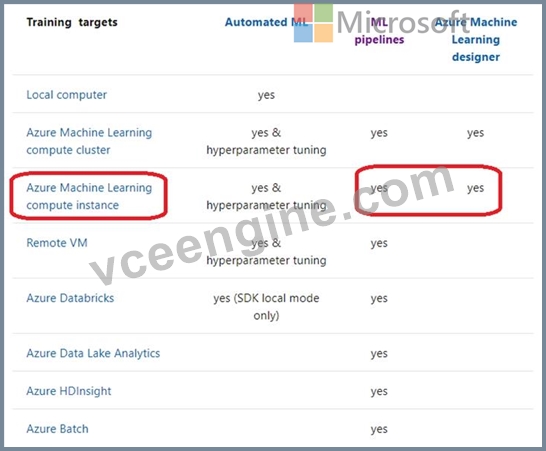
Box 2: mlc_cluster
With Azure Machine Learning, you can train your model on a variety of resources or environments, collectively referred to as compute targets. A compute target can be a local machine or a cloud resource, such as an Azure Machine Learning Compute, Azure HDInsight or a remote virtual machine.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/concept-compute-target
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-set-up-training-targets
NEW QUESTION # 438
......
Exam DP-100 Demo: https://www.vceengine.com/DP-100-vce-test-engine.html
DOWNLOAD the newest VCEEngine DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1TnRNmdaRFQlAri6PEvs2_orvRCodkbf7