DOWNLOAD the newest FreeDumps MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1LfVSvsWTyeWuuStikr61q8wHFMhd_nhi
We know making progress and getting the certificate of MLA-C01 study materials will be a matter of course with the most professional experts in command of the newest and the most accurate knowledge in it. Our AWS Certified Machine Learning Engineer - Associate exam prep has taken up a large part of market. with decided quality to judge from customers' perspective, If you choose the right MLA-C01 Practice Braindumps, it will be a wise decision. Our behavior has been strictly ethical and responsible to you, which is trust worthy.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
We offer three different formats for preparing for the Amazon MLA-C01 exam questions, all of which will ensure your definite success on your AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam dumps. FreeDumps is there with updated MLA-C01 Questions so you can pass the AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam and move toward the new era of technology with full ease and confidence.
NEW QUESTION # 51
A financial company receives a high volume of real-time market data streams from an external provider. The streams consist of thousands of JSON records every second.
The company needs to implement a scalable solution on AWS to identify anomalous data points.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: A
Explanation:
The correct answer is A. Ingest real-time data into Amazon Kinesis data streams. Use the built-in RANDOM_CUT_FOREST function in Amazon Managed Service for Apache Flink to process the data streams and to detect data anomalies.
Amazon Kinesis Data Streams is a fully managed service that can handle high-volume, real-time data streams with low latency and high scalability. By integrating Amazon Managed Service for Apache Flink (MSK for Flink) with the built-in RANDOM_CUT_FOREST (RCF) algorithm, the company can perform real-time anomaly detection directly on streaming data without building or managing custom infrastructure. RCF is designed for unsupervised anomaly detection on streaming datasets, making it ideal for financial market data that arrives continuously and at high velocity.
Option B adds operational complexity because it requires deploying a SageMaker endpoint, setting up Lambda functions, and maintaining the orchestration between Kinesis and Lambda. Option C further increases overhead by requiring self-managed Apache Kafka clusters on EC2, combined with SageMaker and Lambda orchestration. Option D introduces SQS and batch ETL processing via AWS Glue, which is not suitable for real-time anomaly detection and significantly increases latency.
Using Kinesis + Managed Flink + RCF provides a serverless, fully managed, and scalable solution with minimal operational overhead. It handles ingestion, streaming processing, and anomaly detection natively.
The architecture eliminates the need for provisioning compute clusters or managing real-time orchestration, reducing operational cost while achieving sub-second detection for thousands of JSON records per second.
This approach aligns with AWS best practices for ML solution monitoring, maintenance, and security, particularly for real-time anomaly detection in high-volume, structured or semi-structured data streams.
NEW QUESTION # 52
A company uses Amazon SageMakerAI to support ML workflows such as model training and deployment.
Select the correct registry from the following list to meet the requirements for each use case with the LEAST operational overhead. Each registry should be selected one or more times. (Select FOUR.)
* Amazon Elastic Container Registry (Amazon ECR)
* SageMaker Model Registry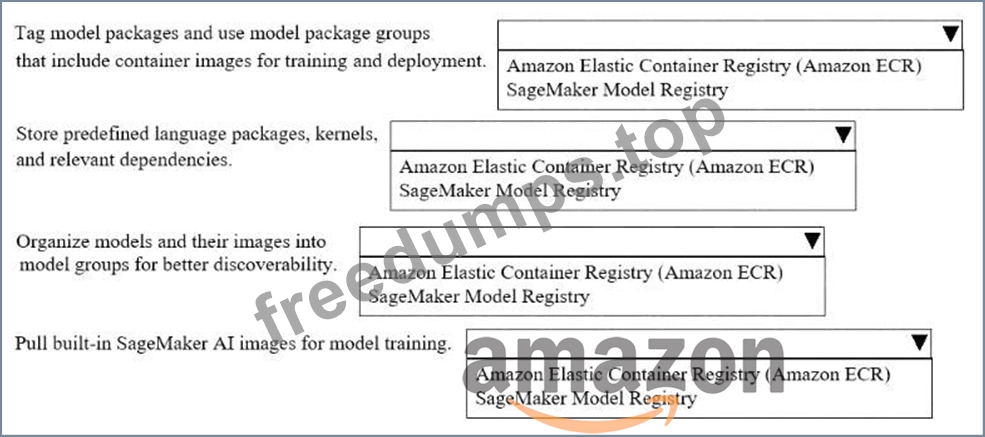
Answer:
Explanation: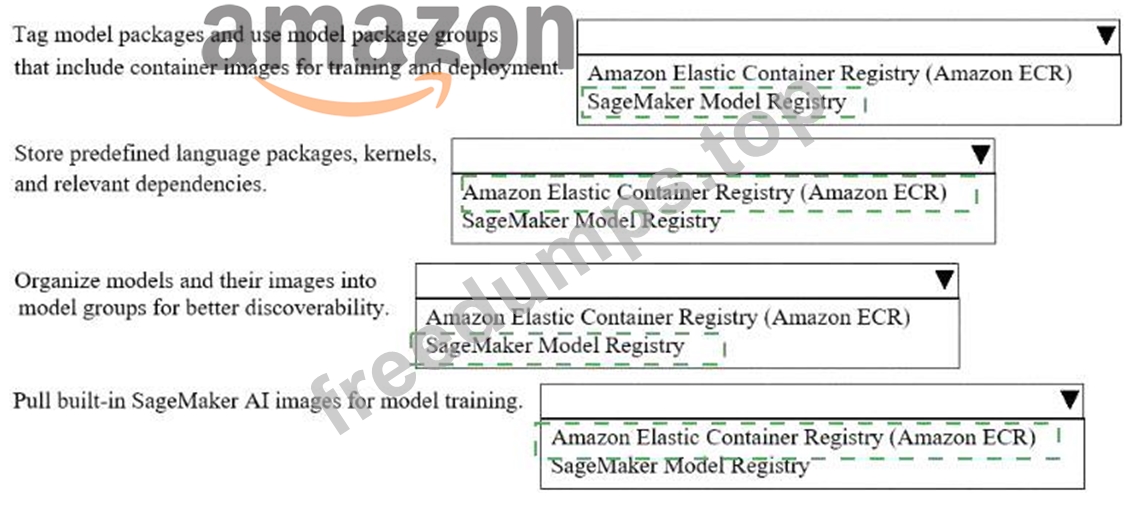
Explanation:
* Tag model packages and use model package groups that include container images for training and deployment # SageMaker Model Registry
* Store predefined language packages, kernels, and relevant dependencies # Amazon Elastic Container Registry (Amazon ECR)
* Organize models and their images into model groups for better discoverability # SageMaker Model Registry
* Pull built-in SageMaker AI images for model training # Amazon Elastic Container Registry (Amazon ECR) The correct hotspot mapping is based on the different purposes of SageMaker Model Registry and Amazon ECR .
For model packages , model package groups , and model discoverability, the correct choice is SageMaker Model Registry . AWS documentation states that a model package group is a collection of versioned model packages, and each version can contain the model artifacts, metadata, and container information used for deployment. AWS also documents that registered models can be organized into groups to support governance, discoverability, and lifecycle management. That is why both " tag model packages and use model package groups " and " organize models and their images into model groups " map to SageMaker Model Registry
.
For storing software environments and pulling training images, the correct choice is Amazon ECR . AWS documentation says SageMaker uses Docker container images , and these images contain the software stack such as frameworks, language packages, kernels, and dependencies. AWS also states that SageMaker provides prebuilt Docker images for training and inference, and these are referenced through Amazon ECR image URIs . Therefore, both " store predefined language packages, kernels, and relevant dependencies " and " pull built-in SageMaker AI images for model training " map to Amazon ECR .
NEW QUESTION # 53
A company has an ML model in Amazon SageMaker AI. An ML engineer needs to implement a monitoring solution to automatically detect changes in the input data distribution of model features.
Which solution will meet this requirement with the LEAST operational overhead?
Answer: D
Explanation:
Option A is correct because the requirement is to detect changes in the input data distribution of model features , which is a data quality / data drift monitoring problem. AWS documentation states that Amazon SageMaker Model Monitor uses rules to detect data drift and alerts you when it happens. The documented workflow is to enable data capture, create a baseline from training data, and then run monitoring jobs that compare incoming inference data against that baseline. That directly matches the need to automatically detect changes in feature distributions.
AWS also documents that Model Monitor can emit metrics to Amazon CloudWatch , and those metrics can be used with CloudWatch alarms to notify teams when data quality drifts beyond acceptable thresholds.
That makes Option A the lowest-operational-overhead solution because it uses SageMaker's built-in monitoring capability plus managed alerting, rather than requiring custom drift logic. The inclusion of emit_metrics and CloudWatch alarming is consistent with the SageMaker monitoring pattern for automated notification.
The other options are weaker. Option B is for model quality monitoring, which focuses on prediction performance against ground truth, not shifts in the input feature distribution. Option C uses SageMaker Debugger, which is aimed at training-time debugging and custom rule analysis rather than managed production data drift monitoring. Option D relies on manual log analysis and endpoint performance metrics, which does not directly solve feature-distribution drift detection and adds more operational effort. Therefore, the best AWS-documented answer is A .
NEW QUESTION # 54
An ML engineer wants to re-train an XGBoost model at the end of each month. A data team prepares the training data. The training dataset is a few hundred megabytes in size. When the data is ready, the data team stores the data as a new file in an Amazon S3 bucket.
The ML engineer needs a solution to automate this pipeline. The solution must register the new model version in Amazon SageMaker Model Registry within 24 hours.
Which solution will meet these requirements?
Answer: A
Explanation:
The requirement is event-driven automation when new data arrives in Amazon S3, followed by training and model registration. Amazon EventBridge natively supports S3 object creation events and can trigger downstream workflows immediately.
By using EventBridge to start an AWS Step Functions workflow that includes a training step and a SageMaker Model Registry registration step, the pipeline runs automatically as soon as new data is uploaded-well within the 24-hour requirement.
Option A introduces unnecessary polling and delay. Option B is time-based and does not ensure alignment with data readiness. Option C is invalid because S3 Lifecycle rules manage object transitions, not workflow execution.
Therefore, EventBridge-triggered Step Functions is the correct solution.
NEW QUESTION # 55
A company is using an Amazon Redshift database as its single data source. Some of the data is sensitive.
A data scientist needs to use some of the sensitive data from the database. An ML engineer must give the data scientist access to the data without transforming the source data and without storing anonymized data in the database.
Which solution will meet these requirements with the LEAST implementation effort?
Answer: C
NEW QUESTION # 56
......
Success in the AWS Certified Machine Learning Engineer - Associate MLA-C01 exam is impossible without proper MLA-C01 exam preparation. I would recommend you select FreeDumps for your MLA-C01 certification test preparation. FreeDumps offers updated Amazon MLA-C01 PDF Questions and practice tests. This MLA-C01 practice test material is a great help to you to prepare better for the final AWS Certified Machine Learning Engineer - Associate MLA-C01 exam.
Test MLA-C01 Questions Pdf: https://www.freedumps.top/MLA-C01-real-exam.html
BTW, DOWNLOAD part of FreeDumps MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1LfVSvsWTyeWuuStikr61q8wHFMhd_nhi