当社Fast2testのすべてのAI-200トレーニングファイルは、この分野の専門家と教授によって設計されています。教材の品質は保証されています。すべての顧客の実際の状況に応じて、すべての顧客に適した学習計画を作成します。当社からAI-200学習教材を購入する場合、AI-200試験に簡単に合格するための専門的なトレーニングを受けることをお約束します。専門的なトレーニングにより、AI-200試験に合格し、関連する認定資格を最短で取得します。
| Section | Objectives |
|---|---|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Develop containerized solutions on Azure | - Implement containerized applications
|
| Connect to and consume Azure services | - Integrate Azure services
|
明日ではなく、今日が大事と良く知られるから、そんなにぐずぐずしないで早く我々社のMicrosoft AI-200日本語対策問題集を勉強し、自身を充実させます。我々社の練習問題は長年でAI-200全真模擬試験トレーニング資料に研究している専業化チームによって編集されます。Microsoft AI-200資格問題集はPDF版、ソフト版、オンライン版を含まれ、この三つバージョンから自分の愛用することを選んでいます。他の人に先立ってMicrosoft AI-200認定資格を得るために、今から勉強しましょう。
質問 # 38
A company uses Azure Monitor Application Insights to monitor application behavior, including incoming requests and dependencies.
You must identify failed requests from the last hour. You must also calculate the average duration of failed request dependency calls, grouped by operation name.
You need to analyze telemetry in Application insights.
Which operators should you mm? To answer, select the appropriate options in the answer area NOTE: Each cot reel selection is worth one point.
正解:
解説: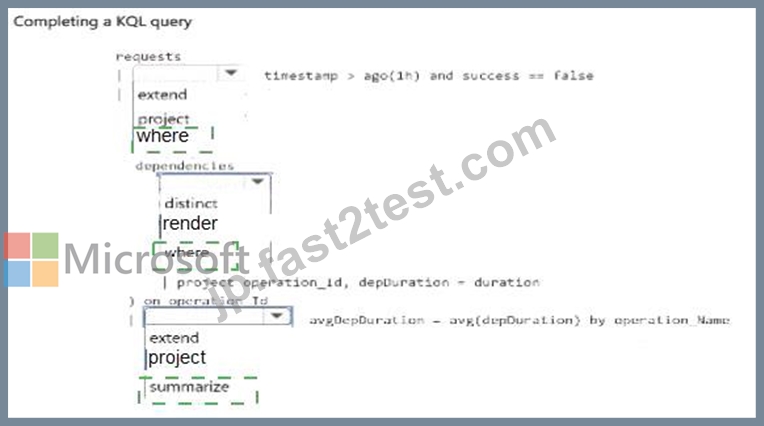
Explanation:
質問 # 39
You need to improve throughput for concurrent application requests to PostgreSQL.
What should you implement?
正解:B
解説:
The correct solution is to implement connection pooling , ideally by using the built-in PgBouncer capability in Azure Database for PostgreSQL Flexible Server. Connection pooling allows many concurrent application requests to share and reuse a smaller set of established PostgreSQL server connections instead of repeatedly opening and closing database sessions. Microsoft notes that creating a new PostgreSQL connection for each operation consumes server resources because each connection involves its own backend process. Reusing pooled connections therefore reduces connection overhead, lowers CPU and memory consumption, and improves throughput for high-concurrency workloads.
This directly matches Fabrikam ' s stated requirement that database connections support high concurrency with minimal latency through connection optimization . PgBouncer can efficiently multiplex large numbers of client connections onto fewer PostgreSQL connections, particularly in transaction pooling mode.
Increasing max_connections is not the preferred solution because each additional PostgreSQL connection consumes memory and other resources; Microsoft explicitly recommends PgBouncer instead when more concurrent connections are required. Increasing shared_buffers addresses caching and memory allocation rather than connection-management overhead. Read replicas can scale read workloads, but they do not optimize the application ' s connection lifecycle.
Study Guide references: Azure Database for PostgreSQL Flexible Server # connection pooling; PgBouncer; connection management and high-concurrency performance.
質問 # 40
An ACA app processes messages from an Azure Storage queue.
The app must scale automatically based on messages in a specific Azure Storage queue by using a Kubernetes Event-driven Autoscaler (KEDA) custom scale rule. You need to configure the required scale rule values.
Which two values should you configure? Each correct answer presents part of the solution. Choose two.
NOTE: Each correct selection is worth one point.
正解:A、B
解説:
Detailed Explanation: A KEDA custom scale rule must identify what scaler to use and which resource within that scaler should be observed. For Azure Storage queues, the trigger type selects the Storage Queue scaler and the queue name identifies the specific queue whose message count drives scaling. Polling interval and maximum replicas are general scaling controls, but they do not define the required queue-specific trigger.
Therefore trigger type and queue name are the essential rule values tested here.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Set scaling rules in Azure Container Apps
質問 # 41
You are implementing the expiration requirement for AI-generated summaries in the Redis cache.
You need to purge the AI summaries five minutes after creation, regardless of how often they are accessed.
What should you do?
正解:C
解説:
Configure a fixed expiration timeout on each Redis key when the summary is created , such as a five- minute TTL. Azure Managed Redis automatically removes a key when its configured timeout expires.
Critically, ordinary read operations do not extend that expiration period, so a summary created at time T will expire approximately five minutes later regardless of how frequently clients retrieve it.
This is the required absolute-expiration behavior. In Redis, applications can establish expiration when writing the value or by using expiration commands after creation. The important design property is that the expiration deadline is not refreshed whenever the key is read.
An allkeys-lru eviction policy addresses memory pressure , not deterministic five-minute expiration. It may evict less recently used keys when memory is constrained, but it does not guarantee removal exactly five minutes after creation. The PERSIST command is directly incorrect because it removes an existing timeout , potentially causing the summary to remain indefinitely. Sliding expiration is also unsuitable because it renews or resets the expiration window based on activity, allowing frequently accessed summaries to remain longer than five minutes.
Therefore, a per-key absolute five-minute expiration is the correct configuration.
Study Guide references: Azure Managed Redis # key expiration; TTL behavior; cache expiration versus eviction; fixed versus sliding expiration.
質問 # 42
Drag and Drop Question
You have a newly provisioned Azure subscription. You are designing a custom Event Grid workflow for AI inference events.
You need to implement the Event Grid components to support routing of high-confidence events to a downstream processor.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
正解:
解説: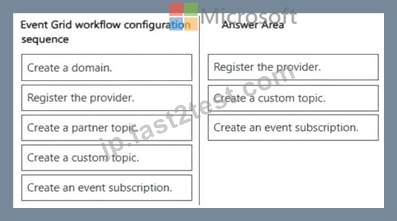
Explanation:
Step 1: Register a provider
Because this is a newly provisioned Azure subscription, you must register the Microsoft.EventGrid resource provider before you can deploy any Event Grid components.
Step 2: Create a custom topic
Since you are routing AI inference events originating from your application, you need to create a custom topic to act as the endpoint where these events are sent.
Step 3: Create an event subscription
You must create an event subscription to define the routing rules. This is where you configure filtering to ensure only high-confidence events are directed to your downstream processor.
Reference:
https://www.c-sharpcorner.com/article/building-event-driven-ai-workflows-with-azure-event-grid-and-net/
質問 # 43
......
他のたくさんのトレーニング資料より、Fast2testのMicrosoftのAI-200試験トレーニング資料は一番良いものです。IT認証のトレーニング資料が必要としたら、Fast2testのMicrosoftのAI-200試験トレーニング資料を利用しなければ絶対後悔しますよ。Fast2testのトレーニング資料を選んだら、あなたは一生で利益を受けることができます。
AI-200受験対策解説集: https://jp.fast2test.com/AI-200-premium-file.html