DOWNLOAD the newest Real4dumps DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1UxFCq3uzc-5gAkSB-1FUUyR1tYxcjdN1
As for candidates who will attend the exam, choosing the practicing materials may be a difficult choice. Then just trying DP-100 learning materials of us, with the pass rate is 98.95%, we help the candidates to pass the exam successfully. Many candidates have sent their thanks to us for helping them to pass the exam by using the DP-100 Learning Materials. The reason why we gain popularity in the customers is the high-quality of DP-100 exam dumps. In addition, we provide you with free update for one year after purchasing. Our system will send the latest version to you email address automatically.
| Section | Objectives |
|---|---|
| Deploy and consume models | - Monitor deployed models and endpoints - Deploy models to endpoints |
| Train machine learning models | - Train models using Azure Machine Learning - Tune hyperparameters and evaluate models |
| Optimize and manage models | - Improve model performance - Track experiments and manage model lifecycle |
| Design and prepare a machine learning solution | - Manage compute and data assets - Select appropriate Azure services for machine learning workloads - Plan and configure Azure Machine Learning workspace |
| Explore and analyze data | - Ingest and prepare data for modeling - Perform exploratory data analysis |
You can know what knowledge points you do not master. By the report from our DP-100 study questions. Then it will be very easy for you to make your own learning plan. We believe that the learning plan based on the report of our DP-100 preparation exam will be very useful for you. So if you buy our DP-100 Practice Engine, it will help you pass your exam and get the certification in a short time, and you will find that our study materials are good value for money.
NEW QUESTION # 128
You create an experiment in Azure Machine Learning Studio. You add a training dataset that contains 10,000 rows. The first 9,000 rows represent class 0 (90 percent).
The remaining 1,000 rows represent class 1 (10 percent).
The training set is imbalances between two classes. You must increase the number of training examples for class 1 to 4,000 by using 5 data rows. You add the Synthetic Minority Oversampling Technique (SMOTE) module to the experiment.
You need to configure the module.
Which values should you use? To answer, select the appropriate options in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.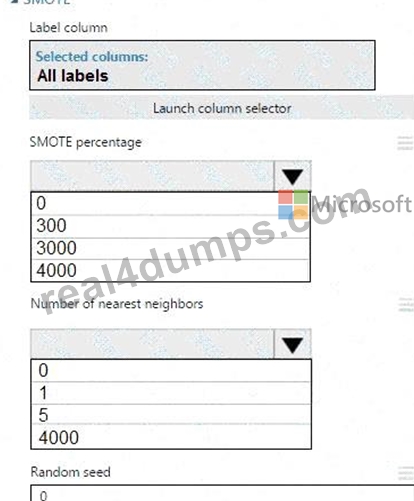
Answer:
Explanation:
Explanation: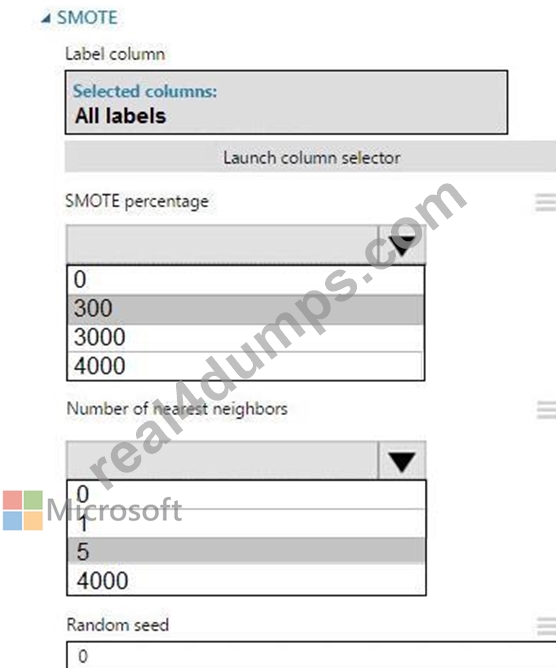
Box 1: 300
You type 300 (%), the module triples the percentage of minority cases (3000) compared to the original dataset (1000).
Box 2: 5
We should use 5 data rows.
Use the Number of nearest neighbors option to determine the size of the feature space that the SMOTE algorithm uses when in building new cases. A nearest neighbor is a row of data (a case) that is very similar to some target case. The distance between any two cases is measured by combining the weighted vectors of all features.
By increasing the number of nearest neighbors, you get features from more cases.
By keeping the number of nearest neighbors low, you use features that are more like those in the original sample.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/smote
NEW QUESTION # 129
You need to set up the Permutation Feature Importance module according to the model training requirements.
Which properties should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Box 1: Accuracy
Scenario: You want to configure hyperparameters in the model learning process to speed the learning phase by using hyperparameters. In addition, this configuration should cancel the lowest performing runs at each evaluation interval, thereby directing effort and resources towards models that are more likely to be successful.
Box 2: R-Squared
NEW QUESTION # 130
You are creating a machine learning model. You have a dataset that contains null rows.
You need to use the Clean Missing Data module in Azure Machine Learning Studio to identify and resolve the null and missing data in the dataset.
Which parameter should you use?
Answer: C
Explanation:
Explanation/Reference:
Explanation:
Remove entire row: Completely removes any row in the dataset that has one or more missing values. This is useful if the missing value can be considered randomly missing.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/clean-missing-data Testlet 1 Case study Overview You are a data scientist in a company that provides data science for professional sporting events. Models will use global and local market data to meet the following business goals:
Understand sentiment of mobile device users at sporting events based on audio from crowd reactions.
Assess a user's tendency to respond to an advertisement.
Customize styles of ads served on mobile devices.
Use video to detect penalty events
Current environment
Media used for penalty event detection will be provided by consumer devices. Media may include
images and videos captured during the sporting event and shared using social media. The images and videos will have varying sizes and formats.
The data available for model building comprises of seven years of sporting event media. The sporting
event media includes; recorded video transcripts or radio commentary, and logs from related social media feeds captured during the sporting events.
Crowd sentiment will include audio recordings submitted by event attendees in both mono and stereo
formats.
Penalty detection and sentiment
Data scientists must build an intelligent solution by using multiple machine learning models for penalty
event detection.
Data scientists must build notebooks in a local environment using automatic feature engineering and
model building in machine learning pipelines.
Notebooks must be deployed to retrain by using Spark instances with dynamic worker allocation.
Notebooks must execute with the same code on new Spark instances to recode only the source of the
data.
Global penalty detection models must be trained by using dynamic runtime graph computation during
training.
Local penalty detection models must be written by using BrainScript.
Experiments for local crowd sentiment models must combine local penalty detection data.
Crowd sentiment models must identify known sounds such as cheers and known catch phrases.
Individual crowd sentiment models will detect similar sounds.
All shared features for local models are continuous variables.
Shared features must use double precision. Subsequent layers must have aggregate running mean
and standard deviation metrics available.
Advertisements
During the initial weeks in production, the following was observed:
Ad response rated declined.
Drops were not consistent across ad styles.
The distribution of features across training and production data are not consistent
Analysis shows that, of the 100 numeric features on user location and behavior, the 47 features that come from location sources are being used as raw features. A suggested experiment to remedy the bias and variance issue is to engineer 10 linearly uncorrelated features.
Initial data discovery shows a wide range of densities of target states in training data used for crowd
sentiment models.
All penalty detection models show inference phases using a Stochastic Gradient Descent (SGD) are
running too slow.
Audio samples show that the length of a catch phrase varies between 25%-47% depending on region
The performance of the global penalty detection models shows lower variance but higher bias when
comparing training and validation sets. Before implementing any feature changes, you must confirm the bias and variance using all training and validation cases.
Ad response models must be trained at the beginning of each event and applied during the sporting
event.
Market segmentation models must optimize for similar ad response history.
Sampling must guarantee mutual and collective exclusively between local and global segmentation
models that share the same features.
Local market segmentation models will be applied before determining a user's propensity to respond to
an advertisement.
Ad response models must support non-linear boundaries of features.
The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviated
from 0.1 +/- 5%.
The ad propensity model uses cost factors shown in the following diagram:
The ad propensity model uses proposed cost factors shown in the following diagram:
Performance curves of current and proposed cost factor scenarios are shown in the following diagram:
NEW QUESTION # 131
You need to implement early stopping criteria as suited in the model training requirements.
Which three code segments should you use to develop the solution? To answer, move the appropriate code segments from the list of code segments to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.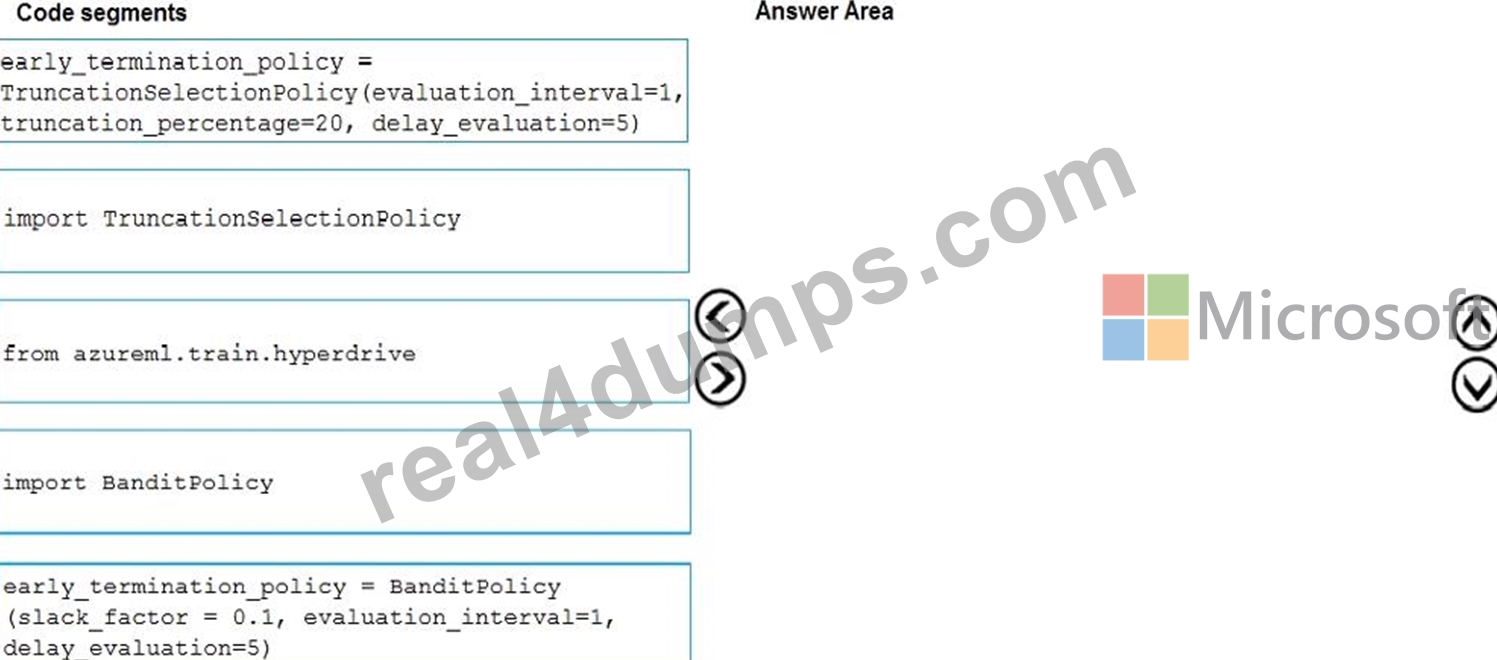
Answer:
Explanation:
1 - from azureml.train.hyperdrive
2 - import TruncationSelectionPolicy
3 - erly_termination_policy=.........
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/service/how-to-tune-hyperparameters
NEW QUESTION # 132
space and set up a development environment. You plan to train a deep neural network (DNN) by using the Tensorflow framework and by using estimators to submit training scripts.
You must optimize computation speed for training runs.
You need to choose the appropriate estimator to use as well as the appropriate training compute target configuration.
Which values should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Box 1: Tensorflow
TensorFlow represents an estimator for training in TensorFlow experiments.
Box 2: 12 vCPU, 112 GB memory..,2 GPU,..
Use GPUs for the deep neural network.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-train-core/azureml.train.dnn
NEW QUESTION # 133
......
That's why it's indispensable to use Designing and Implementing a Data Science Solution on Azure (DP-100) real exam dumps. Real4dumps understands the significance of Updated Microsoft DP-100 Questions, and we're committed to helping candidates clear tests in one go. To help Microsoft DP-100 test applicants prepare successfully in one go, Real4dumps's DP-100 dumps are available in three formats: Designing and Implementing a Data Science Solution on Azure (DP-100) web-based practice test, desktop DP-100 practice Exam software, and DP-100 dumps PDF.
Dump DP-100 Check: https://www.real4dumps.com/DP-100_examcollection.html
DOWNLOAD the newest Real4dumps DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1UxFCq3uzc-5gAkSB-1FUUyR1tYxcjdN1