P.S. Free & New AI-200 dumps are available on Google Drive shared by PrepAwayETE: https://drive.google.com/open?id=1xUXc9whsrzBOrqNoAntp0KffdMvAjXfQ
The Microsoft AI-200 web-based practice test software is very user-friendly and simple to use. It is accessible on all browsers (Chrome, Firefox, MS Edge, Safari, Opera, etc). It will save your progress and give a report of your mistakes which will surely be beneficial for your overall exam preparation.
| Section | Objectives |
|---|---|
| Topic 1: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Topic 2: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Topic 3: Develop containerized solutions on Azure | - Implement containerized applications
|
| Topic 4: Connect to and consume Azure services | - Integrate Azure services
|
>> Valid Dumps AI-200 Ebook <<
Beware that the sections of the exam change from time to time. Therefore, be alert by checking the updates frequently. It will prevent you from wasting time, material expenses, and inner peace. PrepAwayETE has another special deal as well. It will provide you with the Microsoft AI-200 Dumps latest updates until 365 days after purchasing the AI-200 exam questions.
NEW QUESTION # 77
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
You need to address the known issue resulting from vector similarity queries.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,D
Explanation:
Known Issues: RU consumption spikes during vector similarity queries.
To address the RU (Request Unit) consumption spikes during vector similarity queries in Azure Cosmos DB, you should perform the following two steps:
Modify the indexing precision of the vector fields
Change the vector index type from flat to quantizedFlat or diskANN
Indexing Precision Tuning: Modifying parameters like vector quantization (e.g., configuring quantizedByteSize) alters the size and precision of the stored vector elements. Lowering the precision decreases memory usage and index size, allowing faster searches that consume far fewer RUs at the expense of marginal recall accuracy.
Index Type Modification: A standard flat index conducts a brute-force k-nearest neighbors (kNN) exact search across every document. This requires vast computational overhead and causes RU spikes as your dataset grows. Transitioning to quantizedFlat or diskANN leverages compression techniques and advanced graph-traversal algorithms to perform approximate nearest neighbor (ANN) searches, dropping query latency and compute costs significantly.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/gen-ai/vector-search-performance-tips
NEW QUESTION # 78
You are developing a .NET application that uses Azure Cosmos DB for NoSQL to store application data The application uses the Azure Cosmos DB for NoSQL SDK to interact with the database account. The application must perform the following tasks
* Initialize the connection by using the account endpoint and key.
* Define shared throughput.
* Perform create, read, update, and delete (CRUD) operations on items stored in a container
Answer:
Explanation: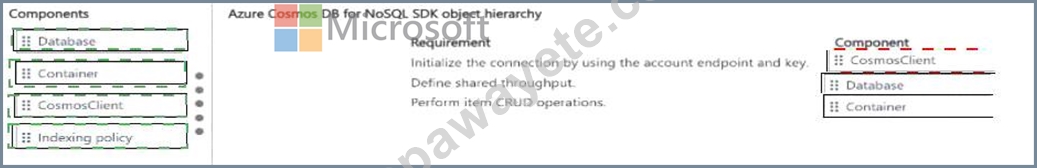
Explanation:
Verified answer: Initialize connection: CosmosClient. Define shared throughput: Database. Perform item CRUD: Container.
Detailed Explanation: The Cosmos DB SDK follows the service resource hierarchy. CosmosClient represents the account connection and is initialized with the account endpoint and credential. Shared throughput is configured at the database level when multiple containers share database throughput. Item create, read, update, and delete operations are performed through a container object because containers hold items and define partitioning/indexing behavior. An indexing policy is configuration attached to a container, not the SDK object used for CRUD.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Cosmos DB databases, containers, and items
NEW QUESTION # 79
Drag and Drop Question
A Python API retrieves a document from Azure Database for PostgreSQL by using a SQL statement. The API accepts the document ID from user input. The current implementation inserts the document ID directly into the SQL statement.
You need to secure the SQL statement execution by minimizing the possibility of SQL injection.
How should you modify the current implementation? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Box 1: Use a parameterized query
To secure your SQL statement against SQL injection, you must replace direct string insertion with parameterized queries (also known as prepared statements).
Box 2: Pass the ID as an argument
The current implementation inserts the document ID directly into the SQL statement.
Box 3: Supply the parameter tuple to the SDK method
Supply parameter tuples: Pass the user input as a separate tuple or list argument into your database driver's execution method (e.g., cursor.execute(query, (document_id,))).
Reference:
https://www.stackhawk.com/blog/finding-and-fixing-sql-injection-vulnerabilities-in-flask-python/
NEW QUESTION # 80
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
You need to optimize vector search queries based on the technical requirements. What should you do?
Answer: C
Explanation:
Scenario: Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
*-> Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
To optimize vector similarity queries that must be performed only against products satisfying mandatory metadata constraints, you should Create a B-tree index on metadata filter columns.
1. Evaluate Query Execution OrderIn PostgreSQL with pgvector, combining metadata filters with vector similarity searches often triggers a multi-stage execution plan. When metadata filtering is highly restrictive, creating a B-tree index allows the database engine to quickly narrow down the row scanned before or during the vector evaluation, preventing a costly full-table scan.
2. Assess Indexing Trade-offs
B-tree Index (Metadata): Directly addresses the requirement that vector calculations must be performed only against products satisfying mandatory metadata constraints. It optimizes the metadata filtering step, significantly reducing compute overhead and isolating the target rows for vector processing.
IVFFlat Index (Vector): While an IVFFlat index speeds up high-dimensional approximate nearest neighbor (ANN) searches, it divides vectors into lists. If a metadata filter is applied after an IVFFlat index scan, it can lead to severe recall degradation or inaccurate results because rows matching the metadata might reside in unsearched vector lists. (Note: For newer workloads, HNSW is generally preferred over IVFFlat for better recall and performance, but regular B-trees remain vital for the metadata layer).
3. Ensure Index Residency in RAM
By isolating the dataset using a compact B-tree index on metadata columns, you minimize the active working set. This helps fulfill your operational requirement to ensure that high-dimensional vector indexes and target rows remain resident in RAM for efficient mathematical throughput.
Reference:
https://www.applied-ai.com/briefings/enterprise-rag-architecture/
NEW QUESTION # 81
Hotspot Question
You are creating an Azure Functions app project in your local development environment by using Azure Functions Core Tools.
You must create the project in either Python or C# without using a template.
You need to specify the command and its parameter required to create the Azure Functions app project.
Which command and parameter should you specify? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Box 1: func init
To initialize a new Azure Functions app project from the command line using Azure Functions Core Tools without using a specific code template, use the func init command combined with the -
-worker-runtime parameter.
Box 2: --worker-runtime
Reference:
https://r-vm.com/python-on-azure-functions
NEW QUESTION # 82
......
About choosing the perfect AI-200 study material, it may be reflected in matters like quality, prices, after-sale services and so on. AI-200 exam simulation is accumulation of knowledge about the exam strictly based on the syllabus of the exam. They give users access to information and exam, offering simulative testing environment when you participate it like in the classroom. And if you are afraid of the lack experience of the exam, our AI-200 Practice Engine will be your good choice.
New AI-200 Study Plan: https://www.prepawayete.com/Microsoft/AI-200-practice-exam-dumps.html
BTW, DOWNLOAD part of PrepAwayETE AI-200 dumps from Cloud Storage: https://drive.google.com/open?id=1xUXc9whsrzBOrqNoAntp0KffdMvAjXfQ