참고: Itcertkr에서 Google Drive로 공유하는 무료 2026 Microsoft DP-600 시험 문제집이 있습니다: https://drive.google.com/open?id=1_cY5TdAL7xQbnjQ0oGpbZe1lDlqUm6Ku
Itcertkr에서 최고최신버전의Microsoft인증DP-600시험덤프 즉 문제와 답을 받으실 수 있습니다. 빨리 소지한다면 좋겠죠. 그래야 여러분은 빨리 한번에Microsoft인증DP-600시험을 패스하실 수 있습니다.Microsoft인증DP-600관련 최고의 자료는 현재까지는Itcertkr덤프가 최고라고 자신 있습니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
Itcertkr에서 최고최신버전의Microsoft인증DP-600시험덤프 즉 문제와 답을 받으실 수 있습니다. 빨리 소지한다면 좋겠죠. 그래야 여러분은 빨리 한번에Microsoft인증DP-600시험을 패스하실 수 있습니다.Microsoft인증DP-600관련 최고의 자료는 현재까지는Itcertkr덤프가 최고라고 자신 있습니다.
질문 # 105
Drag and Drop Question
You have Fabric tenant that contains a semantic model named Model1. Model1 contains the following tables.
You are designing a Microsoft Power BI report named Report1 that will deliver near-real-time (NRT) shipping data. Report1 will contain data about many shipped packages.
You need to ensure that each table is in the appropriate storage mode to support Report1. The solution must support near-real-time data delivery while maintaining high query performance.
Which storage mode should you select for each table? To answer, drag the appropriate storage modes to the correct tables. Each mode may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
정답:
설명:
질문 # 106
You have a Fabric tenant.
You plan to create a Fabric notebook that will use Spark DataFrames to generate Microsoft Power Bl visuals.
You run the following code.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
정답:
설명:
Explanation:
The code embeds an existing Power BI report. - No
The code creates a Power BI report. - Yes
The code displays a summary of the DataFrame. - Yes
The code provided seems to be a snippet from a SQL query or script which is neither creating nor embedding a Power BI report directly. It appears to be setting up a DataFrame for use within a larger context, potentially for visualization in Power BI, but the code itself does not perform the creation or embedding of a report.
Instead, it's likely part of a data processing step that summarizes data.
References =
Introduction to DataFrames - Spark SQL
Power BI and Azure Databricks
질문 # 107
You have a Fabric workspace named Workspace1 that contains a lakehouse named Lakehouse1.
In Workspace1. you create a data pipeline named Pipeline1.
You have CSV files stored in an Azure Storage account.
You need to add an activity to Pipeline1 that will copy data from the CSV files to Lakehouse1. The activity must support Power Query M formula language expressions.
Which type of activity should you add?
정답:C
설명:
The requirement is to copy data from CSV files in Azure Storage into a Fabric Lakehouse, and it must support Power Query M formula language.
Dataflow activity in Fabric pipelines allows you to use Power Query Online, which is based on the M formula language.
Notebook uses Spark (Python, PySpark, Scala, SQL), not M.
Copy data activity moves data but does not support Power Query M transformations.
Script is for T-SQL or stored procedure execution, not M.
Therefore, the correct activity is Dataflow.
Reference: Dataflows in Microsoft Fabric
질문 # 108
You have a Fabric workspace named Workspace1 that contains the following items:
A warehouse named Warehouse1
A semantic model named Model1
An interactive report named Report1
You need to allow a user named User1 to access a single table in Warehouse1.
The solution must follow the principle of least privilege.
What should you do first?
정답:C
설명:
Requirement
Fabric workspace: Workspace1
Contains: Warehouse1, Model1, Report1
Task: Allow User1 to access a single table in Warehouse1.
Must follow principle of least privilege # grant only the exact permissions required.
Step 1: Evaluate Options
A). Assign object level permissions to User1 for Warehouse1.
In Fabric warehouses, you can grant permissions at the object level (table, schema, or column).
If the requirement is access to only one table, the correct approach is to grant SELECT permissions on that specific table.
This satisfies least privilege.
Correct. #
B). Assign the db_datareader role to User1 for Warehouse1.
db_datareader provides read access to all tables in the database/warehouse.
This violates least privilege.
Not correct.
C). Share Warehouse1 with User1.
Sharing grants access to the whole warehouse.
Too broad, not least privilege.
Not correct.
D). Assign the Viewer role to User1 for Workspace1.
Viewer role allows seeing all items in the workspace (warehouse, model, reports).
This would expose more than the single table.
Not correct.
Step 2: Correct Action
Use object-level permissions:
GRANT SELECT ON dbo.TableName TO [User1];
This ensures User1 can only query that specific table, nothing else.
References
Manage object-level security in Microsoft Fabric warehouses
Principle of least privilege in Fabric
질문 # 109
You have a Fabric eventhouse named Eventhousel that contains a table named Weatherdata. A sample of the data in Weatherdata is shown in the following table.
You plan to use a KQL queryset to manipulate the data in Eventhouse1. The result set must have the following columns.
You need to build the query.
Which four KQL statements should you use in sequence? To answer, move the appropriate statements from the list of statements to the answer area and arrange them in the correct order.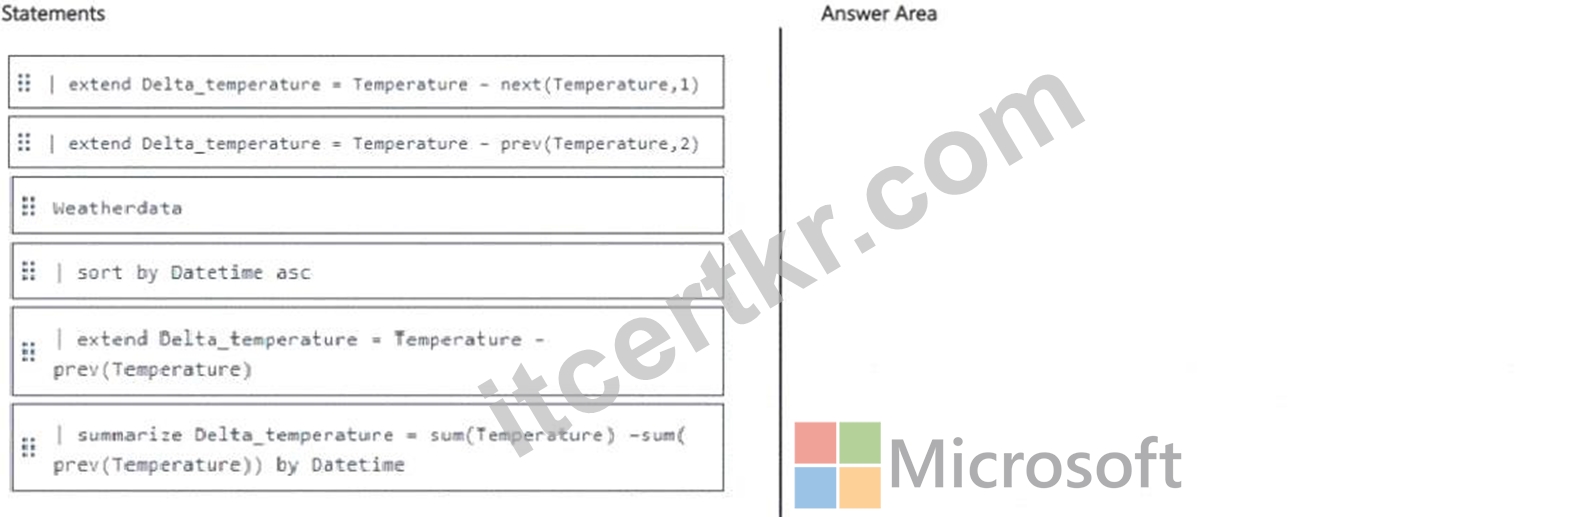
정답:
설명:
Explanation:
Comprehensive Detailed Explanation
Step 1: Understanding the requirement
We need a KQL query that:
Reads data from Weatherdata.
Orders by Datetime.
Calculates Delta_temperature as the difference between the current row and the preceding row.
Returns the final columns: Datetime, Lat, Long, Temperature, Delta_temperature.
Step 2: Evaluate the provided statements
Weatherdata # Starts the query with the source table.
| sort by Datetime asc # Ensures chronological order, required for prev() to work correctly.
| extend Delta_temperature = Temperature - prev(Temperature) # Computes difference between the current row and the previous row's temperature.
| project Datetime, Lat, Long, Temperature, Delta_temperature # Selects the required output columns.
Step 3: Incorrect choices (to avoid)
next(Temperature,1) # Would calculate the difference with the next row, not the previous.
prev(Temperature,2) # Would skip one row, giving the difference with two rows back, which is not needed.
summarize ... by Datetime # Aggregates the data; not required here since we just need row-level differences.
Step 4: Final Correct Sequence
Weatherdata
| sort by Datetime asc
| extend Delta_temperature = Temperature - prev(Temperature)
| project Datetime, Lat, Long, Temperature, Delta_temperature
References
prev() function in KQL
extend operator in KQL
project operator in KQL
질문 # 110
......
우선 우리Itcertkr 사이트에서Microsoft DP-600관련자료의 일부 문제와 답 등 샘플을 제공함으로 여러분은 무료로 다운받아 체험해보실 수 있습니다.체험 후 우리의Itcertkr에 신뢰감을 느끼게 됩니다. Itcertkr에서 제공하는Microsoft DP-600덤프로 시험 준비하시면 편안하게 시험을 패스하실 수 있습니다.
DP-600시험대비 덤프 최신자료: https://www.itcertkr.com/DP-600_exam.html
참고: Itcertkr에서 Google Drive로 공유하는 무료, 최신 DP-600 시험 문제집이 있습니다: https://drive.google.com/open?id=1_cY5TdAL7xQbnjQ0oGpbZe1lDlqUm6Ku