Databricks Certified-Data-Engineer-Professional試験攻略、Certified-Data-Engineer-Professional認証資格

我々Jpexamは最も速いパースする方法をあげるし、PDF版、ソフト版、オンライン版の三つ種類版を提供します。PDF版、ソフト版、オンライン版は各自のメリットがあるので、あなたは自分の好きにするし、我々JpexamのDatabricks Certified-Data-Engineer-Professional問題集デモを参考して選択できます。どんな版でも、Databricks Certified-Data-Engineer-Professional試験に合格するのには成功への助力です。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Data Modeling | ~10% | - Apply dimensional modeling techniques
- Design scalable Delta Lake schemas and clustering
|
| Topic 2: Developing Code for Data Processing using Python and SQL | ~22% | - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader
- Implement scalable Python/SQL code and project structures
- Manage dependencies, libraries, and UDFs
|
| Topic 3: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation
|
| Topic 4: Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables
- Diagnose common pipeline and job failures
|
| Topic 5: Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations
- Enforce data quality and quarantine bad data
|
| Topic 6: Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines
- Apply AUTO CDC APIs and exactly-once semantics
|
| Topic 7: CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines
- Deploy with Declarative Automation Bundles, CLI, and REST API
|
| Topic 8: Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage
- Leverage system tables and observability tools
|
| Topic 9: Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs
- Implement row-level security, column masking, and compliance
|
>> Databricks Certified-Data-Engineer-Professional試験攻略 <<
有難いCertified-Data-Engineer-Professional試験攻略一回合格-信頼的なCertified-Data-Engineer-Professional認証資格
Certified-Data-Engineer-Professionalの最新の準備資料は、PDFバージョン、ソフトウェアバージョン、オンラインバージョンを含む3つの異なるバージョンをユーザーに提供します。関連する3つのバージョンのCertified-Data-Engineer-Professionalティーチングコンテンツは同じですが、すべてのタイプのユーザーにとって、どのバージョンのCertified-Data-Engineer-Professional学習教材であるかを問わず、より良いCertified-Data-Engineer-Professional学習経験。以下では、私たちの研究資料の主な利点をご紹介したいと思います。ぜひお見逃しなく。
Databricks Certified Data Engineer Professional 認定 Certified-Data-Engineer-Professional 試験問題 (Q189-Q194):
質問 # 189
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.
Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales.
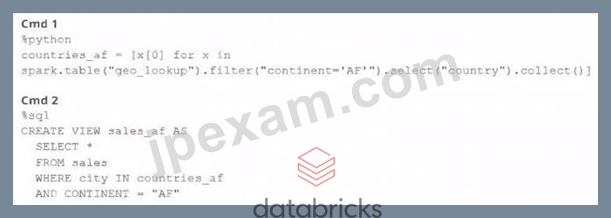
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
- A. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable representing a PySpark DataFrame.
- B. Both commands will succeed. Executing show tables will show that countries at and sales at have been registered as views.
- C. Cmd 1 will succeed. Cmd 2 will search all accessible databases for a table or view named countries af: if this entity exists, Cmd 2 will succeed.
- D. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable containing a list of strings.
- E. Both commands will fail. No new variables, tables, or views will be created.
正解:D
解説:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view.
Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter.
質問 # 190
The following code has been migrated to a Databricks notebook from a legacy workload:
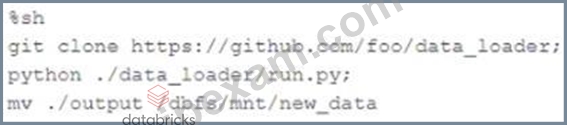
The code executes successfully and provides the logically correct results, however, it takes over
20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
- A. Instead of cloning, the code should use %sh pip install so that the Python code can get executed in parallel across all nodes in a cluster.
- B. %sh executes shell code on the driver node. The code does not take advantage of the worker nodes or Databricks optimized Spark.
- C. Python will always execute slower than Scala on Databricks. The run.py script should be refactored to Scala.
- D. %sh does not distribute file moving operations; the final line of code should be updated to use %fs instead.
- E. %sh triggers a cluster restart to collect and install Git. Most of the latency is related to cluster startup time.
正解:B
解説:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
質問 # 191
Predictive Optimization is an automated Databricks service enabled by default for Unity Catalog Managed tables. It helps maintain Delta tables by continuously optimizing them to ensure optimal performance and costs. Which two operations does Predictive Optimization run to maintain the Delta tables? (Choose two.)
- A. ANALYZE
- B. COMPACT
- C. PARTITION BY
- D. BUCKETING
- E. OPTIMIZE
正解:A、E
解説:
Predictive Optimization automatically runs OPTIMIZE to compact small files and improve data layout, and ANALYZE to collect and refresh table statistics. Together, these operations ensure efficient query planning, better data skipping, and optimized performance and cost for Unity Catalog managed Delta tables.
質問 # 192
The Databricks workspace administrator has configured interactive clusters for each of the data engineering groups. To control costs, clusters are set to terminate after 30 minutes of inactivity.
Each user should be able to execute workloads against their assigned clusters at any time of the day.
Assuming users have been added to a workspace but not granted any permissions, which of the following describes the minimal permissions a user would need to start and attach to an already configured cluster.
- A. Cluster creation allowed. "Can Restart" privileges on the required cluster
- B. Cluster creation allowed. "Can Attach To" privileges on the required cluster
- C. Workspace Admin privileges, cluster creation allowed. "Can Attach To" privileges on the required cluster
- D. "Can Restart" privileges on the required cluster
- E. "Can Manage" privileges on the required cluster
正解:D
解説:
https://learn.microsoft.com/en-us/azure/databricks/security/auth-authz/access-control/cluster-acl
https://docs.databricks.com/en/security/auth-authz/access-control/cluster-acl.html
質問 # 193
A data governance team at a large enterprise is improving data discoverability across its organization. The team has hundreds of tables in their Databricks Lakehouse with thousands of columns that lack proper documentation. Many of these tables were created by different teams over several years, with missing context about column meanings and business logic. The data governance team needs to quickly generate comprehensive column descriptions for all existing tables to meet compliance requirements and improve data literacy across the organization. They want to leverage modern capabilities to automatically generate meaningful descriptions rather than manually documenting each column, which would take months to complete. Which approach should the team use in Databricks to automatically generate column comments and descriptions for existing tables?
- A. Use the DESCRIBE TABLE command to extract existing schema information and manually write descriptions based on column names and data types.
- B. Navigate to the table in Databricks Catalog Explorer, select the table schema view, and use the AI Generate option which leverages artificial intelligence to automatically create meaningful column descriptions based on column names, data types, sample values, and data patterns.
- C. Use Delta Lake's DESCRIBE HISTORY command to analyze table evolution and infer column purposes from historical changes.
- D. Write custom PySpark code using df.describe() and df.schema to programmatically generate basic statistical descriptions for each column.
正解:B
解説:
The Catalog Explorer provides an AI-powered "AI Generate" capability that automatically creates intelligent column descriptions by analyzing column names, data types, sample values, and observed data patterns. This approach enables rapid, scalable documentation of existing tables, significantly improving data discoverability and compliance without manual effort.
質問 # 194
......
今、私たちDatabricksは非常に競争の激しい世界に住んでいます。あなたがまともな仕事を見つけて高い給料を稼ぎたいなら、あなたは優れた能力と豊富な知識を所有していなければなりません。この状況では、Certified-Data-Engineer-Professionalガイドトレントを所有することは非常に重要です。特定の分野で優れた能力を習得し、仕事をうまく処理できるからです。私たちが提供するCertified-Data-Engineer-Professional試験準備は、Certified-Data-Engineer-Professional試験に合格し、簡単にCertified-Data-Engineer-Professional試験トレントを所有するという夢を実現するのに役立ちます。
Certified-Data-Engineer-Professional認証資格: https://www.jpexam.com/Certified-Data-Engineer-Professional_exam.html
- 試験の準備方法-正確的なCertified-Data-Engineer-Professional試験攻略試験-実際的なCertified-Data-Engineer-Professional認証資格 🏮 最新【 Certified-Data-Engineer-Professional 】問題集ファイルは“ www.goshiken.com ”にて検索Certified-Data-Engineer-Professional受験記
- 試験の準備方法-便利なCertified-Data-Engineer-Professional試験攻略試験-効率的なCertified-Data-Engineer-Professional認証資格 🗨 “ www.goshiken.com ”を開き、✔ Certified-Data-Engineer-Professional ️✔️を入力して、無料でダウンロードしてくださいCertified-Data-Engineer-Professional対策学習
- 試験の準備方法-便利なCertified-Data-Engineer-Professional試験攻略試験-効率的なCertified-Data-Engineer-Professional認証資格 💔 ➥ www.passtest.jp 🡄サイトにて✔ Certified-Data-Engineer-Professional ️✔️問題集を無料で使おうCertified-Data-Engineer-Professionalテストトレーニング
- Certified-Data-Engineer-Professional復習対策書 🤓 Certified-Data-Engineer-Professional難易度受験料 😲 Certified-Data-Engineer-Professional参考書 🔕 ⇛ www.goshiken.com ⇚を入力して「 Certified-Data-Engineer-Professional 」を検索し、無料でダウンロードしてくださいCertified-Data-Engineer-Professional全真模擬試験
- Certified-Data-Engineer-Professional試験の準備方法|便利なCertified-Data-Engineer-Professional試験攻略試験|認定するDatabricks Certified Data Engineer Professional認証資格 👺 ✔ www.japancert.com ️✔️で▶ Certified-Data-Engineer-Professional ◀を検索して、無料でダウンロードしてくださいCertified-Data-Engineer-Professional受験方法
- Certified-Data-Engineer-Professional復習対策書 🟨 Certified-Data-Engineer-Professional問題数 🐇 Certified-Data-Engineer-Professional資格勉強 🧑 ☀ www.goshiken.com ️☀️は、➤ Certified-Data-Engineer-Professional ⮘を無料でダウンロードするのに最適なサイトですCertified-Data-Engineer-Professional全真模擬試験
- Certified-Data-Engineer-Professional受験体験 📒 Certified-Data-Engineer-Professional専門知識 🤵 Certified-Data-Engineer-Professional対策学習 🪐 ▛ www.mogiexam.com ▟で➥ Certified-Data-Engineer-Professional 🡄を検索して、無料で簡単にダウンロードできますCertified-Data-Engineer-Professional復習対策書
- 一番優秀なCertified-Data-Engineer-Professional試験攻略 - 合格スムーズCertified-Data-Engineer-Professional認証資格 | 高品質なCertified-Data-Engineer-Professional練習問題 Databricks Certified Data Engineer Professional 🐳 【 www.goshiken.com 】で使える無料オンライン版《 Certified-Data-Engineer-Professional 》 の試験問題Certified-Data-Engineer-Professional全真模擬試験
- 有難い-完璧なCertified-Data-Engineer-Professional試験攻略試験-試験の準備方法Certified-Data-Engineer-Professional認証資格 🚦 サイト⇛ www.jpshiken.com ⇚で⮆ Certified-Data-Engineer-Professional ⮄問題集をダウンロードCertified-Data-Engineer-Professionalテストトレーニング
- 完璧なDatabricks Certified-Data-Engineer-Professional試験攻略 - 合格スムーズCertified-Data-Engineer-Professional認証資格 | 最高のCertified-Data-Engineer-Professional練習問題 🍘 今すぐ☀ www.goshiken.com ️☀️で▛ Certified-Data-Engineer-Professional ▟を検索し、無料でダウンロードしてくださいCertified-Data-Engineer-Professional受験記
- Certified-Data-Engineer-Professional模擬解説集 🥿 Certified-Data-Engineer-Professionalミシュレーション問題 🤡 Certified-Data-Engineer-Professional参考書 📹 { www.passtest.jp }で「 Certified-Data-Engineer-Professional 」を検索して、無料でダウンロードしてくださいCertified-Data-Engineer-Professional全真模擬試験
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, onlyfans.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes