Microsoft DP-750 is a difficult subject which is hard to pass, but you do not worry too much. If you take right action, passing exam easily is not also impossible. Do you know which method is available and valid? Yes, it couldn't be better if you purchasing DP-750 Training Kit. We help many candidates who are determined to get IT certifications. Our good DP-750 training kit quality and after-sales service, the vast number of users has been very well received.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
>> DP-750 Exam Sample Online <<
Our DP-750 learning materials are famous for high quality, and we have the experienced experts to compile and verify DP-750 exam dumps, the correctness and the quality can be guaranteed. DP-750 learning materials contain both questions and answers, and you can have a quickly check after you finish practicing. Moreover, we offer you free update for one year, and you can know the latest information about the DP-750 Exam Materials if you choose us. The update version will be sent to your email automatically.
NEW QUESTION # 28
You have an Azure Databricks workspace.
You have an Azure key vault named kv-secure that stores a secret named storageKey. The value of storageKey is managed and updated by the cloud security team at your company.
You need to enable a Databricks notebook named Notebook 1 to retrieve the value of storageKey securely at runtime. The solution must follow the principle of least privilege and always retrieve the latest value.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.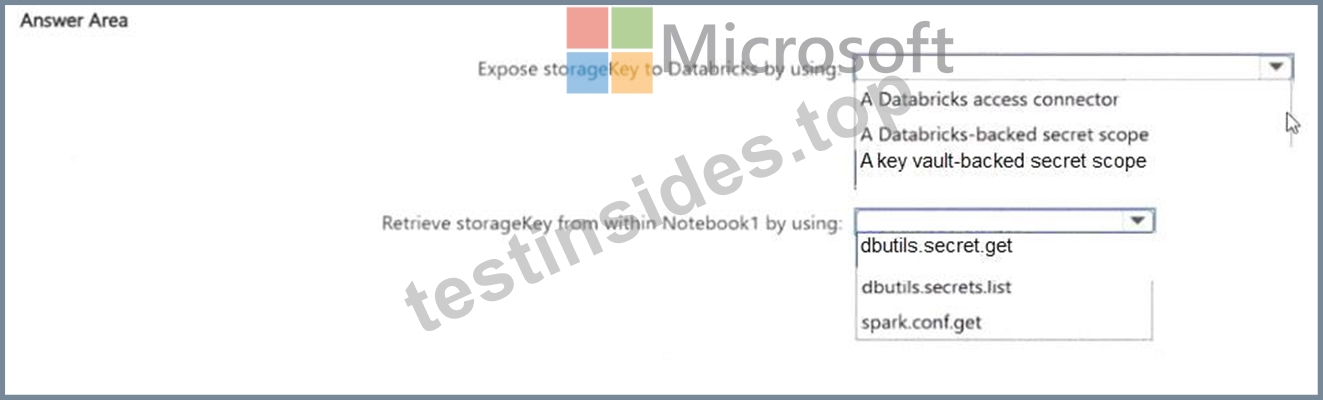
Answer:
Explanation: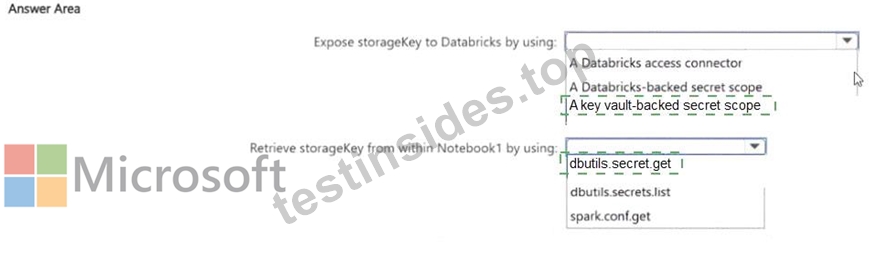
Explanation:
The solution is a Key Vault-backed secret scope combined with dbutils.secrets.get() in the notebook.
An Azure Key Vault-backed secret scope does not copy the secret value into Databricks. Every call to dbutils.
secrets.get() fetches the live current value directly from Key Vault at runtime. This means when the cloud security team rotates storageKey in Key Vault, the notebook automatically picks up the new value on its next run - no Databricks configuration changes needed. That satisfies 'always retrieve the latest value.' The principle of least privilege is upheld because only the secret scope has read access to Key Vault through a service principal or managed identity, and individual users never see the raw secret value - Databricks redacts it in logs automatically.
A Databricks-backed scope stores a copy of the secret inside Databricks, so it wouldn't automatically reflect Key Vault updates. Hardcoding or using environment variables would expose the secret in plain text.
Reference: https://learn.microsoft.com/en-us/azure/databricks/security/secrets/secret-scopes
NEW QUESTION # 29
Hotspot Question
You have an Azure Databricks workspace.
You have an Azure key vault named kv-secure that stores a secret named storageKey. The value of storageKey is managed and updated by the cloud security team at your company.
You need to enable a Databricks notebook named Notebook1 to retrieve the value of storageKey securely at runtime. The solution must follow the principle of least privilege and always retrieve the latest value.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.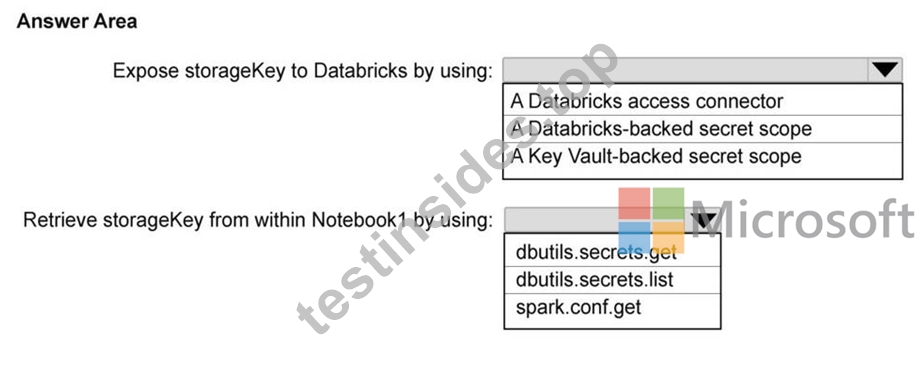
Answer:
Explanation: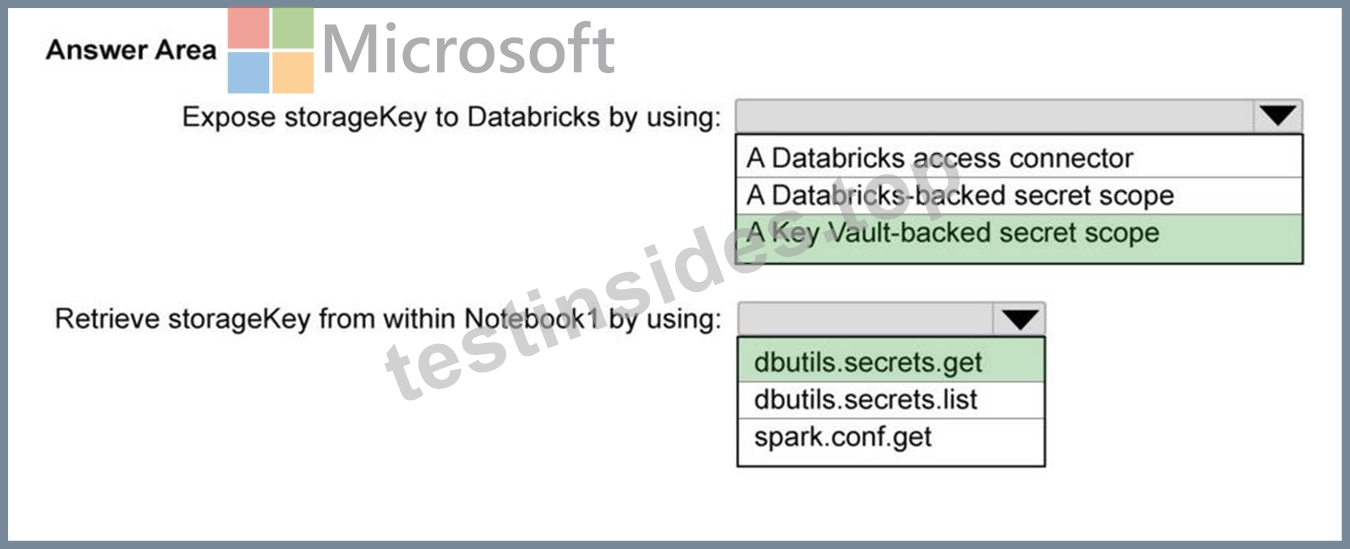
NEW QUESTION # 30
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a foreign catalog in Catalog Explorer.
Does this meet the goal?
Answer: A
Explanation:
The correct answer is A - Yes.
A foreign catalog created through Lakehouse Federation in Catalog Explorer is the correct solution for all three requirements. Here's why it works:
The schemas and tables of DB1 can be queried in Databricks - Lakehouse Federation pushes the query down to the external SQL Server and returns results, so analysts write normal SQL in Databricks.
They appear alongside other Unity Catalog objects - the foreign catalog sits in the same three-tier hierarchy as native catalogs, schemas, and tables, visible in Catalog Explorer alongside all other Unity Catalog assets.
The data is NOT copied into Databricks-managed storage - foreign catalogs query data in place at the source; nothing is replicated or materialised in Databricks storage.
This is exactly the scenario Lakehouse Federation was built for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/query-federation/lakehouse-federation
NEW QUESTION # 31
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.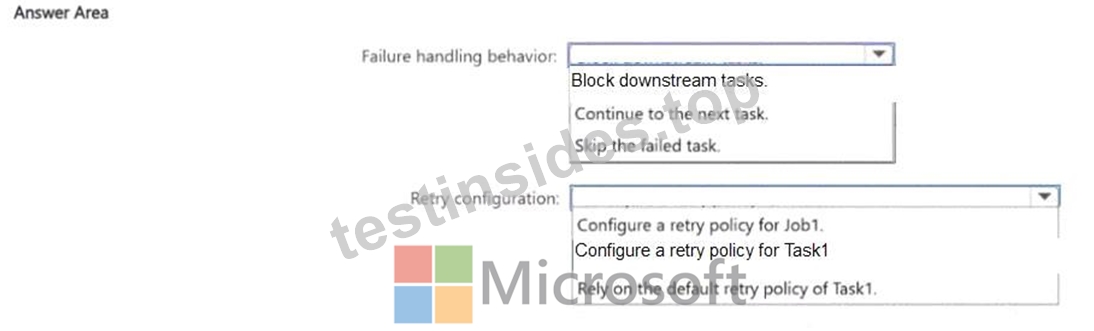
Answer:
Explanation: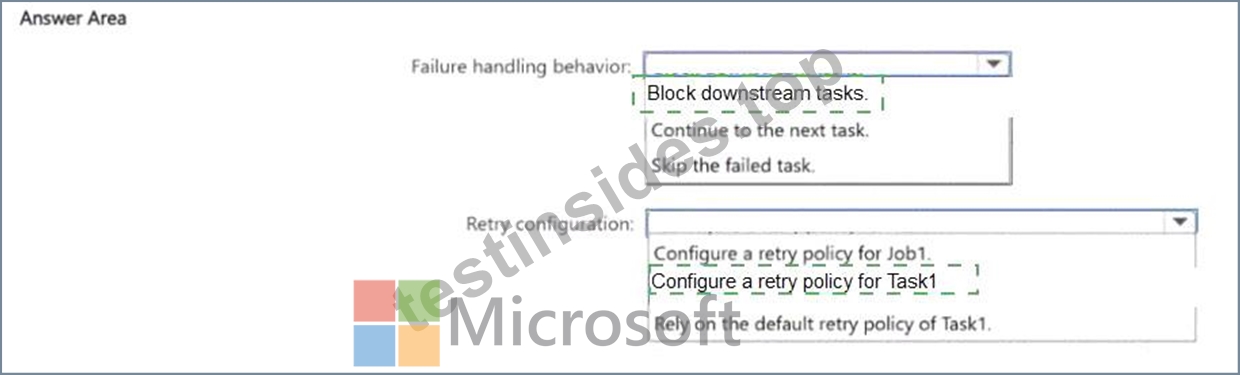
Explanation:
Two task-level settings solve this:
Task1 retry policy: configure Task1 with a maximum number of retries and a retry interval. When Task1 fails, Lakeflow Jobs automatically re-runs it up to the retry limit without any manual intervention. This handles transient infrastructure failures transparently.
Task2 run condition set to ' All succeeded ' with Task1 as its dependency: this means Task2 only starts when Task1 has succeeded. If Task1 fails and exhausts all retries, Task2 remains blocked - it never runs on data from a failed upstream ingestion. The dependency is declared in Task2 ' s ' Depends on ' setting in the job configuration.
These two settings are independent and composable. Task1 ' s retry policy gives it multiple chances to recover. Task2 ' s dependency and run condition ensure the downstream transformation only runs on clean, successfully ingested data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#task-retries
NEW QUESTION # 32
You have an Azure Databricks workspace named Workspace1. You create a compute cluster named Cluser1 that will be used to ingest data.
You need to install the required libraries on Cluster 1. The solution must use Unity Catalog for access control.
What should you do?
Answer: D
Explanation:
The correct answer is B. The %pip install command (or pip3 in a terminal context) creates an isolated, per- session library environment in notebooks, which is the Unity Catalog-compatible approach. Unity Catalog workspaces require cluster access mode set to 'Shared' or 'Single User,' and %pip installs work seamlessly within those modes without requiring cluster restarts.
Option A (custom dependency script) introduces extra maintenance work for every environment change - exactly what the question says to avoid. Option C installs libraries at the cluster level and requires a manual restart, which disrupts other users sharing the cluster and bypasses the per-notebook isolation model that Unity Catalog recommends. Option D uploads libraries to the Workspace file system (legacy DBFS approach), which is being deprecated in favour of Unity Catalog Volumes for library storage.
Reference: https://learn.microsoft.com/en-us/azure/databricks/libraries/notebooks-python-libraries
NEW QUESTION # 33
......
You can be a part of this wonderful community. To do this you just need to pass the Microsoft DP-750 certification exam. Are you ready to accept this challenge? Looking for the proven and easiest way to crack the Microsoft DP-750 certification exam? If your answer is yes then you do not need to go anywhere. Just download TestInsides DP-750 exam practice questions and start Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam preparation without wasting further time. The TestInsides DP-750 Dumps will provide you with everything that you need to learn, prepare and pass the challenging TestInsides Microsoft DP-750 exam with flying colors. You must try TestInsides DP-750 exam questions today.
DP-750 Exam Guide Materials: https://www.testinsides.top/DP-750-dumps-review.html