実際的-便利なCertified-Data-Engineer-Professional学習範囲試験-試験の準備方法Certified-Data-Engineer-Professionalテスト問題集

この驚くほど高く受け入れられている試験に適合するには、Certified-Data-Engineer-Professional学習教材のような上位の実践教材で準備する必要があります。彼らは時間とお金の面で最良の選択です。 Certified-Data-Engineer-Professionalトレーニング準備のすべての内容は、素人にfされているのではなく、この分野のエリートによって作成されています。弊社の優秀なヘルパーによる効率に魅了された数万人の受験者を引き付けたリーズナブルな価格に沿ってみましょう。難しい難問は、Certified-Data-Engineer-Professionalクイズガイドで解決します。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Optimize data layout using Liquid Clustering
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Manage and troubleshoot third-party library installations and dependencies
- Building and Testing ETL Pipelines
- 1. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 2. Compare streaming tables and materialized views
- 3. Use control flow operators in pipeline components
- 4. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 5. Use APPLY CHANGES APIs for change data capture
- 6. Configure environments, dependencies, memory, and retry behavior
- 7. Develop unit and integration tests for data processing code
- 8. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
|
| Data Sharing and Federation | - Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Share live Lakehouse data with external computing platforms
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Cost & Performance Optimisation | - Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Apply data skipping and file pruning techniques
- 3. Use Change Data Feed to address streaming table limitations and improve latency
|
| Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Apply anonymization and pseudonymization techniques
|
| Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Monitoring and Alerting | - Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest data from message buses and cloud storage
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
>> Certified-Data-Engineer-Professional学習範囲 <<
効率的なCertified-Data-Engineer-Professional学習範囲と実際的なCertified-Data-Engineer-Professionalテスト問題集
Certified-Data-Engineer-Professional学習資料は、消費者に無料の試用サービスをGoShiken提供します。 Certified-Data-Engineer-Professional学習資料に興味があり、Databricks無料でトライアル質問バンクをすぐにダウンロードして体験できます。 トライアルを通じて、Certified-Data-Engineer-Professional試験ガイドでさまざまな学習経験ができます。私たちの言うことは嘘ではないことがわかり、すぐに製品に恋をすることになります。 あなたの人生の成功の鍵として、Certified-Data-Engineer-Professional学習教材があなたにもたらす利益は金銭では測定されません。 Certified-Data-Engineer-Professional試験トレントは、最短時間でDatabricks Certified Data Engineer Professional試験に合格するのに役立ちます。
Databricks Certified Data Engineer Professional 認定 Certified-Data-Engineer-Professional 試験問題 (Q202-Q207):
質問 # 202
A data engineer wants to automate job monitoring and recovery in Databricks using the Jobs API.
They need to list all jobs, identify a failed job, and rerun it. Which sequence of API actions should the data engineer perform?
- A. Use the jobs/list endpoint to list jobs, check job run statuses with jobs/runs/list, and rerun a failed job using jobs/run-now.
- B. Use the jobs/list endpoint to list jobs, then use the jobs/create endpoint to create a new job, and run the new job using jobs/run-now.
- C. Use the jobs/get endpoint to retrieve job details, then use jobs/update to rerun failed jobs.
- D. Use the jobs/cancel endpoint to remove failed jobs, then recreate them with jobs/create and run the new ones.
正解:A
解説:
The Databricks Jobs REST API provides several endpoints for automation. The correct monitoring and rerun flow uses three specific calls:
GET /api/2.1/jobs/list - Lists all available jobs within the workspace.
GET /api/2.1/jobs/runs/list - Returns all runs for a specific job, including their current state (e.g., TERMINATED: FAILED).
POST /api/2.1/jobs/run-now - Immediately triggers a rerun of the specified job.
This sequence aligns with Databricks' prescribed automation model for job observability and recovery. Using jobs/update modifies metadata but does not rerun jobs, and jobs/create is only used for creating new jobs, not rerunning failed ones. Cancelling and recreating jobs introduces unnecessary duplication. Therefore, option A is the correct automated recovery workflow.
質問 # 203
The data engineer is using Spark's MEMORY_ONLY storage level. Which indicators should the data engineer look for in the spark UI's Storage tab to signal that a cached table is not performing optimally?
- A. On Heap Memory Usage is within 75% of off Heap Memory usage
- B. The number of Cached Partitions> the number of Spark Partitions
- C. Size on Disk is < Size in Memory
- D. The RDD Block Name included the '' annotation signaling failure to cache
- E. Size on Disk is> 0
正解:E
解説:
When using Spark's MEMORY_ONLY storage level, the ideal scenario is that the data is fully cached in memory, and the Size on Disk should be 0 (indicating that the data is not spilled to disk). If the Size on Disk is greater than 0, it suggests that some data has been spilled to disk, which can lead to degraded performance as reading from disk is slower than reading from memory.
質問 # 204
A data engineer is configuring Delta Sharing for a Databricks-to-Databricks scenario to optimize read performance. The recipient needs to perform time travel queries and streaming reads on shared sales data. Which configuration will provide the optimal performance while enabling these capabilities?
- A. Use the open sharing protocol instead of Databricks-to-Databricks sharing for better performance.
- B. Share tables WITHOUT HISTORY and enable partitioning for better query performance.
- C. Share the entire schema WITHOUT HISTORY and rely on recipient-side caching for performance.
- D. Share tables WITH HISTORY, ensure tables don't have partitioning enabled, and enable CDF before sharing.
正解:D
解説:
The official Delta Sharing guidance specifies that in order for recipients to use time travel queries and streaming reads, providers must share Delta tables WITH HISTORY. Sharing history ensures the Delta log is included, which enables efficient access to table snapshots and incremental data streams.
Additionally, Change Data Feed (CDF) must be enabled prior to sharing if downstream consumers require streaming CDC queries. Without history, recipients cannot perform time travel or streaming queries. Open sharing supports static Delta tables but lacks streaming support.
Therefore, sharing tables WITH HISTORY and enabling CDF is the required configuration for both performance and functionality.
質問 # 205
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.
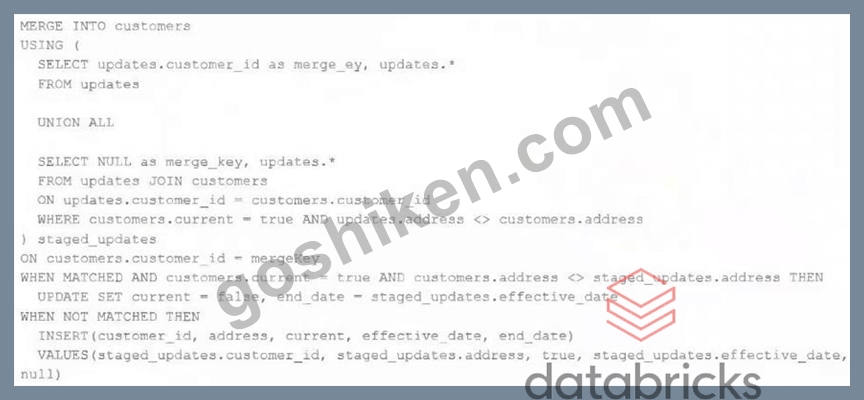
Which statement describes this implementation?
- A. The customers table is implemented as a Type 0 table; all writes are append only with no changes to existing values.
- B. The customers table is implemented as a Type 2 table; old values are maintained but marked as no longer current and new values are inserted.
- C. The customers table is implemented as a Type 3 table; old values are maintained as a new column alongside the current value.
- D. The customers table is implemented as a Type 2 table; old values are overwritten and new customers are appended.
- E. The customers table is implemented as a Type 1 table; old values are overwritten by new values and no history is maintained.
正解:B
質問 # 206
The data governance team has instituted a requirement that the "user" table containing Personal Identifiable Information (PII) must have the appropriate masking on the SSN column. This means that anyone outside of the HRAdminGroup should see masked social security numbers as ***-**-
****.
The team created a masking function:

What does the data governance team need to do next to achieve this goal?
- A. CREATE TABLE users
(name STRING);
ALTER TABLE users CREATE COLUMN ssn CREATE MASK ssn_mask; - B. CREATE TABLE users
(name STRING, int STRING);
ALTER TABLE users ALTER COLUMN ssn CREATE MASK if is_member('HRAdminGroup'); - C. CREATE TABLE users
(name STRING, ssn INT MASKED ssn_mask); - D. CREATE TABLE users
(name STRING, ssn STRING);
ALTER TABLE users ALTER COLUMN ssn SET MASK ssn_mask;
正解:D
解説:
In Databricks, after creating a masking function, you apply it to a column using ALTER TABLE
<table> ALTER COLUMN <column> SET MASK <mask_function>. The table must already include the column (here, ssn as STRING). This ensures that only users in the HRAdminGroup see the unmasked SSN, while all others see the masked value.
質問 # 207
......
私たちGoShikenの将来の雇用のためのより資格のある認定は、その能力を証明するのに十分な資格Certified-Data-Engineer-Professional認定を取得するためにのみ考慮される効果があり、社会的競争でライバルを乗り越えることができます。多くの受験者はCertified-Data-Engineer-Professional試験の難しさに負けていますが、Certified-Data-Engineer-Professional試験の資料を知っていれば、難易度を簡単に克服できます。 Certified-Data-Engineer-Professional試験問題を購入する場合は、Webで製品の機能を確認するか、Certified-Data-Engineer-Professional試験問題の無料デモをお試しください。
Certified-Data-Engineer-Professionalテスト問題集: https://www.goshiken.com/Databricks/Certified-Data-Engineer-Professional-mondaishu.html
- 1冊で合格がつかめるお得な Certified-Data-Engineer-Professional 問題集 🕢 サイト「 www.mogiexam.com 」で「 Certified-Data-Engineer-Professional 」問題集をダウンロードCertified-Data-Engineer-Professional試験対応
- 一番売れているDatabricks Certified-Data-Engineer-Professional合格教本 🦉 ▷ www.goshiken.com ◁から簡単に▷ Certified-Data-Engineer-Professional ◁を無料でダウンロードできますCertified-Data-Engineer-Professionalオンライン試験
- 有効なCertified-Data-Engineer-Professional学習問題集、Certified-Data-Engineer-Professional信頼できる学習参考書、 🥟 ☀ www.passtest.jp ️☀️の無料ダウンロード⏩ Certified-Data-Engineer-Professional ⏪ページが開きますCertified-Data-Engineer-Professional受験料
- Certified-Data-Engineer-Professional資格受験料 🎁 Certified-Data-Engineer-Professionalテストサンプル問題 👿 Certified-Data-Engineer-Professional模擬試験 🔦 今すぐ✔ www.goshiken.com ️✔️を開き、▷ Certified-Data-Engineer-Professional ◁を検索して無料でダウンロードしてくださいCertified-Data-Engineer-Professional受験料
- Certified-Data-Engineer-Professional試験の準備方法|最高のCertified-Data-Engineer-Professional学習範囲試験|真実的なDatabricks Certified Data Engineer Professionalテスト問題集 👾 ▛ Certified-Data-Engineer-Professional ▟を無料でダウンロード➡ www.xhs1991.com ️⬅️ウェブサイトを入力するだけCertified-Data-Engineer-Professional関連資格知識
- 1冊で合格がつかめるお得な Certified-Data-Engineer-Professional 問題集 🤞 ✔ www.goshiken.com ️✔️にて限定無料の▛ Certified-Data-Engineer-Professional ▟問題集をダウンロードせよCertified-Data-Engineer-Professional資格受験料
- Certified-Data-Engineer-Professional認定資格試験 🚛 Certified-Data-Engineer-Professional日本語版復習指南 💋 Certified-Data-Engineer-Professionalオンライン試験 👓 ⏩ www.mogiexam.com ⏪は、《 Certified-Data-Engineer-Professional 》を無料でダウンロードするのに最適なサイトですCertified-Data-Engineer-Professional模擬トレーリング
- Databricks Certified-Data-Engineer-Professional学習範囲: Databricks Certified Data Engineer Professional - GoShiken 優秀なウェブサイト 🍔 今すぐ{ www.goshiken.com }で▷ Certified-Data-Engineer-Professional ◁を検索し、無料でダウンロードしてくださいCertified-Data-Engineer-Professionalテストサンプル問題
- 1冊で合格がつかめるお得な Certified-Data-Engineer-Professional 問題集 🚺 【 www.it-passports.com 】を開いて【 Certified-Data-Engineer-Professional 】を検索し、試験資料を無料でダウンロードしてくださいCertified-Data-Engineer-Professional問題トレーリング
- Certified-Data-Engineer-Professional資格専門知識 🕺 Certified-Data-Engineer-Professional入門知識 🎁 Certified-Data-Engineer-Professional資格専門知識 🧇 今すぐ“ www.goshiken.com ”で{ Certified-Data-Engineer-Professional }を検索し、無料でダウンロードしてくださいCertified-Data-Engineer-Professional日本語版復習指南
- Certified-Data-Engineer-Professional資格受験料 📙 Certified-Data-Engineer-Professional復習対策書 🍃 Certified-Data-Engineer-Professionalオンライン試験 🐟 ➠ www.it-passports.com 🠰にて限定無料の“ Certified-Data-Engineer-Professional ”問題集をダウンロードせよCertified-Data-Engineer-Professional資格専門知識
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.callcentersindia.co.in, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes