Valid Certified-Data-Engineer-Professional Cram Materials - Certified-Data-Engineer-Professional Valid Exam Format

To be the best global supplier of electronic Certified-Data-Engineer-Professional study materials for our customers through innovation and enhancement of our customers' satisfaction has always been our common pursuit. The advantages of our Certified-Data-Engineer-Professional guide dumps are too many to count. And the most important point is that the pass rate of our Certified-Data-Engineer-Professional learning quiz is preety high as 98% to 99%. I guess this is also the candidates care most as well. You can totally trust in our Certified-Data-Engineer-Professional exam questions!
| Section | Objectives |
|---|
| Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Design and implement scalable data models using Delta Lake to manage large datasets
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Identify the benefits of liquid clustering over partitioning and Z-Ordering
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
|
| Monitoring and Alerting | - Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Query Profile and Spark UI to monitor workloads
- Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Apply Change Data Feed to address streaming table limitations and improve latency
- 5. Understand Delta optimization techniques such as deletion vectors and liquid clustering
|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 2. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 3. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 4. Create pipeline components using control flow operators such as if/else and foreach
- 5. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 6. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
|
>> Valid Certified-Data-Engineer-Professional Cram Materials <<
High Pass-Rate Valid Certified-Data-Engineer-Professional Cram Materials & Leader in Qualification Exams & Realistic Databricks Databricks Certified Data Engineer Professional
Databricks Certified-Data-Engineer-Professional Practice tests are formatted like real tests. The BraindumpsIT platform provides an exceptional level of support for individuals preparing for and taking the Databricks Certified-Data-Engineer-Professional exam. Their dedicated support team is available to assist candidates with any issues or concerns related to Databricks Certified-Data-Engineer-Professional Test Preparation. Additionally, the platform offers a money-back guarantee for those who do not pass the Certified-Data-Engineer-Professional test on their first attempt.
Databricks Certified Data Engineer Professional Sample Questions (Q232-Q237):
NEW QUESTION # 232
A small company based in the United States has recently contracted a consulting firm in India to implement several new data engineering pipelines to power artificial intelligence applications. All the company's data is stored in regional cloud storage in the United States.
The workspace administrator at the company is uncertain about where the Databricks workspace used by the contractors should be deployed.
Assuming that all data governance considerations are accounted for, which statement accurately informs this decision?
- A. Cross-region reads and writes can incur significant costs and latency; whenever possible, compute should be deployed in the same region the data is stored.
- B. Databricks runs HDFS on cloud volume storage; as such, cloud virtual machines must be deployed in the region where the data is stored.
- C. Databricks notebooks send all executable code from the user's browser to virtual machines over the open internet; whenever possible, choosing a workspace region near the end users is the most secure.
- D. Databricks workspaces do not rely on any regional infrastructure; as such, the decision should be made based upon what is most convenient for the workspace administrator.
- E. Databricks leverages user workstations as the driver during interactive development; as such, users should always use a workspace deployed in a region they are physically near.
Answer: A
Explanation:
This is the correct answer because it accurately informs this decision. The decision is about where the Databricks workspace used by the contractors should be deployed. The contractors are based in India, while all the company's data is stored in regional cloud storage in the United States. When choosing a region for deploying a Databricks workspace, one of the important factors to consider is the proximity to the data sources and sinks. Cross-region reads and writes can incur significant costs and latency due to network bandwidth and data transfer fees.
Therefore, whenever possible, compute should be deployed in the same region the data is stored to optimize performance and reduce costs.
NEW QUESTION # 233
The data engineering team maintains the following code:
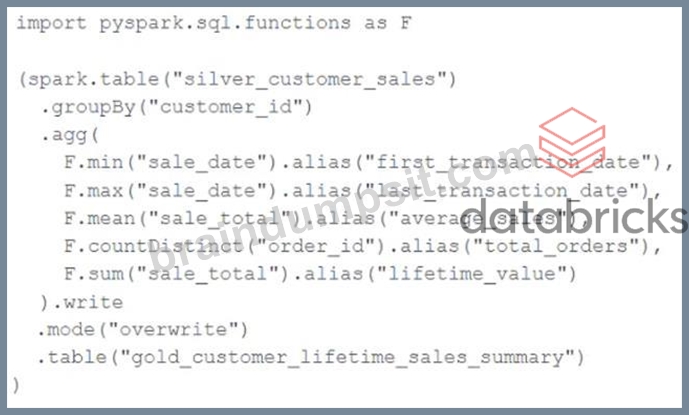
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. A batch job will update the gold_customer_lifetime_sales_summary table, replacing only those rows that have different values than the current version of the table, using customer_id as the primary key.
- B. An incremental job will detect if new rows have been written to the silver_customer_sales table; if new rows are detected, all aggregates will be recalculated and used to overwrite the gold_customer_lifetime_sales_summary table.
- C. An incremental job will leverage running information in the state store to update aggregate values in the gold_customer_lifetime_sales_summary table.
- D. The gold_customer_lifetime_sales_summary table will be overwritten by aggregated values calculated from all records in the silver_customer_sales table as a batch job.
- E. The silver_customer_sales table will be overwritten by aggregated values calculated from all records in the gold_customer_lifetime_sales_summary table as a batch job.
Answer: D
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids. The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed.
NEW QUESTION # 234
Which statement describes the correct use of pyspark.sql.functions.broadcast?
- A. It caches a copy of the indicated table on attached storage volumes for all active clusters within a Databricks workspace.
- B. It marks a DataFrame as small enough to store in memory on all executors, allowing a broadcast join.
- C. It marks a column as having low enough cardinality to properly map distinct values to available partitions, allowing a broadcast join.
- D. It marks a column as small enough to store in memory on all executors, allowing a broadcast join.
- E. It caches a copy of the indicated table on all nodes in the cluster for use in all future queries during the cluster lifetime.
Answer: B
Explanation:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
NEW QUESTION # 235
Which of the following is true of Delta Lake and the Lakehouse?
- A. Z-order can only be applied to numeric values stored in Delta Lake tables
- B. Primary and foreign key constraints can be leveraged to ensure duplicate values are never entered into a dimension table.
- C. Views in the Lakehouse maintain a valid cache of the most recent versions of source tables at all times.
- D. Delta Lake automatically collects statistics on the first 32 columns of each table which are leveraged in data skipping based on query filters.
- E. Because Parquet compresses data row by row. strings will only be compressed when a character is repeated multiple times.
Answer: D
Explanation:
Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters. Data skipping is a performance optimization technique that aims to avoid reading irrelevant data from the storage layer. By collecting statistics such as min/max values, null counts, and bloom filters, Delta Lake can efficiently prune unnecessary files or partitions from the query plan. This can significantly improve the query performance and reduce the I/O cost.
NEW QUESTION # 236
A data engineer deploys a multi-task Databricks job that orchestrates three notebooks. One task intermittently fails with Exit Code 1 but succeeds on retry. The engineer needs to collect detailed logs for the failing attempts, including stdout/stderr and cluster lifecycle context, and share them with the platform team. What steps the data engineer needs to follow using built-in tools?
- A. Export the notebook run results to HTML; this bundle includes complete stdout, stderr, and cluster event history across all tasks.
- B. Download worker logs directly from the Spark UI and ignore driver logs, as worker logs contain stdout/stderr for all tasks and cluster events.
- C. From the job run details page, export the job's logs or configure log delivery; then retrieve the compute driver logs and event logs from the compute details page to correlate stdout/stderr with cluster events.
- D. Use the notebook interactive debugger to re-run the entire multi-task job, and capture step- through traces for the failing task.
Answer: C
Explanation:
The recommended way to troubleshoot and collect detailed job logs is through the Job Run Details page in Databricks. From there, engineers can export run logs or configure automatic log delivery to a storage destination. The driver and event logs available under compute details provide stdout, stderr, and cluster lifecycle context required for root-cause analysis.
NEW QUESTION # 237
......
If you purchase our study materials to prepare the Certified-Data-Engineer-Professional Exam, your passing rate will be much higher than others. Also, the operation of our study material is smooth and flexible and the system is stable and powerful. You can install the Certified-Data-Engineer-Professional exam guide on your computers, mobile phone and other electronic devices. There are no restrictions to the number equipment you install. In short, it depends on your own choice. We sincerely hope that you can enjoy the good service of our products.
Certified-Data-Engineer-Professional Valid Exam Format: https://www.braindumpsit.com/Certified-Data-Engineer-Professional_real-exam.html
- Free PDF Quiz 2026 Perfect Databricks Certified-Data-Engineer-Professional: Valid Databricks Certified Data Engineer Professional Cram Materials 😟 Search on ✔ www.examdiscuss.com ️✔️ for ➥ Certified-Data-Engineer-Professional 🡄 to obtain exam materials for free download 🌿Simulation Certified-Data-Engineer-Professional Questions
- Updated Databricks Certified-Data-Engineer-Professional Exam Questions For Accurately Prepare [2026] 🚰 Open [ www.pdfvce.com ] and search for ✔ Certified-Data-Engineer-Professional ️✔️ to download exam materials for free ✴Certified-Data-Engineer-Professional Valid Exam Experience
- Pass Guaranteed 2026 Fantastic Databricks Certified-Data-Engineer-Professional: Valid Databricks Certified Data Engineer Professional Cram Materials 📺 Download ✔ Certified-Data-Engineer-Professional ️✔️ for free by simply searching on ⮆ www.troytecdumps.com ⮄ 🧬New Certified-Data-Engineer-Professional Test Registration
- Simulation Certified-Data-Engineer-Professional Questions 📌 Certified-Data-Engineer-Professional Valid Test Materials 🚔 Sample Certified-Data-Engineer-Professional Test Online 🎤 Immediately open ⮆ www.pdfvce.com ⮄ and search for “ Certified-Data-Engineer-Professional ” to obtain a free download 💰Valid Dumps Certified-Data-Engineer-Professional Ebook
- Certified-Data-Engineer-Professional Examinations Actual Questions 🆎 Reliable Certified-Data-Engineer-Professional Test Experience 🤗 Updated Certified-Data-Engineer-Professional CBT 🔻 Search for ✔ Certified-Data-Engineer-Professional ️✔️ and download exam materials for free through ▶ www.pass4test.com ◀ ⚗Practice Certified-Data-Engineer-Professional Exam Pdf
- Intereactive Certified-Data-Engineer-Professional Testing Engine 🤝 Flexible Certified-Data-Engineer-Professional Learning Mode 🦸 Customizable Certified-Data-Engineer-Professional Exam Mode 💻 Enter ⏩ www.pdfvce.com ⏪ and search for { Certified-Data-Engineer-Professional } to download for free ⓂFlexible Certified-Data-Engineer-Professional Learning Mode
- Pass Guaranteed 2026 Fantastic Databricks Certified-Data-Engineer-Professional: Valid Databricks Certified Data Engineer Professional Cram Materials 🍸 Search for ➤ Certified-Data-Engineer-Professional ⮘ and download exam materials for free through { www.dumpsquestion.com } 👡New Certified-Data-Engineer-Professional Exam Papers
- Valid Dumps Certified-Data-Engineer-Professional Ebook 🟣 Certified-Data-Engineer-Professional New Cram Materials 💅 Intereactive Certified-Data-Engineer-Professional Testing Engine 💲 Download ➠ Certified-Data-Engineer-Professional 🠰 for free by simply searching on ▷ www.pdfvce.com ◁ 🍜Flexible Certified-Data-Engineer-Professional Learning Mode
- Certified-Data-Engineer-Professional Valid Test Materials ⚽ Certified-Data-Engineer-Professional Valid Exam Experience 😞 Certified-Data-Engineer-Professional Examinations Actual Questions 🥡 Simply search for 【 Certified-Data-Engineer-Professional 】 for free download on { www.exam4labs.com } 🗯Practice Certified-Data-Engineer-Professional Exam Pdf
- Free PDF Pass-Sure Certified-Data-Engineer-Professional - Valid Databricks Certified Data Engineer Professional Cram Materials 🔍 The page for free download of ⇛ Certified-Data-Engineer-Professional ⇚ on 【 www.pdfvce.com 】 will open immediately 📀Simulation Certified-Data-Engineer-Professional Questions
- Get Free 365 Days Update on Databricks Certified-Data-Engineer-Professional Dumps 🏫 Search for ➡ Certified-Data-Engineer-Professional ️⬅️ and download it for free immediately on ➽ www.practicevce.com 🢪 🔅Sample Certified-Data-Engineer-Professional Test Online
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, jogajog.com.bd, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes