Unsere Garantie, Die Prüfungsfragen und Antworten zu Microsoft AI-500 (Designing and Implementing Multi-Agent AI Solutions) von EchteFrage ist eine Garantie für eine erfolgreiche Prüfung! Bisher fiel noch keiner unserer Kandidaten durch! Falls aber jemand durch die Zertifizierungsprüfung fallen sollte, zahlen wir die 100% Material-Gebühr zurück. Wir übernehmen die volle Geld-zurück-Garantie auf Ihre Zertifizierungsprüfungen! Unsere Fragen und Antoworten sind alle aus dem Fragenpool, alle sind echt und original.
| Section | Weight | Objectives |
|---|---|---|
| Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Implement observability
|
| Architect multi-agent solutions | 15–20% | - Design workflow and tool integration
|
| Secure, govern, and deploy multi-agent solutions | 20–25% | - Deploy and maintain solutions
|
| Develop multi-agent solutions in Azure | 30–35% | - Implement agents using Azure AI services
|
Egal wenn Sie irgendwelche IT-Zertifizierungsprüfung ablegen, bieten die Prüfungsunterlagen von EchteFrage Ihnen viele Hilfen, weil EchteFrage Dumps alle mögliche Fragen in den aktuellen Prüfungen und auch die ausführliche Analyse der Antworten beinhalten. Solange Sie alle Prüfungsfragen und Testantworten ernst lernen, können Sie die Microsoft AI-500 Prüfung sehr leichten bestehen.
66. Frage
You have a Microsoft Foundry multi-agent solution. The solution includes an orchestrator agent that sends a mix of simple requests, reasoning-heavy tasks, and tool-calling workflows to a single premium model deployment.
Response quality is acceptable, but costs are too high, and latency varies significantly across requests.
You need to recommend a solution to reduce token utilization based on the complexity of the user input.
What should you include in the recommendation?
Antwort: A
Begründung:
The workload mixes simple prompts, reasoning-heavy tasks, and tool-calling workflows, so a single premium model is over-provisioned for many requests. Microsoft Foundry ' s model router evaluates request complexity and routes each request to an appropriate model from a configured pool. Simple work can use lower-cost, lower-latency models, while complex reasoning can still be assigned to a more capable model.
Structured outputs constrain response format but do not reduce model capability according to request complexity. Prompt Optimizer can improve prompt quality but does not perform per-request model selection, and choosing another flagship model would preserve the same all-requests-use-premium pattern. Therefore A directly addresses the cost and latency variability by matching model capacity to workload complexity. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - Model router
67. Frage
You need to implement the business rule for claim Approval. Which workflow node should you use?
Antwort: D
Begründung:
The business rule requires human review for refunds above the stated threshold before payment can continue.
A workflow therefore needs a user or operator interaction point that pauses progress and obtains an explicit response. In the workflow options provided, Ask a question is the node that introduces that human interaction.
Invoke agent simply delegates work to another agent; it does not itself guarantee human approval. Deliver a message sends information without collecting a decision, and Go to changes control flow without obtaining authorization. Microsoft Agent Framework and Foundry workflow guidance treat human-in-the-loop approval as a first-class orchestration requirement for consequential actions. The decisive requirement is not just to notify a reviewer, but to stop automated progression until the reviewer supplies a decision. Therefore the workflow must include an interactive question/approval step before the refund-processing action can proceed for amounts over the threshold. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Microsoft Agent Framework - Human-in-the-loop workflows
68. Frage
You have a LangGraph multi-agent workflow that uses Azure Cosmos DB as a checkpointer.
You plan to change the pruning rules for the running message list before the next release You need to implement evaluations tor memory. The solution must meet the following requirements:
* Verify that claim-related state values remain correct at transition points.
* Verify that conversation context is preserved after an interruption.
* Identify the source of any loss of continuity during a run
Which three actions should you perform Each correct answer presents part of the solution NOTE: Each correct selection is worth one point.
Antwort: A,D,F
Begründung:
Memory evaluation must verify persistence across interruption, correctness of checkpointed state, and enough telemetry to locate where continuity was lost. Running a scripted multi-turn case with one stable `thread_id` before and after a restart directly tests whether the Cosmos-backed LangGraph checkpointer restores the same conversation/workflow. Comparing persisted checkpoint documents with expected state values at each handoff verifies that claim-related state has not been corrupted by the new pruning rules. Correlating the evaluation run with trace spans then provides the diagnostic path to identify which agent transition or state- management operation caused a failure. Changing the thread ID each turn would intentionally create separate state scopes, and removing durable artifacts would defeat the persistence test. Tool-call arguments alone do not prove workflow-memory continuity. Therefore D, E, and F are the complementary actions required. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Azure Cosmos DB integrations for LangGraph and agent state
69. Frage
HOTSPOT -
You have a multi-agent solution in a Microsoft Foundry project. The project is connected to an Application Insights resource.
You have the following code that implements tracing.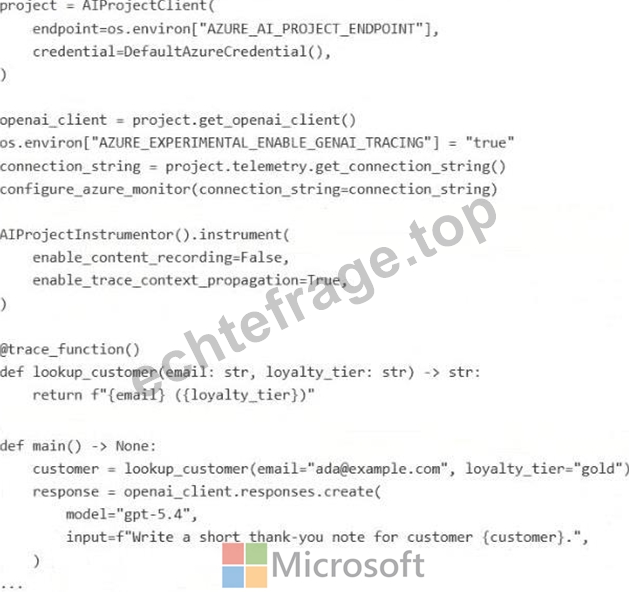
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.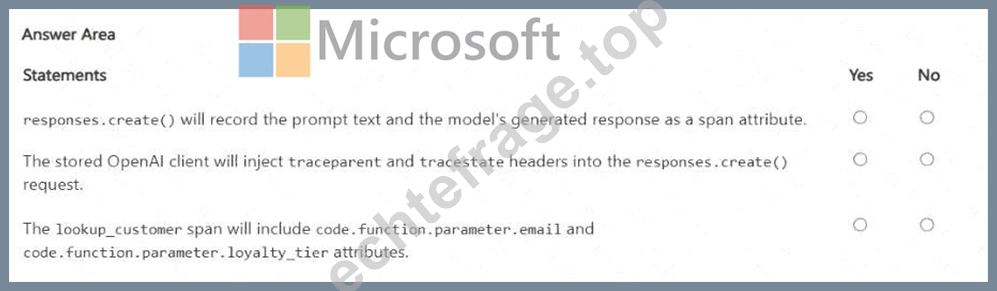
Antwort:
Begründung: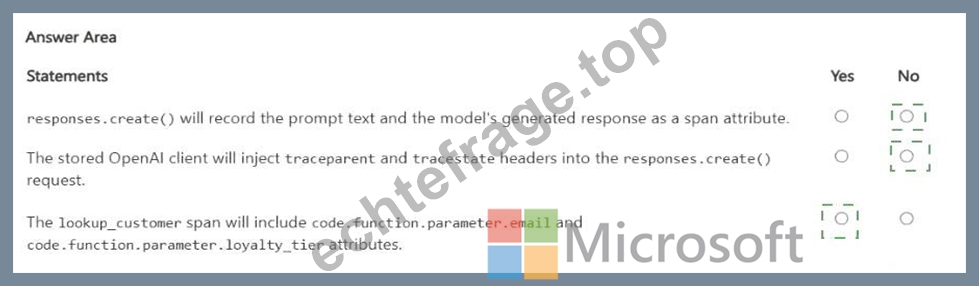
Explanation:
No / No / Yes
The first statement is false because content recording is explicitly disabled, so prompt and generated response text are not stored as GenAI span content attributes even though tracing remains active. The second is false because the OpenAI client is obtained before trace-context propagation is enabled; Microsoft documents that clients created before the instrumentation change are not retroactively configured for that propagation behavior. The third statement is true because the tracing decorator for ordinary functions records supported function parameters as `code.function.parameter. < name > ` attributes. Those parameter attributes are separate from GenAI prompt-content recording, so disabling message content does not suppress them.
Consequently `email` and `loyalty_tier` can appear on the `lookup_customer` span. The correct sequence is No, No, Yes. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - client-side agent tracing
70. Frage
You have a Microsoft Foundry multi-agent customer support solution. The solution includes an orchestrator that starts a single conversation trace when a user request arrives and can invoke two agents named Agent1 and Agent2 concurrently. Each agent can invoke Model Context Protocol (MCP)-hosted tools and dependent REST APIs.
The solution uses OpenTelemetry SDKs to emit logs, metrics, and traces via OTLP to an OpenTelemetry Collector. The solution emits the conversation ID, trace ID, and span ID for agent invocations, tool invocations, and external API calls.
You have a monitoring dashboard that includes:
* Latency
* Throughput
* Reliability
* Token usage
* Content safety triggers
* Time to First Token (TTFT)
Alert rules are configured for latency anomalies and tool invocation failures.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.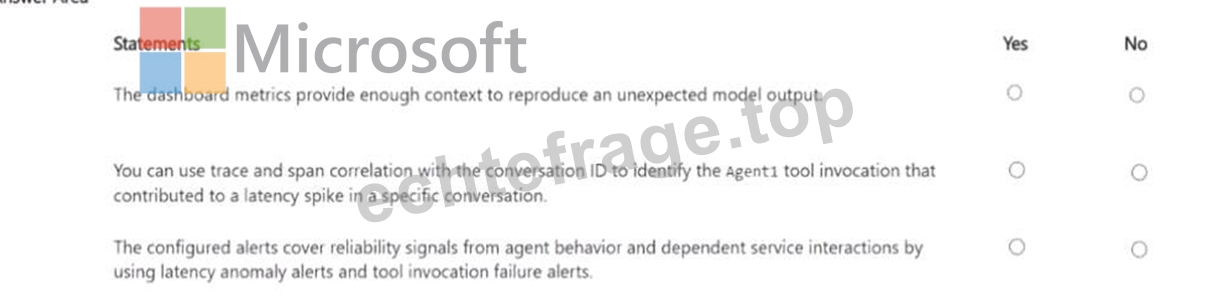
Antwort:
Begründung: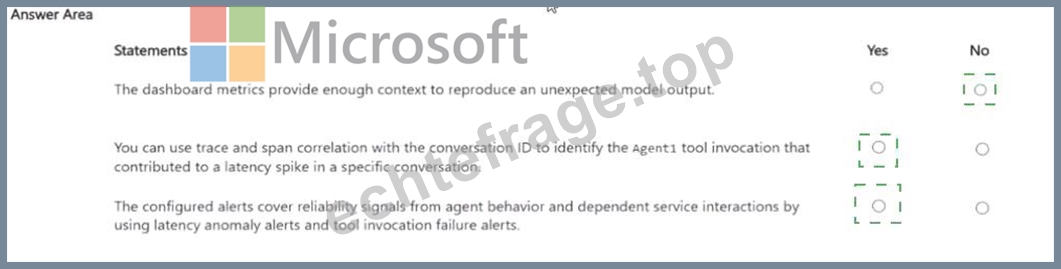
Explanation:
No / Yes / Yes
Aggregate dashboard metrics do not provide enough execution context to reproduce a specific unexpected model output, so the first statement is false. Reproduction normally requires detailed trace data such as model inputs/outputs, ordered agent spans, tool calls, and dependency results. The second statement is true because the solution emits conversation, trace, and span identifiers across agent, MCP tool, and REST API calls.
OpenTelemetry correlation can therefore isolate the Agent1 tool span that contributed to a latency spike in one conversation. The third statement is also true: latency-anomaly alerts and tool-invocation failure alerts cover important reliability signals from both agent execution and dependent service interactions. They are not the entire observability strategy, but they do address the reliability conditions described. The correct sequence is No, Yes, Yes. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - agent tracing concepts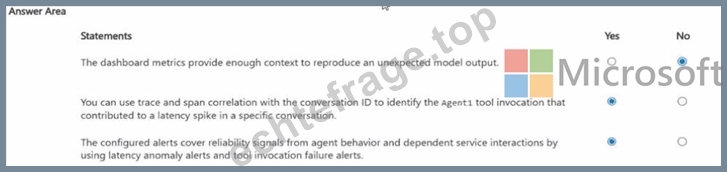
71. Frage
......
Viele IT-Leute sind sich einig, dass Microsoft AI-500 Zertifikat ein Sprungbrett zu dem Höhepunkt der IT-Branche ist. Deshalb kümmern sich viele IT-Experten um die Microsoft AI-500 Zertifizierungsprüfung.
AI-500 Simulationsfragen: https://www.echtefrage.top/AI-500-deutsch-pruefungen.html