What's more, part of that Prep4sureGuide DP-100 dumps now are free: https://drive.google.com/open?id=133W67LwSkSA40qucMF2DDTnoJddNlr5y
The Prep4sureGuide is a leading platform that is committed to offering make the Microsoft Exam Questions preparation simple, smart, and successful. To achieve this objective Prep4sureGuide has got the services of experienced and qualified Designing and Implementing a Data Science Solution on Azure (DP-100) exam trainers. They work together and put all their efforts and ensure the top standard of Prep4sureGuide Designing and Implementing a Data Science Solution on Azure (DP-100) exam dumps all the time.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and retrain models | 10-15% | - Implement retraining pipelines
|
| Topic 2: Design and prepare a machine learning solution | 20-25% | - Prepare development environments
|
| Topic 3: Prepare a model for deployment | 20-25% | - Manage deployment assets
|
| Topic 4: Explore data and train models | 35-40% | - Prepare data for modeling
|
Our DP-100 actual exam are scientific and efficient learning system for a variety of professional knowledge that is recognized by many industry experts. We have carried out the reforms according to the development of the digital devices not only on the content of our DP-100 Exam Dumps, but also on the layouts since we provide the latest and precise DP-100 information to our customers, so there is no doubt we will apply the most modern technologies to benefit our customers.
NEW QUESTION # 104
You are performing feature engineering on a dataset.
You must add a feature named CityName and populate the column value with the text London.
You need to add the new feature to the dataset.
Which Azure Machine Learning Studio module should you use?
Answer: B
Explanation:
Explanation/Reference:
Explanation:
Typical metadata changes might include marking columns as features.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/edit-metadata Testlet 1 Case study Overview You are a data scientist in a company that provides data science for professional sporting events. Models will use global and local market data to meet the following business goals:
Understand sentiment of mobile device users at sporting events based on audio from crowd reactions.
Assess a user's tendency to respond to an advertisement.
Customize styles of ads served on mobile devices.
Use video to detect penalty events
Current environment
Media used for penalty event detection will be provided by consumer devices. Media may include
images and videos captured during the sporting event and shared using social media. The images and videos will have varying sizes and formats.
The data available for model building comprises of seven years of sporting event media. The sporting
event media includes; recorded video transcripts or radio commentary, and logs from related social media feeds captured during the sporting events.
Crowd sentiment will include audio recordings submitted by event attendees in both mono and stereo
formats.
Penalty detection and sentiment
Data scientists must build an intelligent solution by using multiple machine learning models for penalty
event detection.
Data scientists must build notebooks in a local environment using automatic feature engineering and
model building in machine learning pipelines.
Notebooks must be deployed to retrain by using Spark instances with dynamic worker allocation.
Notebooks must execute with the same code on new Spark instances to recode only the source of the
data.
Global penalty detection models must be trained by using dynamic runtime graph computation during
training.
Local penalty detection models must be written by using BrainScript.
Experiments for local crowd sentiment models must combine local penalty detection data.
Crowd sentiment models must identify known sounds such as cheers and known catch phrases.
Individual crowd sentiment models will detect similar sounds.
All shared features for local models are continuous variables.
Shared features must use double precision. Subsequent layers must have aggregate running mean
and standard deviation metrics available.
Advertisements
During the initial weeks in production, the following was observed:
Ad response rated declined.
Drops were not consistent across ad styles.
The distribution of features across training and production data are not consistent
Analysis shows that, of the 100 numeric features on user location and behavior, the 47 features that come from location sources are being used as raw features. A suggested experiment to remedy the bias and variance issue is to engineer 10 linearly uncorrelated features.
Initial data discovery shows a wide range of densities of target states in training data used for crowd
sentiment models.
All penalty detection models show inference phases using a Stochastic Gradient Descent (SGD) are
running too slow.
Audio samples show that the length of a catch phrase varies between 25%-47% depending on region
The performance of the global penalty detection models shows lower variance but higher bias when
comparing training and validation sets. Before implementing any feature changes, you must confirm the bias and variance using all training and validation cases.
Ad response models must be trained at the beginning of each event and applied during the sporting
event.
Market segmentation models must optimize for similar ad response history.
Sampling must guarantee mutual and collective exclusively between local and global segmentation
models that share the same features.
Local market segmentation models will be applied before determining a user's propensity to respond to
an advertisement.
Ad response models must support non-linear boundaries of features.
The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviated
from 0.1 +/- 5%.
The ad propensity model uses cost factors shown in the following diagram: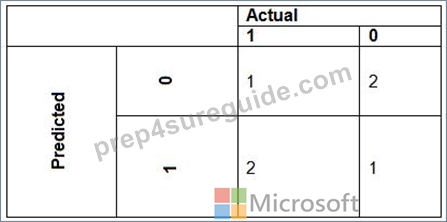
The ad propensity model uses proposed cost factors shown in the following diagram: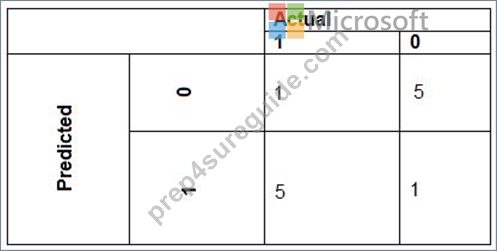
Performance curves of current and proposed cost factor scenarios are shown in the following diagram: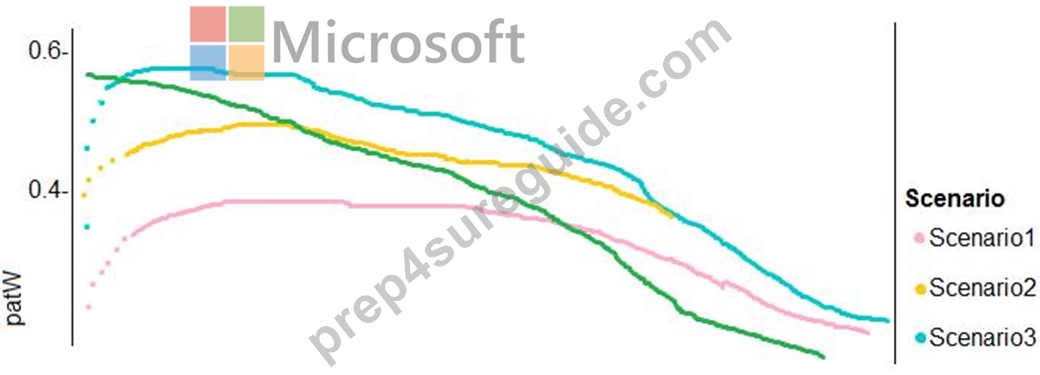
NEW QUESTION # 105
You have a feature set containing the following numerical features: X, Y, and Z.
The Poisson correlation coefficient (r-value) of X, Y, and Z features is shown in the following image: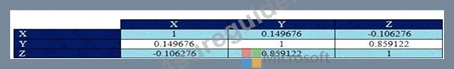
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.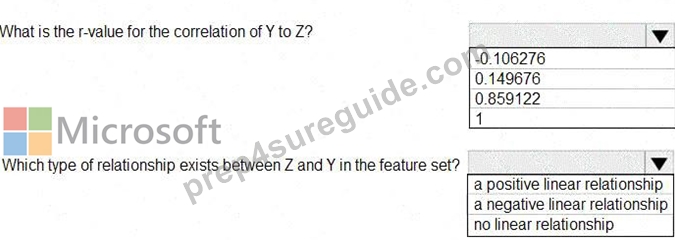
Answer:
Explanation: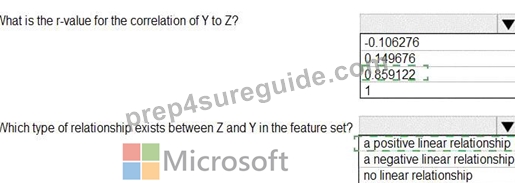
Explanation: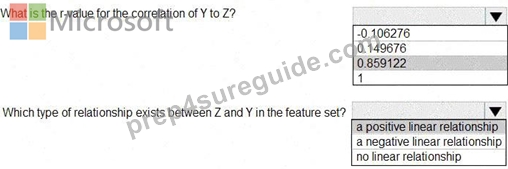
Box 1: 0.859122
Box 2: a positively linear relationship
+1 indicates a strong positive linear relationship
-1 indicates a strong negative linear correlation
0 denotes no linear relationship between the two variables.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/compute-linear-correlation
NEW QUESTION # 106
You are creating a machine learning model that can predict the species of a penguin from its measurements.
You have a file that contains measurements for free species of penguin in comma delimited format.
The model must be optimized for area under the received operating characteristic curve performance metric averaged for each class.
You need to use the Automated Machine Learning user interface in Azure Machine Learning studio to run an experiment and find the best performing model.
Which five actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the collect order.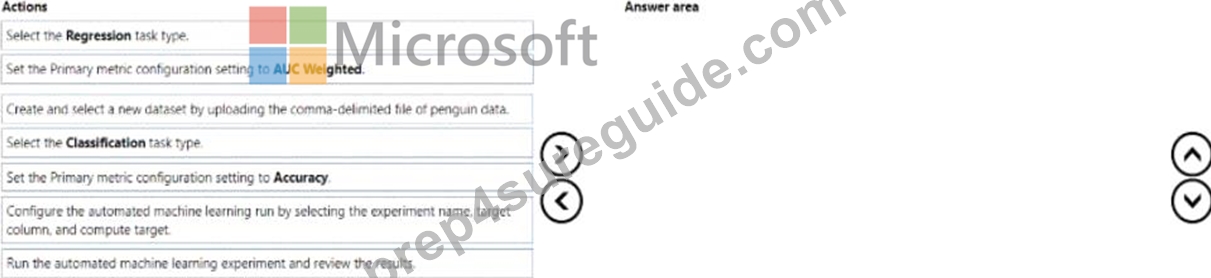
Answer:
Explanation: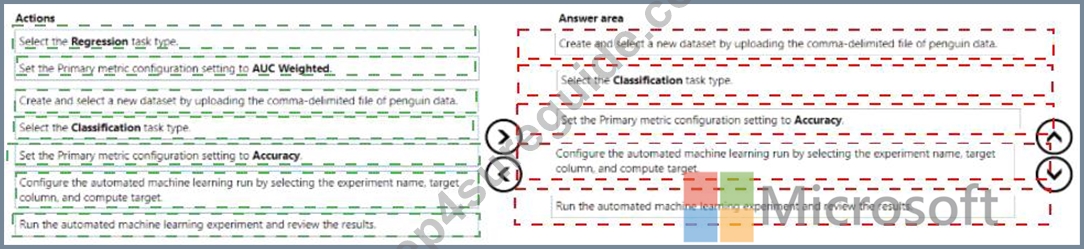
Explanation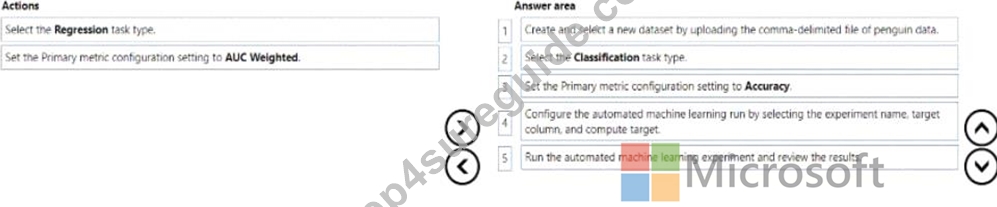
NEW QUESTION # 107
You have an Azure Machine Learning workspace that contains a CPU-based compute cluster and an Azure Kubernetes Services (AKS) inference cluster. You create a tabular dataset containing data that you plan to use to create a classification model.
You need to use the Azure Machine Learning designer to create a web service through which client applications can consume the classification model by submitting new data and getting an immediate prediction as a response.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.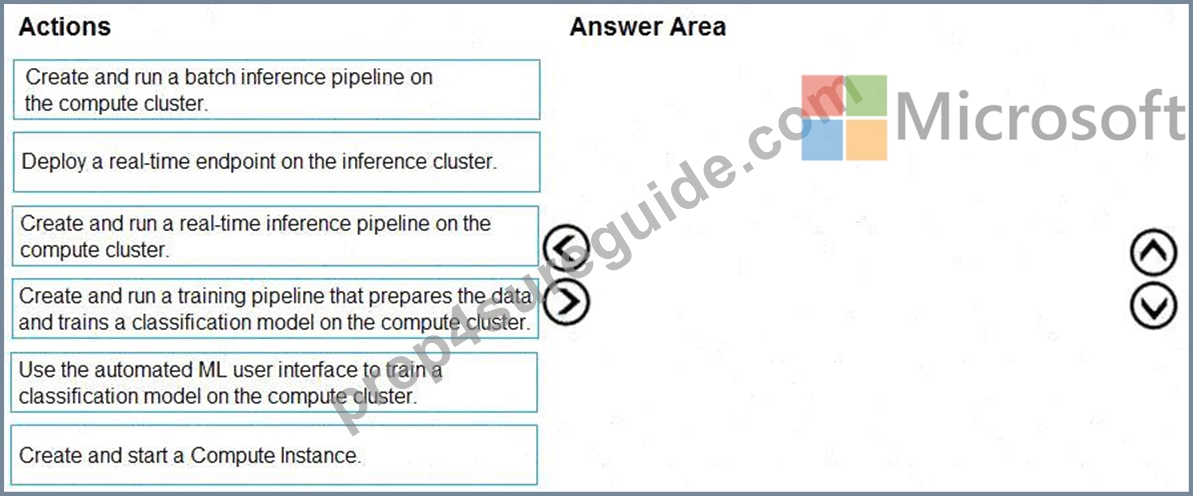
Answer:
Explanation: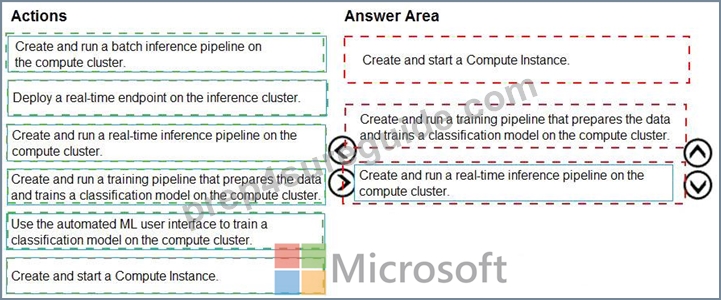
Explanation: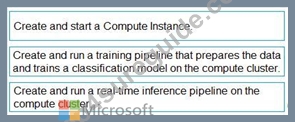
Step 1: Create and start a Compute Instance
To train and deploy models using Azure Machine Learning designer, you need compute on which to run the training process, test the model, and host the model in a deployed service.
There are four kinds of compute resource you can create:
Compute Instances: Development workstations that data scientists can use to work with data and models.
Compute Clusters: Scalable clusters of virtual machines for on-demand processing of experiment code.
Inference Clusters: Deployment targets for predictive services that use your trained models.
Attached Compute: Links to existing Azure compute resources, such as Virtual Machines or Azure Databricks clusters.
Step 2: Create and run a training pipeline..
After you ' ve used data transformations to prepare the data, you can use it to train a machine learning model.
Create and run a training pipeline
Step 3: Create and run a real-time inference pipeline
After creating and running a pipeline to train the model, you need a second pipeline that performs the same data transformations for new data, and then uses the trained model to inference (in other words, predict) label values based on its features. This pipeline will form the basis for a predictive service that you can publish for applications to use.
Reference:
https://docs.microsoft.com/en-us/learn/modules/create-classification-model-azure-machine-learning-designer/
NEW QUESTION # 108
You are creating a new Azure Machine Learning pipeline using the designer.
The pipeline must train a model using data in a comma-separated values (CSV) file that is published on a website. You have not created a dataset for this file.
You need to ingest the data from the CSV file into the designer pipeline using the minimal administrative effort.
Which module should you add to the pipeline in Designer?
Answer: A
Explanation:
Explanation
The preferred way to provide data to a pipeline is a Dataset object. The Dataset object points to data that lives in or is accessible from a datastore or at a Web URL. The Dataset class is abstract, so you will create an instance of either a FileDataset (referring to one or more files) or a TabularDataset that's created by from one or more files with delimited columns of data.
Example:
from azureml.core import Dataset
iris_tabular_dataset = Dataset.Tabular.from_delimited_files([(def_blob_store, 'train-dataset/iris.csv')]) Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-create-your-first-pipeline
NEW QUESTION # 109
......
If you want to pass your exam and get your certification, we can make sure that our DP-100 guide questions will be your ideal choice. Our company will provide you with professional team, high quality service and reasonable price. In order to help customers solve problems, our company always insist on putting them first and providing valued service. We deeply believe that our DP-100 question torrent will help you pass the exam and get your certification successfully in a short time. Maybe you cannot wait to understand our DP-100 Guide questions; we can promise that our products have a higher quality when compared with other study materials. At the moment I am willing to show our DP-100 guide torrents to you, and I can make a bet that you will be fond of our products if you understand it.
Reliable DP-100 Exam Pdf: https://www.prep4sureguide.com/DP-100-prep4sure-exam-guide.html
BONUS!!! Download part of Prep4sureGuide DP-100 dumps for free: https://drive.google.com/open?id=133W67LwSkSA40qucMF2DDTnoJddNlr5y