P.S. Free & New HPE7-J01 dumps are available on Google Drive shared by BraindumpsPrep: https://drive.google.com/open?id=17O5sQ0F9DC8TaIvOTFhar_injLxnMfZ-
When you click into BraindumpsPrep's site, you will see so many people daily enter the website. You can not help but be surprised. In fact, this is normal. BraindumpsPrep is provide different training materials for alot of candidates. They are using our training materials tto pass the exam. This shows that our HP HPE7-J01 Exam Training materials can really play a role. If you want to buy, then do not miss BraindumpsPrep website, you will be very satisfied.
| Section | Weight | Objectives |
|---|---|---|
| HPE Storage Solutions Management | 20% | - Implement performance optimization strategies - Manage and monitor storage infrastructure using HPE tools - Perform capacity planning and reporting - Configure quality of service (QoS) |
| Troubleshooting HPE Storage Solutions | 15% | - Perform health checks and diagnostics - Resolve data protection and replication issues - Diagnose storage connectivity issues - Troubleshoot performance bottlenecks |
| Architecting HPE Storage Solutions | 35% | - Design block, file, and object storage solutions - Design HPE StoreOnce solutions for backup and recovery - Design HPE Cloud Bank target solutions - Design HPE Nimble Storage solutions - Design HPEPrimera and HPE 3PAR StoreServ solutions |
| HPE Storage Solutions Integration | 30% | - Integrate HPE Primera and HPE 3PAR with SAN infrastructure - Integrate with cloud providers (AWS, Azure, GCP) - Implement data protection and disaster recovery - Integrate HPE Nimble Storage with network environments - Integrate HPE StoreOnce with backup software |
>> Reliable HPE7-J01 Test Review <<
One can start using product of BraindumpsPrep instantly after buying. The 24/7 support system is available for the customers so that they don't stick to any problems. If they do so, they can contact the support system, which will assist them in the right way and solve their issues. A lot of Advanced HPE Storage Architect Solutions Written Exam (HPE7-J01) exam applicants have used the Advanced HPE Storage Architect Solutions Written Exam (HPE7-J01) practice material. They are satisfied with it because it is updated.
NEW QUESTION # 28
Which statement is correct regarding the HPE Timeless Program for the HPE Alletra Storage MP solutions?
Answer: A
Explanation:
The HPE Timeless Program is a strategic lifecycle management offering designed to future-proof customer investments in the HPE Alletra Storage MP platform (specifically the B10000 for Block).
The program provides benefits such as a non-disruptive controller refresh at no additional cost after three or more years, all-inclusive software licensing, and a 100% data availability guarantee.
To qualify for the HPE Timeless Program, the storage configuration must meet specific minimum hardware requirements to ensure it can support future generations of controller technology without a "forklift" upgrade. According to the HPE Master ASE Advanced Storage Architect training materials and program guidelines, the entry-level qualification for the Timeless benefit on Alletra MP requires the system to be configured with at least 16-core controller nodes (CNodes) and a minimum capacity threshold of 42TB RAW storage.
While the Alletra MP architecture supports 8-core, 16-core, and 32-core nodes, the 8-core "entry" models are often excluded from certain enterprise-level refresh programs because they may not provide sufficient overhead for the performance requirements of next-generation operating systems.
NEW QUESTION # 29
A company with 2484 VMs and 300 servers needs to implement a file, object, and block storage solution.
What are the minimum requirements for this solution?
Answer: D
Explanation:
The HPE Alletra MP is a modular, disaggregated storage platform designed to provide different storage personas (Block or File/Object) based on the software stack installed on the controller nodes. However, the minimum hardware "footprint" required to form a functional, supported cluster differs significantly between these personas.
For HPE GreenLake for File Storage (which utilizes the Alletra MP X10000 hardware and provides both File and Object protocols), the architecture is based on a disaggregated shared-everything (DASE) model.
According to the HPE Alletra MP Installation and Architecture Guide, the minimum supported configuration for a File/Object cluster is three X10000 controller nodes. This 3-node minimum is a hard requirement to establish proper quorum and high availability for the V-Tree metadata and the distributed file system logic. A single X10000 node (as suggested in Options A and C) cannot function as a standalone file
/object cluster in a production environment.
Furthermore, the Alletra MP X10000 persona is specifically optimized for high-density unstructured data (File and Object). While the B10000 persona (Options A, B, and C) is intended for Block storage, the question asks for a solution that covers file, object, and block. In many modern software-defined or unified scenarios, especially those aligned with the Alletra MP's future-proof roadmap, the X10000 hardware can serve multiple personas. However, strictly following the current architectural minimums for the File/Object requirement mentioned, you must have at least three nodes. Therefore, a 3-node cluster of X10000s is the foundational requirement to even begin providing the file and object services the customer needs. Options A and B fail the minimum cluster size requirement for the File/Object persona.
NEW QUESTION # 30
Match the Brocade virtual fabric term with its description.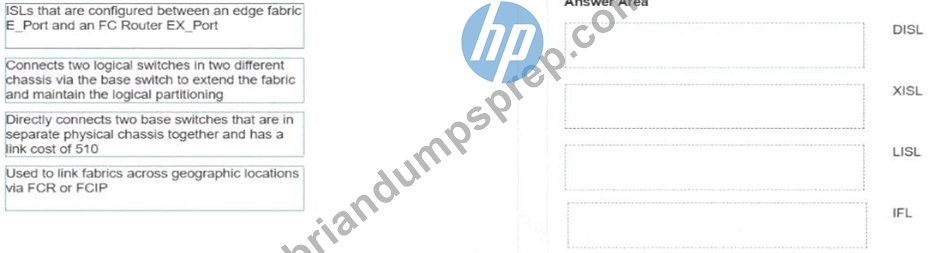
Answer:
Explanation: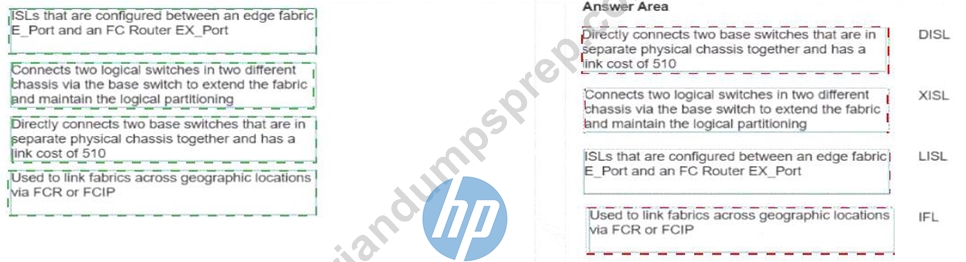
Explanation:
LISL: Directly connects two base switches that are in separate physical chassis together and has a link cost of
510
XISL: Connects two logical switches in two different chassis via the base switch to extend the fabric and maintain the logical partitioning DISL: ISLs that are configured between an edge fabric E_Port and an FC Router EX_Port IFL: Used to link fabrics across geographic locations via FCR or FCIP Brocade Virtual Fabrics (VF) allow a single physical switch to be partitioned into multiple logical switches, each with its own data and control planes. This architectural flexibility requires specialized Inter-Switch Link (ISL) types to maintain logical isolation across physical chassis.
LISL (Logical ISL): These are logical links that directly connect two Base Switches located in separate physical chassis. A defining characteristic of an LISL in Brocade Fabric OS is its default link cost of 510, which ensures it is typically used only for specific inter-fabric control traffic unless manually adjusted.
XISL (Extended ISL): An XISL is a transport link used to connect two logical switches residing in different physical chassis by tunneling through the Base Fabric. This allows the administrator to extend a single logical fabric across multiple physical devices while maintaining strict logical partitioning and reducing the number of physical cables required between chassis.
DISL (Dedicated ISL): These links are specifically configured between an edge fabric E_Port and an FC Router EX_Port. They are used in Fibre Channel Routing (FCR) topologies to provide a dedicated path for inter-fabric traffic between a standard fabric and a meta-fabric router.
IFL (Inter-Fabric Link): IFLs are the foundational links used to connect disparate fabrics across geographic locations. They utilize either Fibre Channel Routing (FCR) or FCIP tunneling to enable communication between devices in different fabrics without merging them into a single logical entity. This is a key component for large-scale disaster recovery and data distribution architectures where fabric stability and distance are primary concerns.
NEW QUESTION # 31
What will occur when a new node is added to an existing HPE Alletra MP X10000 storage array?
Answer: C
Explanation:
The HPE Alletra MP X10000 is an object and file storage solution utilizing a Disaggregated Shared- Everything (DASE) architecture. A key differentiator of this disaggregated design is the stateless nature of the controller nodes and the centralized management of the data plane. When a cluster expansion occurs--such as adding a new controller node or an additional JBOF (Just a Bunch of Flash) storage shelf--the system is designed to automatically optimize the workload distribution. According to the HPE Alletra MP Architectural Guide, adding an additional JBOF or drives triggers an automatic rebalancing of the data stripes. Unlike older architectures where manual rebalancing services were required (such as in the 3PAR/B10000 block lineage), the X10000 uses a sophisticated hashing mechanism.
Specifically, data is distributed across DSPs (Data Storage Processors) which are virtualized management units. Upon the addition of hardware, these DSPs are rebalanced across the available compute and storage resources in a matter of seconds. Because the nodes are stateless and state is persisted only within the JBOFs, this rebalancing happens with minimal performance impact and no need for the massive "data movement" traditionally associated with expanding a RAID group. This ensures that as a customer scales from the minimum of 3 nodes up to 8 or more, the system always maintains an optimal load balance and utilizes all available flash bandwidth and compute cycles in parallel.
NEW QUESTION # 32
Which statement is correct regarding Fibre Channel over IP (FCIP)?
Answer: C
Explanation:
Fibre Channel over IP (FCIP), as defined by IETF RFC 3821, is a tunneling protocol used to interconnect Fibre Channel (FC) storage area networks (SANs) over long distances using standard IP infrastructure. One of the primary architectural reasons for choosing FCIP over native Fibre Channel extension is its ability to overcome distance constraints.
Native Fibre Channel is governed by a flow-control mechanism called Buffer-to-Buffer (BB) Credits. In a native FC link, a frame cannot be sent until the sender has a "credit" from the receiver. As the distance between sites increases, the time it takes for an acknowledgment (and thus the return of a credit) to travel back significantly increases. This creates a "protocol drop-off" where performance collapses once the distance exceeds the available buffer memory. In contrast, FCIP encapsulates FC frames into TCP/IP segments. TCP/IP uses a different flow- control mechanism called windowing.
By moving the transport to TCP/IP, the storage traffic is no longer strictly bound by the physical light-propagation constraints of the FC buffer-credit mechanism. While latency still increases with distance (governed by the speed of light in fiber), FCIP provides no fixed protocol distance limitation, making it possible to replicate data across continents or globally (asynchronous replication) as long as the IP network provides a path.
NEW QUESTION # 33
......
We know that HPE7-J01 exam is very important for you working in the IT industry, so we developed the HPE7-J01 test software that will bring you a great help. All exam materials you you need are provided by our team, and we have carried out the scientific arrangement and analysis only to relieve your pressure and burden in preparation for HPE7-J01 Exam.
Exam HPE7-J01 Details: https://www.briandumpsprep.com/HPE7-J01-prep-exam-braindumps.html
DOWNLOAD the newest BraindumpsPrep HPE7-J01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=17O5sQ0F9DC8TaIvOTFhar_injLxnMfZ-