NCP-AIO Exam Demo & NCP-AIO Exam Cram Questions

P.S. Free 2026 NVIDIA NCP-AIO dumps are available on Google Drive shared by DumpsKing: https://drive.google.com/open?id=19G_lHajMyNWhVAnMgyesPOcfV0CBAlYV
if you want to have a better experience on the real exam before you go to attend it, you can choose to use the software version of our NCP-AIO learning guide which can simulate the real exam, and you can download our NCP-AIO exam prep on more than one computer. We strongly believe that the software version of our NCP-AIO Study Materials will be of great importance for you to prepare for the exam and all of the employees in our company wish you early success.
| Topic | Details |
|---|
| Topic 1 | - Workload Management: This section of the exam measures the skills of AI infrastructure engineers and focuses on managing workloads effectively in AI environments. It evaluates the ability to administer Kubernetes clusters, maintain workload efficiency, and apply system management tools to troubleshoot operational issues. Emphasis is placed on ensuring that workloads run smoothly across different environments in alignment with NVIDIA technologies.
|
| Topic 2 | - Administration: This section of the exam measures the skills of system administrators and covers essential tasks in managing AI workloads within data centers. Candidates are expected to understand fleet command, Slurm cluster management, and overall data center architecture specific to AI environments. It also includes knowledge of Base Command Manager (BCM), cluster provisioning, Run.ai administration, and configuration of Multi-Instance GPU (MIG) for both AI and high-performance computing applications.
|
| Topic 3 | - Installation and Deployment: This section of the exam measures the skills of system administrators and addresses core practices for installing and deploying infrastructure. Candidates are tested on installing and configuring Base Command Manager, initializing Kubernetes on NVIDIA hosts, and deploying containers from NVIDIA NGC as well as cloud VMI containers. The section also covers understanding storage requirements in AI data centers and deploying DOCA services on DPU Arm processors, ensuring robust setup of AI-driven environments.
|
| Topic 4 | - Troubleshooting and Optimization: NVIThis section of the exam measures the skills of AI infrastructure engineers and focuses on diagnosing and resolving technical issues that arise in advanced AI systems. Topics include troubleshooting Docker, the Fabric Manager service for NVIDIA NVlink and NVSwitch systems, Base Command Manager, and Magnum IO components. Candidates must also demonstrate the ability to identify and solve storage performance issues, ensuring optimized performance across AI workloads.
|
>> NCP-AIO Exam Demo <<
NCP-AIO Exam Demo - 100% Pass Quiz NVIDIA NCP-AIO - NVIDIA AI Operations First-grade Exam Cram Questions
Our NCP-AIO practice test software contains multiple learning tools that will help you pass the NVIDIA AI Operations in the first attempt. We provide actual NCP-AIO questions pdf dumps also for quick practice. Our NCP-AIO vce products are easy to use, and you can simply turn things around by going through all the NVIDIA AI Operations exam material to ensure your success in the exam. Our NCP-AIO Pdf Dumps will help you prepare for the NVIDIA AI Operations even when you are at work.
NVIDIA AI Operations Sample Questions (Q47-Q52):
NEW QUESTION # 47
You are tasked with implementing data versioning and reproducibility for AI experiments. Which storage features or technologies are most relevant?
- A. Snapshots and cloning capabilities of the storage system.
- B. Integration with version control systems like Git for data.
- C. Replication for disaster recovery
- D. Data compression algorithms for minimizing storage footprint.
- E. Encryption for security
Answer: A,B
Explanation:
Snapshots and cloning allow you to create consistent copies of data at specific points in time, facilitating reproducibility. Integrating with version control systems enables tracking changes to data and code together, ensuring experiments can be recreated accurately. While compression, replication, and encryption are important, they are not directly related to versioning and reproducibility.
NEW QUESTION # 48
You have a Kubernetes cluster with several nodes equipped with NVIDIA GPUs. You want to ensure that pods requesting GPUs are only scheduled on nodes that have the appropriate NVIDIA drivers and the NVIDIA Container Toolkit installed. Which Kubernetes feature(s) can you leverage to achieve this?
- A. Network policies and ingress controllers.
- B. Resource quotas and limit ranges.
- C. Pod priority and preemption.
- D. Taints and tolerations.
- E. Node affinity and tolerations.
Answer: D,E
Explanation:
The correct answers are A and E. Taints and Tolerations ensure that pods are not scheduled onto inappropriate nodes. Nodes can be tainted to indicate the lack of NVIDIA drivers or the Container Toolkit, and pods requiring GPUs can tolerate these taints to indicate their compatibility. Node Affinity, in tandem with taints, provides more fine-grained control over scheduling. You can use node affinity to prefer or require that pods with GPU requests are scheduled on nodes labeled with specific NVIDIA hardware or driver versions. Options B, C, and D are not directly relevant to GPU-aware scheduling.
NEW QUESTION # 49
A user submits a Slurm job script with the following options:
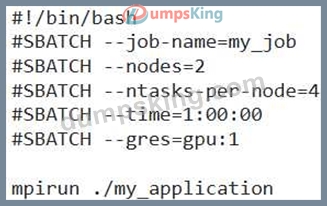
Assuming each node has 4 GPUs, how many GPU resources will be allocated to this job across the entire cluster?
Answer: C
Explanation:
The job requests 2 nodes (nodes=2) and one GPU per node Therefore, a total of 2 GPUs (2 nodes 1 GPU/node) will be allocated to the job.
NEW QUESTION # 50
You are designing a data center that must support both interactive AI development and large-scale batch training jobs. You want to maximize GPU utilization while ensuring that interactive users have a responsive experience. Which of the following strategies is MOST effective?
- A. Run all workloads on a single large GPU server to simplify management.
- B. Allocate dedicated GPUs to interactive users and run batch jobs on idle CPUs.
- C. Use NVIDIA MPS (Multi-Process Service) to allow interactive users and batch jobs to share GPUs concurrently, and implement QOS to prioritize interactive workloads.
- D. Oversubscribe all GPUs to maximize utilization, even if it degrades interactive performance.
- E. Schedule batch jobs to run only during off-peak hours when interactive users are not active.
Answer: C
Explanation:
NVIDIA MPS allows multiple processes to share a GPU concurrently, which maximizes utilization. QOS ensures that interactive workloads receive priority, maintaining a responsive experience. Dedicated GPUs for interactive users wastes resources when they are idle. Scheduling batch jobs for off-peak hours is limiting and inefficient. Oversubscribing without QOS can severely impact interactive performance. Running all workloads on a single server creates a single point of failure and limits scalability.
NEW QUESTION # 51
An AI model serving application is deployed on a multi-GPU server using Triton Inference Server. You notice that one GPU is consistently underutilized compared to the others. Which of the following could be contributing factors and how could you troubleshoot them?
- A. One of the GPUs might be experiencing hardware issues. Use 'nvidia-smi' to monitor GPU health metrics like temperature and ECC errors.
- B. The load balancer distributing requests to Triton might not be evenly distributing the load across all GPUs. Examine the load balancer's configuration and metrics.
- C. The NVIDIA driver version is outdated. Upgrade it.
- D. The server's CPU is underpowered.
- E. The model configuration in Triton might be pinning specific models to specific GPUs. Check the 'config.pbtxt file for 'instance_group' settings.
Answer: A,B,E
Explanation:
Triton allows pinning models to specific GPUs, so the configuration should be checked (A). Hardware issues (B) can cause underutilization, so GPU health should be monitored. An uneven load distribution from the load balancer (C) can also lead to underutilization of some GPUs. While an outdated driver or an underpowered CPU might impact overall performance, they are less likely to cause such a specific imbalance in GPU utilization.
NEW QUESTION # 52
......
DumpsKing serves as a most important source of IT certification information. You can find learning materials and study guides. If you are interesting in our DumpsKing NVIDIA NCP-AIO exam dumps, you can depend on our DumpsKing to make a sound choice. DumpsKing NVIDIA NCP-AIO test packed so much with the latest information about the certification training. By using our DumpsKing NVIDIA NCP-AIO practice test, you have made preparations for the exam.
NCP-AIO Exam Cram Questions: https://www.dumpsking.com/NCP-AIO-testking-dumps.html
- Complete NCP-AIO Exam Demo - First-Grade NCP-AIO Exam Cram Questions - Efficient NVIDIA NVIDIA AI Operations 👑 Open ➠ www.vce4dumps.com 🠰 enter ➽ NCP-AIO 🢪 and obtain a free download 🦰Reliable NCP-AIO Exam Question
- NCP-AIO Valid Test Forum 👕 NCP-AIO Training Materials 🛒 NCP-AIO Latest Exam Format ⏫ Easily obtain 《 NCP-AIO 》 for free download through ➽ www.pdfvce.com 🢪 🖋NCP-AIO Valid Test Forum
- NCP-AIO Hottest Certification 🏬 NCP-AIO Study Group 🥌 Authorized NCP-AIO Certification 🤎 Easily obtain free download of ➥ NCP-AIO 🡄 by searching on ➥ www.vce4dumps.com 🡄 🏉Reliable NCP-AIO Exam Question
- NCP-AIO Certification Torrent 🌅 NCP-AIO Training Materials 😼 NCP-AIO Pass Exam 🕛 Immediately open 《 www.pdfvce.com 》 and search for ⏩ NCP-AIO ⏪ to obtain a free download ⛺NCP-AIO Training Materials
- Top Features of www.troytecdumps.com Updated NCP-AIO Exam Practice Questions 🧞 Simply search for ➽ NCP-AIO 🢪 for free download on ▶ www.troytecdumps.com ◀ ‼NCP-AIO Passing Score Feedback
- Valid Braindumps NCP-AIO Free 🃏 Free NCP-AIO Vce Dumps 🛤 NCP-AIO Valid Test Forum 🥩 Search for “ NCP-AIO ” and download it for free on ➽ www.pdfvce.com 🢪 website ❓NCP-AIO Valid Test Forum
- NVIDIA AI Operations dumps torrent - NCP-AIO exam pdf - NVIDIA AI Operations study practice 🖖 Open “ www.troytecdumps.com ” enter 《 NCP-AIO 》 and obtain a free download 🏯Valid NCP-AIO Exam Vce
- NCP-AIO Latest Exam Online ⬅ NCP-AIO Latest Braindumps Ebook 🐸 NCP-AIO Certification Torrent 💌 Go to website ➥ www.pdfvce.com 🡄 open and search for ( NCP-AIO ) to download for free 💫NCP-AIO Certification Torrent
- Complete NCP-AIO Exam Demo - First-Grade NCP-AIO Exam Cram Questions - Efficient NVIDIA NVIDIA AI Operations Ⓜ Search for ➡ NCP-AIO ️⬅️ and obtain a free download on ⮆ www.exam4labs.com ⮄ 🐛NCP-AIO Training Materials
- NCP-AIO Training Materials 💆 NCP-AIO Passing Score Feedback 🤠 NCP-AIO Valid Test Forum 🦏 Search for [ NCP-AIO ] and easily obtain a free download on ➥ www.pdfvce.com 🡄 🍰Valid Braindumps NCP-AIO Free
- NCP-AIO Training Materials 🎫 NCP-AIO Training Materials 🦊 Free NCP-AIO Vce Dumps 🐜 Download ➥ NCP-AIO 🡄 for free by simply searching on ( www.testkingpass.com ) 📔NCP-AIO Pass Exam
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! Download part of DumpsKing NCP-AIO dumps for free: https://drive.google.com/open?id=19G_lHajMyNWhVAnMgyesPOcfV0CBAlYV