P.S. Free 2026 Microsoft AI-103 dumps are available on Google Drive shared by Prep4sureExam: https://drive.google.com/open?id=1hbbP04lH8R74e3bryDSCQYt2TCvw_bvB
Up to now we classify our AI-103 exam questions as three different versions. They are pdf, software and the most convenient one APP online. Though the content of these three versions is the same, but their displays are different. Each of them has their respective feature and advantage including new information that you need to know to pass the AI-103 test. So you can choose the version of AI-103 training quiz according to your personal preference.
| Section | Weight | Objectives |
|---|---|---|
| Implement agentic solutions | 20-25% | - Build AI agents
|
| Implement text analysis and information extraction solutions | 10-15% | - Analyze and extract information
|
| Implement generative AI solutions | 25-30% | - Optimize and evaluate models
|
| Implement computer vision solutions | 10-15% | - Analyze visual content
|
| Plan and manage Azure AI solutions | 25-30% | - Plan Azure AI resources
|
>> Test AI-103 Questions Vce <<
simulation tests of our AI-103 learning materials have the functions of timing and mocking exams, which will allow you to adapt to the exam environment in advance and it will be of great benefit for subsequent exams. After you complete the learning task, the system of our AI-103 test prep will generate statistical reports based on your performance so that you can identify your weaknesses and conduct targeted training and develop your own learning plan. For the complex part of our AI-103 Exam Question, you may be too cumbersome, but our system has explained and analyzed this according to the actual situation to eliminate your doubts and make you learn better.
NEW QUESTION # 89
You have a Microsoft Foundry project that contains an agent.
The agent uses Azure AI Search for Retrieval Augmented Generation (RAG).
You plan to ingest and index PDF product manuals.
You need to build a solution that supports semantic similarity matching. The solution must ensure that the agent retrieves relevant data when user questions use different wording than the product manuals.
Which indexing approach should you use?
Answer: C
Explanation:
Vector search is the correct indexing and retrieval type to use for this solution.
Vector search versus semantic ranking
While both features help bridge the gap between different wordings, vector search is specifically designed at the indexing and retrieval layer to handle semantic similarity matching by converting text into mathematical vectors (embeddings) based on conceptual meaning. Semantic ranking is a secondary re-ranking layer applied after initial retrieval to improve precision, but it cannot function as the primary indexing method on its own.
Reference:
https://www.scribd.com/document/866453317/Agentforce-Specialist
NEW QUESTION # 90
You have an application named App1 that uses Azure Speech in Foundry Tools to transcribe live calls.
Transcript segments often contain both English and Spanish. App1 sends each segment to Azure Translator in Foundry Tools to translate to another language.
Sometimes, mixed-language segments result in incomplete or incorrect translations.
You need to reduce translation errors. The solution must ensure that the entire transcript is translated successfully.
What should you do before sending the segments to Translator?
Answer: C
Explanation:
The correct answer is C. Split the mixed-language segments into single-language segments and translate each segment separately . Azure Translator has a known limitation for text that contains mixed-language input within the same sentence or segment. Microsoft's Translator known-issues guidance states that the Text translation API does not support translating sentences that contain mixed-language text and that translations can be incorrect or incomplete when a single sentence includes multiple languages. The documented workaround is to specify the intended source language, remove the mixed-language sentence, or split the text into single-language segments.
In this scenario, specifying English for all segments would fail when Spanish content is present. Automatic language detection can detect a dominant language, but it does not reliably solve a segment that contains both English and Spanish. Document translation is also not the right fix because the issue is mixed-language content inside transcript segments, and Microsoft notes similar incomplete results for mixed-source-language documents. Splitting the transcript into language-homogeneous segments ensures each translation request has a clear source language and lets the entire transcript be translated reliably. Reference topics: Azure Translator in Foundry Tools, text translation, language detection, mixed-language input, and transcript preprocessing.
NEW QUESTION # 91
You have a Microsoft Azure AI Foundry project named Project1.
You plan to create an app named App1 that will connect to Project1 and chat by using a generative AI model.
You need to connect App1 to Project1 by using the Azure AI Foundry SDK. The solution must minimize development effort.
What should you configure in App1?
Answer: C
Explanation:
To minimize development effort when using the Azure AI Foundry SDK, you should configure the AIProjectClient object using the project connection string.
This approach is highly efficient because the connection string is a single string that encapsulates multiple required parameters--such as the subscription ID, resource group name, and project name--allowing the client to initialize and authenticate with minimal code.
How to Configure the AIProjectClient
1. Retrieve Connection String: In the Azure AI Foundry portal, go to the Overview page of your project. Under Project details, copy the Project connection string.
2. Initialize the Client: Use the from_connection_string method (or equivalent initialization depending on SDK version) to create the client.
Minimal Code Example (Python)
import os
from azure.ai.projects import AIProjectClient
from azure.identity import DefaultAzureCredential
# Load the connection string from an environment variable for security
conn_str = os.environ["PROJECT_CONNECTION_STRING"]
# Load the connection string from an environment variable for security
conn_str = os.environ["PROJECT_CONNECTION_STRING"]
Reference:
https://workshop.aifoundry.app/1-introduction/3-quick_start
NEW QUESTION # 92
You have a Microsoft Foundry project that processes procurement documents submitted by suppliers.
You need to implement two pipelines by using Azure Content Understanding in Foundry Tools. The solution must meet the following requirements:
* Include a pipeline named Pipeline1 that supports cost-effective, high-volume processing of standalone PDF invoices.
* Include a pipeline named Pipeline2 that supports cross-document validation by using multi-step reasoning and reference data.
How should you configure each pipeline? To answer, drag the appropriate configurations to the correct pipelines. Each configuration may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.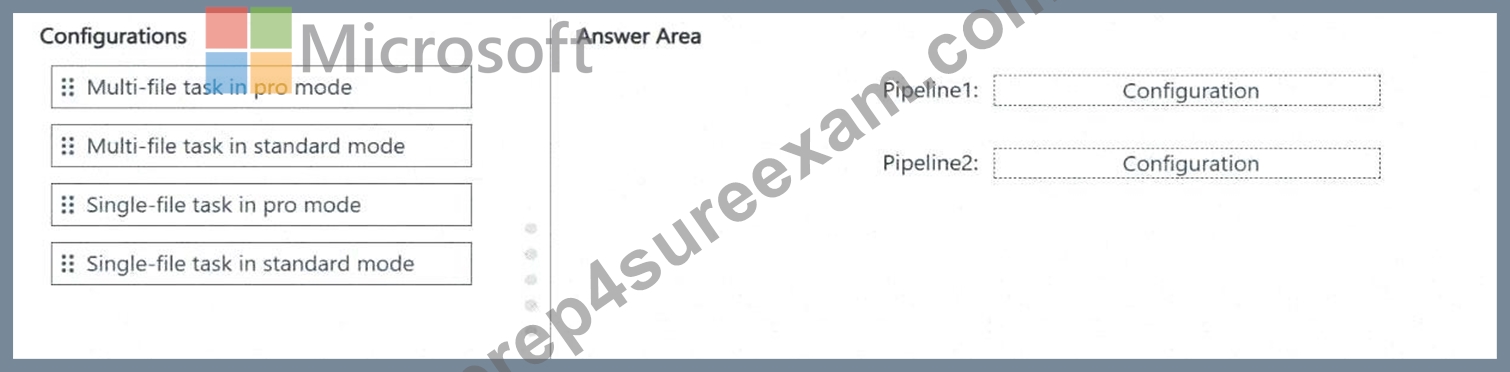
Answer:
Explanation: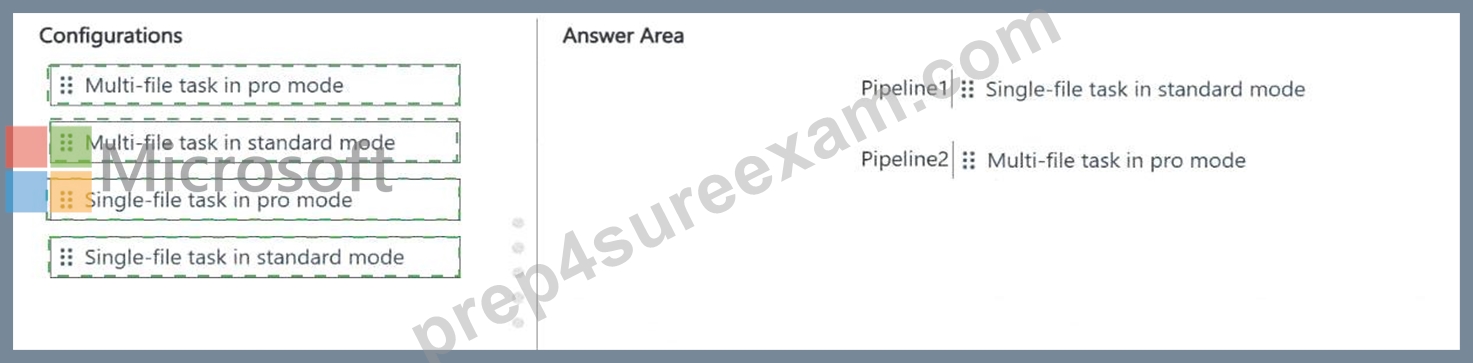
Explanation:
Pipeline1: Single-file task in standard mode
Pipeline2: Multi-file task in pro mode
Pipeline1 should use a single-file task in standard mode because the workload is high-volume processing of standalone PDF invoices. Azure Content Understanding standard mode is intended for individual files that require straightforward structured extraction, and Microsoft describes it as minimizing cost and latency for broad, data-centric processing scenarios. This makes it the best fit for cost-effective invoice extraction where each PDF can be processed independently.
Pipeline2 should use a multi-file task in pro mode because the requirement includes cross-document validation, multi-step reasoning, and reference data. Microsoft guidance states that pro mode is designed for advanced scenarios requiring multi-step reasoning and cross-file analysis, including processing multiple input files in a single request, validating or enriching data across documents, and using reference data to guide extraction and validation.
Single-file pro mode would add unnecessary capability for Pipeline1 and would not optimize for cost- effective high-volume standalone processing. Multi-file standard mode does not meet the pro-mode requirement for reference-data-based reasoning. Reference topics: Azure Content Understanding standard mode, pro mode, single-file tasks, multi-file tasks, field extraction, and procurement document validation.
NEW QUESTION # 93
You plan to deploy a containerized version of an Azure Al Language service that will be used for sentiment analysis.
You configure https: //contoso.cognitiveservices.azure, cow as the endpoint URI for the service.
You need to run the container on an Azure virtual machine by using Docker.
How should you complete the command? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.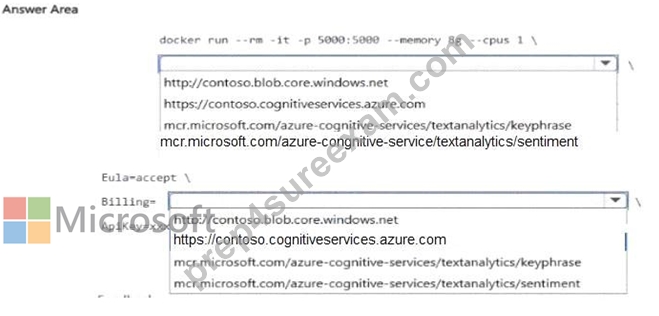
Answer:
Explanation: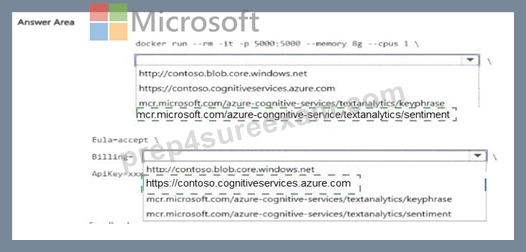
Explanation:
First selection:
mcr.microsoft.com/azure-cognitive-services/textanalytics/sentiment
Second selection:
https://contoso.cognitiveservices.azure.com
Completed command:
docker run --rm -it -p 5000:5000 --memory 8g --cpus 1 \
mcr.microsoft.com/azure-cognitive-services/textanalytics/sentiment \
Eula=accept \
Billing=https://contoso.cognitiveservices.azure.com \
ApiKey=xxx
The image mcr.microsoft.com/azure-cognitive-services/textanalytics/sentiment is the official Microsoft Container Registry image for Azure AI Language sentiment analysis. The Billing argument must reference the endpoint of the provisioned Azure AI Language resource associated with the supplied API key. It is not the address used by applications to invoke the locally running container.
Azure
AI containers require three licensing and metering parameters: Eula=accept, a valid Billing endpoint, and ApiKey. Without all three values, the container does not start. The command maps host port 5000 to container port 5000, allocates 8 GB of memory and one CPU, creates an interactive terminal, and automatically removes the stopped container. Applications subsequently invoke the locally hosted service through an address such as http://
< vm-address > :5000. The Azure endpoint remains responsible for metering and authentication; analyzed customer text is processed by the container rather than sent to the billing endpoint.
Study Guide alignment: Implement text analysis solutions - perform sentiment analysis and opinion mining, deploy Azure Language containers, and configure container billing parameters.
NEW QUESTION # 94
......
Because Microsoft AI-103 exam is concerning the future and the destiny of IT people, they pay more attention to the certification. When you decide to choosing IT industry, you have proved your ability. However, what we learn is not enough at all. Microsoft AI-103 Certification will be a big challenge for the candidates. If you decide to join our Prep4sureExam, we guarantee your success in the first attempt. If you fail, FULL REFUND!
AI-103 Exam Bootcamp: https://www.prep4sureexam.com/AI-103-dumps-torrent.html
What's more, part of that Prep4sureExam AI-103 dumps now are free: https://drive.google.com/open?id=1hbbP04lH8R74e3bryDSCQYt2TCvw_bvB