What's more, part of that ITCertMagic Databricks-Certified-Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1plp1iwwUa1wk4cu24kaZXCxOxUoLmyxH
Even though our Databricks-Certified-Data-Engineer-Associate training materials have received quick sale all around the world, in order to help as many candidates for the exam as possible to pass the Databricks-Certified-Data-Engineer-Associate exam, we still keep the most favorable price for our best Databricks-Certified-Data-Engineer-Associate test prep. In addition, if you keep a close eye on our website you will find that we will provide discount in some important festivals, we can assure you that you can use the least amount of money to buy the best product in here. We aim at providing the best Databricks-Certified-Data-Engineer-Associate Exam Engine for our customers and at trying our best to get your satisfaction.
The Databricks Databricks-Certified-Data-Engineer-Associate Exam is conducted online and consists of 80 multiple-choice questions. The duration of the exam is 2 hours, and candidates must achieve a minimum score of 60% to pass. Databricks-Certified-Data-Engineer-Associate exam fee is $300, and candidates can schedule their exam at any time through the GAQM website. Databricks Certified Data Engineer Associate Exam certification is valid for three years and can be renewed by passing the latest version of the exam.
>> Databricks-Certified-Data-Engineer-Associate Braindumps Downloads <<
Another outstanding quality is that you can print out the Databricks Databricks-Certified-Data-Engineer-Associate questions. The hard copy will enable you to prepare for the Databricks Databricks-Certified-Data-Engineer-Associate exam questions comfortably. ITCertMagic adds another favor to its users by ensuring them a money-back deal. The unparalleled authority of the ITCertMagic lies in its mission to provide its users with the updated material of the actual Databricks Databricks-Certified-Data-Engineer-Associate Certification Exam.
Databricks Certified Data Engineer Associate certification exam covers topics such as data engineering concepts, data ingestion, data processing, data storage, and data transformation using Apache Spark and Delta Lake. Candidates who Pass Databricks-Certified-Data-Engineer-Associate Exam will have a deep understanding of the Databricks platform and will be able to design, build, and maintain data pipelines that are scalable, reliable, and efficient. Databricks Certified Data Engineer Associate Exam certification is ideal for data engineers, data analysts, and data scientists who work with big data and want to enhance their skills and advance their careers.
NEW QUESTION # 243
A data engineer is preparing a Declarative Automation Bundle, formerly known as a Databricks Asset Bundle, to deploy a Lakeflow pipeline.
To ensure that the pipeline is deployed to the correct environment, where should workspace-specific configurations, such as the workspace host URL and root storage path, be defined within the bundle project?
Answer: D
Explanation:
Workspace-specific deployment settings should be defined under each environment in the targets section of databricks.yml. A bundle target represents a deployment environment such as development, staging, or production. Each target can contain its own workspace mapping, including the workspace host and an optional root_path. This structure allows one bundle codebase to be deployed predictably to different environments without embedding infrastructure details in notebooks or pipeline source code. A README file is documentation and is not interpreted as bundle configuration. Hardcoding workspace details in Python couples transformation logic to a particular environment. Global local environment variables are machine-specific and do not provide a complete, version-controlled bundle definition. Therefore, option C correctly places the workspace-specific settings in the declarative configuration used during validation and deployment.
NEW QUESTION # 244
What can be used to simplify and unify siloed data architectures that are specialized for specific use cases?
Answer: B
Explanation:
A data lakehouse is a unified architecture that combines the best features of data lakes and data warehouses. It simplifies and unifies siloed data architectures by allowing both structured and unstructured data to coexist in the same system, supporting a wide variety of use cases, such as analytics, machine learning, and business intelligence.
Data lakes are good for storing large amounts of raw data but lack the structure and performance needed for high-performance analytics.
Data warehouses are designed for structured data and analytics but aren't optimized for large volumes of unstructured or semi-structured data.
Delta Lake is a storage layer that brings reliability to data lakes, but a lakehouse is the broader architecture that unifies these approaches.
NEW QUESTION # 245
In which of the following scenarios should a data engineer use the MERGE INTO command instead of the INSERT INTO command?
Answer: E
Explanation:
The MERGE INTO command is used to perform upserts, which are a combination of insertions and updates, based on a source table into a target Delta table1. The MERGE INTO command can handle scenarios where the target table cannot contain duplicate records, such as when there is a primary key or a unique constraint on the target table. The MERGE INTO command can match the source and target rows based on a merge condition and perform different actions depending on whether the rows are matched or not. For example, the MERGE INTO command can update the existing target rows with the new source values, insert the new source rows that do not exist in the target table, or delete the target rows that do not exist in the source table1.
The INSERT INTO command is used to append new rows to an existing table or create a new table from a query result2. The INSERT INTO command does not perform any updates or deletions on the existing target table rows. The INSERT INTO command can handle scenarios where the location of the data needs to be changed, such as when the data needs to be moved from one table to another, or when the data needs to be partitioned by a certain column2. The INSERT INTO command can also handle scenarios where the target table is an external table, such as when the data is stored in an external storage system like Amazon S3 or Azure Blob Storage3. The INSERT INTO command can also handle scenarios where the source table can be deleted, such as when the source table is a temporary table or a view4. The INSERT INTO command can also handle scenarios where the source is not a Delta table, such as when the source is a Parquet, CSV, JSON, or Avro file5.
Reference:
1: MERGE INTO | Databricks on AWS
2: [INSERT INTO | Databricks on AWS]
3: [External tables | Databricks on AWS]
4: [Temporary views | Databricks on AWS]
5: [Data sources | Databricks on AWS]
NEW QUESTION # 246
A data engineer needs to create a table in Databricks using data from a CSV file at location /path/to/csv.
They run the following command: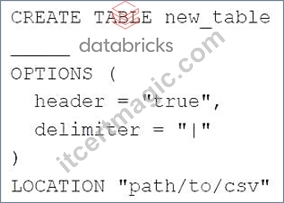
Which of the following lines of code fills in the above blank to successfully complete the task?
Answer: C
Explanation:
A data lakehouse is a new paradigm that can be used to simplify and unify siloed data architectures that are specialized for specific use cases. A data lakehouse combines the best of both data lakes and data warehouses, providing a single platform that supports diverse data types, open standards, low-cost storage, high-performance queries, ACID transactions, schema enforcement, and governance. A data lakehouse enables data engineers to build reliable and scalable data pipelines that can serve various downstream applications and users, such as data science, machine learning, analytics, and reporting. A data lakehouse leverages the power of Delta Lake, a storage layer that brings reliability and performance to data lakes. References: What is a data lakehouse?, Delta Lake, Lakehouse: A New Generation of Open Platforms that Unify Data Warehousing and Advanced Analytics
NEW QUESTION # 247
Which of the following is hosted completely in the control plane of the classic Databricks architecture?
Answer: B
Explanation:
Explanation
In the classic Databricks architecture, the control plane includes components like the Databricks web application, the Databricks REST API, and the Databricks Workspace. These components are responsible for managing and controlling the Databricks environment, including cluster provisioning, notebook management, access control, and job scheduling. The other options, such as worker nodes, JDBC data sources, Databricks Filesystem (DBFS), and driver nodes, are typically part of the data plane or the execution environment, which is separate from the control plane. Worker nodes are responsible for executing tasks and computations, JDBC data sources are used to connect to external databases, DBFS is a distributed file system for data storage, and driver nodes are responsible for coordinating the execution of Spark jobs.
NEW QUESTION # 248
......
Test Databricks-Certified-Data-Engineer-Associate Dumps Demo: https://www.itcertmagic.com/Databricks/real-Databricks-Certified-Data-Engineer-Associate-exam-prep-dumps.html
DOWNLOAD the newest ITCertMagic Databricks-Certified-Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1plp1iwwUa1wk4cu24kaZXCxOxUoLmyxH