P.S. Free 2026 Databricks Databricks-Certified-Data-Engineer-Associate dumps are available on Google Drive shared by VCE4Plus: https://drive.google.com/open?id=1Z7R9OgDBNo4PGjy1OqZ-Z5SwqJk5sgMN
The VCE4Plus team regularly revises the Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) PDF version to add new questions and update Databricksmation, so candidates are always up-to-date. We provide candidates with comprehensive Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam questions with up to 1 year of free updates. If you are doubtful, feel free to download a free demo of VCE4Plus Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) PDF dumps, desktop practice exam software, and web-based Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) practice exam. Don't wait. Purchase Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam dumps at an affordable price and start preparing for the updated Databricks Databricks-Certified-Data-Engineer-Associate certification exam today.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Data Engineer Associate Exam |
| Exam Number: | DE-A |
| Related Certifications: | Databricks Certified Data Engineer Professional |
| Exam Format: | Proctored online or test center, Multiple-choice, Scenario-based questions |
| Exam Duration: | 90 minutes |
| Available Languages: | English |
| Certificate Validity Period: | 2 years |
| Passing Score: | Approximately ~70% (not officially fixed/publicly guaranteed) |
| Exam Price: | USD 200 |
| Real Exam Qty: | 45 scored multiple-choice questions |
| Recommended Training: | Databricks Data Engineering Learning Path (Databricks Academy) Official Data Engineering with Databricks Course |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Certified-Data-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored exam or test center |
| Pre Condition: | No formal prerequisites required; recommended ~6 months hands-on experience with Databricks, Spark SQL, and PySpark. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-engineer-associate |
>> Databricks-Certified-Data-Engineer-Associate Valid Guide Files <<
It will provide you with the Databricks Databricks-Certified-Data-Engineer-Associate dumps latest updates until 365 days after purchasing the Databricks-Certified-Data-Engineer-Associate exam questions. Above all, you will obtain these updates entirely free if the Databricks Databricks-Certified-Data-Engineer-Associate certification authorities issue fresh updates. VCE4Plus ensures that you will hold the prestigious Databricks Databricks-Certified-Data-Engineer-Associate certificate on the first endeavor if you work consistently, taking help from our remarkable, up-to-date, and competitive Databricks Databricks-Certified-Data-Engineer-Associate dumps.
Databricks Certified Data Engineer Associate exam covers a wide range of topics, including data ingestion, data transformation, data storage, and data processing. Databricks-Certified-Data-Engineer-Associate Exam is designed to test the skills and knowledge of candidates in using Databricks to build and optimize data pipelines. Databricks Certified Data Engineer Associate Exam certification exam also tests the knowledge of candidates in working with Databricks to perform data transformations and store data in a variety of formats. Successful candidates will have a deep understanding of Databricks and its capabilities, and will be able to use this knowledge to build efficient and effective data pipelines.
NEW QUESTION # 273
Which Databricks SQL predicate correctly performs a null-safe equality comparison so that rows are matched when both sides are NULL or when both are equal non-NULL values?
Answer: A
Explanation:
Databricks SQL uses the null-safe equality operator <=>. It returns TRUE when both values are NULL or when both non-NULL values are equal. The operator must be written without spaces:
customer_id <=> :cid.
NEW QUESTION # 274
A data engineer wants to create a new table containing the names of customers that live in France.
They have written the following command: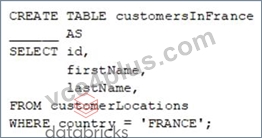
A senior data engineer mentions that it is organization policy to include a table property indicating that the new table includes personally identifiable information (PII).
Which of the following lines of code fills in the above blank to successfully complete the task?
Answer: A
Explanation:
Explanation
Ref:https://www.databricks.com/discover/pages/data-quality-management
CREATE TABLE my_table (id INT COMMENT 'Unique Identification Number', name STRING COMMENT 'PII', age INT COMMENT 'PII') TBLPROPERTIES ('contains_pii'=True) COMMENT 'Contains PII';
NEW QUESTION # 275
Which of the following describes a scenario in which a data engineer will want to use a single-node cluster?
Answer: E
Explanation:
The scenario in which a data engineer will want to use a single-node cluster is when they are working interactively with a small amount of data. A single-node cluster is a cluster consisting of an Apache Spark driver and no Spark workers1. A single-node cluster supports Spark jobs and all Spark data sources, including Delta Lake1. A single-node cluster is helpful for single-node machine learning workloads that use Spark to load and save data, and for lightweight exploratory data analysis1. A single-node cluster can run Spark locally, spawn one executor thread per logical core in the cluster, and save all log output in the driver log1. A single-node cluster can be created by selecting the Single Node button when configuring a cluster1.
The other options are not suitable for using a single-node cluster. When running automated reports to be refreshed as quickly as possible, a data engineer will want to use a multi-node cluster that can scale up and down automatically based on the workload demand2. When working with SQL within Databricks SQL, a data engineer will want to use a SQL Endpoint that can execute SQL queries on a serverless pool or an existing cluster3. When concerned about the ability to automatically scale with larger data, a data engineer will want to use a multi-node cluster that can leverage the Databricks Lakehouse Platform and the Delta Engine to handle large-scale data processing efficiently and reliably4. When manually running reports with a large amount of data, a data engineer will want to use a multi-node cluster that can distribute the computation across multiple workers and leverage the Spark UI to monitor the performance and troubleshoot the issues.
References:
* 1: Single Node clusters | Databricks on AWS
* 2: Autoscaling | Databricks on AWS
* 3: SQL Endpoints | Databricks on AWS
* 4: Databricks Lakehouse Platform | Databricks on AWS
* : [Spark UI | Databricks on AWS]
NEW QUESTION # 276
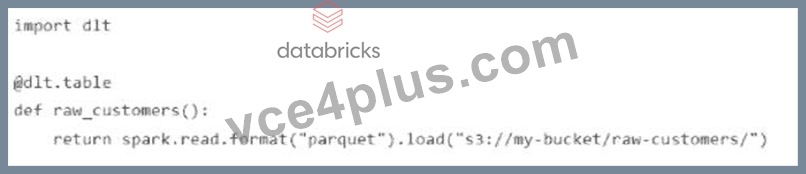
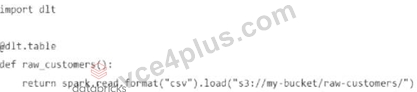
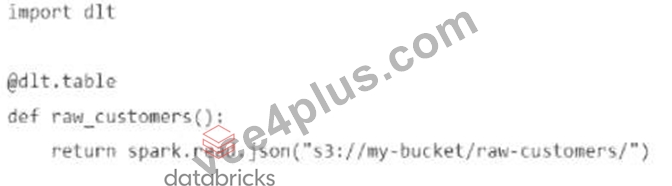
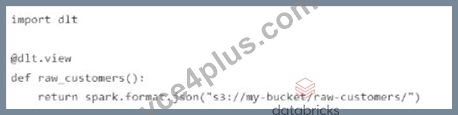
A Data Engineer is building a simple data pipeline using Delta Live Tables (DLT) in Databricksto ingest customer data. The raw customer data is stored in a cloud storage location in JSON format. The task is to create a DLT pipeline that reads the rawJSON data and writes it into a Delta table for further processing.
Which code snippet will correctly ingest the raw JSON data and create a Delta table using DLT?
Answer: C
NEW QUESTION # 277
A Delta Live Table pipeline includes two datasets defined using STREAMING LIVE TABLE. Three datasets are defined against Delta Lake table sources using LIVE TABLE.
The table is configured to run in Development mode using the Continuous Pipeline Mode.
Assuming previously unprocessed data exists and all definitions are valid, what is the expected outcome after clicking Start to update the pipeline?
Answer: A
Explanation:
The Continuous Pipeline Mode for Delta Live Tables allows the pipeline to run continuously and process data as it arrives. This mode is suitable for streaming ingest and CDC workloads that require low-latency updates.
The Development mode for Delta Live Tables allows the pipeline to run on a dedicated cluster that is not shared with other pipelines. This mode is useful for testing and debugging the pipeline logic before deploying it to production. Therefore, the correct answer is B, because the pipeline will run continuously on a dedicated cluster until it is manually stopped, and the compute resources will be released only after the pipeline is shut down. References: Databricks Documentation - Configure pipeline settings for Delta Live Tables, Databricks Documentation - Continuous vs. triggered pipeline execution, Databricks Documentation - Development vs.
production mode.
NEW QUESTION # 278
......
Study Databricks-Certified-Data-Engineer-Associate Plan: https://www.vce4plus.com/Databricks/Databricks-Certified-Data-Engineer-Associate-valid-vce-dumps.html
DOWNLOAD the newest VCE4Plus Databricks-Certified-Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1Z7R9OgDBNo4PGjy1OqZ-Z5SwqJk5sgMN