P.S. Free 2026 Google Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by Prep4pass: https://drive.google.com/open?id=14GgI_AAs7VE2Se3Mn8sRyoShkyUbGDBZ
We Prep4pass offer the best high-pass-rate Professional-Machine-Learning-Engineer training materials which help thousands of candidates to clear exams and gain their dreaming certifications. The more outstanding or important the certification is, the fiercer the competition will be. Our Professional-Machine-Learning-Engineer practice materials will be your winning magic to help you stand out easily. Our Professional-Machine-Learning-Engineer Study Guide contains most key knowledge of the real test which helps you prepare efficiently. If you pursue 100% pass rate, our Professional-Machine-Learning-Engineer exam questions and answers will help you clear for sure with only 20 to 30 hours' studying.
| Section | Objectives |
|---|---|
| Topic 1: Deployment and operations | - Monitoring and maintenance
|
| Topic 2: ML model development | - Model training and tuning
|
| Topic 3: Data preparation and processing | - Data ingestion and pipelines
|
| Topic 4: ML pipeline automation and orchestration | - Pipeline design
|
| Topic 5: Designing ML solutions | - ML architecture design
|
>> Professional-Machine-Learning-Engineer Associate Level Exam <<
Are you still worrying about how to safely pass Google certification Professional-Machine-Learning-Engineer exams? Do you have thought to select a specific training? Choosing a good training can effectively help you quickly consolidate a lot of IT knowledge, so you can be well ready for Google certification Professional-Machine-Learning-Engineer exam. Prep4pass's expert team used their experience and knowledge unremitting efforts to do research of the previous years exam, and finally have developed the best pertinence training program about Google Certification Professional-Machine-Learning-Engineer Exam. Our training program can effectively help you have a good preparation for Google certification Professional-Machine-Learning-Engineer exam. Prep4pass's training program will be your best choice.
NEW QUESTION # 298
As the lead ML Engineer for your company, you are responsible for building ML models to digitize scanned customer forms. You have developed a TensorFlow model that converts the scanned images into text and stores them in Cloud Storage. You need to use your ML model on the aggregated data collected at the end of each day with minimal manual intervention. What should you do?
Answer: B
NEW QUESTION # 299
You work for a manufacturing company. You need to train a custom image classification model to detect product detects at the end of an assembly line. Although your model is performing well, some images in your holdout set are consistently mislabeled with high confidence. You want to use Vertex Al to understand your models results. What should you do?
Answer: B
NEW QUESTION # 300
You are developing a recommendation engine for an online clothing store. The historical customer transaction data is stored in BigQuery and Cloud Storage. You need to perform exploratory data analysis (EDA), preprocessing and model training. You plan to rerun these EDA, preprocessing, and training steps as you experiment with different types of algorithms. You want to minimize the cost and development effort of running these steps as you experiment. How should you configure the environment?
Answer: A
Explanation:
A Vertex AI Workbench managed notebook is a fully integrated development environment (IDE) that allows you to access BigQuery and Cloud Storage data sources directly from the JupyterLab interface. You can use the BigQuery UI extension or the %%bigquery magic commands to query the tables, and use the Cloud Storage UI extension or the %%gcs magic commands to access the files. You can also use the built-in tools and libraries for EDA, preprocessing, and model training, such as TensorFlow, scikit-learn, pandas, and matplotlib. A managed notebook is a cost-effective and convenient option, as you do not need to provision or manage the underlying VM instance, and you can scale up or down the machine type as needed. You can also leverage the Vertex AI platform features, such as custom training, hyperparameter tuning, and model deployment, from within the notebook.
References:
* Vertex AI Workbench documentation
* BigQuery UI extension for JupyterLab
* Cloud Storage UI extension for JupyterLab
* Vertex AI platform documentation
NEW QUESTION # 301
You are developing a model to predict whether a failure will occur in a critical machine part.
You have a dataset consisting of a multivariate time series and labels indicating whether the machine part failed.
You recently started experimenting with a few different preprocessing and modeling approaches in a Vertex Al Workbench notebook.
You want to log data and track artifacts from each run.
How should you set up your experiments?
Answer: A
Explanation:
The option A is the most suitable solution for logging data and tracking artifacts from each run of a model development experiment in a Vertex AI Workbench notebook. Vertex AI Workbench is a service that allows you to create and run interactive notebooks on Google Cloud. You can use Vertex AI Workbench to experiment with different preprocessing and modeling approaches for your time series prediction problem.
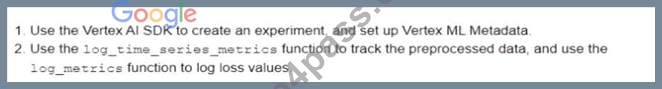
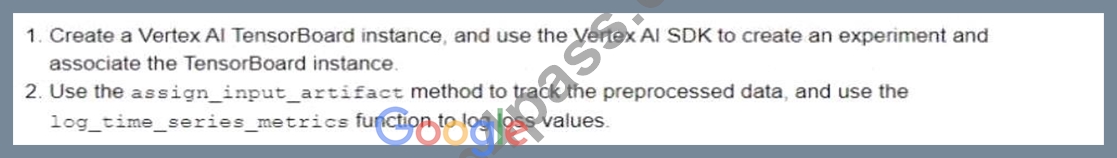
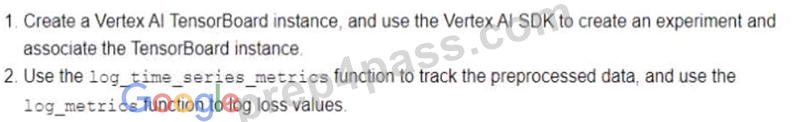
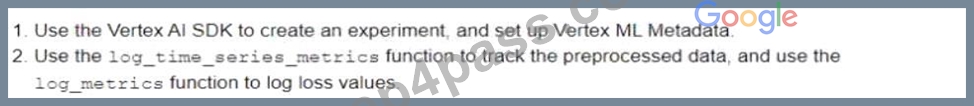
You can also use the Vertex AI TensorBoard instance and the Vertex AI SDK to create an experiment and associate the TensorBoard instance. TensorBoard is a tool that allows you to visualize and monitor the metrics and artifacts of your ML experiments. You can use the Vertex AI SDK to create an experiment object, which is a logical grouping of runs that share a common objective. You can also use the Vertex AI SDK to associate the experiment object with a TensorBoard instance, which is a managed service that hosts a TensorBoard web app. By using the Vertex AI TensorBoard instance and the Vertex AI SDK, you can easily set up and manage your experiments, and access the TensorBoard web app from the Vertex AI console. You can also use the log_time_series_metrics function and the log_metrics function to log data and track artifacts from each run.
The log_time_series_metrics function is a function that allows you to log the time series data, such as the multivariate time series and the labels, to the TensorBoard instance. The log_metrics function is a function that allows you to log the scalar metrics, such as the loss values, to the TensorBoard instance. By using these functions, you can record the data and artifacts from each run of your experiment, and compare them in the TensorBoard web app. You can also use the TensorBoard web app to visualize the data and artifacts, such as the time series plots, the scalar charts, the histograms, and the distributions. By using the Vertex AI TensorBoard instance, the Vertex AI SDK, and the log functions, you can log data and track artifacts from each run of your experiment in a Vertex AI Workbench notebook. References:
* Vertex AI Workbench documentation
* Vertex AI TensorBoard documentation
* Vertex AI SDK documentation
* log_time_series_metrics function documentation
* log_metrics function documentation
* [Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate]
NEW QUESTION # 302
Your team is working on an NLP research project to predict political affiliation of authors based on articles they have written. You have a large training dataset that is structured like this: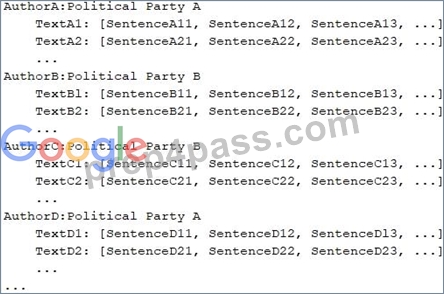
You followed the standard 80%-10%-10% data distribution across the training, testing, and evaluation subsets. How should you distribute the training examples across the train-test-eval subsets while maintaining the 80-10-10 proportion?
Answer: C
Explanation:
If we just put inside the Training set, Validation set and Test set, randomly Text, Paragraph or sentences the model will have the ability to learn specific qualities about The Author's use of language beyond just his own articles. Therefore the model will mixed up different opinions.
Rather if we divided things up a the author level, so that given authors were only on the training data, or only in the test data or only in the validation data. The model will find more difficult to get a high accuracy on the test validation (What is correct and have more sense!). Because it will need to really focus in author by author articles rather than get a single political affiliation based on a bunch of mixed articles from different authors.
https://developers.google.com/machine-learning/crash-course/18th-century-literature
NEW QUESTION # 303
......
For most users, access to the relevant qualifying examinations may be the first, so many of the course content related to qualifying examinations are complex and arcane. According to these ignorant beginners, the Professional-Machine-Learning-Engineer Exam Questions set up a series of basic course, by easy to read, with corresponding examples to explain at the same time, the Google Professional Machine Learning Engineer study question let the user to be able to find in real life and corresponds to the actual use of learned knowledge, deepened the understanding of the users and memory. Because many users are first taking part in the exams, so for the exam and test time distribution of the above lack certain experience, and thus prone to the confusion in the examination place, time to grasp, eventually led to not finish the exam totally.
Professional-Machine-Learning-Engineer Valid Exam Notes: https://www.prep4pass.com/Professional-Machine-Learning-Engineer_exam-braindumps.html
P.S. Free & New Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by Prep4pass: https://drive.google.com/open?id=14GgI_AAs7VE2Se3Mn8sRyoShkyUbGDBZ