P.S. Kostenlose und neue Databricks-Certified-Professional-Data-Engineer Prüfungsfragen sind auf Google Drive freigegeben von ITZert verfügbar: https://drive.google.com/open?id=18965eSJykAnK-LUifoYBP2zuUZMox7rO
Mit den Schulungsunterlagen zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung von ITZert würden Sie eine glänzende Zukunft haben und Erfolg erzielen. Sie werden Sie nicht nur zum Erfolg führen, sondern auch Ihre Fähigkeiten in der IT-Branche effizient entfalten. Sie umfassen zahlreiche Wissensgebiete und können Ihre Kenntnisse verbessern. Wenn Sie noch warten oder zögern, denn Sie wissen nicht, wie man die Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung bestehen kann, keine Sorge. Die Schulungsunterlagen zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung von ITZert wird alle Ihren Probleme lösen.
| Section | Weight | Objectives |
|---|---|---|
| Monitoring and Alerting | 10% | - Performance and health monitoring - Pipeline observability and logging - Setting up alerts and notifications |
| Debugging and Deploying | 10% | - CI/CD and DevOps practices - Deployment using bundles, CLI, and APIs - Troubleshooting pipelines and errors |
| Data Transformation, Cleansing, and Quality | 10% | - Standardization and normalization - Data validation and quality checks - Handling missing or inconsistent data |
| Data Governance | 7% | - Policy enforcement - Unity Catalog management - Data lineage and metadata tracking |
| Data Modelling | 6% | - Delta Lake table design - Medallion Architecture implementation - Schema design and management |
| Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic - Data transformation and aggregation - Integration with Databricks APIs and tools |
| Data Ingestion & Acquisition | 7% | - Connecting to diverse data sources - Schema inference and evolution - Auto Loader and streaming ingestion |
| Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Data encryption and masking - Access control and permissions |
| Cost & Performance Optimisation | 13% | - Query optimization and caching - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling |
>> Databricks-Certified-Professional-Data-Engineer Prüfungsübungen <<
Mit ITZert können Sie ganz leicht die Databricks Databricks-Certified-Professional-Data-Engineer Prüfung bestehen. Wenn Sie die Databricks Databricks-Certified-Professional-Data-Engineer Schulungsunterlagen im ITZert wählen und Databricks Databricks-Certified-Professional-Data-Engineer die Prüfungsfragen und Anworten zur Zertifizierungsprüfung herunterladen, werden Sie sicher selbstbewusster sein, dass Sie die Prüfung ganz leicht bestehen können. Obwohl es auch andere Prüfungsunterlagen zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung auf andere Websites gibt, versprechen wir Ihnen, dass unsere Produkte am besten sind. Unsere Übungsfragen-und antworten sind sehr präzis. Sue umfassen viele Wissensgebiete. Sie sind immer erneuert und ergänzt. Deshalb steht unser ITZert Ihnen eine genauige Prüfungsvorbereitung zur Verfügung. Wenn Sie ITZert wählen, können Sie viel Zeit ersparen, ganz leicht und schnell die Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung bestehen und so schnell wie möglich ein IT-Fachmann in der Databricks IT-Branche werden.
215. Frage
The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.
The below query is used to create the alert: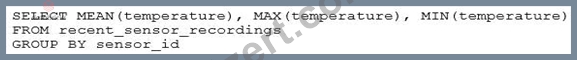
The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120. Notifications are triggered to be sent at most every 1 minute.
If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?
Antwort: A
Begründung:
This is the correct answer because the query is using a GROUP BY clause on the sensor_id column, which means it will calculate the mean temperature for each sensor separately. The alert will trigger when the mean temperature for any sensor is greater than 120, which means at least one sensor had an average temperature above 120 for three consecutive minutes. The alert will stop when the mean temperature for all sensors drops below 120. Verified References: [Databricks Certified Data Engineer Professional], under "SQL Analytics" section; Databricks Documentation, under "Alerts" section.
216. Frage
What steps need to be taken to set up a DELTA LIVE PIPELINE as a job using the workspace UI?
Antwort: C
Begründung:
Explanation
The answer is,
Select Workflows UI and Delta live tables tab, under task type select Delta live tables pipeline and select the notebook.
Create a pipeline
To create a new pipeline using the Delta Live Tables notebook:
1.Click Workflows in the sidebar, click the Delta Live Tables tab, and click Create Pipeline.
2.Give the pipeline a name and click to select a notebook.
3.Optionally enter a storage location for output data from the pipeline. The system uses a de-fault location if you leave Storage Location empty.
4.Select Triggered for Pipeline Mode.
5.Click Create.
The system displays the Pipeline Details page after you click Create. You can also access your pipeline by clicking the pipeline name in the Delta Live Tables tab.
217. Frage
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table named users .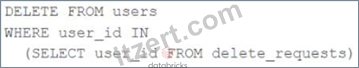
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
Antwort: A
Begründung:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delete from a table" section; Databricks Documentation, under
"Remove files no longer referenced by a Delta table" section.
218. Frage
What is the underlying technology that makes the Auto Loader work?
Antwort: C
219. Frage
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below: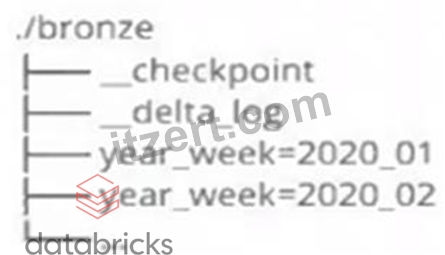
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
Antwort: D
Begründung:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss. Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation , under "Checkpointing" section.
220. Frage
......
Wollen Sie Ihre Fähigkeit beim Lernen der Databricks Databricks-Certified-Professional-Data-Engineer Zertifzierungsunterlagen verbessern und sich von anderen besser anerkannt? Databricks Prüfungen helfen Ihnen, Ihre Fähigkeit zu verbessern. Wenn Sie die Databricks-Certified-Professional-Data-Engineer Zertifizierung besitzen, können Sie Ihre Arbeit besser erledigen. Obwohl die Databricks-Certified-Professional-Data-Engineer Prüfung sehr schwierig ist, können Sie sich nicht um die Vorbereitung der Prüfung sorgen. Nach der Nutzung der ITZert Databricks-Certified-Professional-Data-Engineer Dumps können Sie die Databricks Databricks-Certified-Professional-Data-Engineer Prüfung zu bestehen und auch die entsprechenden Kenntnisse beherrschen.
Databricks-Certified-Professional-Data-Engineer Examengine: https://www.itzert.com/Databricks-Certified-Professional-Data-Engineer_valid-braindumps.html
P.S. Kostenlose und neue Databricks-Certified-Professional-Data-Engineer Prüfungsfragen sind auf Google Drive freigegeben von ITZert verfügbar: https://drive.google.com/open?id=18965eSJykAnK-LUifoYBP2zuUZMox7rO