100% Pass 2026 Trustable Databricks-Certified-Data-Engineer-Professional: Current Databricks Certified Data Engineer Professional Exam Exam Content

With our Databricks-Certified-Data-Engineer-Professional learning quiz, the exam will be a piece of cake. And Databricks-Certified-Data-Engineer-Professional training materials serve as a breakthrough of your entire career. Meanwhile, Databricks-Certified-Data-Engineer-Professional study guide provides you considerable solution through the exam and efficient acquaintance. By imparting the knowledge of the exam to those ardent exam candidates who are eager to succeed like you, our experts treat it as responsibility to offer help. So please prepare to get striking progress if you can get our Databricks-Certified-Data-Engineer-Professional Study Guide with following traits for your information.
| Section | Weight | Objectives |
|---|
| Topic 1: Debugging and Deploying | 10% | - Implement CI/CD and DevOps practices
- Deploy using Asset Bundles, CLI, and APIs
- Troubleshoot and debug pipelines
|
| Topic 2: Developing Code for Data Processing using Python and SQL | 22% | - Implement complex data processing logic
- Write efficient and maintainable code
- Use Databricks-specific libraries and APIs
|
| Topic 3: Data Sharing and Federation | 5% | - Use Delta Sharing for secure data sharing
- Manage cross-platform data access
- Implement Lakehouse Federation
|
| Topic 4: Monitoring and Alerting | 10% | - Track data lineage and metrics
- Monitor pipeline performance and health
- Set up alerts and notifications
|
| Topic 5: Cost & Performance Optimisation | 13% | - Optimize compute and storage resources
- Improve query and pipeline performance
- Apply cost management best practices
|
| Topic 6: Data Ingestion & Acquisition | 7% | - Use Auto Loader and structured streaming
- Handle incremental and batch data loads
- Ingest data from diverse sources
|
| Topic 7: Data Transformation, Cleansing, and Quality | 10% | - Enforce data quality standards
- Implement schema evolution and management
- Apply data cleansing and validation rules
|
| Topic 8: Data Modelling | 6% | - Optimize table design and partitioning
- Implement dimensional and relational models
- Design Medallion Architecture
|
| Topic 9: Data Governance | 7% | - Manage data assets and metadata
- Enforce data policies and standards
- Use Unity Catalog for governance
|
| Topic 10: Ensuring Data Security and Compliance | 10% | - Ensure data privacy and compliance
- Secure data at rest and in transit
- Implement access control and permissions
|
>> Current Databricks-Certified-Data-Engineer-Professional Exam Content <<
Comprehensive Review for the Databricks-Certified-Data-Engineer-Professional Exams Questions
Information about Databricks Databricks-Certified-Data-Engineer-Professional Exam: Visit TorrentValid and find out the best features of updated Databricks Databricks-Certified-Data-Engineer-Professional exam dumps that is available in three user-friendly formats. We guarantee that you will be able to ace the Databricks-Certified-Data-Engineer-Professional examination on the first attempt by studying with our actual Databricks-Certified-Data-Engineer-Professional exam questions.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q129-Q134):
NEW QUESTION # 129
Where in the Spark UI can one diagnose a performance problem induced by not leveraging predicate push-down?
- A. In the Stage's Detail screen, in the Completed Stages table, by noting the size of data read from the Input column
- B. In the Executor's log file, by gripping for "predicate push-down"
- C. In the Storage Detail screen, by noting which RDDs are not stored on disk
- D. In the Query Detail screen, by interpreting the Physical Plan
- E. In the Delta Lake transaction log. by noting the column statistics
Answer: D
Explanation:
This is the correct answer because it is where in the Spark UI one can diagnose a performance problem induced by not leveraging predicate push-down. Predicate push-down is an optimization technique that allows filtering data at the source before loading it into memory or processing it further. This can improve performance and reduce I/O costs by avoiding reading unnecessary data. To leverage predicate push-down, one should use supported data sources and formats, such as Delta Lake, Parquet, or JDBC, and use filter expressions that can be pushed down to the source. To diagnose a performance problem induced by not leveraging predicate push-down, one can use the Spark UI to access the Query Detail screen, which shows information about a SQL query executed on a Spark cluster. The Query Detail screen includes the Physical Plan, which is the actual plan executed by Spark to perform the query. The Physical Plan shows the physical operators used by Spark, such as Scan, Filter, Project, or Aggregate, and their input and output statistics, such as rows and bytes. By interpreting the Physical Plan, one can see if the filter expressions are pushed down to the source or not, and how much data is read or processed by each operator.
NEW QUESTION # 130
A data engineer is testing a collection of mathematical functions, one of which calculates the area under a curve as described by another function.
assert(myIntegrate(lambda x: x*x, 0, 3) [0] == 9)
Which kind of the test does the above line exemplify?
- A. Manual
- B. Unit
- C. functional
- D. End-to-end
- E. Integration
Answer: B
Explanation:
A unit test is designed to verify the correctness of a small, isolated piece of code, typically a single function. Testing a mathematical function that calculates the area under a curve is an example of a unit test because it is testing a specific, individual function to ensure it operates as expected.
NEW QUESTION # 131
A CHECK constraint has been successfully added to the Delta table named activity_details using the following logic:
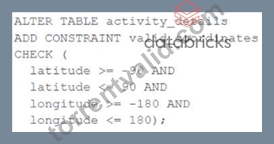
A batch job is attempting to insert new records to the table, including a record where latitude =
45.50 and longitude = 212.67.
Which statement describes the outcome of this batch insert?
- A. The write will fail when the violating record is reached; any records previously processed will be recorded to the target table.
- B. The write will include all records in the target table; any violations will be indicated in the boolean column named valid_coordinates.
- C. The write will insert all records except those that violate the table constraints; the violating records will be recorded to a quarantine table.
- D. The write will fail completely because of the constraint violation and no records will be inserted into the target table.
- E. The write will insert all records except those that violate the table constraints; the violating records will be reported in a warning log.
Answer: D
Explanation:
The CHECK constraint is used to ensure that the data inserted into the table meets the specified conditions. In this case, the CHECK constraint is used to ensure that the latitude and longitude values are within the specified range. If the data does not meet the specified conditions, the write operation will fail completely and no records will be inserted into the target table. This is because Delta Lake supports ACID transactions, which means that either all the data is written or none of it is written. Therefore, the batch insert will fail when it encounters a record that violates the Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from constraint, and the target table will not be updated.
NEW QUESTION # 132
The data engineering team maintains the following code:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
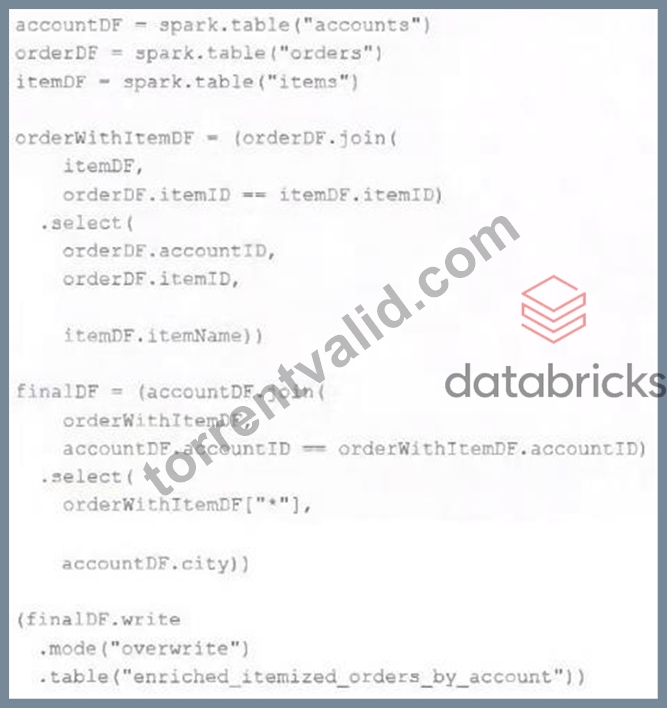
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- B. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
- C. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
- D. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
- E. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
Answer: A
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables.
NEW QUESTION # 133
The Databricks CLI is use to trigger a run of an existing job by passing the job_id parameter. The response that the job run request has been submitted successfully includes a filed run_id.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from Which statement describes what the number alongside this field represents?
- A. The job_id and number of times the job has been are concatenated and returned.
- B. The job_id is returned in this field.
- C. The number of times the job definition has been run in the workspace.
- D. The globally unique ID of the newly triggered run.
- E. The total number of jobs that have been run in the workspace.
Answer: D
Explanation:
When triggering a job run using the Databricks CLI, the run_id field in the response represents a globally unique identifier for that particular run of the job. This run_id is distinct from the job_id.
While the job_id identifies the job definition and is constant across all runs of that job, the run_id is unique to each execution and is used to track and query the status of that specific job run within the Databricks environment. This distinction allows users to manage and reference individual executions of a job directly.
NEW QUESTION # 134
......
When they will be giving their final examination to get Databricks Databricks-Certified-Data-Engineer-Professional certification they don't struggle much and do it easily. The results of the customizable Databricks-Certified-Data-Engineer-Professional exam dumps can then be used to identify areas of strength and weakness and to create a personalized study plan that focuses on improving in the areas that need the most work. Taking Databricks-Certified-Data-Engineer-Professional Practice Tests regularly could help individuals build their confidence, reduce test anxiety, and improve their overall performance.
Databricks-Certified-Data-Engineer-Professional Related Certifications: https://www.torrentvalid.com/Databricks-Certified-Data-Engineer-Professional-valid-braindumps-torrent.html
- Real Databricks-Certified-Data-Engineer-Professional Braindumps ⚗ Databricks-Certified-Data-Engineer-Professional Trustworthy Source 🍪 Databricks-Certified-Data-Engineer-Professional Trustworthy Source 🗼 Open website ☀ www.easy4engine.com ️☀️ and search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ for free download ⚽Latest Databricks-Certified-Data-Engineer-Professional Exam Registration
- Question Databricks-Certified-Data-Engineer-Professional Explanations 🙎 Dump Databricks-Certified-Data-Engineer-Professional Collection 🦠 Databricks-Certified-Data-Engineer-Professional Reliable Test Duration 📷 Easily obtain ▶ Databricks-Certified-Data-Engineer-Professional ◀ for free download through “ www.pdfvce.com ” 🚋Databricks-Certified-Data-Engineer-Professional Exam Torrent
- Real Databricks-Certified-Data-Engineer-Professional Braindumps 💅 Valid Databricks-Certified-Data-Engineer-Professional Exam Cost 📑 Databricks-Certified-Data-Engineer-Professional Reliable Test Duration 🟤 The page for free download of ➠ Databricks-Certified-Data-Engineer-Professional 🠰 on ➥ www.torrentvce.com 🡄 will open immediately 🌑Databricks-Certified-Data-Engineer-Professional Test Score Report
- Databricks-Certified-Data-Engineer-Professional Trustworthy Source 🚆 Test Databricks-Certified-Data-Engineer-Professional Prep ⏏ Latest Databricks-Certified-Data-Engineer-Professional Exam Registration 😫 Go to website ➤ www.pdfvce.com ⮘ open and search for { Databricks-Certified-Data-Engineer-Professional } to download for free 🛸Databricks-Certified-Data-Engineer-Professional New Dumps Ppt
- Current Databricks-Certified-Data-Engineer-Professional Exam Content | Databricks Databricks-Certified-Data-Engineer-Professional Related Certifications: Databricks Certified Data Engineer Professional Exam Pass Success 🤲 Open website ➡ www.prepawayete.com ️⬅️ and search for 【 Databricks-Certified-Data-Engineer-Professional 】 for free download 🐇Real Databricks-Certified-Data-Engineer-Professional Braindumps
- Current Databricks-Certified-Data-Engineer-Professional Exam Content | Databricks Databricks-Certified-Data-Engineer-Professional Related Certifications: Databricks Certified Data Engineer Professional Exam Pass Success 🥳 Go to website ➤ www.pdfvce.com ⮘ open and search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ to download for free 🦢Databricks-Certified-Data-Engineer-Professional Trustworthy Source
- Latest Databricks-Certified-Data-Engineer-Professional Material 🏫 Databricks-Certified-Data-Engineer-Professional Reliable Test Duration 🩳 Reliable Databricks-Certified-Data-Engineer-Professional Test Simulator 🐑 Download ➠ Databricks-Certified-Data-Engineer-Professional 🠰 for free by simply entering { www.torrentvce.com } website 🧇Databricks-Certified-Data-Engineer-Professional Exam Simulator Online
- Databricks - Databricks-Certified-Data-Engineer-Professional –Trustable Current Exam Content 🏐 Open ⮆ www.pdfvce.com ⮄ and search for { Databricks-Certified-Data-Engineer-Professional } to download exam materials for free 🧪Latest Databricks-Certified-Data-Engineer-Professional Exam Vce
- Reliable Databricks-Certified-Data-Engineer-Professional Test Simulator 🚜 Reliable Databricks-Certified-Data-Engineer-Professional Test Labs 🧜 Dump Databricks-Certified-Data-Engineer-Professional Collection 💯 Search on ▶ www.pdfdumps.com ◀ for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 to obtain exam materials for free download 👸Databricks-Certified-Data-Engineer-Professional Reliable Test Duration
- Real Databricks-Certified-Data-Engineer-Professional Braindumps 🈺 Databricks-Certified-Data-Engineer-Professional New Dumps Ppt 🪐 Question Databricks-Certified-Data-Engineer-Professional Explanations 🏯 Simply search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ for free download on ⇛ www.pdfvce.com ⇚ 🍋Latest Databricks-Certified-Data-Engineer-Professional Material
- What are the Benefits of Preparing with the www.testkingpass.com Databricks Databricks-Certified-Data-Engineer-Professional Exam Dumps? 💔 Search for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 and easily obtain a free download on ☀ www.testkingpass.com ️☀️ 🍮Latest Databricks-Certified-Data-Engineer-Professional Material
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes