If you are going to buying the DP-750 learning materials online, the safety for the website is quite important. We have professional technicians to examine the website every day, therefore we can provide you with a clean and safe shopping environment. DP-750 learning materials of us contain the most knowledge points for the exam, and it will not only help you to get a certificate successfully but also improve your ability in the process of learning. We also offer you free update for one year if you buy DP-750 Exam Dumps from us.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
UpdateDumps presents its Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam product at an affordable price as we know that applicants desire to save money. To gain all these benefits you need to enroll in the Implementing Data Engineering Solutions Using Azure Databricks EXAM and put all your efforts to pass the challenging Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam easily. In addition, you can test specs of the Implementing Data Engineering Solutions Using Azure Databricks practice material before buying by trying a free demo. These incredible features make UpdateDumps prep material the best option to succeed in the Microsoft DP-750 examination. Therefore, don't wait. Order Now !!!
NEW QUESTION # 54
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to ingest data from CSV files stored in Azure Data Lake Storage Gen2. New rows are appended frequently.
You need to implement a data ingestion solution that meets the following requirements:
- New data must be available in near-real-time (NRT).
- The data must be stored in managed Delta tables.
- The solution must minimize custom code and maintenance effort.
What should you include in the solution?
Answer: D
Explanation:
You should use Auto Loader with Delta Live Tables (DLT) or a streaming readStream using the cloudFiles format to load data into Unity Catalog managed tables.
To achieve the absolute lowest maintenance and custom code, Delta Live Tables with Auto Loader is the recommended choice.
Configure Cloud FilesFormat option: Set the source format to cloudFiles in your Spark stream.File detection: Auto Loader automatically tracks new files arriving in Azure Data Lake Storage (ADLS) Gen2.Schema evolution: It infers and adapts to schema changes without code updates.
Reference:
https://docs.databricks.com/aws/en/ingestion/cloud-object-storage/auto-loader/unity-catalog
NEW QUESTION # 55
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.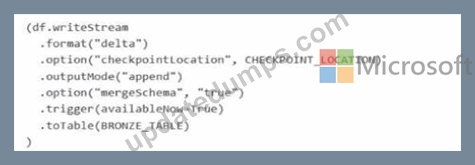
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.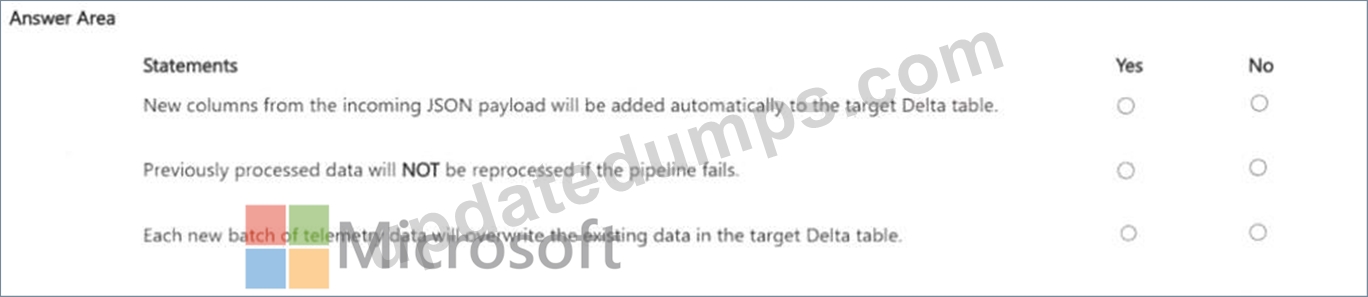
Answer:
Explanation: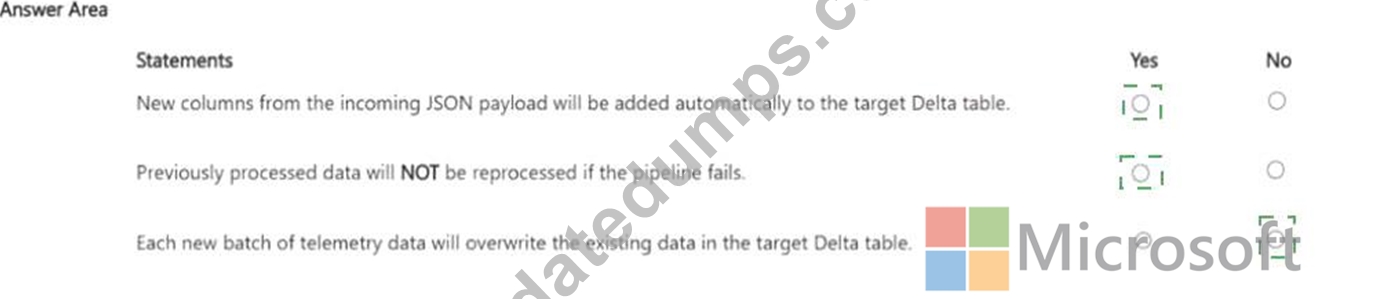
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: 'overwrite' replaces existing data; 'append' adds to it.
Always check whether the code uses the correct Delta format (.format('delta')), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 56
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements.
What should you do?
Answer: C
Explanation:
The correct answer is A. Photon is Azure Databricks ' native vectorized query engine, written in C++, designed to accelerate data ingestion and SQL-heavy workloads significantly over the standard Spark JVM path. Enabling it on a job compute cluster directly addresses Contoso ' s requirement for ' fast and consistent performance for BI workloads ' and ' production ingestion workloads that can scale automatically during telemetry spikes. ' Photon integrates transparently - no code changes are needed - and pairs well with autoscaling job clusters to handle the bursty 40,000-sensor telemetry load.
Option B contradicts the isolation requirement: Contoso explicitly needs production and development separated, not merged onto shared compute. Option C with a fixed large node gives peak capacity at all times, driving up costs even during quiet periods. Option D disabling autoscaling is the opposite of what ' s needed
- telemetry spikes require elastic scaling, not a locked node count.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/photon
NEW QUESTION # 57
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to ensure that data lineage is captured and can be reviewed for tables accessed by Databricks notebooks and jobs. The solution must minimize administrative effort.
Which compute configuration should you use to capture the data lineage and what should you use to review the data lineage? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.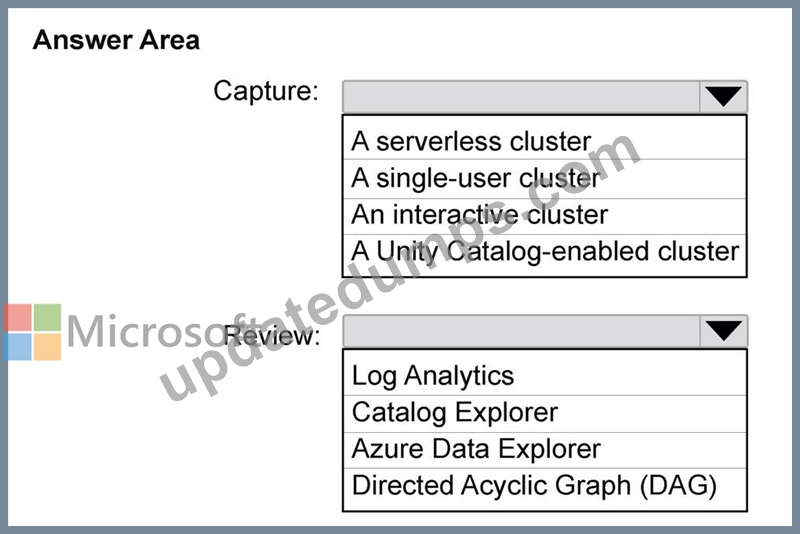
Answer:
Explanation: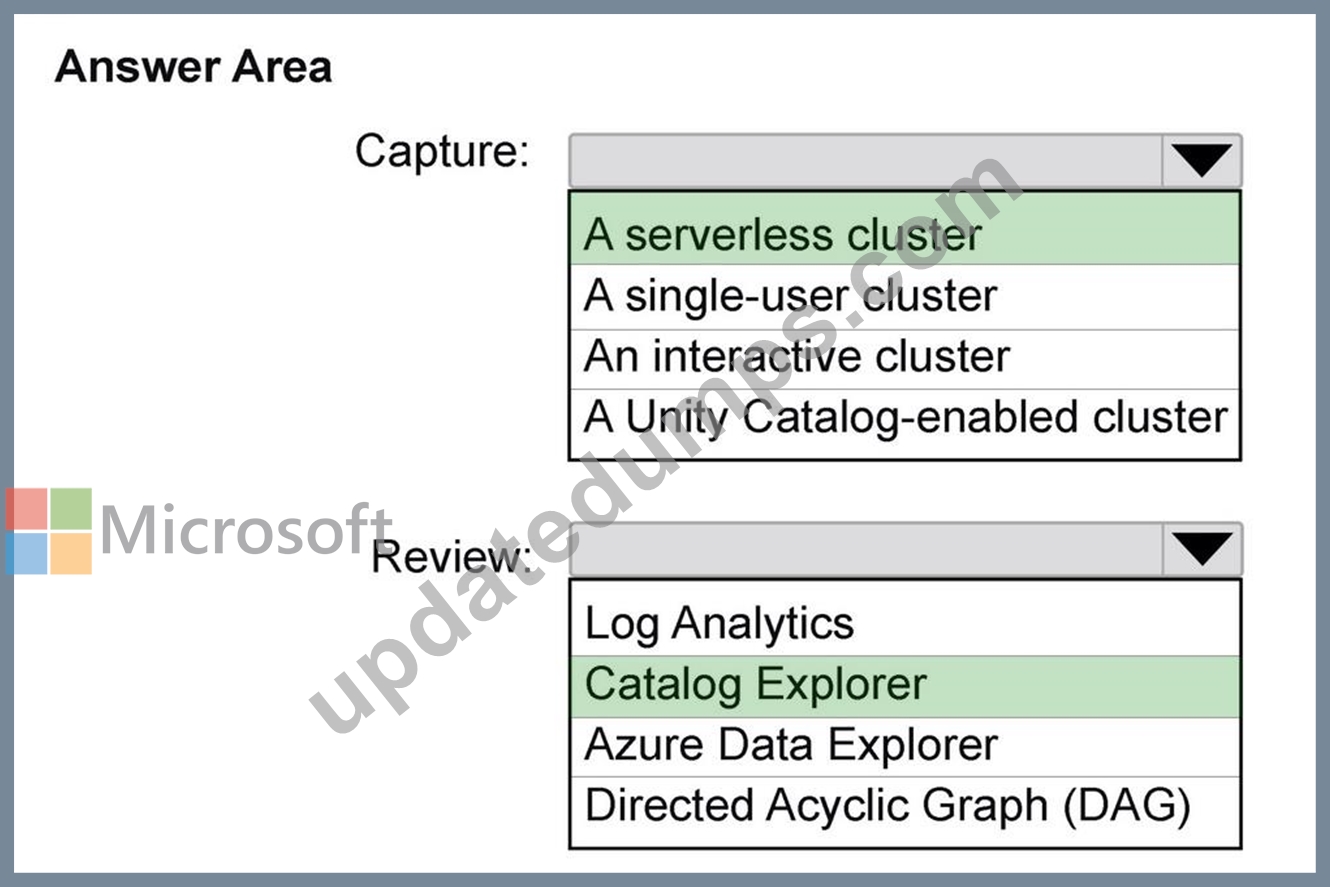
NEW QUESTION # 58
You have an Azure Databricks workspace named Workspace1. You create a compute cluster named Cluser1 that will be used to ingest data.
You need to install the required libraries on Cluster 1. The solution must use Unity Catalog for access control.
What should you do?
Answer: D
Explanation:
The correct answer is B. The %pip install command (or pip3 in a terminal context) creates an isolated, per- session library environment in notebooks, which is the Unity Catalog-compatible approach. Unity Catalog workspaces require cluster access mode set to 'Shared' or 'Single User,' and %pip installs work seamlessly within those modes without requiring cluster restarts.
Option A (custom dependency script) introduces extra maintenance work for every environment change - exactly what the question says to avoid. Option C installs libraries at the cluster level and requires a manual restart, which disrupts other users sharing the cluster and bypasses the per-notebook isolation model that Unity Catalog recommends. Option D uploads libraries to the Workspace file system (legacy DBFS approach), which is being deprecated in favour of Unity Catalog Volumes for library storage.
Reference: https://learn.microsoft.com/en-us/azure/databricks/libraries/notebooks-python-libraries
NEW QUESTION # 59
......
We have thousands of satisfied customers around the globe so you can freely join your journey for the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exam with us. UpdateDumps also guarantees that it will provide your money back if in any case, you are unable to pass the Microsoft DP-750 Exam but the terms and conditions are there that you must have to follow.
DP-750 Pdf Version: https://www.updatedumps.com/Microsoft/DP-750-updated-exam-dumps.html