BTW, DOWNLOAD part of DumpStillValid DP-800 dumps from Cloud Storage: https://drive.google.com/open?id=1x4t3ufCAkQkWAeHq9EKDmsctiBXNv4Rv
It is a truism that an internationally recognized DP-800 certification can totally mean you have a good command of the knowledge in certain areas. If you are overwhelmed by workload heavily and cannot take a breath from it, why not choose our DP-800 preparation torrent? We are specialized in providing our customers with the most reliable and accurate exam materials and help them pass their exams by achieve their satisfied scores. With our DP-800 practice materials, your exam will be a piece of cake.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design and develop database solutions (35–40%) | 35-40% | - Design and implement programmability objects
|
| Topic 2: Secure, optimize, and deploy database solutions (35–40%) | 35-40% | - Optimize database performance
|
| Topic 3: Implement AI capabilities in database solutions (25–30%) | 25-30% | - Implement AI features
|
>> New DP-800 Test Pass4sure <<
DP-800 Certification exams are essential to move ahead, because being certified professional a well-off career would be in your hand. DP-800 is among one of the strong certification provider, who provides massively rewarding pathways with a plenty of work opportunities to you and around the world. But the mystery is quite challenging to pass exam unless you have an updated exam material. Thousands of people attempt DP-800’s exam but majorly fails despite of having good professional experience, because only practice and knowledge isn’t enough a person needs to go through the exam material designed by DP-800, otherwise there is no escape out of reading. Well, you have landed at the right place; DumpStillValid offers your experts designed material which will gauge your understanding of various topics.
NEW QUESTION # 80
You have an Azure SQL database that contains a table named Customer. Customer contains the following columns:
- NationalIDNumber is unique per customer.
- InvestigationNotes contains free-form text.
You have a stored procedure that performs point lookups by NationalIDNumber and returns InvestigationNotes in the query results without filtering on InvestigationNotes.
You need to encrypt both columns by using Always Encrypted and the highest security possible.
Which type of Always Encrypted encryption should you use for each column?
Answer: A
Explanation:
To achieve the highest security for an Azure SQL Database using Always Encrypted, you must use Randomized Encryption for the InvestigationNotes and Deterministic Encryption for the NationalIDNumber.
While "Randomized" is more secure, it does not support point lookups (equality searches).
Therefore, a hybrid approach is required to maintain functionality while maximizing protection.
Recommended Encryption Settings
* NationalIDNumber
Deterministic is required to allow the Stored Procedure to perform point lookups (WHERE NationalIDNumber = @id).
* InvestigationNotes
Use randomized as it provides the highest security. It prevents pattern matching and "leakage" for sensitive text.
Reference:
https://medium.com/@ih_hira/implementing-always-encrypted-with-azure-key-vault-and-entity- framework-core-in-azure-sql-part-1-3a0e5fd7ed9b
NEW QUESTION # 81
You have an Azure SQL database named SalesDB that contains tables named Sales.Orders and Sales.
OrderLines. Both tables contain sales data
You have a Retrieval Augmented Generation (RAG) service that queries SalesDB to retrieve order details and passes the results to a large language model (ILM) as JSON text. The following is a sample of the JSON.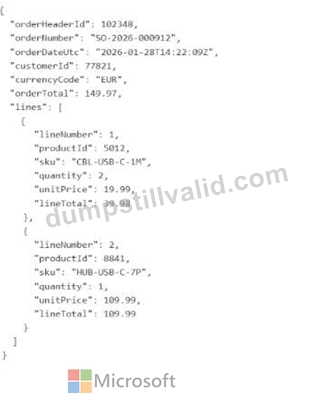
You need to return one 1SON document per order that includes the order header fields and an array of related order lines. The LIM must receive a single JSON array of orders, where each order contains a lines property that is a JSON array of line Items.
Which transact-SQL commands should you use to produce the required JSON shape from the relational tables? To answer, drag the appropriate commands to the correct operations. Each command may be used once, more than once, or not at all. Vou may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.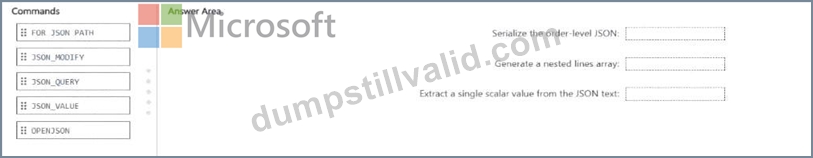
Answer:
Explanation: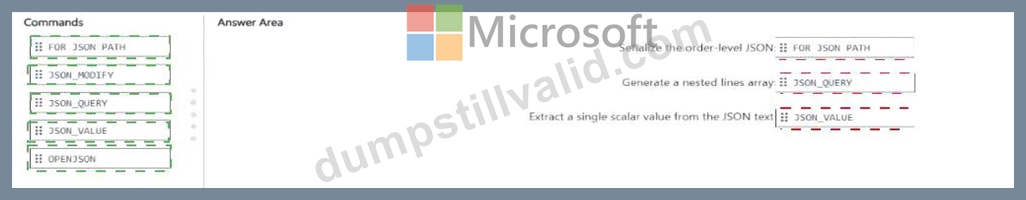
Explanation:
* Serialize the order-level JSON : FOR JSON PATH
* Generate a nested lines array : JSON_QUERY
* Extract a single scalar value from the JSON text : JSON_VALUE
The correct mapping is based on how SQL Server and Azure SQL JSON functions are designed to shape relational data into JSON for AI and RAG scenarios.
To serialize the order-level JSON , use FOR JSON PATH . Microsoft documents that FOR JSON PATH gives you full control over the JSON output shape and formats the result as an array of JSON objects . It is the standard way to turn relational query results into the JSON structure needed by downstream consumers such as APIs and LLM-based RAG services. It also supports nested output through subqueries and aliases.
To generate a nested lines array , use JSON_QUERY . Microsoft explains that JSON_QUERY returns a JSON object or array from JSON text, and it is used when you want to preserve a JSON fragment instead of treating it as plain text. In this scenario, the nested lines property must be emitted as a proper JSON array inside each order document, so JSON_QUERY is the correct command to embed that array in the final JSON shape.
To extract a single scalar value from the JSON text , use JSON_VALUE . Microsoft explicitly states that JSON_VALUE extracts a scalar value from a JSON string, while JSON_QUERY is for objects or arrays. So whenever the requirement is to pull out one property such as an order number, currency code, or customer ID from JSON text, JSON_VALUE is the correct function.
The unused commands are not the best fit here:
* OPENJSON is primarily for parsing JSON into rows and columns, not for shaping relational tables into nested output.
* JSON_MODIFY is for updating JSON text, not generating the required output structure.
So the drag-and-drop answers are:
* Serialize the order-level JSON # FOR JSON PATH
* Generate a nested lines array # JSON_QUERY
* Extract a single scalar value from the JSON text # JSON_VALUE
NEW QUESTION # 82
You have an Azure SQL database that contains tables named dbo.ProductDocs and dbo.ProductDocsEmbeddings. dbo.ProductDocs contains product documentation and the following columns:
- DocID (int)
- Title (nvarchar(200))
- Body (nvarchar(max))
- LastModified (datetime2)
The documentation is edited throughout the day.
dbo.ProductDocsEmbeddings contains the following columns:
- DocID (int)
- ChunkOrder (int)
- ChunkText (nvarchar(max))
- Embedding (vector(1536))
The current embedding pipeline runs once per night.
You need to ensure that embeddings are updated every time the underlying documentation content changes. The solution must NOT require a nightly batch process.
What should you include in the solution?
Answer: D
Explanation:
To ensure embeddings are updated immediately when the product information table changes, you should implement Azure SQL Database Change Tracking combined with Azure Functions triggered via Event Grid. This approach eliminates daily batch processes by enabling an event- driven architecture that triggers embedding regeneration only for modified rows.
Reference:
https://medium.com/@granthgharewal/why-change-tracking-needs-to-be-enabled-for-sql-trigger- azure-functions-7d230a669fb8
NEW QUESTION # 83
You have a Microsoft SQL Server 2025 instance that has a managed identity enabled.
You have a database that contains a table named dbo.ManualChunks. dbo.ManualChunks contains product manuals.
A retrieval query already returns the top five matching chunks as nvarchar(max) text.
You need to call an Azure OpenAI REST endpoint for chat completions. The solution must provide the highest level of security.
You write the following Transact-SG1 code.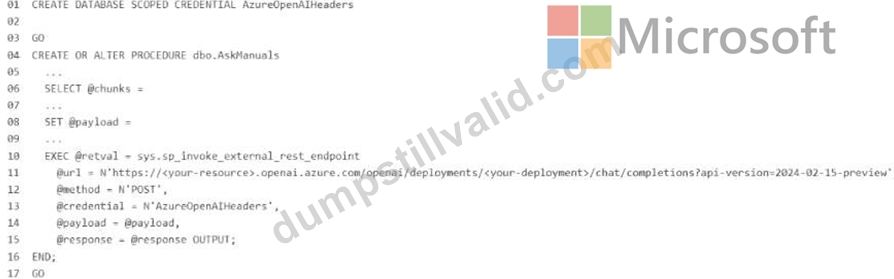
What should you insert at line 02?
Answer: D
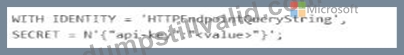
Explanation:
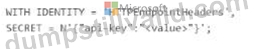
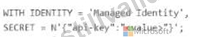
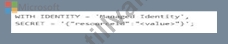
The correct answer is Option B because the requirement is to call an Azure OpenAI REST endpoint from SQL Server 2025 while providing the highest level of security , and the instance already has a managed identity enabled . For Microsoft's SQL AI features, the preferred secure pattern is to use a database scoped credential with IDENTITY = ' Managed Identity ' instead of storing an API key. Microsoft documents that SQL Server 2025 supports managed identity for external AI endpoints, and for Azure OpenAI the credential secret uses the Cognitive Services resource identifier: { " resourceid " : " https://cognitiveservices.azure.
com " } .
So line 02 should be:
WITH IDENTITY = ' Managed Identity ' ,
SECRET = ' { " resourceid " : " https://cognitiveservices.azure.com " } ' ; Why the other options are incorrect:
* A and D use HTTP header or query-string credentials with an API key , which is less secure than managed identity because a secret key must be stored and rotated manually. Microsoft recommends managed identity where supported to avoid embedded secrets.
* C mixes Managed Identity with an api-key secret, which is not the correct pattern for Azure OpenAI managed-identity authentication.
* E uses an invalid identity value for this scenario. The accepted credential identities for external REST endpoint calls include HTTPEndpointHeaders , HTTPEndpointQueryString , Managed Identity , and Shared Access Signature .
Because the endpoint is Azure OpenAI and the question explicitly asks for the highest security , managed identity with the Cognitive Services resource ID is the Microsoft-aligned answer.
NEW QUESTION # 84
You have an Azure SQL database that supports an AI-enabled product catalog API. The database contains a table named Sales.Orders. Sales.Orders contains 20 million rows and has a nonclustered index on a column named CreateDate.
The API passes a date parameter named @OrderDate.
You have a stored procedure named get_latest_day_orders that filters by running the following query.
WHERE CAST(CreateDate AS date) = @0rderDate.
A review of the query execution reveals that the query causes an index scan.
You need to modify the predicate to ensure that Microsoft SQL Server can use an index seek on CreateDate for a single day.
Which WHERE clause should you use?
Answer: C
Explanation:
To achieve an Index Seek on your CreateDate column, you must remove the CAST function from the column side of the equation. Wrapping a column in a function makes the expression non- SARGable (Searchable Argument), forcing SQL Server to scan the entire index rather than jumping to a specific range.
The Recommended WHERE Clause
To capture all rows for a single day while remaining SARGable, use a range comparison:
WHERE CreateDate >= @OrderDate
AND CreateDate < DATEADD(day, 1, @OrderDate)
Why This Works
Eliminates Functions on Columns: By keeping CreateDate "naked," the query optimizer can use the nonclustered index to find the exact starting point.
Handles Time Components: Since CreatedDate likely contains time data (DATETIME or DATETIME2), this logic captures everything from 00:00:00.000 up to (but not including) midnight of the following day.
Single Day Precision: It creates a "half-open" interval that is the standard best practice for date filtering in SQL Server.
Reference:
https://medium.com/@c.charalambos1998/how-to-design-indexes-in-sql-server-for-faster-query- performance-4a2279a9b512
NEW QUESTION # 85
......
Far more effective than online courses free or other available exam materials from the other websites, our DP-800 exam questions are the best choice for your time and money. As the content of our DP-800 study materials has been prepared by the most professional and specilized experts. I can say that no one can know the DP-800 learning quiz better than them and they can teach you how to deal with all of the exam questions and answers skillfully.
DP-800 Top Dumps: https://www.dumpstillvalid.com/DP-800-prep4sure-review.html
What's more, part of that DumpStillValid DP-800 dumps now are free: https://drive.google.com/open?id=1x4t3ufCAkQkWAeHq9EKDmsctiBXNv4Rv