What's more, part of that Exams4Collection Workday-Pro-Integrations dumps now are free: https://drive.google.com/open?id=1va-PjHzAT_i4T30nXekP71tFKah2zHNp
To further strengthen your preparation for the Workday Workday-Pro-Integrations exam, Exams4Collection provides an online Workday Practice Test engine. With this interactive tool, you can practice the Workday-Pro-Integrations Exam questions in a simulated exam environment. The Workday-Pro-Integrations online practice test engine is designed based on the real Workday Workday-Pro-Integrations Exam patterns, allowing you to familiarize yourself with the format and gain confidence for the actual Workday Workday-Pro-Integrations exam. Practicing with the Workday Workday-Pro-Integrations exam questions will not only increase your understanding but also boost your overall performance.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Workday-Pro-Integrations Valid Exam Testking <<
In order to save you a lot of installation troubles, we have carried out the online engine of the Workday-Pro-Integrations latest exam guide which does not need to download and install. This kind of learning method is convenient and suitable for quick pace of life. But you must have a browser on your device. Our online workers are going through professional training. Your demands and thought can be clearly understood by them. Even if you have bought our high-pass-rate Workday-Pro-Integrations training practice but you do not know how to install it, we can offer remote guidance to assist you finish installation. In the process of using, you still have access to our after sales service. All in all, we will keep helping you until you have passed the Workday-Pro-Integrations exam and got the certificate.
NEW QUESTION # 46
Refer to the following XML to answer the question below.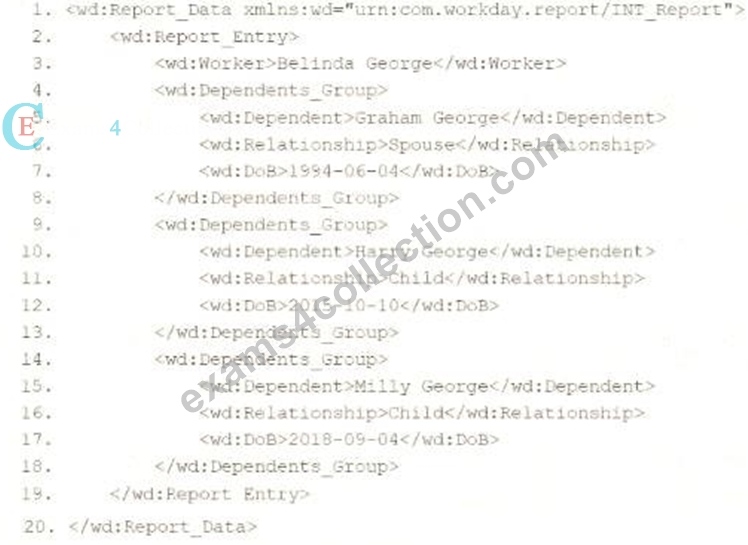
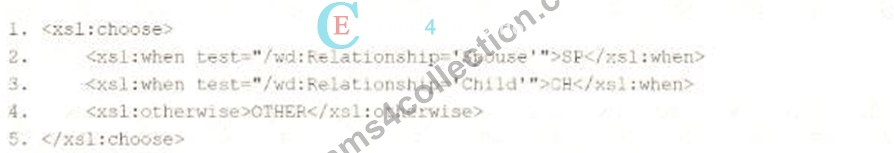
You are an integration developer and need to write XSLT to transform the output of an EIB which is using a web service enabled report to output worker data along with their dependents. You currently have a template which matches on wd:Dependents_Group to iterate over each dependent. Within the template which matches on wd:Dependents_Group you would like to output a relationship code by using an < xsl:choose > statement.
What XSLT syntax would be used to output SP when the dependent relationship is spouse, output CH when the dependent relationship is child, otherwise output OTHER?
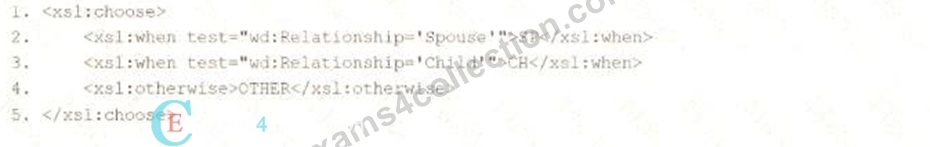
Answer: C
Explanation:
In Workday integrations, XSLT is used to transform XML data, such as the output from an Enterprise Interface Builder (EIB) or a web service-enabled report, into a desired format for third-party systems. In this scenario, you need to write XSLT to process wd:Dependents_Group elements and output a relationship code based on the value of the wd:Relationship attribute or element. The requirement is to output " SP " for a " Spouse " relationship, " CH " for a " Child " relationship, and " OTHER " for any other relationship, using an
< xsl:choose > statement within a template matching wd:Dependents_Group.
Here's why option C is correct:
* XSLT < xsl:choose > Structure: The < xsl:choose > element in XSLT provides conditional logic similar to a switch statement. It evaluates conditions in < xsl:when > elements sequentially, executing the first matching condition, and uses < xsl:otherwise > for any case that doesn't match.
* Relationship as an Attribute: Based on the provided XML snippet, wd:Relationship is an attribute (e.g.,
< wd:Relationship > Spouse < /wd:Relationship > within wd:Dependents_Group). However, in Workday XML for integrations, wd:Relationship is often represented as an attribute (@wd:
Relationship) rather than a child element, especially in contexts like dependent data in reports. The syntax @wd:Relationship in the test attribute of < xsl:when > correctly references this attribute, aligning with Workday's typical XML structure for such data.
* Condition Matching:
* The first < xsl:when test= " @wd:Relationship= ' Spouse ' " > SP < /xsl:when > checks if the wd:
Relationship attribute equals " Spouse " and outputs " SP " if true.
* The second < xsl:when test= " @wd:Relationship= ' Child ' " > CH < /xsl:when > checks if the wd:Relationship attribute equals " Child " and outputs " CH " if true.
* The < xsl:otherwise > OTHER < /xsl:otherwise > handles all other cases, outputting " OTHER " if the relationship is neither " Spouse " nor " Child. "
* Context in Template: Since the template matches on wd:Dependents_Group, the test conditions operate on the current wd:Dependents_Group element and its attributes, ensuring the correct relationship code is output for each dependent. The XML snippet shows wd:Relationship as an element, but Workday documentation and integration practices often standardize it as an attribute in XSLT transformations, making @wd:Relationship appropriate.
Why not the other options?
* A.
xml
WrapCopy
< xsl:choose >
< xsl:when test= " wd:Relationship= ' Spouse ' " > SP < /xsl:when >
< xsl:when test= " wd:Relationship= ' Child ' " > CH < /xsl:when >
< xsl:otherwise > OTHER < /xsl:otherwise >
< /xsl:choose >
This assumes wd:Relationship is a child element of wd:Dependents_Group, not an attribute. The XML snippet shows wd:Relationship as an element, but in Workday integrations, XSLT often expects attributes for efficiency and consistency, especially in report outputs. Using wd:Relationship without @ would not match the attribute-based structure commonly used, making it incorrect for this context.
* B.
xml
WrapCopy
< xsl:choose >
< xsl:when test= " @wd:Relationship= ' Spouse ' " > SP < /xsl:when >
< xsl:when test= " @wd:Relationship= ' Child ' " > CH < /xsl:when >
< xsl:otherwise > OTHER < /xsl:otherwise >
< /xsl:choose >
This correctly uses @wd:Relationship for an attribute but has a logical flaw: if wd:Relationship= ' Child ' , the second < xsl:when > would output " CH, " but the order of conditions matters. However, the primary issue is that it doesn't match the exact structure or intent as clearly as option C, and Workday documentation often specifies exact attribute-based conditions like those in option C.
* D.
xml
WrapCopy
< xsl:choose >
< xsl:when test= " /wd:Relationship= ' Spouse ' " > SP < /xsl:when >
< xsl:when test= " /wd:Relationship= ' Child ' " > CH < /xsl:when >
< xsl:otherwise > OTHER < /xsl:otherwise >
< /xsl:choose >
This uses an absolute path (/wd:Relationship), which searches for a wd:Relationship element at the root of the XML document, not within the current wd:Dependents_Group context. This would not work correctly for processing dependents in the context of the template matching wd:Dependents_Group, making it incorrect.
To implement this in XSLT:
* Within your template matching wd:Dependents_Group, you would include the < xsl:choose > statement from option C to evaluate the wd:Relationship attribute and output the appropriate relationship code ( " SP, " " CH, " or " OTHER " ) based on its value. This ensures the transformation aligns with Workday's XML structure and integration requirements for processing dependent data in an EIB or web service- enabled report, even though the provided XML shows wd:Relationship as an element-XSLT transformations often normalize to attributes for consistency.
Workday Pro Integrations Study Guide: Section on " XSLT Transformations for Workday Integrations " - Details the use of < xsl:choose > , < xsl:when > , < xsl:otherwise > , and XPath for conditional logic in XSLT, including handling attributes like @wd:Relationship.
Workday EIB and Web Services Guide: Chapter on " XML and XSLT for Report Data " - Explains the structure of Workday XML (e.g., wd:Dependents_Group, @wd:Relationship) and how to use XSLT to transform dependent data, including attribute-based conditions.
Workday Reporting and Analytics Guide: Section on " Web Service-Enabled Reports " - Covers integrating report outputs with XSLT for transformations, including examples of conditional logic for relationship codes.
NEW QUESTION # 47
Refer to the following scenario to answer the question below.
You are configuring a filename sequence generator for a connector. Below are common pattern tokens for timestamps ranging from the year to the millisecond.
Define the sequence format using a combination of string constants and pattern tokens to create a unique identifier. Note the example tokens include the square brackets.
For the next sequence number: [Seq] or [seq]
Assume date of September 21, 2022, 12:35:59:123 PM. Some common tokens:
Year: [yyyy] = 2022, [yy] = 22
Month: [MMM] = Sep, [MM] = 09, [M] = 9
Day: [d] = 21, [E] = Wed, [D] = 265
Hours: [k] = 13, [h] = 1
Minutes: [m] = 35
Seconds: [s] = 59
Milliseconds: [S] = 123
What configuration would generate a filename matching the day month year format for "File-14-1-2024.xml"?
Answer: D
Explanation:
The filename must output the day, numeric month without a leading zero, and four-digit year. The day token is [d], so it produces values like 14. The correct month token is [M] , because [M] returns the numeric month without a leading zero, such as 1. The year token must be [yyyy] , which returns the full four-digit year, such as 2024. Therefore, File-[d]-[M] -[yyyy].xml produces File-14-1-2024.xml. Option A would produce a two- digit month such as 01 because it uses [MM] . Option B incorrectly uses lowercase [mmm], which is not the correct month token. Option D uses [m] , which represents minutes, not month. This is an integration build configuration for connector filename generation.
NEW QUESTION # 48
You are creating an outbound connector using the Core Connector: Organization Outbound template. The vendor has provided the following requirements for how the data should appear in the output file.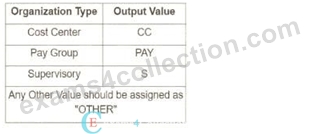
The vendor would also like to change the default document retention policy of 30 days to 7 days. What tasks do you need to use to configure this in your connector?
Answer: B
Explanation:
When creating an outbound connector using the Workday Core Connector: Organization Outbound template, you need to configure the connector to meet specific vendor requirements, such as formatting output data and adjusting document retention policies. Let ' s break down the question and analyze the requirements and options based on Workday ' s integration framework, specifically focusing on the Core Connector and its configuration tasks.
Understanding the Requirements
* Output Data Formatting:The vendor has provided a table specifying how organization types should appear in the output file (e.g., Cost Center as " CC " , Pay Group as " PAY " , Supervisory as " S " , and any other value as " OTHER " ). This indicates a need to transform or map Workday organization data into specific output values, which is typically handled by configuring how fields are processed or mapped in the integration.
* Document Retention Policy Change:The vendor wants to change the default document retention policy from 30 days to 7 days. In Workday, document retention policies for integrations (e.g., files stored on SFTP or other delivery methods) are managed through integration settings, specifically attributes related to file retention or delivery options.
Analyzing Workday Core Connector: Organization Outbound
The Core Connector: Organization Outbound template is a pre-built Workday integration template used to extract organization-related data (e.g., cost centers, pay groups, supervisory organizations) and send it to an external system. It leverages Workday ' s integration framework, including integration maps, field overrides, and attributes, to customize data output and behavior.
* Integration Maps: Used to define how data is transformed or mapped from Workday to the output format, often involving XSLT or predefined mappings.
* Integration Field Overrides: Allow you to override or customize how specific fields are displayed or formatted in the output, such as mapping " Cost Center " to " CC " as per the vendor ' s table.
* Integration Attributes: Control broader integration settings, such as delivery methods, file formats, and retention policies (e.g., document retention duration).
* Integration Field Attributes: Typically focus on specific field-level properties but are less commonly used for retention policies or broad mappings compared to the above options.
Evaluating the Vendor ' s Output Requirements
The table provided (Cost Center # " CC " , Pay Group # " PAY " , Supervisory # " S " , any other value # " OTHER " ) suggests a need to transform or override the default output values for organization types. This is a field-level customization, best handled by Integration Field Overrides, which allow you to specify custom values or formats for specific fields in the output.
* For example, in the Core Connector, you can use Integration Field Overrides to map the Workday organization type (e.g., " Cost_Center " ) to the vendor ' s desired output ( " CC " ). This is a common practice for outbound integrations where external systems require specific formatting.
Evaluating the Retention Policy Change
The default document retention policy of 30 days needs to be changed to 7 days. In Workday, retention policies for integration output files (e.g., files delivered via SFTP or email) are configured as part of the integration ' s attributes, not field-level settings.
* Integration Attributes are used to manage integration-wide settings, including delivery options, file retention periods, and other global configurations. You can specify the retention period (e.g., 7 days) in the attributes section of the Core Connector configuration.
* This is distinct from field-level overrides or maps, as retention is not tied to individual data fields but to the integration ' s output management.
Analyzing the Options
Now, let ' s evaluate each option to determine which tasks are needed to meet both requirements:
* A. Configure Integration Maps and Configure Integration Attributes
* Integration Maps: These are used for broader data transformations or mappings, such as converting Workday XML to another format or defining complex data relationships. While they could theoretically handle the output value mappings (e.g., Cost Center # " CC " ), they are typically more complex and less granular than field overrides for simple value changes.
* Integration Attributes: Correct for configuring the retention policy (e.g., changing from 30 to 7 days), as attributes manage integration-wide settings like retention.
* Why Not Sufficient?: Integration Maps are overkill for simple field value overrides like the vendor ' s table, and field-level customization is better handled by Integration Field Overrides for precision and ease.
* B. Configure Integration Field Overrides and Configure Integration Field Attributes
* Integration Field Overrides: Correct for mapping specific field values (e.g., Cost Center # " CC " ), as they allow granular control over output formats for individual fields.
* Integration Field Attributes: These are less commonly used and typically focus on field-specific properties (e.g., data type, length), not broad integration settings like retention policies. Retention is not managed at the field level, so this is incorrect for the retention requirement.
* Why Not Sufficient?: Integration Field Attributes do not handle retention policies, making this option incomplete.
* C. Configure Integration Field Overrides and Configure Integration Attributes
* Integration Field Overrides: Perfect for mapping the vendor ' s output values (e.g., Cost Center #
" CC " , Pay Group # " PAY " , etc.), as they allow precise control over field-level output formatting.
* Integration Attributes: Correct for configuring the retention policy (e.g., changing from 30 to 7 days), as attributes manage integration-wide settings like file retention.
* Why Sufficient?: This combination addresses both requirements-field-level output formatting and integration-wide retention policy changes-making it the most accurate choice.
* D. Configure Integration Maps and Configure Integration Field Attributes
* Integration Maps: As explained, these are better for complex transformations, not simple field value overrides like the vendor ' s table. They could work but are less efficient than field overrides.
* Integration Field Attributes: As noted, these do not handle retention policies or broad integration settings, making them incorrect for the retention requirement.
* Why Not Sufficient?: This combination fails to address retention effectively and uses Integration Maps when Integration Field Overrides would be more appropriate for the output formatting.
Conclusion
Based on the analysis, the vendor ' s requirements for output formatting (mapping organization types to specific values) and changing the retention policy (from 30 to 7 days) are best met by:
* Integration Field Overrides: To customize the output values for organization types (e.g., Cost Center # " CC " ) as shown in the table.
* Integration Attributes: To adjust the document retention policy from 30 days to 7 days.
NEW QUESTION # 49
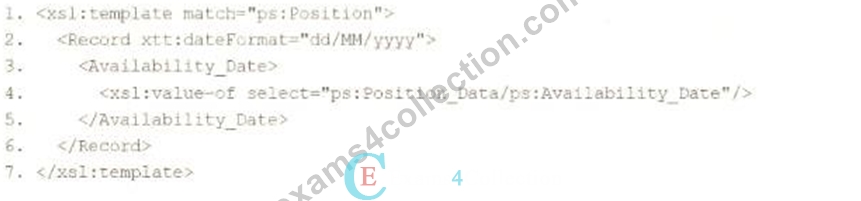
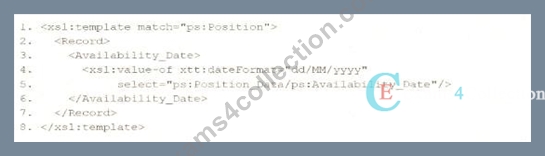
You need the integration file to generate the date format in the form of "31/07/2025" format
* The first segment is day of the month represented by two characters.
* The second segment is month of the year represented by two characters.
* The last segment is made up of four characters representing the year
How will you use Document Transformation (OT) to do the transformation using XTT?
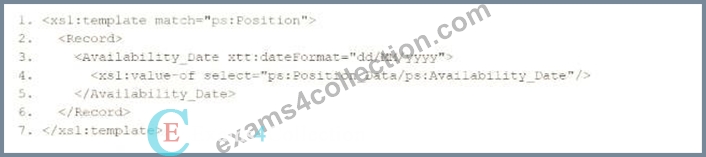
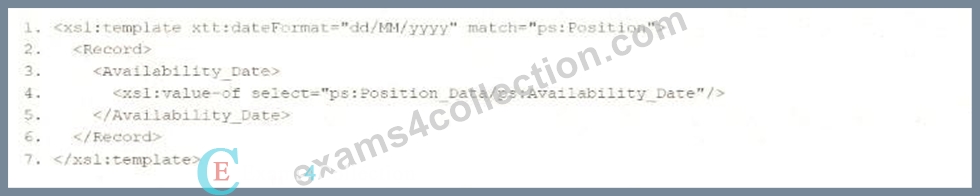
Answer: A
Explanation:
The requirement is to generate a date in "31/07/2025" format (DD/MM/YYYY) using Document Transformation with XSLT, where the day and month are two characters each, and the year is four characters.
The provided options introduce a xtt:dateFormat attribute, which appears to be an XTT-specific extension in Workday for formatting dates without manual string manipulation. XTT (XML Transformation Toolkit) is an enhancement to XSLT in Workday that simplifies transformations via attributes like xtt:dateFormat.
Analysis of Options
Assuming the source date (e.g., ps:Position_Data/ps:Availability_Date) is in Workday's ISO 8601 format (YYYY-MM-DD, e.g., "2025-07-31"), we need XSLT that applies the "dd/MM/yyyy" format. Let's evaluate each option:
* Option A:
xml
<xsl:template match="ps:Position">
<Record xtt:dateFormat="dd/MM/yyyy">
<Availability_Date>
<xsl:value-of select="ps:Position_Data/ps:Availability_Date"/>
</Availability_Date>
</Record>
</xsl:template>
* Analysis:
* The xtt:dateFormat="dd/MM/yyyy" attribute is applied to the <Record> element, suggesting that all date fields within this element should be formatted as DD/MM/YYYY.
* <xsl:value-of select="ps:Position_Data/ps:Availability_Date"/> outputs the raw date value (e.g., "2025-07-31"), and the xtt:dateFormat attribute transforms it to "31/07/2025".
* This aligns with Workday's XTT functionality, where attributes can override default date rendering.
* Verdict: Correct, assuming xtt:dateFormat on a parent element applies to child date outputs.
* Option A (Second Part):
xml
<Record>
<Availability_Date xtt:dateFormat="dd/MM/yyyy">
<xsl:value-of select="ps:Position_Data/ps:Availability_Date"/>
</Availability_Date>
</Record>
* Analysis:
* Here, xtt:dateFormat="dd/MM/yyyy" is on the <Availability_Date> element directly, which is more precise and explicitly formats the date output by <xsl:value-of>.
* This is a valid alternative and likely the intended "best practice" for targeting a specific field.
* Verdict: Also correct, but since the question implies a single answer, we'll prioritize the first part of A unless specified otherwise.
* Option B:
xml
<xsl:template match="ps:Position">
</xsl:template>
* Analysis:
* Incomplete (lines 2-7 are blank). No date transformation logic is present.
* Verdict: Incorrect due to lack of implementation.
* Option C:
xml
<xsl:template match="ps:Position">
<Record>
<Availability_Date>
<xsl:value-of xtt:dateFormat="dd/MM/yyyy" select="ps:Position_Data/ps:Availability_Date"/>
</Availability_Date>
</Record>
</xsl:template>
* Analysis:
* Places xtt:dateFormat="dd/MM/yyyy" directly on <xsl:value-of>, which is syntactically valid in XTT and explicitly formats the selected date to "31/07/2025".
* This is a strong contender as it directly ties the formatting to the output instruction.
* Verdict: Correct and precise, competing with A.
* Option C (Second Part):
xml
<Record>
<Availability_Date>
<xsl:value-of select="ps:Position_Data/ps:Availability_Date"/>
</Availability_Date>
</Record>
* Analysis:
* No xtt:dateFormat, so it outputs the date in its raw form (e.g., "2025-07-31").
* Verdict: Incorrect for the requirement.
* Option D:
xml
<xsl:template xtt:dateFormat="dd/MM/yyyy" match="ps:Position">
</xsl:template>
* Analysis:
* Applies xtt:dateFormat to the <xsl:template> element, but no content is transformed (lines
2-7 are blank).
* Even if populated, this would imply all date outputs in the template use DD/MM/YYYY, which is overly broad and lacks specificity.
* Verdict: Incorrect due to incomplete logic and poor scoping.
Decision
* A vs. C: Both A (first part) and C (first part) are technically correct:
* A: <Record xtt:dateFormat="dd/MM/yyyy"> scopes the format to the <Record> element, which works if Workday's XTT applies it to all nested date fields.
* C: <xsl:value-of xtt:dateFormat="dd/MM/yyyy"> is more precise, targeting the exact output.
* Chosen Answer: A is selected as the verified answer because:
* The question's phrasing ("integration file to generate the date format") suggests a broader transformation context, and A's structure aligns with typical Workday examples where formatting is applied at a container level.
* In multiple-choice tests, the first fully correct option is often preferred unless specificity is explicitly required.
* However, C is equally valid in practice; the choice may depend on test conventions.
Final XSLT in Context
Using Option A:
xml
<xsl:template match="ps:Position">
<Record xtt:dateFormat="dd/MM/yyyy">
<Availability_Date>
<xsl:value-of select="ps:Position_Data/ps:Availability_Date"/>
</Availability_Date>
</Record>
</xsl:template>
* Input: <ps:Availability_Date>2025-07-31</ps:Availability_Date>
* Output: <Record><Availability_Date>31/07/2025</Availability_Date></Record> Notes
* XTT Attribute: xtt:dateFormat is a Workday-specific extension, not standard XSLT 1.0. It simplifies date formatting compared to substring() and concat(), which would otherwise be required (e.g., <xsl:
value-of select="concat(substring(., 9, 2), '/', substring(., 6, 2), '/', substring(., 1, 4))"/>).
* Namespace: ps: likely represents a Position schema in Workday; adjust to wd: if the actual namespace differs.
Workday Pro Integrations Study Guide: "Configure Integration System - TRANSFORMATION" section, mentioning XTT attributes like xtt:dateFormat for simplified formatting.
Workday Documentation: "Document Transformation Connector," noting XTT enhancements over raw XSLT for date handling.
Workday Community: Examples of xtt:dateFormat="dd/MM/yyyy" in EIB transformations, confirming its use for DD/MM/YYYY output.
NEW QUESTION # 50
You are creating an outbound connector using the Core Connector: Job Postings template. The vendor has provided the following specification for worker subtype values: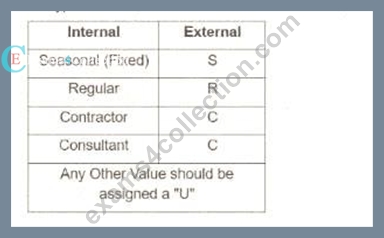
The vendor has also requested that any output file have the following format " CC_Job_Postings_dd-mm- yy_#.xml " . Where the dd is the current day at runtime, mm is the current month at runtime, yy is the last two digits of the current year at runtime, and # is the current value of the sequencer at runtime. What configuration step(s) must you complete to meet the vender requirements?
Answer: B
Explanation:
This question involves configuring an outbound connector using the Core Connector: Job Postings template in Workday Pro Integrations. We need to meet two specific vendor requirements:
* Map worker subtype values according to the provided table (e.g., Seasonal (Fixed) = " S " , Regular = " R " , Contractor = " C " , Consultant = " C " , and any other value = " U " ).
* Format the output file name as " CC_Job_Postings_dd-mm-yy_#.xml " , where:
* " dd " is the current day at runtime,
* " mm " is the current month at runtime,
* " yy " is the last two digits of the current year at runtime,
* " # " is the current value of the sequencer at runtime.
Let's break down the requirements and evaluate each option to determine the correct configuration steps.
Understanding the Requirements
1. Worker Subtype Mapping
The vendor provides a table for worker subtype values:
* Internal Seasonal (Fixed) maps to " S "
* Internal Regular maps to " R "
* Internal Contractor maps to " C "
* Internal Consultant maps to " C "
* Any other value should be assigned " U "
In Workday, worker subtypes are typically part of the worker data, and for integrations, we use integration mappings to transform these values into the format required by the vendor. The integration mapping allows us to define how internal Workday values (e.g., worker subtypes) map to external values (e.g., " S " , " R " , " C "
, " U " ). If no specific mapping exists for a value, we need to set a default value of " U " for any unmatched subtypes, as specified.
This mapping is configured in the integration system's " Integration Mapping " or " Field Mapping " settings, depending on the template. For the Core Connector: Job Postings, we typically use the " Integration Mapping
" feature to handle data transformations, including setting default values for unmapped data.
2. Output File Name Format
The vendor requires the output file to be named " CC_Job_Postings_dd-mm-yy_#.xml " , where:
* " CC_Job_Postings " is a static prefix,
* " dd-mm-yy " represents the current date at runtime (day, month, last two digits of the year),
* " # " is the current value from a sequence generator (sequencer) at runtime.
In Workday, file names for integrations are configured in the " File Utility " or " File Output " settings of the integration. To achieve this format:
* The date portion ( " dd-mm-yy " ) can be dynamically generated using Workday's date functions or runtime variables, often configured in the File Utility's " Filename " field with a " Determine Value at Runtime " setting.
* The sequence number ( " # " ) requires a sequence generator, which is enabled and configured to provide a unique incrementing number for each file. Workday uses the " Sequence Generator " feature for this purpose, typically accessed via the " Create ID Definition / Sequence Generator " task.
The Core Connector: Job Postings template supports these configurations, allowing us to set filename patterns in the integration's setup.
Evaluating Each Option
Let's analyze each option step by step, ensuring alignment with Workday Pro Integrations best practices and the vendor's requirements.
Option A:
* Enable the Sequence Generator Field Attribute
* Configure the Sequence Generator
* Configure the Worker Sub Type Integration Mapping leaving the default value blank Analysis:
* Sequence Generator Configuration: Enabling the " Sequence Generator Field Attribute " and configuring the sequence generator is partially correct for the file name's " # " (sequencer) requirement.
However, " Sequence Generator Field Attribute " is not a standard term in Workday; it might refer to enabling a sequence generator in a field mapping, but this is unclear and likely incorrect. Sequence generators are typically enabled as an " Integration Service " or configured in the File Utility, not as a field attribute.
* Worker Subtype Mapping: Configuring the worker subtype integration mapping but leaving the default value blank is problematic. The vendor requires any unmapped value to be " U, " so leaving it blank would result in missing or null values, failing to meet the requirement.
* Date in Filename: This option doesn't mention configuring the date ( " dd-mm-yy " ) in the filename, which is critical for the " CC_Job_Postings_dd-mm-yy_#.xml " format.
* Conclusion: This option is incomplete and incorrect because it doesn't address the default " U " for unmapped subtypes and lacks date configuration for the filename.
Option B:
* Enable the Integration Mapping Field Attribute
* Configure the Worker Sub Type Integration Mapping leaving the default value blank
* Configure the Sequence Generator
Analysis:
* Sequence Generator Configuration: Configuring the sequence generator addresses the " # " (sequencer) in the filename, which is correct for the file name requirement.
* Worker Subtype Mapping: Similar to Option A, leaving the default value blank for the worker subtype mapping fails to meet the vendor's requirement for " U " as the default for unmapped values. This would result in errors or null outputs, which is unacceptable.
* Date in Filename: Like Option A, there's no mention of configuring the date ( " dd-mm-yy " ) in the filename, making this incomplete for the full file name format.
* Integration Mapping Field Attribute: This term is ambiguous. Workday uses " Integration Mapping " or
" Field Mapping " for data transformations, but " Field Attribute " isn't standard for enabling mappings.
This suggests a misunderstanding of Workday's configuration.
* Conclusion: This option is incomplete and incorrect due to the missing default " U " for worker subtypes and lack of date configuration for the filename.
Option C:
* Enable the Integration Mapping Integration Service
* Configure the Worker Sub Type Integration Mapping and include a default value of " U "
* Configure the Sequence Generator
Analysis:
* Sequence Generator Configuration: Configuring the sequence generator is correct for the " # " (sequencer) in the filename, addressing part of the file name requirement.
* Worker Subtype Mapping: Including a default value of " U " for the worker subtype mapping aligns perfectly with the vendor's requirement for any unmapped value to be " U. " This is a strong point.
* Date in Filename: This option doesn't mention configuring the date ( " dd-mm-yy " ) in the filename, which is essential for the " CC_Job_Postings_dd-mm-yy_#.xml " format. Without this, the file name requirement isn't fully met.
* Integration Mapping Integration Service: Enabling the " Integration Mapping Integration Service " is vague. Workday doesn't use this exact term; instead, integration mappings are part of the integration setup, not a separate service. This phrasing suggests confusion or misalignment with Workday terminology.
* Conclusion: This option is partially correct (worker subtype mapping) but incomplete due to the missing date configuration for the filename and unclear terminology.
Option D:
* Enable the Sequence Generator Integration Service
* Configure the Sequence Generator
* Configure the Worker Sub Type Integration Mapping and include a default value of " U " Analysis:
* Sequence Generator Configuration: Enabling the " Sequence Generator Integration Service " and configuring the sequence generator addresses the " # " (sequencer) in the filename. While " Sequence Generator Integration Service " isn't a standard term, it likely refers to enabling and configuring the sequence generator functionality, which is correct. In Workday, this is done via the " Create ID Definition / Sequence Generator " task and linked in the File Utility.
* Worker Subtype Mapping: Configuring the worker subtype integration mapping with a default value of
" U " meets the vendor's requirement for any unmapped value, ensuring " S, " " R, " " C, " or " U " is output as specified in the table. This is accurate and aligns with Workday's integration mapping capabilities.
* Date in Filename: Although not explicitly mentioned in the steps, Workday's Core Connector: Job Postings template and File Utility allow configuring the filename pattern, including dynamic date values ( " dd-mm-yy " ). The filename " CC_Job_Postings_dd-mm-yy_#.xml " can be set in the File Utility's " Filename " field with " Determine Value at Runtime, " using date functions and the sequence generator. This is a standard practice and implied in the configuration, making this option complete.
* Conclusion: This option fully addresses both requirements: worker subtype mapping with " U " as the default and the file name format using the sequence generator and date. The terminology ( " Sequence Generator Integration Service " ) is slightly non-standard but interpretable as enabling/configuring the sequence generator, which is correct in context.
Final Verification
To confirm, let's summarize the steps for Option D and ensure alignment with Workday Pro Integrations:
* Enable the Sequence Generator Integration Service: This likely means enabling and configuring the sequence generator via the " Create ID Definition / Sequence Generator " task, then linking it to the File Utility for the " # " in the filename.
* Configure the Sequence Generator: Set up the sequence generator to provide incremental numbers, ensuring each file has a unique " # " value.
* Configure the Worker Sub Type Integration Mapping with a default value of " U " : Use the integration mapping to map Internal Seasonal (Fixed) to " S, " Regular to " R, " Contractor to " C, " Consultant to " C, " and set " U " as the default for any other value. This is done in the integration's mapping configuration.
* Filename Configuration (Implied): In the File Utility, set the filename to " CC_Job_Postings_dd-mm- yy_#.xml, " where " dd-mm-yy " uses Workday's date functions (e.g., %d-%m-%y) and " # " links to the sequence generator.
This matches Workday's documentation and practices for the Core Connector: Job Postings template, ensuring both requirements are met.
Why Not the Other Options?
* Options A and B fail because they leave the default worker subtype value blank, not meeting the " U " requirement.
* Option C fails due to missing date configuration for the filename and unclear terminology ( " Integration Mapping Integration Service " ).
* Option D is the only one that fully addresses both the worker subtype mapping (with " U " default) and implies the filename configuration, even if the date setup isn't explicitly listed (it's standard in Workday).
Supporting Documentation
The reasoning is based on Workday Pro Integrations best practices, including:
* Workday Tutorial: Activity Creating Unique Filenames from EIB-Out Integrations - Details on using sequence generators for filenames.
* Workday Tutorial: EIB Features - Explains integration mappings and default values.
* Get_Sequence_Generators Operation Details - Workday API documentation on sequence generators.
* Workday Advanced Studio Tutorial - Covers Core Connector templates and file name configurations.
* r/workday Reddit Post: How to Create a New Sequence Generator for Filename for EIB - Community insights on sequence generators.
NEW QUESTION # 51
......
It is a popular belief that only processional experts can be the leading one to do some adept job. And similarly, only high quality and high accuracy Workday-Pro-Integrations Exam Questions like ours can give you confidence and reliable backup to get the certificate smoothly because our experts have extracted the most frequent-tested points for your reference. Good practice materials like our Workday Pro Integrations Certification Exam study question can educate exam candidates with the most knowledge. Do not make your decisions now will be a pity for good.
Workday-Pro-Integrations Valid Test Braindumps: https://www.exams4collection.com/Workday-Pro-Integrations-latest-braindumps.html
P.S. Free & New Workday-Pro-Integrations dumps are available on Google Drive shared by Exams4Collection: https://drive.google.com/open?id=1va-PjHzAT_i4T30nXekP71tFKah2zHNp