If you spare only a few days for exam preparation, our Databricks-Certified-Data-Engineer-Professional learning materials can be your best choice for your time and money. With our Databricks-Certified-Data-Engineer-Professional exam questions, you can not only pass exam in the least time with the least efforts but can also secure a brilliant percentage. And we will find that our Databricks-Certified-Data-Engineer-Professional Study Guide is the most effective exam materials. We can claim that with our Databricks-Certified-Data-Engineer-Professional training engine for 20 to 30 hours, you can pass the exam with ease.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Sharing and Federation | 5% | - Implement Lakehouse Federation - Use Delta Sharing for secure data sharing - Manage cross-platform data access |
| Topic 2: Ensuring Data Security and Compliance | 10% | - Ensure data privacy and compliance - Secure data at rest and in transit - Implement access control and permissions |
| Topic 3: Developing Code for Data Processing using Python and SQL | 22% | - Write efficient and maintainable code - Use Databricks-specific libraries and APIs - Implement complex data processing logic |
| Topic 4: Data Modelling | 6% | - Optimize table design and partitioning - Design Medallion Architecture - Implement dimensional and relational models |
| Topic 5: Cost & Performance Optimisation | 13% | - Optimize compute and storage resources - Improve query and pipeline performance - Apply cost management best practices |
| Topic 6: Debugging and Deploying | 10% | - Troubleshoot and debug pipelines - Deploy using Asset Bundles, CLI, and APIs - Implement CI/CD and DevOps practices |
| Topic 7: Monitoring and Alerting | 10% | - Track data lineage and metrics - Set up alerts and notifications - Monitor pipeline performance and health |
| Topic 8: Data Governance | 7% | - Enforce data policies and standards - Manage data assets and metadata - Use Unity Catalog for governance |
| Topic 9: Data Ingestion & Acquisition | 7% | - Ingest data from diverse sources - Use Auto Loader and structured streaming - Handle incremental and batch data loads |
| Topic 10: Data Transformation, Cleansing, and Quality | 10% | - Implement schema evolution and management - Apply data cleansing and validation rules - Enforce data quality standards |
>> Cert Databricks Databricks-Certified-Data-Engineer-Professional Exam <<
If you are a positive and optimistic person and want to improve your personal skills, especially for the IT technology, congratulate you, you have found the right place. Databricks exam certification as an important IT certification has attracted many IT candidates. While Pass4sures Databricks-Certified-Data-Engineer-Professional real test dumps can help you get your goals. The aim of the Pass4sures is to help all of you pass your test and get your certification. When you visit our website, you will find that we have three different versions for the dumps. Then focusing on the Databricks-Certified-Data-Engineer-Professional free demo, you can free download it for a try. The questions of the free demo are part of the Databricks-Certified-Data-Engineer-Professional complete exam dumps, so if you want the complete one, you will pay for it. What's more, the Databricks-Certified-Data-Engineer-Professional questions are selected and compiled by our professional team with accurate answers which can ensure you 100% pass.
NEW QUESTION # 33
Each configuration below is identical to the extent that each cluster has 400 GB total of RAM 160 total cores and only one Executor per VM.
Given an extremely long-running job for which completion must be guaranteed, which cluster configuration will be able to guarantee completion of the job in light of one or more VM failures?
Answer: B
Explanation:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
NEW QUESTION # 34
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below: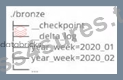
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
Answer: A
Explanation:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss.
NEW QUESTION # 35
An organization processes customer data from web and mobile applications. Data includes names, emails, phone numbers, and location history. Data arrives both as batch files (from SFTP daily) and streaming JSON events (from Kafka in real-time).
To comply with data privacy policies, the following requirements must be met:
- Personally Identifiable Information (PII) such as email, phone
number, and IP address must be masked or anonymized before storage.
- Both batch and streaming pipelines must apply consistent PII
handling.
- Masking logic must be auditable and reproducible.
- The masked data must remain usable for downstream analytics.
How should the data engineer design a compliant data pipeline on Databricks that supports both batch and streaming modes, applies data masking to PII, and maintains traceability for audits?
Answer: B
Explanation:
Databricks recommends applying data masking or anonymization before persisting PII to ensure compliance with privacy regulations such as GDPR and HIPAA. In a Lakeflow Declarative Pipeline, developers can define custom Python or SQL-based masking functions to standardize PII handling across both batch and streaming inputs.
This approach ensures that data entering the Delta Lake is already anonymized, guaranteeing consistent and auditable behavior. By applying masking during ingestion (in the Bronze layer), audit trails are preserved through pipeline event logs.
While Unity Catalog column masks (option C) can enforce dynamic masking at query time, they do not prevent PII storage. Thus, option D aligns with the best practice of securing PII before storage, while still supporting reproducibility and analytics usability.
NEW QUESTION # 36
A distributed team of data analysts share computing resources on an interactive cluster with autoscaling configured. In order to better manage costs and query throughput, the workspace administrator is hoping to evaluate whether cluster upscaling is caused by many concurrent users or resource-intensive queries.
In which location can one review the timeline for cluster resizing events?
Answer: E
NEW QUESTION # 37
To reduce storage and compute costs, the data engineering team has been tasked with curating a series of aggregate tables leveraged by business intelligence dashboards, customer-facing applications, production machine learning models, and ad hoc analytical queries.
The data engineering team has been made aware of new requirements from a customer-facing application, which is the only downstream workload they manage entirely. As a result, an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added.
Which of the solutions addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed?
Answer: E
Explanation:
This is the correct answer because it addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed. The situation is that an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added, due to new requirements from a customer-facing application. By configuring a new table with all the requisite fields and new names and using this as the source for the customer-facing application, the data engineering team can meet the new requirements without affecting other teams that rely on the existing table schema and name. By creating a view that maintains the original data schema and table name by aliasing select fields from the new table, the data engineering team can also avoid duplicating data or creating additional tables that need to be managed.
NEW QUESTION # 38
......
We stick to the principle "Credit management first and first class service". While purchasing our Databricks-Certified-Data-Engineer-Professional exma questions, not only you have no need to worry about the quality of our Databricks-Certified-Data-Engineer-Professional exam materials quality but also our service is satisfying on the Databricks-Certified-Data-Engineer-Professional study guide. We promise buyers “Pass Guaranteed” and we only offer the latest Databricks-Certified-Data-Engineer-Professional Training Materials. If you would like to choose safely high passing rate of Databricks-Certified-Data-Engineer-Professional exam torrent materials, our Databricks-Certified-Data-Engineer-Professional learning guide will be the first choice for you.
Databricks-Certified-Data-Engineer-Professional Valid Exam Tutorial: https://www.pass4sures.top/Databricks-Certification/Databricks-Certified-Data-Engineer-Professional-testking-braindumps.html