Databricks-Certified-Professional-Data-Engineer Databricks Certified Professional Data Engineer Exam Pass4sure Zertifizierung & Databricks Certified Professional Data Engineer Exam zuverlässige Prüfung Übung

BONUS!!! Laden Sie die vollständige Version der EchteFrage Databricks-Certified-Professional-Data-Engineer Prüfungsfragen kostenlos herunter: https://drive.google.com/open?id=1mlqLy4mw9Al3Qsa44vrQuFpJSuFtkFcK
Wir EchteFrage bietet Ihnen die Prüfungsfragen und Antworten zur Databricks Databricks-Certified-Professional-Data-Engineer von höchster Qualität, damit Sie viel näher von Ihrem Erfolg sind. Wenn Sie noch ein paar Sorgen haben, können Sie die Databricks-Certified-Professional-Data-Engineer Demo durch die Webseite EchteFrage herunterladen. Hier versprechen wir Ihnen, dass wir Ihnen noch einjähriger Aktualisierung kostenlos anbieten werden, nachdem Sie die Prüfungsfragen und Antworten zur Databricks Databricks-Certified-Professional-Data-Engineer gekauft haben.
Databricks Databricks-Certified-Professional-Data-Engineer Exam Syllabus Topics:
| Section | Objectives |
|---|
| Production Pipelines and Orchestration | - Pipeline reliability and fault tolerance
- Automate ETL pipelines and scheduling
- Build and manage workflows using Databricks Jobs
|
| Data Ingestion and Transformation | - Transform and clean datasets using Spark SQL and DataFrame APIs
- Ingest data using Apache Spark and Databricks
- Handle batch and streaming data pipelines
|
| Data Modeling and Storage | - Delta Lake table design and optimization
- Design scalable data lakehouse architectures
- Schema evolution and data partitioning strategies
|
| Security, Governance, Monitoring, and Optimization | - Implement Unity Catalog governance and access control
- Cost optimization and performance tuning
- Monitor and optimize Spark workloads
|
>> Databricks-Certified-Professional-Data-Engineer Fragen&Antworten <<
Databricks-Certified-Professional-Data-Engineer PDF & Databricks-Certified-Professional-Data-Engineer Testking
EchteFrage ist eine Website, die den Traum vielen IT-Fachleuten erfüllen kann. Wenn Sie einen IT-Traum haben, dann wählen Sie doch EchteFrage. Die Fragenkataloge zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung von EchteFrage sind von vielen IT-Fachleuten begehrt, die Ihnen helfen, die Databricks-Certified-Professional-Data-Engineer Zertifizierung zu bestehen und im Berufsleben befördert zu werden.
Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer Prüfungsfragen mit Lösungen (Q69-Q74):
69. Frage
The viewupdatesrepresents an incremental batch of all newly ingested data to be inserted or updated in the customerstable.
The following logic is used to process these records.
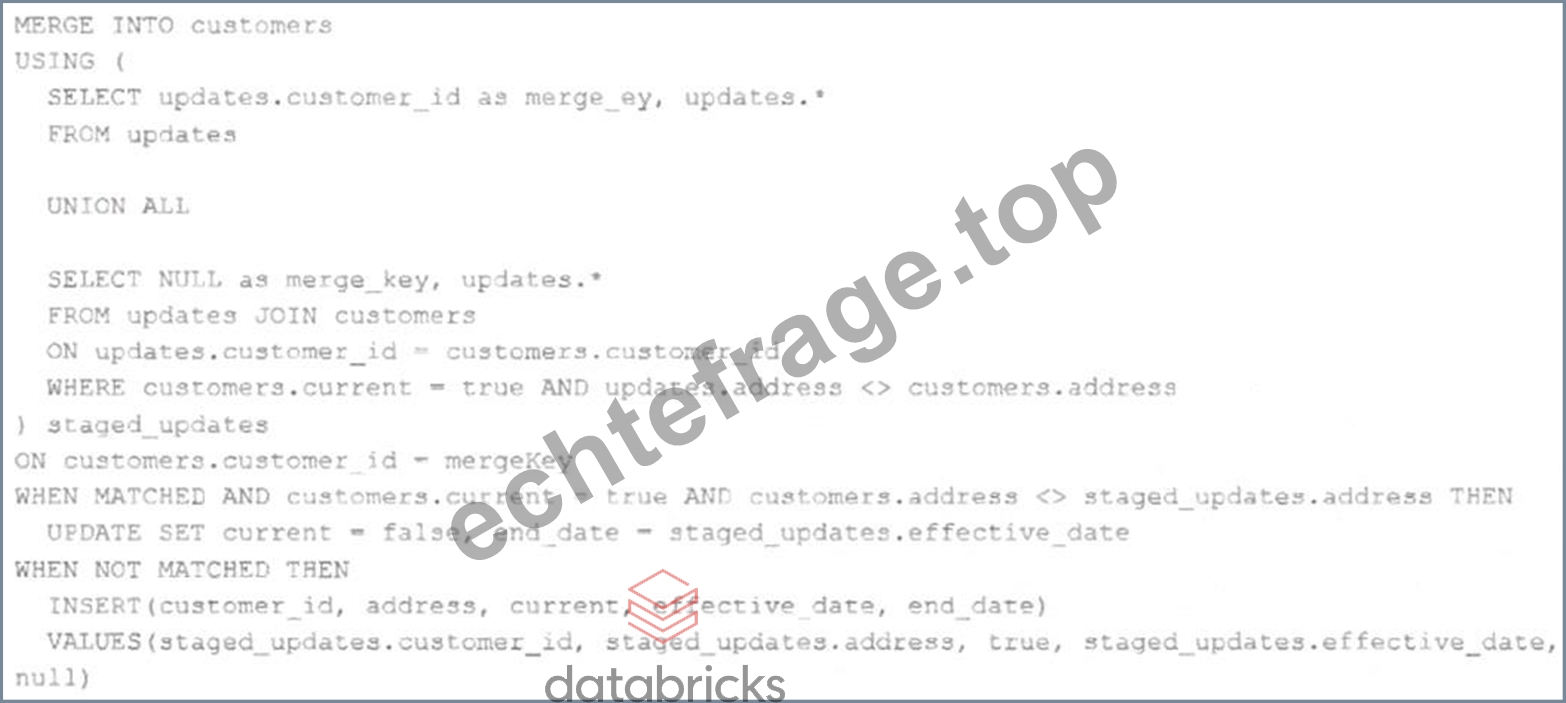
Which statement describes this implementation?
- A. The customers table is implemented as a Type 2 table; old values are overwritten and new customers are appended.
- B. The customers table is implemented as a Type 2 table; old values are maintained but marked as no longer current and new values are inserted.
- C. The customers table is implemented as a Type 1 table; old values are overwritten by new values and no history is maintained.
- D. The customers table is implemented as a Type 0 table; all writes are append only with no changes to existing values.
- E. The customers table is implemented as a Type 3 table; old values are maintained as a new column alongside the current value.
Antwort: B
Begründung:
The logic uses the MERGE INTO command to merge new records from the view updates into the table customers. The MERGE INTO command takes two arguments: a target table and a source table or view. The command also specifies a condition to match records between the target and the source, and a set of actions to perform when there is a match or not. In this case,the condition is to match records by customer_id, which is the primary key of the customers table. The actions are to update the existing record in the target with the new values from the source, and set the current_flag to false to indicate that the record is no longer current; and to insert a new record in the target with the new values from the source, and set the current_flag to true to indicate that the record is current. This means that old values are maintained but marked as no longer current and new values are inserted, which is the definition of a Type 2 table. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Merge Into (Delta Lake on Databricks)" section.
70. Frage
A data engineer needs to capture pipeline settings from an existing in the workspace, and use them to create and version a JSON file to create a new pipeline.
Which command should the data engineer enter in a web terminal configured with the Databricks CLI?
- A. Use the get command to capture the settings for the existing pipeline; remove the pipeline_id and rename the pipeline; use this in a create command
- B. Use list pipelines to get the specs for all pipelines; get the pipeline spec from the return results parse and use this to create a pipeline
- C. Stop the existing pipeline; use the returned settings in a reset command
- D. Use the alone command to create a copy of an existing pipeline; use the get JSON command to get the pipeline definition; save this to git
Antwort: A
Begründung:
The Databricks CLI provides a way to automate interactions with Databricks services. When dealing with pipelines, you can use the databricks pipelines get --pipeline-id command to capture the settings of an existing pipeline in JSON format. This JSON can then be modified by removing the pipeline_id to prevent conflicts and renaming the pipeline to create a new pipeline. The modified JSON file can then be used with the databricks pipelines create command to create a new pipeline with those settings.
Reference:
Databricks Documentation on CLI for Pipelines: Databricks CLI - Pipelines
71. Frage
A data engineer is configuring a Databricks Asset Bundle to deploy a job with granular permissions. The requirements are:
* Grant the data-engineers group CAN_MANAGE access to the job.
* Ensure the auditors' group can view the job but not modify/run it.
* Avoid granting unintended permissions to other users/groups.
How should the data engineer deploy the job while meeting the requirements?
- A. resources:
jobs:
my-job:
name: data-pipeline
tasks: [...]
job: [...]
permissions:
- group_name: data-engineers
level: CAN_MANAGE
permissions:
- group_name: auditors
level: CAN_VIEW - B. resources:
jobs:
my-job:
name: data-pipeline
tasks: [...]
job_clusters: [...]
permissions:
- group_name: data-engineers
level: CAN_MANAGE
- group_name: auditors
level: CAN_VIEW
- group_name: admin-team
level: IS_OWNER - C. permissions:
- group_name: data-engineers
level: CAN_MANAGE
- group_name: auditors
level: CAN_VIEW
resources:
jobs:
my-job:
name: data-pipeline
tasks: [...]
job_clusters: [...] - D. resources:
jobs:
my-job:
name: data-pipeline
tasks: [...]
job_clusters: [...]
permissions:
- group_name: data-engineers
level: CAN_MANAGE
- group_name: auditors
level: CAN_VIEW
Antwort: D
Begründung:
Comprehensive and Detailed Explanation from Databricks Documentation:
Databricks Asset Bundles (DABs) allow jobs, clusters, and permissions to be defined as code in YAML configuration files. According to the Databricks documentation on job permissions and bundle deployment, when defining permissions within a job resource, they must be scoped directly under that specific job's definition. This ensures that permissions are applied only to the intended job resource and not inadvertently propagated to other jobs or resources.
In this scenario, the data engineer must grant the data-engineers group CAN_MANAGE access, allowing them to configure, edit, and manage the job, while the auditors group should only have CAN_VIEW, giving them read-only access to see configurations and results without the ability to modify or execute. Importantly, no additional groups should be granted permissions, in order to follow the principle of least privilege.
Options A and B introduce unnecessary or unintended groups (like admin-team in A) or define permissions outside of the job scope (as in B). Option C improperly separates the permissions block outside the job resource, which is not aligned with Databricks bundle best practices.
Option D is the correct approach because it defines the job resource my-job with its name, tasks, clusters, and the exact intended permissions (CAN_MANAGE for data-engineers and CAN_VIEW for auditors). This aligns with Databricks' principle of least privilege and ensures compliance with governance standards in Unity Catalog-enabled workspaces.
72. Frage
A senior data engineer is planning large-scale data workflows. The task is to identify the considerations that form a foundation for creating scalable data models for managing large datasets. The team has listed Delta Lake capabilities and wants to determine which feature should not be considered as a core factor.
Which key feature can be ignored while evaluating Delta Lake?
- A. Delta Lake optimizes metadata handling, efficiently managing billions of files and facilitating scalability to petabyte-scale datasets.
- B. Delta Lake's ability to process data in both batch and streaming modes seamlessly, providing flexibility in ingestion and processing.
- C. Delta Lake works with various data formats (Parquet, JSON, CSV) and integrates well with Spark and Databricks tools.
- D. Delta Lake provides limited support for monitoring and troubleshooting data pipelines, so relevant partner tools have to be identified and set up for enhanced operational efficiency.
Antwort: D
Begründung:
The Databricks documentation emphasizes that Delta Lake provides robust capabilities for batch and streaming unification, scalable metadata management, and seamless integration with Databricks and Apache Spark. These are core design principles for building modern, scalable data platforms. However, the statement claiming that Delta provides "limited support for monitoring and troubleshooting" is not valid . Delta Lake itself includes comprehensive logging, event history tracking, and data lineage via the transaction log, and integrates with Databricks' built-in monitoring tools. Hence, such a limitation is not a design consideration when evaluating Delta Lake's scalability. Therefore, this statement (D) can be ignored, as it does not reflect Delta Lake's documented capabilities.
73. Frage
The Databricks workspace administrator has configured interactive clusters for each of the data engineering groups. To control costs, clusters are set to terminate after 30 minutes of inactivity. Each user should be able to execute workloads against their assigned clusters at any time of the day.
Assuming users have been added to a workspace but not granted any permissions, which of the following describes the minimal permissions a user would need to start and attach to an already configured cluster.
- A. Cluster creation allowed. "Can Restart" privileges on the required cluster
- B. Workspace Admin privileges, cluster creation allowed. "Can Attach To" privileges on the required cluster
- C. Cluster creation allowed. "Can Attach To" privileges on the required cluster
- D. "Can Manage" privileges on the required cluster
- E. "Can Restart" privileges on the required cluster
Antwort: E
Begründung:
Explanation
https://learn.microsoft.com/en-us/azure/databricks/security/auth-authz/access-control/cluster-acl
https://docs.databricks.com/en/security/auth-authz/access-control/cluster-acl.html
74. Frage
......
Möchten Sie die Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsrüfung mühlos bestehen? Die SchulungsMaterialien von EchteFrage über Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierung sind eine gute Wahl. Die Testaufgaben von Databricks Databricks-Certified-Professional-Data-Engineer Prüfung aus EchteFrage enthalten alle Inhalte und Antworten, die Sie bei der Databricks-Certified-Professional-Data-Engineer Prüfung wissen müssen. Daher können Sie in begrenzter Zeit die Schwerpunkte der Databricks-Certified-Professional-Data-Engineer Prüfung greifen und einmalig bestehen, so dass Sie Ihren beruflichen Wert erhöhen und näher zu ihrem Erfolg kommen können.
Databricks-Certified-Professional-Data-Engineer PDF: https://www.echtefrage.top/Databricks-Certified-Professional-Data-Engineer-deutsch-pruefungen.html
- Databricks-Certified-Professional-Data-Engineer German 👙 Databricks-Certified-Professional-Data-Engineer Schulungsangebot Ⓜ Databricks-Certified-Professional-Data-Engineer Fragenpool 🎁 Suchen Sie auf der Webseite ☀ www.zertpruefung.ch ️☀️ nach ➤ Databricks-Certified-Professional-Data-Engineer ⮘ und laden Sie es kostenlos herunter 🐽Databricks-Certified-Professional-Data-Engineer Lernhilfe
- Databricks-Certified-Professional-Data-Engineer Databricks Certified Professional Data Engineer Exam neueste Studie Torrent - Databricks-Certified-Professional-Data-Engineer tatsächliche prep Prüfung 🛷 ▷ www.itzert.com ◁ ist die beste Webseite um den kostenlosen Download von { Databricks-Certified-Professional-Data-Engineer } zu erhalten 🤟Databricks-Certified-Professional-Data-Engineer Prüfungs
- Databricks-Certified-Professional-Data-Engineer Lernhilfe 🍕 Databricks-Certified-Professional-Data-Engineer Prüfungs 🖋 Databricks-Certified-Professional-Data-Engineer German 🌰 Sie müssen nur zu 《 de.fast2test.com 》 gehen um nach kostenloser Download von ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ zu suchen 🎅Databricks-Certified-Professional-Data-Engineer Prüfungsvorbereitung
- Databricks-Certified-Professional-Data-Engineer Examengine 🤫 Databricks-Certified-Professional-Data-Engineer Testfagen ♿ Databricks-Certified-Professional-Data-Engineer Prüfungen 🕠 Öffnen Sie die Website ▛ www.itzert.com ▟ Suchen Sie ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ Kostenloser Download 🌍Databricks-Certified-Professional-Data-Engineer Schulungsangebot
- Databricks-Certified-Professional-Data-Engineer Deutsch Prüfung 🟧 Databricks-Certified-Professional-Data-Engineer Deutsch Prüfung ⌚ Databricks-Certified-Professional-Data-Engineer Deutsch Prüfung 🤕 Suchen Sie auf ➥ www.echtefrage.top 🡄 nach ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ und erhalten Sie den kostenlosen Download mühelos 🤠Databricks-Certified-Professional-Data-Engineer Fragenpool
- Databricks-Certified-Professional-Data-Engineer Fragen Beantworten 🪕 Databricks-Certified-Professional-Data-Engineer German 🎇 Databricks-Certified-Professional-Data-Engineer Testfagen 💒 Suchen Sie jetzt auf { www.itzert.com } nach ➽ Databricks-Certified-Professional-Data-Engineer 🢪 um den kostenlosen Download zu erhalten 🧍Databricks-Certified-Professional-Data-Engineer Pruefungssimulationen
- Databricks-Certified-Professional-Data-Engineer Musterprüfungsfragen - Databricks-Certified-Professional-Data-EngineerZertifizierung - Databricks-Certified-Professional-Data-EngineerTestfagen ✔ Suchen Sie jetzt auf 《 www.pruefungfrage.de 》 nach 「 Databricks-Certified-Professional-Data-Engineer 」 und laden Sie es kostenlos herunter 📁Databricks-Certified-Professional-Data-Engineer Fragen Beantworten
- Databricks-Certified-Professional-Data-Engineer Prüfungsvorbereitung 🧿 Databricks-Certified-Professional-Data-Engineer Examengine 😤 Databricks-Certified-Professional-Data-Engineer Lerntipps 🏵 Erhalten Sie den kostenlosen Download von ( Databricks-Certified-Professional-Data-Engineer ) mühelos über ➽ www.itzert.com 🢪 👉Databricks-Certified-Professional-Data-Engineer Testfagen
- Databricks-Certified-Professional-Data-Engineer Fragen Beantworten 🌤 Databricks-Certified-Professional-Data-Engineer Testfagen 🏴 Databricks-Certified-Professional-Data-Engineer Zertifizierungsfragen 🚚 Erhalten Sie den kostenlosen Download von { Databricks-Certified-Professional-Data-Engineer } mühelos über ➠ www.pass4test.de 🠰 👎Databricks-Certified-Professional-Data-Engineer Trainingsunterlagen
- Databricks-Certified-Professional-Data-Engineer Testking 🐣 Databricks-Certified-Professional-Data-Engineer Trainingsunterlagen 🦯 Databricks-Certified-Professional-Data-Engineer Pruefungssimulationen 🌾 Geben Sie ✔ www.itzert.com ️✔️ ein und suchen Sie nach kostenloser Download von ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ 💈Databricks-Certified-Professional-Data-Engineer Fragenpool
- Databricks-Certified-Professional-Data-Engineer Deutsch Prüfung ⚽ Databricks-Certified-Professional-Data-Engineer Simulationsfragen ⬛ Databricks-Certified-Professional-Data-Engineer Lernhilfe 🦸 Öffnen Sie die Webseite 「 www.pruefungfrage.de 」 und suchen Sie nach kostenloser Download von “ Databricks-Certified-Professional-Data-Engineer ” 🛰Databricks-Certified-Professional-Data-Engineer Deutsch Prüfung
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
2026 Die neuesten EchteFrage Databricks-Certified-Professional-Data-Engineer PDF-Versionen Prüfungsfragen und Databricks-Certified-Professional-Data-Engineer Fragen und Antworten sind kostenlos verfügbar: https://drive.google.com/open?id=1mlqLy4mw9Al3Qsa44vrQuFpJSuFtkFcK