P.S. Free & New AI-300 dumps are available on Google Drive shared by ActualCollection: https://drive.google.com/open?id=1fQtUs1X4otTEoTR2UwnNhLCzYoimm0q_
The ActualCollection is committed to presenting the excellent viable observe cloth to prevail within the Microsoft AI-300 examination. With actual PDF questions, customizable exercise checks, and 24/7 guide, customers can be assured that they're getting the fine possible prep cloth. The AI-300 is a fantastic choice for absolutely everyone looking to increase their profession with the AI-300 certification. Purchase Now.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
| Topic 2: Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Topic 3: Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Topic 4: Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
| Topic 5: Implement machine learning model lifecycle and operations | 25–30% | - Monitor and maintain models in production
|
>> AI-300 Test Score Report <<
The Operationalizing Machine Learning and Generative AI Solutions (AI-300) practice questions are designed by experienced and qualified Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam trainers. They have the expertise, knowledge, and experience to design and maintain the top standard of Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam dumps. So rest assured that with the Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam real questions you can not only ace your Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam dumps preparation but also get deep insight knowledge about Microsoft AI-300 exam topics. So download Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam questions now and start this journey.
NEW QUESTION # 118
Drag and Drop Question
A team is deploying a new version of a customer scoring model to a production online endpoint in Azure Machine Learning.
The team must minimize risk by gradually introducing the new model version and ensuring that traffic can be reverted immediately if issues occur.
You need to roll out the new model according to the requirements.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.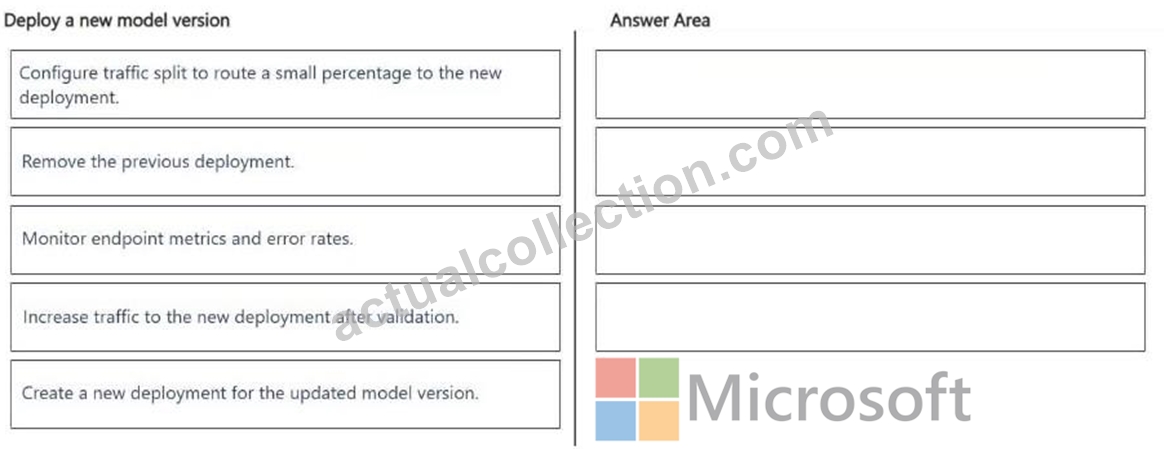
Answer:
Explanation: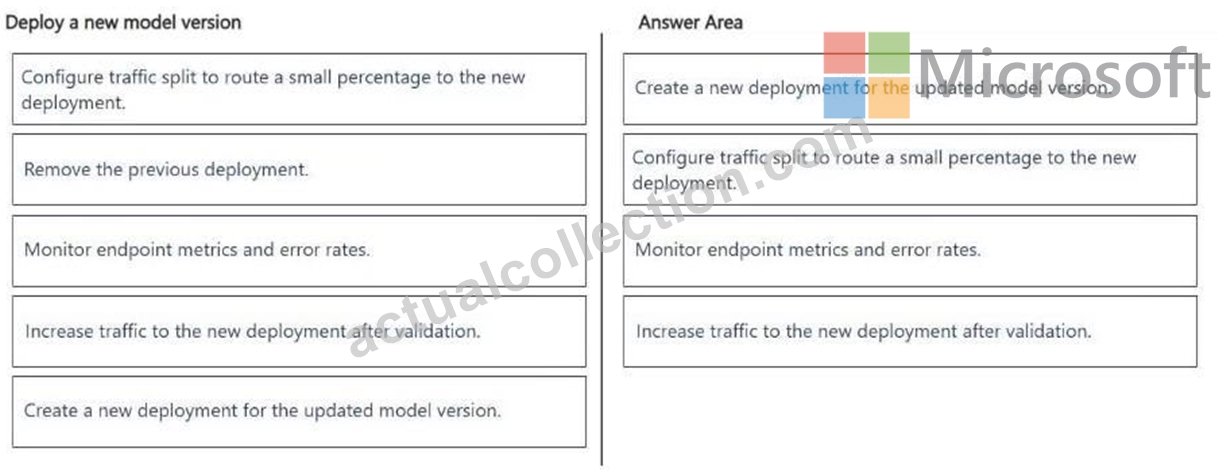
Explanation:
To safely deploy your new customer scoring model with minimal risk, you should use Azure Machine Learning managed online endpoints with a blue-green deployment strategy. This allows you to test the new model (green) alongside the old model (blue) and route traffic gradually.
Here is the step-by-step process to execute this rollout.
Step 1: Create a New Deployment for the updated model version.
1. Create a New Deployment under the Existing Endpoint
Do not overwrite your current production deployment. Instead, deploy the new model version as a separate deployment within the same managed online endpoint.
Keep the existing deployment (e.g., blue-deployment) running at 100% traffic.
Create the new deployment (e.g., green-deployment) with the new model version.
Set the initial traffic allocation for the new deployment to 0%.
2. Test the New Deployment in Isolation [Step not in this question]
Before exposing real customers to the new model, test its stability and performance in the production environment.
Send test scoring requests directly to the green-deployment.
Use the X-MS-Routing-Override: green-deployment HTTP header in your SDK or REST requests to bypass the traffic split and target the new model directly.
Verify that the data schema, latency, and prediction outputs match your expectations.
Step 2: Configure traffic split to route a small percentage to the new deployment.
3. Gradually Shift Traffic (Canary Testing)
Once internal testing passes, begin introducing real production traffic to the new model in phases.
3a. Update the endpoint's traffic configuration to route a small percentage (e.g., 10%) to green- deployment. [Step 2] Step 3: Monitor endpoint metrics and error rates.
3b) Monitor system metrics closely, looking for spikes in HTTP 4xx/5xx errors, timeouts, or unusual scoring distributions. [Step 3] Step 4: Increase traffic to the new deployment after validation
3c) If performance remains stable over a designated observation period, incrementally increase the traffic (e.g., to 30%, 50%, then 100%). [Step 4] Further future actions outside the context of the question:
4. Monitor App Insights and MetricsAzure ML integrates natively with Azure Monitor and Application Insights. Track these critical metrics during the shift:CPU/Memory Utilization: Ensure the new model does not exhaust container resources.
Model Latency: Compare the response times of the new deployment against the old one.
Tracking Token/Feature Drift: Ensure the live customer data matches the model's expected input feature distribution.
5. Instant Rollback Plan
If the new model causes errors, triggers high latency, or skews customer scores, you can revert traffic immediately.
Update the endpoint traffic settings to route 100% of traffic back to the original blue-deployment.
Set the green-deployment traffic to 0%.This configuration change takes effect almost instantly, isolating the faulty model without any downtime for your users.
Keep the green-deployment alive at 0% traffic while you pull the logs to investigate the root cause, then delete it once fixed.
Incorrect:
[Remove the previous deployment]
A step further in the future.
Reference:
https://chandras4bigdata.medium.com/mlops-interview-and-study-guide-489d13ff82fa
NEW QUESTION # 119
When comparing prompt variants, the team plans to assess whether the generated responses are grammatically correct.
You need to evaluate the quality of the language from the generated responses.
Which evaluator should you use?
Answer: A
Explanation:
In Microsoft Foundry ' s built-in evaluation framework, each evaluator measures a specific dimension of language quality. Fluency evaluates the grammatical correctness, sentence structure, and overall linguistic smoothness of generated text. A high fluency score means the response reads naturally, with proper grammar, punctuation, and sentence construction - regardless of factual accuracy or relevance to the topic. Coherence (option A) measures whether ideas flow logically from one sentence to the next - it is about logical structure, not grammar. Textual Similarity (option B) measures how closely the generated text matches a reference text using metrics like ROUGE or BLEU - it is a comparison metric, not a standalone quality dimension. Groundedness (option C) measures whether claims are supported by the provided context - it is a factual fidelity metric. For grammatical correctness specifically, Fluency is the correct evaluator.
Microsoft Learn Reference Topic: Built-in AI evaluators in Microsoft Foundry - Fluency, Coherence, Groundedness, and Similarity
NEW QUESTION # 120
A product team is building a customer support assistant that must respond consistently across multiple channels.
Early testing shows that small wording changes in prompts cause large differences in tone and factual accuracy.
The team needs prompts that are reliable, reusable, and adaptable across multiple use cases without retraining the underlying model.
You need to design prompts that improve response quality while remaining flexible for future changes.
Which two actions should you perform? Each correct answer presents part of the solution. (Choose two.)
Answer: B,D
Explanation:
B and C provide the strongest architecture for reusable and predictable prompts. Separating persistent application instructions from dynamic user input establishes a clear instruction hierarchy . The stable portion of the prompt can define application behavior while channel-specific or request-specific content remains variable. This reduces coupling between user wording and the behavioral rules of the assistant and makes the prompt easier to reuse, version, test, and modify.
The system prompt should establish the model ' s role, behavioral boundaries, tone, communication style, response format, and other persistent rules. Microsoft specifically describes system messages as high-priority instructions used to define an assistant ' s role and boundaries and to set tone and communication style.
Fine-tuning for every conversational variation is unnecessarily expensive and contradicts the requirement to remain adaptable without retraining. Increasing temperature increases randomness and therefore works against consistent responses. Although repeating important instructions can sometimes mitigate recency effects, Microsoft treats this as an optional prompt-engineering technique to experiment with, not the primary architectural technique for producing reusable prompts.
Study Guide Reference: Design and implement a GenAIOps infrastructure - design and develop prompts, prompt management, prompt variants, system instructions, and reusable prompt structures.
NEW QUESTION # 121
You run Azure Machine Learning training experiments. The training scripts directory contains 100 files that includes a file named .amlignore. The directory also contains subdirectories named ./outputs and ./logs.
There are 20 files in the training scripts directory that must be excluded from the snapshot to the compute targets. You create a file named .gitignore in the root of the directory. You add the names of the 20 files to the .gitignore file. These 20 files continue to be copied to the compute targets.
You need to exclude the 20 files.
What should you do?
Answer: B
Explanation:
To exclude the 20 files from the training snapshot, you must add the file names to the .amlignore file located in the root of your training scripts directory.
Why the Files Are Still Copying
Azure Machine Learning training experiments use a specific order of precedence when creating a directory snapshot for compute targets:
.amlignore takes absolute priority: If an .amlignore file exists in the directory, Azure ML only respects the rules inside it. It completely ignores any .gitignore file present.
.gitignore is a fallback: Azure ML only respects .gitignore rules if an .amlignore file does not exist in the directory. Because you have both files, the .gitignore file is being completely bypassed.
Reference:
https://learn.microsoft.com/en-us/python/api/azureml-core/azureml.core.experiment.experiment
NEW QUESTION # 122
A team is building a Retrieval-Augmented Generation (RAG) system.
The team observes that the retrieved documents are often irrelevant or incomplete.
You need to improve retrieval accuracy.
What should you adjust?
Answer: A
Explanation:
To best improve retrieval accuracy when documents are irrelevant or incomplete, you should adjust Chunk size and overlap.
Fixes Irrelevant Retrievals: If your chunks are too large, they pack in multiple unrelated topics.
This adds noise, dilutes the semantic vector, and causes the system to pull in massive blocks of text where only a single sentence was actually relevant. Tuning the size ensures chunks stay highly specific.
Fixes Incomplete Retrievals: If your chunks are too small or lack sufficient overlap, vital context gets completely cut off at the boundaries. Adding an optimal overlap (typically 10%-20%) ensures that a sentence split across a boundary preserves its surrounding meaning, keeping the context whole.
Incorrect:
[Not B]
Temperature parameter: This is a generative LLM setting that dictates the creativity or randomness of the output text. It has absolutely zero control over the vector search database or the specific documents picked during the initial retrieval phase.
[Not C]¨
Token limits: This caps how much context you can pass into the prompt window or how much text the model can generate. While a higher limit lets you pass more documents, it does not magically fix the underlying data quality or prevent the retrieval algorithm from pulling in wrong files.
[Not D]
Embedding strategy: While choosing a stronger model or fine-tuning embeddings changes how text is numerically represented, it cannot overcome poorly structured data. Even the best embedding model cannot successfully capture semantic meaning if your data ingestion pipeline is feeding it randomly sliced, incomplete paragraphs Reference:
https://pmc.ncbi.nlm.nih.gov/articles/PMC12649634/
NEW QUESTION # 123
......
Many people worry about that they have no time for practice the AI-300 exam dumps and the cost of test is high. If you failed the test, it will be terrible to you. Getting the Microsoft certification quickly seems impossible to you. Maybe our AI-300 Dumps PDF is a better choice for you. It will help you get clear real exam quickly and effectively.
Test AI-300 Passing Score: https://www.actualcollection.com/AI-300-exam-questions.html
BONUS!!! Download part of ActualCollection AI-300 dumps for free: https://drive.google.com/open?id=1fQtUs1X4otTEoTR2UwnNhLCzYoimm0q_