P.S. Tech4ExamがGoogle Driveで共有している無料かつ新しいMLA-C01ダンプ:https://drive.google.com/open?id=14DPrX-MKNu3TnPt42JvODnBHdkKNJvKx
クライアントの時間を節約するために、MLA-C01実践ガイドを購入してから5〜10分後にクライアントに製品をメール形式で送信し、情報を簡素化して学習と学習に数十時間しか必要としないようにします。テストの準備をします。 MLA-C01ガイド資料の使用過程で発生する問題をクライアントが解決できるように、クライアントはいつでも学習資料に関する問題について相談できます。したがって、当社のMLA-C01トレーニング資料は人を対象としたものであり、クライアントの経験を重要な地位に置いていると言えます。
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Related Certifications: | AWS Certified AI Practitioner AWS Certified Machine Learning - Specialty |
| Certificate Validity Period: | 3 years |
| Real Exam Qty: | 65 (50 scored, 15 unscored) |
| Exam Price: | 150 USD |
| Exam Duration: | 130 minutes |
| Passing Score: | 720 (scaled score 100–1000) |
| Available Languages: | Japanese, English, Simplified Chinese, Korean |
| Exam Format: | Ordering, Multiple response, Multiple choice, Matching, Case study |
| Recommended Training: | AWS Training and Certification AWS Certified Machine Learning Engineer - Associate Official Exam Guide |
| Exam Registration: | Pearson VUE Registration AWS Certification Portal |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE testing centers |
| Pre Condition: | Recommended: 1+ year hands-on experience with AWS services and machine learning engineering; familiarity with Amazon SageMaker and related ML services. No mandatory prerequisite exams. |
| Official Syllabus URL: | https://docs.aws.amazon.com/aws-certification/latest/machine-learning-engineer-associate-01/machine-learning-engineer-associate-01.html |
IT業種の発展はますます速くなることにつれて、ITを勉強する人は急激に多くなりました。人々は自分が将来何か成績を作るようにずっと努力しています。IT領域の人々にとって、Amazon試験の資格認証は重要な表現です。自分の能力を証明するために、MLA-C01試験に合格する必要があります。弊社のMLA-C01模擬問題集を入手して、試験に合格する把握が大きくなります。努力すれば、あなたは美しい未来が見えます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
質問 # 78
A company has a custom extract, transform, and load (ETL) process that runs on premises. The ETL process is written in the R language and runs for an average of 6 hours. The company wants to migrate the process to run on AWS.
Which solution will meet these requirements?
正解:C
解説:
The ETL process has two critical characteristics: it is long-running (6 hours) and written in R. AWS Lambda is unsuitable because it has a maximum execution time of 15 minutes. AWS Glue primarily supports Spark- based ETL and does not natively support custom R-based workloads.
AWS documentation recommends using Amazon SageMaker Processing Jobs for long-running, custom data processing workloads. Processing jobs allow users to run arbitrary code in custom Docker containers, making them ideal for migrating on-premises ETL jobs written in R.
By building a custom Docker image that includes the R runtime and required libraries and storing it in Amazon ECR, the company can run the ETL job at scale on managed infrastructure without rewriting the code.
SageMaker script mode is intended for training, not ETL. Therefore, SageMaker processing jobs with a custom container are the correct solution.
質問 # 79
Case Study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
Before the ML engineer trains the model, the ML engineer must resolve the issue of the imbalanced data.
Which solution will meet this requirement with the LEAST operational effort?
正解:C
質問 # 80
A company is working on an ML project that will include Amazon SageMaker notebook instances.
An ML engineer must ensure that the SageMaker notebook instances do not allow root access.
Which solution will prevent the deployment of notebook instances that allow root access?
正解:C
質問 # 81
A company has a conversational AI assistant that sends requests through Amazon Bedrock to an Anthropic Claude large language model (LLM). Users report that when they ask similar questions multiple times, they sometimes receive different answers. An ML engineer needs to improve the responses to be more consistent and less random.
Which solution will meet these requirements?
正解:A
質問 # 82
An ML engineer needs to use Amazon SageMaker Feature Store to create and manage features to train a model.
Select and order the steps from the following list to create and use the features in Feature Store. Each step should be selected one time. (Select and order three.)
* Access the store to build datasets for training.
* Create a feature group.
* Ingest the records.
正解:
解説:
Explanation: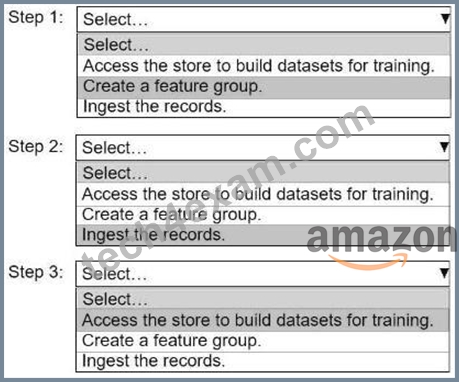
Step 1: Create a feature group.
Step 2: Ingest the records.
Step 3: Access the store to build datasets for training.
* Step 1: Create a Feature Group
* Why? A feature group is the foundational unit in SageMaker Feature Store, where features are defined, stored, and organized. Creating a feature group specifies the schema (name, data type) for the features and the primary keys for data identification.
* How? Use the SageMaker Python SDK or AWS CLI to define the feature group by specifying its name, schema, and S3 storage location for offline access.
* Step 2: Ingest the Records
* Why? After creating the feature group, the raw data must be ingested into the Feature Store. This step populates the feature group with data, making it available for both real-time and offline use.
* How? Use the SageMaker SDK or AWS CLI to batch-ingest historical data or stream new records into the feature group. Ensure the records conform to the feature group schema.
* Step 3: Access the Store to Build Datasets for Training
* Why? Once the features are stored, they can be accessed to create training datasets. These datasets combine relevant features into a single format for machine learning model training.
* How? Use the SageMaker Python SDK to query the offline store or retrieve real-time features using the online store API. The offline store is typically used for batch training, while the online store is used for inference.
Order Summary:
* Create a feature group.
* Ingest the records.
* Access the store to build datasets for training.
This process ensures the features are properly managed, ingested, and accessible for model training using Amazon SageMaker Feature Store.
質問 # 83
......
MLA-C01模擬資料: https://www.tech4exam.com/MLA-C01-pass-shiken.html
P.S.Tech4ExamがGoogle Driveで共有している無料の2026 Amazon MLA-C01ダンプ:https://drive.google.com/open?id=14DPrX-MKNu3TnPt42JvODnBHdkKNJvKx