DP-700専門試験 & DP-700日本語対策問題集

2026年MogiExamの最新DP-700 PDFダンプおよびDP-700試験エンジンの無料共有:https://drive.google.com/open?id=1gEac7z1j_N8bzW8jLFQu3UbXBh400PQ-
時々重要な試験に合格するために大量の問題をする必要があります。我々の提供するソフトはこの要求をよく満たして専門的な解答の分析はあなたの理解にヘルプを提供できます。MicrosoftのDP-700試験の資料のいくつかのバーションのデモは我々のウェブサイトで無料でダウンロードできます。あなたの愛用する版をやってみよう。我々の共同の努力はあなたに順調にMicrosoftのDP-700試験に合格させることができます。
Microsoft DP-700 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Implement and manage an analytics solution | 30–35% | - Manage data lifecycle and governance
- 1. Implement data governance with Microsoft Purview
- 2. Manage data access and security
- 3. Implement data retention and archiving
- Configure workspace settings
- 1. Configure Microsoft Fabric workspace settings
- 2. Configure domain workspace settings
- 3. Configure Spark workspace settings
- 4. Configure Dataflows Gen2 settings
- 5. Configure OneLake workspace settings
- Manage data storage
- 1. Create and manage OneLake shortcuts
- 2. Choose appropriate data stores
- 3. Implement data mirroring
|
| Ingest and transform data | 30–35% | - Design and implement data loading patterns
- 1. Design streaming data loading patterns
- 2. Prepare data for dimensional models
- 3. Design full and incremental data loads
- Orchestrate data operations
- 1. Orchestrate with notebooks and pipelines
- 2. Implement schedules and triggers
- 3. Use parameters and dynamic expressions
- Ingest data
- 1. Ingest data using pipelines
- 2. Ingest data using Eventstreams
- 3. Ingest data using Dataflows Gen2
- Transform data
- 1. Transform data using KQL
- 2. Transform data using PySpark
- 3. Clean, denormalize, and aggregate data
- 4. Transform data using SQL
|
| Monitor and optimize an analytics solution | 30–35% | - Optimize performance
- 1. Optimize Spark and query performance
- 2. Optimize pipelines and data flows
- 3. Optimize Lakehouse and data warehouse performance
- 4. Optimize storage efficiency
- Monitor analytics solutions
- 1. Configure alerts and notifications
- 2. Monitor data ingestion and transformation
- 3. Monitor semantic model refreshes
- 4. Monitor Fabric items and activities
- Troubleshoot issues
- 1. Identify and resolve Dataflow errors
- 2. Identify and resolve notebook and Spark errors
- 3. Identify and resolve pipeline errors
- 4. Identify and resolve storage and query errors
|
>> DP-700専門試験 <<
DP-700日本語対策問題集 & DP-700日本語版復習資料
教材をシミュレートするDP-700のページでは、サンプルの質問であるデモを提供しています。デモを提供する目的は、お客様にトピックの私たちの部分を理解してもらうことと、それが開かれたときの学習資料の形式は何ですか?私たちの考えでは、これら2つのことは、DP-700試験に関心のあるお客様が最も心配しているということです。製品ページにアクセスできるクリック可能なWebサイトであるソフトウェアを提供します。 DP-700試験でマークされた赤いボックスはデモです。 PDFバージョンを無料でダウンロードでき、3つの形式すべてをクリックして表示できます。
Microsoft Implementing Data Engineering Solutions Using Microsoft Fabric 認定 DP-700 試験問題 (Q109-Q114):
質問 # 109
You have a Fabric workspace named Workspace1 that contains a notebook named Notebook1.
In Workspace1, you create a new notebook named Notebook2.
You need to ensure that you can attach Notebook2 to the same Apache Spark session as Notebook1.
What should you do?
- A. Enable high concurrency for notebooks.
- B. Change the runtime version.
- C. Increase the number of executors.
- D. Enable dynamic allocation for the Spark pool.
正解:A
解説:
To ensure that Notebook2 can attach to the same Apache Spark session as Notebook1, you need to enable high concurrency for notebooks. High concurrency allows multiple notebooks to share a Spark session, enabling them to run within the same Spark context and thus share resources like cached data, session state, and compute capabilities. This is particularly useful when you need notebooks to run in sequence or together while leveraging shared resources.
質問 # 110
You are developing a data engineering solution in Fabric by using Apache Spark.
You need to monitor the performance of Spark workloads the solution must meet the following requirements
* Provide comprehensive information about the performance of the data engineering workloads.
* Identify stages and tasks that run slowly.
* Minimize administrative effort
What should you use?
- A. the Spark Ul
- B. Spark job event logs
- C. workspace metrics in Fabric
- D. Spark application logs
正解:A
質問 # 111
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric eventstream that loads data into a table named Bike_Location in a KQL database. The table contains the following columns:
BikepointID
Street
Neighbourhood
No_Bikes
No_Empty_Docks
Timestamp
You need to apply transformation and filter logic to prepare the data for consumption. The solution must return data for a neighbourhood named Sands End when No_Bikes is at least 15. The results must be ordered by No_Bikes in ascending order.
Solution: You use the following code segment:

Does this meet the goal?
正解:A
解説:
This code does not meet the goal because this is an SQL-like query and cannot be executed in KQL, which is required for the database.
Correct code should look like:

質問 # 112
You have two Fabric notebooks named Load_Salesperson and Load_Orders that read data from Parquet files in a lakehouse. Load_Salesperson writes to a Delta table named dim_salesperson. Load.Orders writes to a Delta table named fact_orders and is dependent on the successful execution of Load_Salesperson.
You need to implement a pattern to dynamically execute Load_Salesperson and Load_Orders in the appropriate order by using a notebook.
How should you complete the code? To answer, drag the appropriate values the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
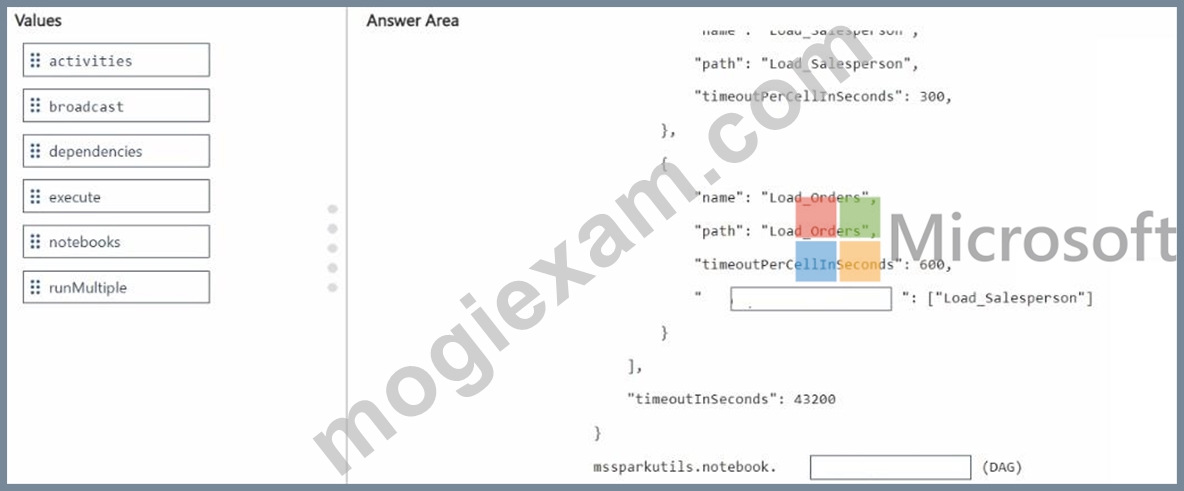
正解:
解説:
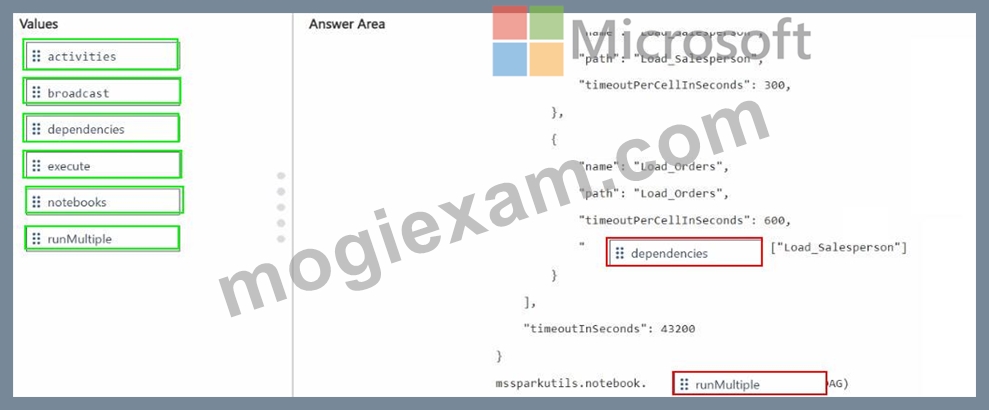
質問 # 113
You are building a data orchestration pattern by using a Fabric data pipeline named Dynamic Data Copy as shown in the exhibit. (Click the Exhibit tab.)
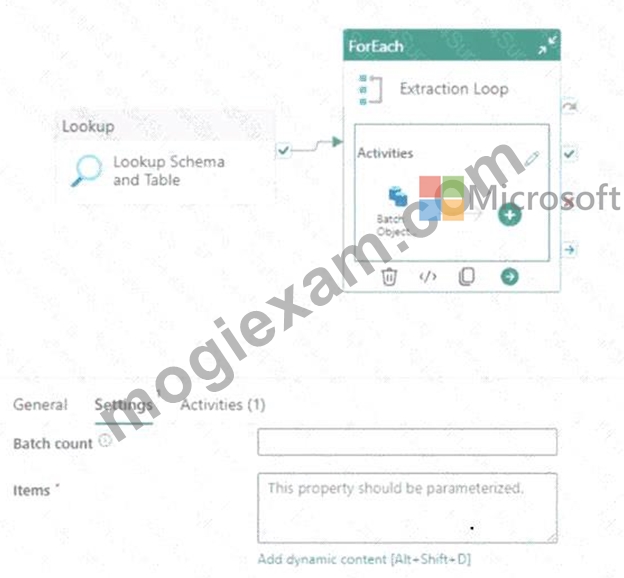
Dynamic Data Copy does NOT use parametrization.
You need to configure the ForEach activity to receive the list of tables to be copied.
How should you complete the pipeline expression? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.

正解:
解説:

Explanation:

質問 # 114
......
MogiExamは毎日24時間オンラインに顧客に対してサービスを提供するアフターサービスはとても良いサイトでございます。最新なDP-700情報を1年間に無料にアップデートしております。少ないお金をかかって、一回に合格しましょう。MogiExamの問題集は最大のお得だね!
DP-700日本語対策問題集: https://www.mogiexam.com/DP-700-exam.html
- DP-700試験の準備方法|実用的なDP-700専門試験試験|素敵なImplementing Data Engineering Solutions Using Microsoft Fabric日本語対策問題集 🦲 ▛ www.xhs1991.com ▟で➠ DP-700 🠰を検索し、無料でダウンロードしてくださいDP-700試験過去問
- 100%合格率のDP-700専門試験試験-試験の準備方法-高品質なDP-700日本語対策問題集 🎰 サイト➠ www.goshiken.com 🠰で▛ DP-700 ▟問題集をダウンロードDP-700試験解答
- 実際的なDP-700専門試験 - 合格スムーズDP-700日本語対策問題集 | 便利なDP-700日本語版復習資料 🌜 ➠ www.shikenpass.com 🠰は、▷ DP-700 ◁を無料でダウンロードするのに最適なサイトですDP-700試験過去問
- DP-700試験概要 😥 DP-700試験概要 🦍 DP-700資料的中率 🔜 ☀ www.goshiken.com ️☀️サイトで✔ DP-700 ️✔️の最新問題が使えるDP-700過去問無料
- 試験DP-700専門試験 - 一生懸命にDP-700日本語対策問題集 | 正確的なDP-700日本語版復習資料 Implementing Data Engineering Solutions Using Microsoft Fabric 🚌 [ www.japancert.com ]に移動し、【 DP-700 】を検索して、無料でダウンロード可能な試験資料を探しますDP-700過去問無料
- DP-700過去問無料 🤷 DP-700日本語試験情報 🤨 DP-700試験概要 😶 ⮆ DP-700 ⮄を無料でダウンロード▛ www.goshiken.com ▟で検索するだけDP-700専門試験
- DP-700模擬問題 🍙 DP-700試験概要 📉 DP-700過去問無料 🌰 ➽ www.xhs1991.com 🢪で➽ DP-700 🢪を検索して、無料でダウンロードしてくださいDP-700日本語試験情報
- 試験DP-700専門試験 - 一生懸命にDP-700日本語対策問題集 | 正確的なDP-700日本語版復習資料 Implementing Data Engineering Solutions Using Microsoft Fabric 💨 サイト▛ www.goshiken.com ▟で[ DP-700 ]問題集をダウンロードDP-700試験過去問
- DP-700試験の準備方法|ユニークなDP-700専門試験試験|検証するImplementing Data Engineering Solutions Using Microsoft Fabric日本語対策問題集 ↘ ➽ www.xhs1991.com 🢪サイトにて最新➡ DP-700 ️⬅️問題集をダウンロードDP-700資格受験料
- DP-700最新の認定試験勉強資料、DP-700試験内容、DP-700出題傾向 👋 [ www.goshiken.com ]サイトで▛ DP-700 ▟の最新問題が使えるDP-700資格勉強
- DP-700過去問無料 📒 DP-700専門試験 😲 DP-700試験時間 👄 《 www.goshiken.com 》から簡単に➡ DP-700 ️⬅️を無料でダウンロードできますDP-700合格受験記
- pixabay.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, quay.io, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, learn.csisafety.com.au, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. MogiExamがGoogle Driveで共有している無料かつ新しいDP-700ダンプ:https://drive.google.com/open?id=1gEac7z1j_N8bzW8jLFQu3UbXBh400PQ-