If you have some doubts about the accuracy of NCM-MCI-6.10 top questions. There are free demo of latest exam cram for you to download. Besides, you can free updating Nutanix braindumps torrent one-year after you purchase. We adhere to the principle of No Help, Full Refund, if you failed the exam with our NCM-MCI-6.10 Valid Dumps, we will full refund you.
| Section | Weight | Objectives |
|---|---|---|
| Business Continuity and Disaster Recovery | 15% | - Replication and recovery configuration - Disaster recovery strategy implementation - Failover and failback operations - BCDR testing and validation |
| Advanced Platform Configuration and Troubleshooting | 25% | - Cluster management, expansion and maintenance - Integration with third-party systems - Prism Central and Prism Element configuration - Security configuration and compliance - API and CLI-based operations |
| Analyze and Optimize Storage Performance | 20% | - Understand storage internals and I/O patterns - Optimize storage configuration and settings - Evaluate and resolve competing workload requirements - Troubleshoot storage performance bottlenecks |
| Monitoring, Automation and Operational Efficiency | 5% | - Operational process optimization - Monitoring and alerting configuration - Automation workflows and tools |
| Network Performance and Security | 20% | - Network troubleshooting and optimization - Optimize physical and virtual network configurations - Implement and analyze Flow security policies - Tune overlay networking and traffic flow |
| Virtualization and VM Performance Optimization | 15% | - Performance metrics analysis and tuning - High availability and migration management - AHV administration and workload management - VM resource adjustment and optimization |
Combined with your specific situation and the characteristics of our NCM-MCI-6.10 exam questions, our professional services will recommend the most suitable version of NCM-MCI-6.10 study materials for you. We introduce a free trial version of the NCM-MCI-6.10 learning guide because we want users to see our sincerity. NCM-MCI-6.10 exam prep sincerely hopes that you can achieve your goals and realize your dreams.
NEW QUESTION # 32
Task 2
Part1
An administrator logs into Prism Element and sees an alert stating the following:
Cluster services down on Controller VM (35.197.75.196)
Correct this issue in the least disruptive manner.
Part2
In a separate request, the security team has noticed a newly created cluster is reporting.
CVM [35.197.75.196] is using the default password.
They have provided some new security requirements for cluster level security.
Security requirements:
Update the default password for the root user on the node to match the admin user password: Note: 192.168.x.
x is not available. To access a node use the Host IP (172.30.0.x) from a CVM or the supplied external IP address.
Update the default password for the nutanix user on the CVM to match the admin user password.
Resolve the alert that is being reported.
Output the cluster-wide configuration of the SCMA policy to Desktop\Files\output.txt before changes are made.
Enable the Advance intrusion Detection Environment (AIDE) to run on a weekly basis for the cluster.
Enable high-strength password policies for the cluster.
Ensure CVMs require SSH keys for login instead of passwords. (SSH keys are located in the Desktop\Files\SSH folder).
Ensure the clusters meets these requirements. Do not reboot any cluster components.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To correct the issue of cluster services down on Controller VM (35.197.75.196) in the least disruptive manner, you need to do the following steps:
Log in to Prism Element using the admin user credentials.
Go to the Alerts page and click on the alert to see more details.
You will see which cluster services are down on the Controller VM. For example, it could be cassandra, curator, stargate, etc.
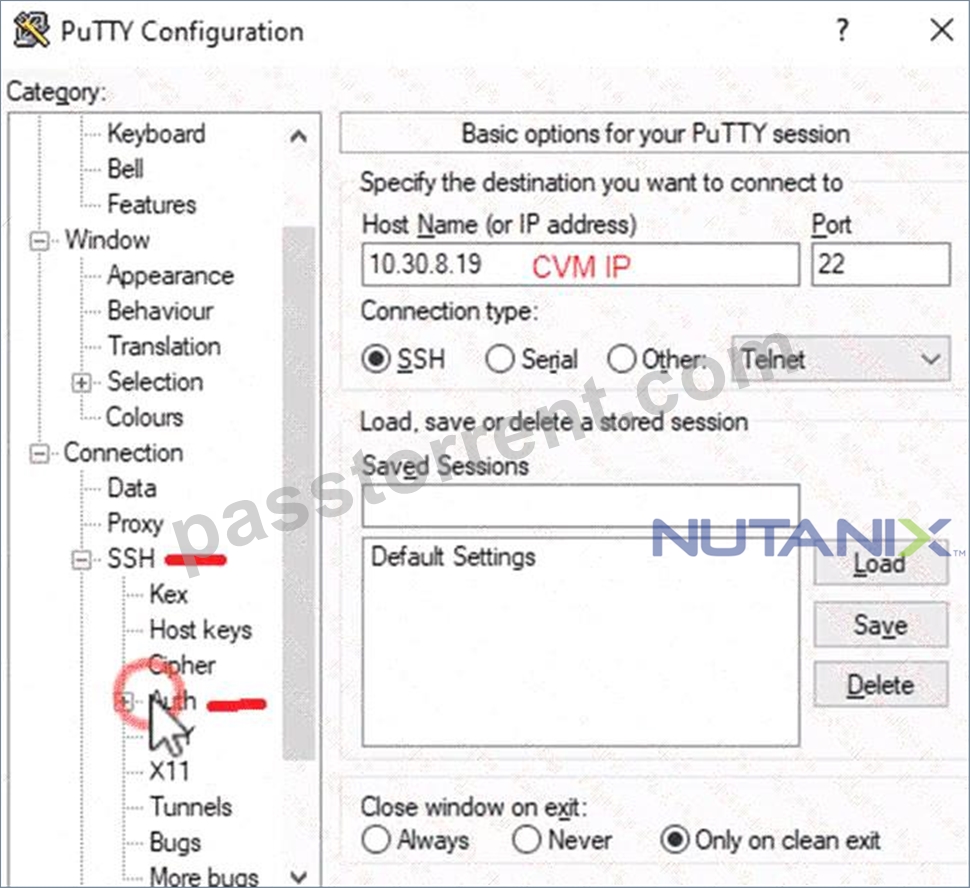
To start the cluster services, you need to SSH to the Controller VM using the nutanix user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the Controller VM. You will need the IP address and the password of the nutanix user, which you can find in Desktop\Files\SSH\nutanix.
txt.
Once you are logged in to the Controller VM, run the command:
cluster status | grep -v UP
This will show you which services are down on the Controller VM.
To start the cluster services, run the command:
cluster start
This will start all the cluster services on the Controller VM.
To verify that the cluster services are running, run the command:
cluster status | grep -v UP
This should show no output, indicating that all services are up.
To clear the alert, go back to Prism Element and click on Resolve in the Alerts page.
To meet the security requirements for cluster level security, you need to do the following steps:
To update the default password for the root user on the node to match the admin user password, you need to SSH to the node using the root user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the node. You will need the IP address and the password of the root user, which you can find in Desktop\Files\SSH\root.txt.
Once you are logged in to the node, run the command:
passwd
This will prompt you to enter a new password for the root user. Enter the same password as the admin user, which you can find in Desktop\Files\SSH\admin.txt.
To update the default password for the nutanix user on the CVM to match the admin user password, you need to SSH to the CVM using the nutanix user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the CVM. You will need the IP address and the password of the nutanix user, which you can find in Desktop\Files\SSH\nutanix.txt.
Once you are logged in to the CVM, run the command:
passwd
This will prompt you to enter a new password for the nutanix user. Enter the same password as the admin user, which you can find in Desktop\Files\SSH\admin.txt.
To resolve the alert that is being reported, go back to Prism Element and click on Resolve in the Alerts page.
To output the cluster-wide configuration of SCMA policy to Desktop\Files\output.txt before changes are made, you need to log in to Prism Element using the admin user credentials.
Go to Security > SCMA Policy and click on View Policy Details. This will show you the current settings of SCMA policy for each entity type.
Copy and paste these settings into a new text file named Desktop\Files\output.txt.
To enable AIDE (Advanced Intrusion Detection Environment) to run on a weekly basis for the cluster, you need to log in to Prism Element using the admin user credentials.
Go to Security > AIDE Configuration and click on Enable AIDE. This will enable AIDE to monitor file system changes on all CVMs and nodes in the cluster.
Select Weekly as the frequency of AIDE scans and click Save.
To enable high-strength password policies for the cluster, you need to log in to Prism Element using the admin user credentials.
Go to Security > Password Policy and click on Edit Policy. This will allow you to modify the password policy settings for each entity type.
For each entity type (Admin User, Console User, CVM User, and Host User), select High Strength as the password policy level and click Save.
To ensure CVMs require SSH keys for login instead of passwords, you need to log in to Prism Element using the admin user credentials.
Go to Security > Cluster Lockdown and click on Configure Lockdown. This will allow you to manage SSH access settings for the cluster.
Uncheck Enable Remote Login with Password. This will disable password-based SSH access to the cluster.
Click New Public Key and enter a name for the key and paste the public key value from Desktop\Files\SSH\id_rsa.pub. This will add a public key for key-based SSH access to the cluster.
Click Save and Apply Lockdown. This will apply the changes and ensure CVMs require SSH keys for login instead of passwords.
Part1
Enter CVM ssh and execute:
cluster status | grep -v UP
cluster start
If there are issues starting some services, check the following:
Check if the node is in maintenance mode by running the ncli host ls command on the CVM. Verify if the parameter Under Maintenance Mode is set to False for the node where the services are down. If the parameter Under Maintenance Mode is set to True, remove the node from maintenance mode by running the following command:
nutanix@cvm$ ncli host edit id=<host id> enable-maintenance-mode=false
You can determine the host ID by using ncli host ls.
See the troubleshooting topics related to failed cluster services in the Advanced Administration Guide available from the Nutanix Portal's Software Documentation page. (Use the filters to search for the guide for your AOS version). These topics have information about common and AOS-specific logs, such as Stargate, Cassandra, and other modules.
Check for any latest FATALs for the service that is down. The following command prints all the FATALs for a CVM. Run this command on all CVMs.
nutanix@cvm$ for i in `svmips`; do echo "CVM: $i"; ssh $i "ls -ltr /home/nutanix/data/logs/*.FATAL"; done NCC Health Check: cluster_services_down_check (nutanix.com) Part2 Vlad Drac2023-06-05T13:22:00.86I'll update this one with a smaller, if possible, command Update the default password for the root user on the node to match the admin user password echo -e "CHANGING ALL AHV HOST ROOT PASSWORDS.\nPlease input new password: "; read -rs password1; echo "Confirm new password: "; read -rs password2; if [ "$password1" == "$password2" ]; then for host in $(hostips); do echo Host $host; echo $password1 | ssh root@$host "passwd --stdin root"; done; else echo "The passwords do not match"; fi Update the default password for the nutanix user on the CVM sudo passwd nutanix Output the cluster-wide configuration of the SCMA policy ncli cluster get-hypervisor-security-config Output Example:
nutanix@NTNX-372a19a3-A-CVM:10.35.150.184:~$ ncli cluster get-hypervisor-security-config Enable Aide : false Enable Core : false Enable High Strength P... : false Enable Banner : false Schedule : DAILY Enable iTLB Multihit M... : false Enable the Advance intrusion Detection Environment (AIDE) to run on a weekly basis for the cluster.
ncli cluster edit-hypervisor-security-params enable-aide=true
ncli cluster edit-hypervisor-security-params schedule=weekly
Enable high-strength password policies for the cluster.
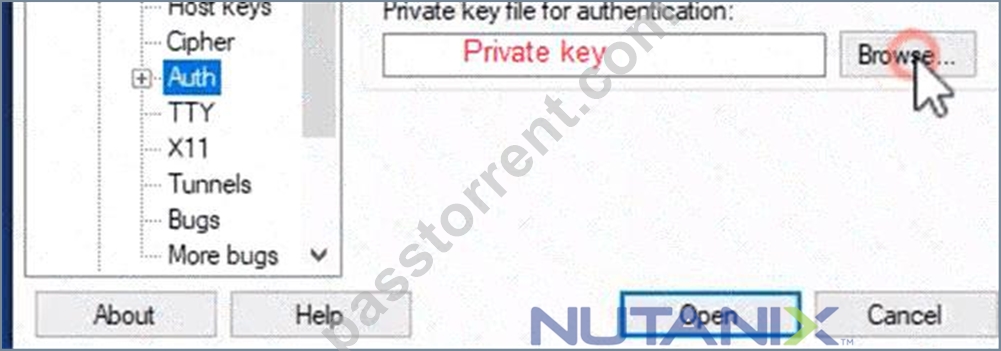
ncli cluster edit-hypervisor-security-params enable-high-strength-password=true Ensure CVMs require SSH keys for login instead of passwords
https://portal.nutanix.com/page/documents/kbs/details?targetId=kA0600000008gb3CAA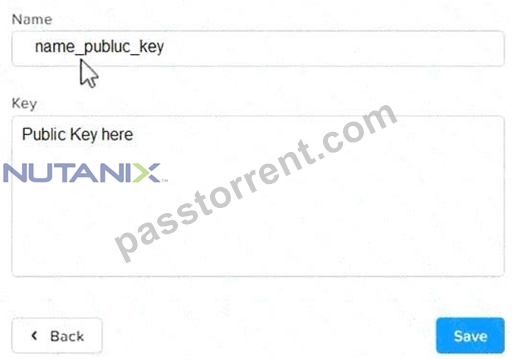
NEW QUESTION # 33
The security team has provided some new security requirements for cluster level security on Cluster 2.
Security requirements:
* Update the password for the root user on the Cluster 2 node to match the admin user password.
Note: The 192.168.x.x network is not available. To access a node use the host IP (172.30.0.x) from the CVM.
* Output the cluster-wide configuration of the SCMA policy to desktop\output.txt before changes are made.
* Enable the Advanced Intrusion Detection Environment (AIDE) to run on a weekly basis for the hypervisor and cvms for Cluster 2.
* Enable high-strength password policies for the hypervisor and cluster.
* Ensure CVMs require SSH keys for login instead of passwords. (SSH keys are located in the desktop\Files\SSH folder.) Ensure the cluster meets these requirements. Do not reboot any cluster components.
Note: Please ensure you are modifying the correct components.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to apply the security requirements to Cluster 2.
1. Access Cluster 2 Prism Element
First, we must access the Prism Element (PE) interface for Cluster 2, as most security settings are cluster- specific.
* From the Prism Central dashboard, navigate to Hardware > Clusters.
* Find Cluster 2 in the list and click its name. This will open the Prism Element login page for that specific cluster in a new tab.
* Log in to Cluster 2's Prism Element using the admin credentials.
2. Requirement: Update Node Root Password
This task syncs the root password for all AHV hypervisor nodes with the cluster's admin user password.
* In the Cluster 2 PE interface, click the gear icon (Settings) in the top right corner.
* Select Cluster Lockdown from the left-hand menu.
* Click the Set Root Password on All Hosts button.
* A dialog box will appear. Enter the current admin password (the one you just used to log in) into both the New Password and Confirm New Password fields.
* Click Save. This will propagate the admin password to the root user on all nodes in Cluster 2.
3. Requirement: Add CVM SSH Key
This task adds the security team's public key to the admin user, which is required before we can disable password-based login.
* On the desktop, navigate to the Files > SSH folder.
* Open the id_rsa.pub file (or equivalent public key file) with Notepad.
* Copy the entire string of text (e.g., ssh-rsa AAAA...).
* In the Cluster 2 PE interface, go to Settings (gear icon) > User Management.
* Select the admin user and click Modify User.
* Paste the copied public key into the Public Keys text box.
* Click Save.
4. Requirement: Apply SCMA Policies (All other requirements)
The remaining requirements are all applied via the command line on a CVM using Nutanix's Security Configuration Management Automation (SCMA).
* Access the CVM:
* Find a CVM IP for Cluster 2 by going to Hardware > CVMs in the PE interface.
* Open an SSH client (like PuTTY) and connect to that CVM's IP address.
* Log in with the username admin and the corresponding password.
* Output Current Policy (Req 2):
* Before making changes, run the following command to see the current policy:
ncli scma status
* Copy the entire output from your SSH terminal.
* Open Notepad on the desktop, paste the copied text, and Save the file to the desktop as output.
txt.
* Apply New Policies (Req 3, 4, 5):
* Run the following commands one by one. The cluster will apply them immediately without a reboot.
* Enable AIDE (Req 3):
ncli scma update aide-status=enabled aide-schedule=weekly
* Enable High-Strength Passwords (Req 4):
ncli scma update password-policy=high
* Require SSH Keys for CVMs (Req 5):
ncli scma update ssh-login=keys-only
Verification
You can verify all changes by running the status command again. The output should now reflect the new, hardened security posture.
ncli scma status
* AIDE Status: should show Enabled
* AIDE Schedule: should show Weekly
* Password Policy: should show High
* SSH Login: should show keys-only
NEW QUESTION # 34
Task 13
An administrator found a CentOS VM, Cent_Down, on the cluster with a corrupted network stack. To correct the issue, the VM will need to be restored from a previous snapshot to become reachable on the network again.
VM credentials:
Username: root
Password: nutanix/4u
Restore the VM and ensure it is reachable on the network by pinging 172.31.0.1 from the VM.
Power off the VM before proceeding.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To restore the VM and ensure it is reachable on the network, you can follow these steps:
Log in to the Web Console of the cluster where the VM is running.
Click on Virtual Machines on the left menu and find Cent_Down from the list. Click on the power icon to power off the VM.
Click on the snapshot icon next to the power icon to open the Snapshot Management window.
Select a snapshot from the list that was taken before the network stack was corrupted. You can use the date and time information to choose a suitable snapshot.
Click on Restore VM and confirm the action in the dialog box. Wait for the restore process to complete.
Click on the power icon again to power on the VM.
Log in to the VM using SSH or console with the username and password provided.
Run the command ping 172.31.0.1 to verify that the VM is reachable on the network. You should see a reply from the destination IP address.
Go to VMS from the prism central gui
Select the VMand go to More -> Guest Shutdown
Go to Snapshots tab and revert to latest snapshot available
power on vm and verify if ping is working
NEW QUESTION # 35
A company who offers Infrastructure as a Service needs to onboard a new customer. The new customer requires a dedicated cloud plan which tolerates two host failures.
The customer is planning to move current workloads in three waves, with three months between waves starting today:
* Wave One: 100 VMs
* Wave Two: 50 VMs
* Wave Three: 20 VMs
Workload profile is:
* vCPU: 4
* vRAM: 16 GB
* Storage: 200 GB
The service provider company needs to estimate required resources upfront, to accommodate customer requirements, considering also that:
* limit the number of total nodes
* selected system vendor HPE
* selected model DX365-10-G11-NVMe
* full-flash node (including NVMe + SSD)
* 12 months runway
Create and save the scenario as IaaS and export to the desktop, name the file IaaS-requirement.pdf Note: You must export the PDF to the desktop as IaaS-requirement.pdf to receive any credit.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to create and export the capacity planning scenario. This task is performed within Prism Central.
1. Navigate to the Planning Dashboard
* From the Prism Central main menu (hamburger icon), navigate to Operations > Planning.
2. Create and Define the Scenario
* Click the + Create Scenario button.
* In the dialog box:
* Scenario Name: IaaS
* Scenario Type: Select New Workload
* Click Create. This will open the scenario editor.
3. Configure Cluster and Runway Settings
* In the "IaaS" scenario editor, find the Runway setting (top left) and set it to 12 Months.
* Find the Cluster configuration tile and click Edit.
* Set Number of Host Failures to Tolerate to 2.
* Click Save.
4. Define the Workload Profile
* In the Workloads section, click the + Add Workload button.
* Select Create a new workload profile.
* Fill in the VM specifications:
* Workload Name: Customer-VM (or similar)
* vCPU per VM: 4
* Memory per VM: 16 GB
* Storage per VM: 200 GB
* Click Add.
5. Set the Workload Growth Plan (Waves)
* You will be returned to the main scenario editor. In the timeline section ("Workload Plan"), add the VMs:
* Wave One (Today):
* Click + Add under the "Today" column.
* Select the Customer-VM profile.
* Enter 100 VMs.
* Click Add.
* Wave Two (3 Months):
* Click the + icon on the timeline itself.
* Set the date to 3 Months from today.
* Click + Add under this new "3 Months" column.
* Select the Customer-VM profile.
* Enter 50 VMs.
* Click Add.
* Wave Three (6 Months):
* Click the + icon on the timeline.
* Set the date to 6 Months from today.
* Click + Add under this new "6 Months" column.
* Select the Customer-VM profile.
* Enter 20 VMs.
* Click Add.
6. Select the Hardware
* In the Hardware configuration tile, click Change Hardware.
* In the "Select Hardware" pane:
* Vendor: Select HPE.
* Model: Search for and select DX365-10-G11-NVMe.
* Note: This model is full-flash by definition, satisfying the requirement.
* Click Done. The planner will recalculate the required nodes.
7. Save and Export the Scenario
* Click the Save icon (floppy disk) in the top-right corner to save the IaaS scenario.
* Click the Export icon (arrow pointing down) in the top-right corner.
* Select PDF from the dropdown menu.
* A "Save As" dialog will appear.
* Navigate to the Desktop.
* Set the file name to IaaS-requirement.pdf.
* Click Save.
NEW QUESTION # 36
An administrator is experiencing an unidentified issue which is causing inode exhaustion on CVMs in Cluster
1. The time between receiving alerts and exhaustion is too short; the administrator needs to lower the alert thresholds to allow more time to clean up inodes until the issue has been identified and resolution implemented.
From Prism Element, modify the appropriate alert policy setting critical threshold for Cluster 1 to 60% and warning threshold to 45%. Ensure the check runs every minute and is not resolved without administrator action.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to modify the alert policy from the Prism Element (PE) interface for Cluster 1.
1. Access Cluster 1 Prism Element
* From the main Prism Central dashboard, navigate to Hardware > Clusters.
* Find Cluster 1 in the list and click its name. This will open the specific Prism Element login page for that cluster.
* Log in to Cluster 1's Prism Element interface.
2. Modify the Alert Policy
* In the Cluster 1 PE interface, click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Alert Policies.
* In the search bar, type inode to find the correct policy.
* Select the checkbox for the policy named cvm_inode_usage_high.
* Click the Update button.
* In the "Update Alert Policy" dialog, configure the following settings:
* Warning Threshold (%): Change the value to 45.
* Critical Threshold (%): Change the value to 60.
* Check Interval (Secs): Change the value to 60 (to run the check every minute).
* Auto Resolve: Uncheck this box (to ensure the alert is not resolved without administrator action).
* Click Save.
NEW QUESTION # 37
......
Firstly, our company always feedbacks our candidates with highly-qualified NCM-MCI-6.10 study guide and technical excellence and continuously developing the most professional NCM-MCI-6.10 exam materials. Secondly, our NCM-MCI-6.10 training materials persist in creating a modern service oriented system and strive for providing more preferential activities for your convenience. Last but not least, we have free demos for your reference, as in the following, you can download which NCM-MCI-6.10 Exam Braindumps demo you like and make a choice.
New Braindumps NCM-MCI-6.10 Book: https://www.passtorrent.com/NCM-MCI-6.10-latest-torrent.html