Our Databricks-Certified-Professional-Data-Engineer test torrent keep a look out for new ways to help you approach challenges and succeed in passing the Databricks Certified Professional Data Engineer Exam exam. An ancient Chinese proverb states that “The journey of a thousand miles starts with a single step”. To be recognized as the leading international exam bank in the world through our excellent performance, our Databricks Certified Professional Data Engineer Exam qualification test are being concentrated on for a long time and have accumulated mass resources and experience in designing study materials. There is plenty of skilled and motivated staff to help you obtain the Databricks Certified Professional Data Engineer Exam exam certificate that you are looking forward. We have faith in our professional team and our Databricks-Certified-Professional-Data-Engineer Study Tool, and we also wish you trust us wholeheartedly.
Databricks Certified Professional Data Engineer certification exam is designed for data engineers who work with Databricks. Databricks-Certified-Professional-Data-Engineer exam tests the candidate's ability to design, build, and maintain data pipelines, as well as their knowledge of various data engineering tools and techniques. Databricks-Certified-Professional-Data-Engineer Exam is intended to validate the candidate's proficiency in using Databricks for data engineering tasks.
>> Databricks-Certified-Professional-Data-Engineer Certification Exam Cost <<
There are three different kinds of our Databricks-Certified-Professional-Data-Engineer exam questions: the PDF, Software and APP online. And i love the Software for the best for no matter how many software you have installed on your computers, our Databricks-Certified-Professional-Data-Engineer learning materials will never be influenced. Also, our Databricks-Certified-Professional-Data-Engineer Study Guide just need to be opened with internet service for the first time. Later, you can freely take it everywhere as long as you use it in the Windows system.
Databricks Certified Professional Data Engineer Exam is an online exam that can be taken from anywhere in the world. Databricks-Certified-Professional-Data-Engineer exam is timed and consists of multiple-choice questions and hands-on tasks that require the candidate to demonstrate their ability to perform specific tasks using Databricks. Databricks-Certified-Professional-Data-Engineer Exam is designed to be challenging and requires a thorough understanding of Databricks data engineering concepts and techniques.
NEW QUESTION # 98
John Smith is a newly joined team member in the Marketing team who currently has access read access to sales tables but does not have access to delete rows from the table, which of the following commands help you accomplish this?
Answer: E
Explanation:
Explanation
The answer is GRANT MODIFY ON TABLE table_name TO john.smith@marketing.com , please note INSERT, UPDATE, and DELETE are combined into one role called MODIFY.
Below are the list of privileges that can be granted to a user or a group, SELECT: gives read access to an object.
CREATE: gives the ability to create an object (for example, a table in a schema).
MODIFY: gives the ability to add, delete, and modify data to or from an object.
USAGE: does not give any abilities, but is an additional requirement to perform any action on a schema object.
READ_METADATA: gives the ability to view an object and its metadata.
CREATE_NAMED_FUNCTION: gives the ability to create a named UDF in an existing catalog or schema.
MODIFY_CLASSPATH: gives the ability to add files to the Spark classpath.
ALL PRIVILEGES: gives all privileges (is translated into all the above privileges
NEW QUESTION # 99
A workspace admin has created a new catalog called finance_data and wants to delegate permission management to a finance team lead without giving them full admin rights.
Which privilege should be granted to the finance team lead?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The MANAGE privilege in Unity Catalog provides the ability to grant and revoke privileges on the specified object (in this case, a catalog) without giving full administrative access or ownership.
This is the Databricks-recommended approach for delegating governance responsibilities while preserving the principle of least privilege.
By contrast, the ALL PRIVILEGES option grants excessive access (including read and write permissions), and metastore admin status provides global control over all catalogs-far exceeding the requirement. The MANAGE privilege enables the finance team lead to control access to objects within finance_data responsibly while limiting overall administrative exposure.
NEW QUESTION # 100
You were asked to create a table that can store the below data, orderTime is a timestamp but the finance team when they query this data normally prefer the orderTime in date format, you would like to create a calculated column that can convert the orderTime column timestamp datatype to date and store it, fill in the blank to complete the DDL.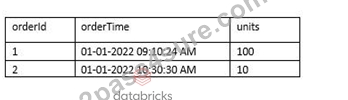
Answer: A
Explanation:
Explanation
The answer is, GENERATED ALWAYS AS (CAST(orderTime as DATE))
https://docs.microsoft.com/en-us/azure/databricks/delta/delta-batch#--use-generated-columns Delta Lake supports generated columns which are a special type of columns whose values are au-tomatically generated based on a user-specified function over other columns in the Delta table. When you write to a table with generated columns and you do not explicitly provide values for them, Delta Lake automatically computes the values.
Note: Databricks also supports partitioning using generated column
NEW QUESTION # 101
To identify the top users consuming compute resources, a data engineering team needs to monitor usage within their Databricks workspace for better resource utilization and cost control. The team decided to use Databricks system tables, available under the System catalog in Unity Catalog, to gain detailed visibility into workspace activity.
Which SQL query should the team run from the System catalog to achieve this?
A)
SELECT sku_name,
identity_metadata.created_by AS user_email,
COUNT(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10
B)
SELECT identity_metadata.run_as AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email
ORDER BY total_dbus DESC
LIMIT 10
C)
SELECT sku_name,
identity_metadata.created_by AS user_email,
SUM(usage_quantity * usage_unit) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10
D)
SELECT sku_name,
usage_metadata.run_name AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The system.billing.usage table in the Unity Catalog System schema provides detailed usage metrics for each workload in the workspace. The field identity_metadata.run_as identifies the user or service principal under which the job or query executed. Summing usage_quantity provides total DBU (Databricks Unit) consumption per user. According to Databricks documentation, this table is the authoritative source for monitoring workspace cost drivers, showing compute SKU, user, and DBU consumption over time. Grouping by identity_metadata.run_as and summing usage_quantity produces the correct aggregation to determine top users. Other queries use non-existent or incorrect fields (created_by, run_name, or multiplied usage quantities), which do not reflect actual billing metrics.
NEW QUESTION # 102
An analytics team wants to run a short-term experiment in Databricks SQL on the customer transactions Delta table (about 20 billion records) created by the data engineering team. Which strategy should the data engineering team use to ensure minimal downtime and no impact on the ongoing ETL processes?
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "A shallow clone creates a copy of the metadata that references the source data files; it is fast and inexpensive." Exact extract: "A deep clone copies the data." Exact extract: "Clones provide a point-in-time snapshot for experimentation without impacting the source."
NEW QUESTION # 103
......
Databricks-Certified-Professional-Data-Engineer Latest Test Discount: https://www.2pass4sure.com/Databricks-Certification/Databricks-Certified-Professional-Data-Engineer-actual-exam-braindumps.html