P.S. Free & New Data-Engineer-Associate dumps are available on Google Drive shared by PDFDumps: https://drive.google.com/open?id=14EoJYkoqAFEBCIBC4PU6U4sM5TgqsJrV
The company is preparing for the test candidates to prepare the Data-Engineer-Associate Study Materials professional brand, designed to be the most effective and easiest way to help users through their want to get the test Data-Engineer-Associate certification and obtain the relevant certification. In comparison with similar educational products, our training materials are of superior quality and reasonable price, so our company has become the top enterprise in the international market.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Store Management | 26% | - Design data models
|
| Topic 2: Data Security and Governance | 18% | - Manage data privacy and compliance
|
| Topic 3: Data Ingestion and Transformation | 34% | - Apply programming concepts
|
| Topic 4: Data Operations and Support | 22% | - Manage and troubleshoot data processes
|
>> Data-Engineer-Associate Latest Braindumps Questions <<
These AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) mock tests will give you real Data-Engineer-Associate exam experience. This feature will boost your confidence when taking the AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) certification exam. The 24/7 support system has been made for you so you don't feel difficulty while using the product. In addition, we offer free demos and up to 1 year of free Amazon Dumps updates. Buy It Now!
NEW QUESTION # 201
A company receives a daily file that contains customer data in .xls format. The company stores the file in Amazon S3. The daily file is approximately 2 GB in size.
A data engineer concatenates the column in the file that contains customer first names and the column that contains customer last names. The data engineer needs to determine the number of distinct customers in the file.
Which solution will meet this requirement with the LEAST operational effort?
Answer: A
Explanation:
AWS Glue DataBrew is a visual data preparation tool that allows you to clean, normalize, and transform data without writing code. You can use DataBrew to create recipes that define the steps to apply to your data, such as filtering, renaming, splitting, or aggregating columns. You can also use DataBrew to run jobs that execute the recipes on your data sources, such as Amazon S3, Amazon Redshift, or Amazon Aurora. DataBrew integrates with AWS Glue Data Catalog, which is a centralized metadata repository for your data assets1.
The solution that meets the requirement with the least operational effort is to use AWS Glue DataBrew to create a recipe that uses the COUNT_DISTINCT aggregate function to calculate the number of distinct customers. This solution has the following advantages:
* It does not require you to write any code, as DataBrew provides a graphical user interface that lets you explore, transform, and visualize your data. You can use DataBrew to concatenate the columns that contain customer first names and last names, and then use the COUNT_DISTINCT aggregate function to count the number of unique values in the resulting column2.
* It does not require you to provision, manage, or scale any servers, clusters, or notebooks, as DataBrew is a fully managed service that handles all the infrastructure for you. DataBrew can automatically scale up or down the compute resources based on the size and complexity of your data and recipes1.
* It does not require you to create or update any AWS Glue Data Catalog entries, as DataBrew can automatically create and register the data sources and targets in the Data Catalog. DataBrew can also use the existing Data Catalog entries to access the data in S3 or other sources3.
Option A is incorrect because it suggests creating and running an Apache Spark job in an AWS Glue notebook. This solution has the following disadvantages:
* It requires you to write code, as AWS Glue notebooks are interactive development environments that allow you to write, test, and debug Apache Spark code using Python or Scala. You need to use the Spark SQL or the Spark DataFrame API to read the S3 file and calculate the number of distinct customers.
* It requires you to provision and manage a development endpoint, which is a serverless Apache Spark environment that you can connect to your notebook. You need to specify the type and number of workers for your development endpoint, and monitor its status and metrics.
* It requires you to create or update the AWS Glue Data Catalog entries for the S3 file, either manually or using a crawler. You need to use the Data Catalog as a metadata store for your Spark job, and specify the database and table names in your code.
Option B is incorrect because it suggests creating an AWS Glue crawler to create an AWS Glue Data Catalog of the S3 file, and running SQL queries from Amazon Athena to calculate the number of distinct customers.
This solution has the following disadvantages:
* It requires you to create and run a crawler, which is a program that connects to your data store, progresses through a prioritized list of classifiers to determine the schema for your data, and then creates metadata tables in the Data Catalog. You need to specify the data store, the IAM role, the schedule, and the output database for your crawler.
* It requires you to write SQL queries, as Amazon Athena is a serverless interactive query service that allows you to analyze data in S3 using standard SQL. You need to use Athena to concatenate the columns that contain customer first names and last names, and then use the COUNT(DISTINCT) aggregate function to count the number of unique values in the resulting column.
Option C is incorrect because it suggests creating and running an Apache Spark job in Amazon EMR Serverless to calculate the number of distinct customers. This solution has the following disadvantages:
* It requires you to write code, as Amazon EMR Serverless is a service that allows you to run Apache Spark jobs on AWS without provisioning or managing any infrastructure. You need to use the Spark SQL or the Spark DataFrame API to read the S3 file and calculate the number of distinct customers.
* It requires you to create and manage an Amazon EMR Serverless cluster, which is a fully managed and scalable Spark environment that runs on AWS Fargate. You need to specify the cluster name, the IAM role, the VPC, and the subnet for your cluster, and monitor its status and metrics.
* It requires you to create or update the AWS Glue Data Catalog entries for the S3 file, either manually or using a crawler. You need to use the Data Catalog as a metadata store for your Spark job, and specify the database and table names in your code.
:
1: AWS Glue DataBrew - Features
2: Working with recipes - AWS Glue DataBrew
3: Working with data sources and data targets - AWS Glue DataBrew
[4]: AWS Glue notebooks - AWS Glue
[5]: Development endpoints - AWS Glue
[6]: Populating the AWS Glue Data Catalog - AWS Glue
[7]: Crawlers - AWS Glue
[8]: Amazon Athena - Features
[9]: Amazon EMR Serverless - Features
[10]: Creating an Amazon EMR Serverless cluster - Amazon EMR
[11]: Using the AWS Glue Data Catalog with Amazon EMR Serverless - Amazon EMR
NEW QUESTION # 202
A company is planning to upgrade its Amazon Elastic Block Store (Amazon EBS) General Purpose SSD storage from gp2 to gp3. The company wants to prevent any interruptions in its Amazon EC2 instances that will cause data loss during the migration to the upgraded storage.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: C
Explanation:
Changing the volume type of the existing gp2 volumes to gp3 is the easiest and fastest way to migrate to the new storage type without any downtime or data loss. You can use the AWS Management Console, the AWS CLI, or the Amazon EC2 API to modify the volume type, size, IOPS, and throughput of your gp2 volumes. The modification takes effect immediately, and you can monitor the progress of the modification using CloudWatch. The other options are either more complex or require additional steps, such as creating snapshots, transferring data, or attaching new volumes, which can increase the operational overhead and the risk of errors. Reference:
Migrating Amazon EBS volumes from gp2 to gp3 and save up to 20% on costs (Section: How to migrate from gp2 to gp3) Switching from gp2 Volumes to gp3 Volumes to Lower AWS EBS Costs (Section: How to Switch from GP2 Volumes to GP3 Volumes) Modifying the volume type, IOPS, or size of an EBS volume - Amazon Elastic Compute Cloud (Section: Modifying the volume type)
NEW QUESTION # 203
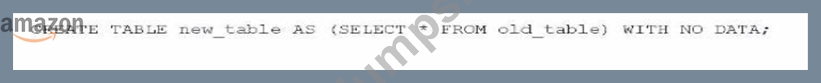
A data engineer needs to create a new empty table in Amazon Athena that has the same schema as an existing table named old-table.
Which SQL statement should the data engineer use to meet this requirement?



Answer: D
Explanation:
Problem Analysis:
The goal is to create a new empty table in Athena with the same schema as an existing table (old_table).
The solution must avoid copying any data.
Key Considerations:
CREATE TABLE AS (CTAS) is commonly used in Athena for creating new tables based on an existing table.
Adding the WITH NO DATA clause ensures only the schema is copied, without transferring any data.
Solution Analysis:
Option A: Copies both schema and data. Does not meet the requirement for an empty table.
Option B: Inserts data into an existing table, which does not create a new table.
Option C: Creates an empty table but does not copy the schema.
Option D: Creates a new table with the same schema and ensures it is empty by using WITH NO DATA.
Final Recommendation:
Use D. CREATE TABLE new_table AS (SELECT * FROM old_table) WITH NO DATA to create an empty table with the same schema.
Athena CTAS Queries
CREATE TABLE Statement in Athena
NEW QUESTION # 204
A company created an extract, transform, and load (ETL) data pipeline in AWS Glue. A data engineer must crawl a table that is in Microsoft SQL Server. The data engineer needs to extract, transform, and load the output of the crawl to an Amazon S3 bucket. The data engineer also must orchestrate the data pipeline.
Which AWS service or feature will meet these requirements MOST cost-effectively?
Answer: C
Explanation:
AWS Glue workflows are a cost-effective way to orchestrate complex ETL jobs that involve multiple crawlers, jobs, and triggers. AWS Glue workflows allow you to visually monitor the progress and dependencies of your ETL tasks, and automatically handle errors and retries. AWS Glue workflows also integrate with other AWS services, such as Amazon S3, Amazon Redshift, and AWS Lambda, among others, enabling you to leverage these services for your data processing workflows. AWS Glue workflows are serverless, meaning you only pay for the resources you use, and you don't have to manage any infrastructure.
AWS Step Functions, AWS Glue Studio, and Amazon MWAA are also possible options for orchestrating ETL pipelines, but they have some drawbacks compared to AWS Glue workflows. AWS Step Functions is a serverless function orchestrator that can handle different types of data processing, such as real-time, batch, and stream processing. However, AWS Step Functions requires you to write code to define your state machines, which can be complex and error-prone. AWS Step Functions also charges you for every state transition, which can add up quickly for large-scale ETL pipelines.
AWS Glue Studio is a graphical interface that allows you to create and run AWS Glue ETL jobs without writing code. AWS Glue Studio simplifies the process of building, debugging, and monitoring your ETL jobs, and provides a range of pre-built transformations and connectors. However, AWS Glue Studio does not support workflows, meaning you cannot orchestrate multiple ETL jobs or crawlers with dependencies and triggers. AWS Glue Studio also does not support streaming data sources or targets, which limits its use cases for real-time data processing.
Amazon MWAA is a fully managed service that makes it easy to run open-source versions of Apache Airflow on AWS and build workflows to run your ETL jobs and data pipelines. Amazon MWAA provides a familiar and flexible environment for data engineers who are familiar with Apache Airflow, and integrates with a range of AWS services such as Amazon EMR, AWS Glue, and AWS Step Functions. However, Amazon MWAA is not serverless, meaning you have to provision and pay for the resources you need, regardless of your usage. Amazon MWAA also requires you to write code to define your DAGs, which can be challenging and time-consuming for complex ETL pipelines. References:
* AWS Glue Workflows
* AWS Step Functions
* AWS Glue Studio
* Amazon MWAA
* AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide
NEW QUESTION # 205
A company uses Amazon S3 to store semi-structured data in a transactional data lake. Some of the data files are small, but other data files are tens of terabytes.
A data engineer must perform a change data capture (CDC) operation to identify changed data from the data source. The data source sends a full snapshot as a JSON file every day and ingests the changed data into the data lake.
Which solution will capture the changed data MOST cost-effectively?
Answer: D
Explanation:
An open source data lake format, such as Apache Parquet, Apache ORC, or Delta Lake, is a cost-effective way to perform a change data capture (CDC) operation on semi-structured data stored in Amazon S3. An open source data lake format allows you to query data directly from S3 using standard SQL, without the need to move or copy data to another service. An open source data lake format also supports schema evolution, meaning it can handle changes in the data structure over time. An open source data lake format also supports upserts, meaning it can insert new data and update existing data in the same operation, using a merge command. This way, you can efficiently capture the changes from the data source and apply them to the S3 data lake, without duplicating or losing any data.
The other options are not as cost-effective as using an open source data lake format, as they involve additional steps or costs. Option A requires you to create and maintain an AWS Lambda function, which can be complex and error-prone. AWS Lambda also has some limits on the execution time, memory, and concurrency, which can affect the performance and reliability of the CDC operation. Option B and D require you to ingest the data into a relational database service, such as Amazon RDS or Amazon Aurora, which can be expensive and unnecessary for semi-structured data. AWS Database Migration Service (AWS DMS) can write the changed data to the data lake, but it also charges you for the data replication and transfer. Additionally, AWS DMS does not support JSON as a source data type, so you would need to convert the data to a supported format before using AWS DMS. Reference:
What is a data lake?
Choosing a data format for your data lake
Using the MERGE INTO command in Delta Lake
[AWS Lambda quotas]
[AWS Database Migration Service quotas]
NEW QUESTION # 206
......
When it comes to a swift Data-Engineer-Associate exam preparation with the best reward, nothing compares PDFDumps Data-Engineer-Associate dumps. They are made with an aim to provide you the most relevant information and knowledge within a few days and ensure you a brilliant success. Each Data-Engineer-Associate Exam Dumps is unique and vitally important for your preparation. The work you are supposed to do have already been done by our highly trained professionals.
Data-Engineer-Associate Exam Actual Questions: https://www.pdfdumps.com/Data-Engineer-Associate-valid-exam.html
BONUS!!! Download part of PDFDumps Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=14EoJYkoqAFEBCIBC4PU6U4sM5TgqsJrV