BTW, DOWNLOAD part of PassExamDumps DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=1t-2thty9TfQaBPchtFoN2h1mEB4lyjC_
These DP-100 exam question formats contain real, valid, and updated Microsoft DP-100 exam questions that will assist you in Microsoft Designing and Implementing a Data Science Solution on Azure exam preparation and enable you to pass the challenging Microsoft DP-100 Exam with good scores. The Microsoft DP-100 questions are prepared by highly experienced professionals and, thus, are kept to the point and concise.
Microsoft DP-100 Certification Exam is a highly recognized certification in the field of data science. It is designed to provide candidates with the skills and knowledge they need to design and implement data science solutions using Azure technologies. By achieving this certification, candidates can demonstrate their expertise in the field, and enhance their career prospects by opening up new opportunities in the industry.
>> Accurate DP-100 Prep Material <<
Only if you download our software and practice no more than 30 hours will you attend your test confidently. Because our Microsoft DP-100 exam torrent can simulate limited-timed examination and online error correcting, it just takes less time and energy for you to prepare the DP-100 Exam than other study materials.
To prepare for the DP-100 exam, candidates must have a solid understanding of data science and machine learning concepts, as well as experience working with Azure data services. They should be familiar with Azure Machine Learning Studio, Azure Databricks, Azure HDInsight, and other relevant Azure technologies. DP-100 exam consists of multiple-choice questions and performance-based tasks that require candidates to demonstrate their ability to design and implement data science solutions in real-world scenarios. The DP-100 Certification is a valuable credential for professionals seeking to advance their careers in data science and machine learning on the Azure platform.
NEW QUESTION # 268
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are a data scientist using Azure Machine Learning Studio.
You need to normalize values to produce an output column into bins to predict a target column.
Solution: Apply a Quantiles binning mode with a PQuantile normalization.
Does the solution meet the goal?
Answer: A
Explanation:
Use the Entropy MDL binning mode which has a target column.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/group-data-into-bins
NEW QUESTION # 269
The finance team asks you to train a model using data in an Azure Storage blob container named finance-data.
You need to register the container as a datastore in an Azure Machine Learning workspace and ensure that an error will be raised if the container does not exist.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.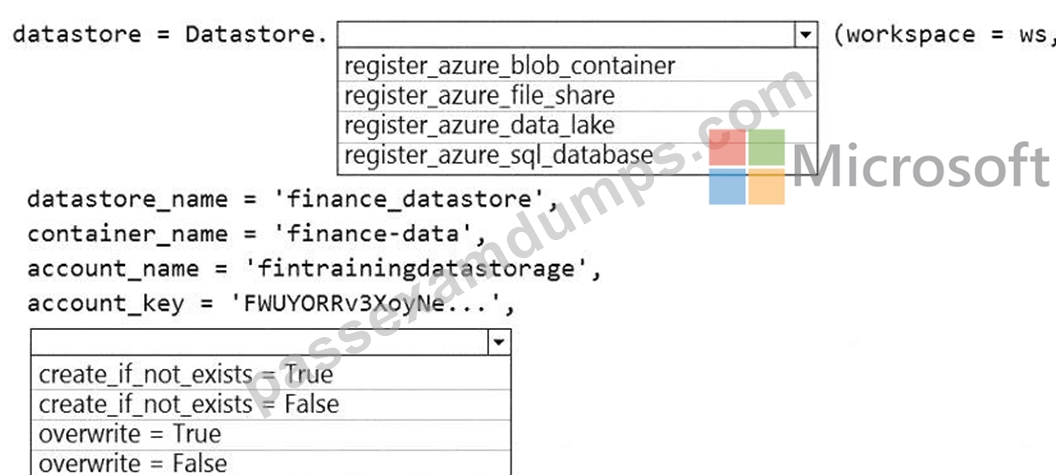
Answer:
Explanation: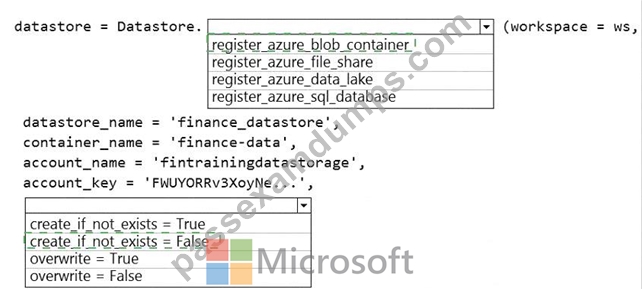
Explanation: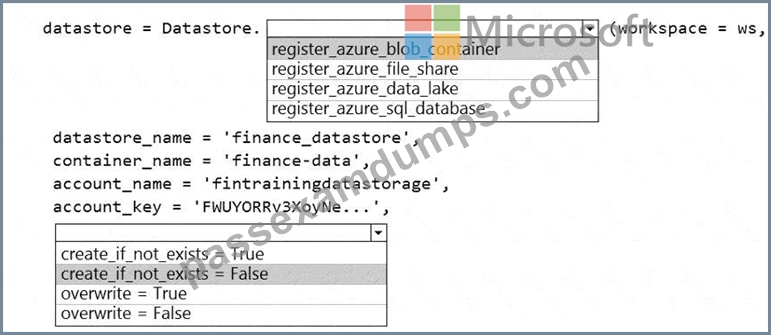
Box 1: register_azure_blob_container
Register an Azure Blob Container to the datastore.
Box 2: create_if_not_exists = False
Create the file share if it does not exists, defaults to False.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-core/azureml.core.datastore.datastore
NEW QUESTION # 270
You are building an intelligent solution using machine learning models.
The environment must support the following requirements:
* Data scientists must build notebooks in a cloud environment
* Data scientists must use automatic feature engineering and model building in machine learning pipelines.
* Notebooks must be deployed to retrain using Spark instances with dynamic worker allocation.
* Notebooks must be exportable to be version controlled locally.
You need to create the environment.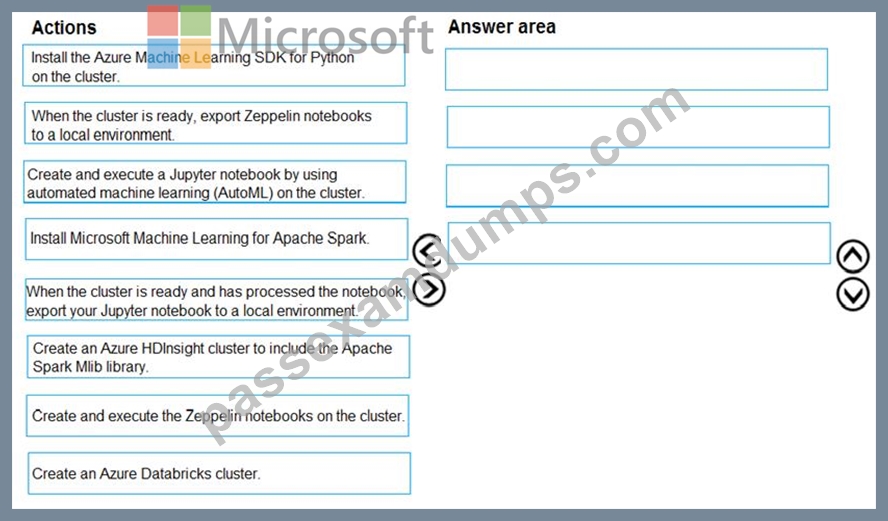
Answer:
Explanation: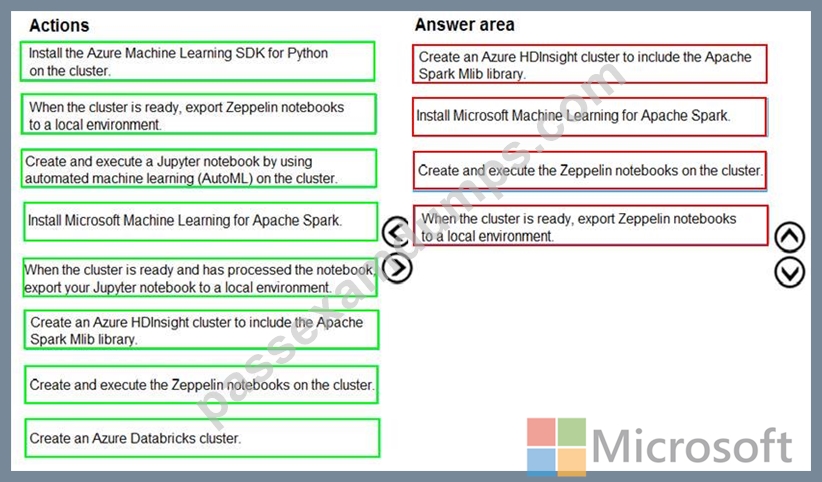
Explanation:
Step 1: Create an Azure HDInsight cluster to include the Apache Spark Mlib library Step 2: Install Microsot Machine Learning for Apache Spark You install AzureML on your Azure HDInsight cluster.
Microsoft Machine Learning for Apache Spark (MMLSpark) provides a number of deep learning and data science tools for Apache Spark, including seamless integration of Spark Machine Learning pipelines with Microsoft Cognitive Toolkit (CNTK) and OpenCV, enabling you to quickly create powerful, highly-scalable predictive and analytical models for large image and text datasets.
Step 3: Create and execute the Zeppelin notebooks on the cluster
Step 4: When the cluster is ready, export Zeppelin notebooks to a local environment.
Notebooks must be exportable to be version controlled locally.
References:
https://docs.microsoft.com/en-us/azure/hdinsight/spark/apache-spark-zeppelin-notebook
https://azuremlbuild.blob.core.windows.net/pysparkapi/intro.html
NEW QUESTION # 271
You have an Azure Machine Learning workspace named Workspace 1 Workspace! has a registered Mlflow model named model 1 with PyFunc flavor You plan to deploy model1 to an online endpoint named endpoint1 without egress connectivity by using Azure Machine learning Python SDK vl You have the following code: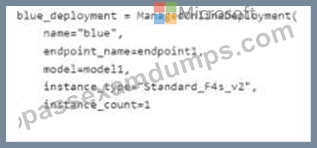
You need to add a parameter to the ManagedOnllneDeployment object to ensure the model deploys successfully Solution: Add the scoring_script parameter.
Does the solution meet the goal?
Answer: A
NEW QUESTION # 272
You are performing sentiment analysis using a CSV file that includes 12,000 customer reviews written in a short sentence format. You add the CSV file to Azure Machine Learning Studio and configure it as the starting point dataset of an experiment. You add the Extract N-Gram Features from Text module to the experiment to extract key phrases from the customer review column in the dataset.
You must create a new n-gram dictionary from the customer review text and set the maximum n-gram size to trigrams.
What should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.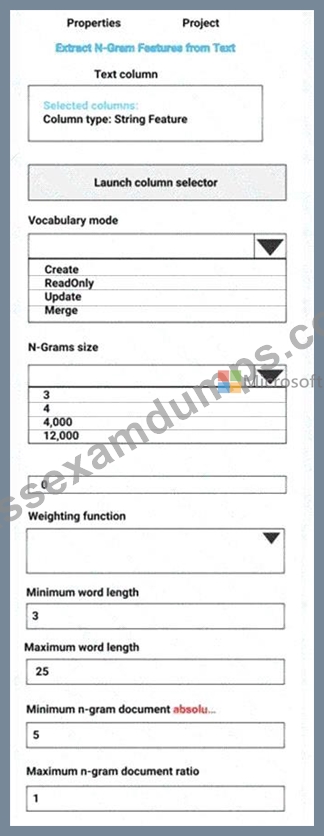
Answer:
Explanation: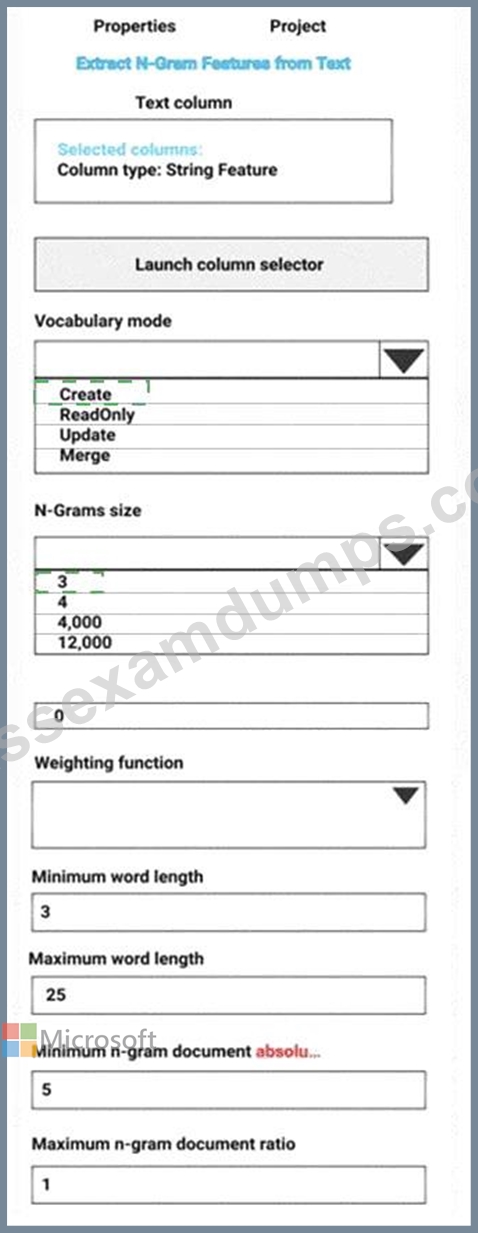
Explanation: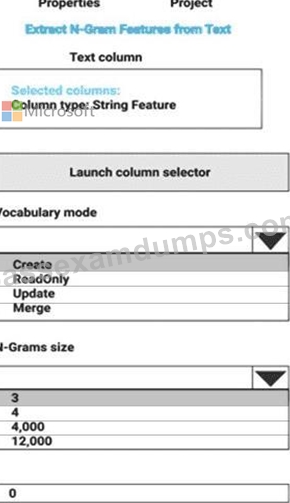
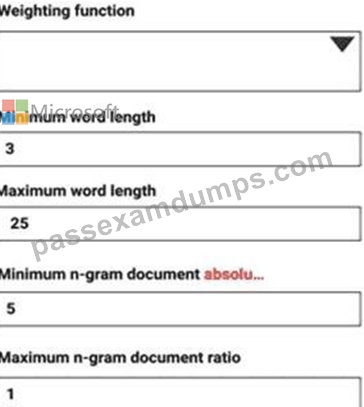
Vocabulary mode: Create
For Vocabulary mode, select Create to indicate that you are creating a new list of n-gram features.
N-Grams size: 3
For N-Grams size, type a number that indicates the maximum size of the n-grams to extract and store. For example, if you type 3, unigrams, bigrams, and trigrams will be created.
Weighting function: Leave blank
The option, Weighting function, is required only if you merge or update vocabularies. It specifies how terms in the two vocabularies and their scores should be weighted against each other.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/extract-n-gram-features- from-text
NEW QUESTION # 273
......
DP-100 Test Dumps Pdf: https://www.passexamdumps.com/DP-100-valid-exam-dumps.html
DOWNLOAD the newest PassExamDumps DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1t-2thty9TfQaBPchtFoN2h1mEB4lyjC_