그리고 ITDumpsKR NCA-GENM 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1bWq3Pl81vRnuMVGZYN0raJTf3ZTiBN2g
IT업계에 종사하고 계신 분은NVIDIA NCA-GENM 시험을 패스하여 자격증을 취득하려고 검색하다 저희 블로그를 보게 되시고 저희 사이트까지 방문하게 될것입니다. 방문하는 순간 NVIDIA NCA-GENM시험에 대한 두려움이 사라질것입니다. 완벽한 구매후 서비스까지 겸비하고 있어 자격증을 취득하는데서의 믿음직스러운 동반자로 되어드릴게요.
| Section | Weight | Objectives |
|---|---|---|
| Experimentation | 25% | - Metrics and validation strategies for generative models - Model training, fine-tuning, and evaluation - Experiment design and methodology |
| Multimodal Data | 15% | - Characteristics of text, image, and audio data - Multimodal model architectures and integration - Data preprocessing, fusion, and representation |
| Performance Optimization | 10% | - Model efficiency and inference optimization - Scalability and deployment considerations - Hardware acceleration with NVIDIA platforms |
| Data Analysis and Visualization | 10% | - Analyzing multimodal datasets and outputs - Interpretation of generative AI outputs - Visualization techniques for model behavior and results |
| Trustworthy AI | 5% | - Robustness and error mitigation - Reliability, fairness, and safety in generative systems - Ethical considerations and responsible use |
| Core Machine Learning and AI Knowledge | 20% | - Neural network architectures relevant to multimodal systems - Fundamental concepts of machine learning and deep learning - Generative AI principles and techniques |
| Software Development and Engineering | 15% | - Best practices for building and maintaining systems - Libraries, frameworks, and tools for multimodal AI - Development workflows for generative AI applications |
ITDumpsKR의 NVIDIA인증 NCA-GENM덤프는 거의 모든 실제시험문제 범위를 커버하고 있습니다.NVIDIA인증 NCA-GENM시험덤프를 구매하여 덤프문제로 시험에서 불합격성적표를 받을시ITDumpsKR에서는 덤프비용 전액 환불을 약속드립니다.
질문 # 27
Consider the following Python code snippet used for processing image and text data for a multimodal model: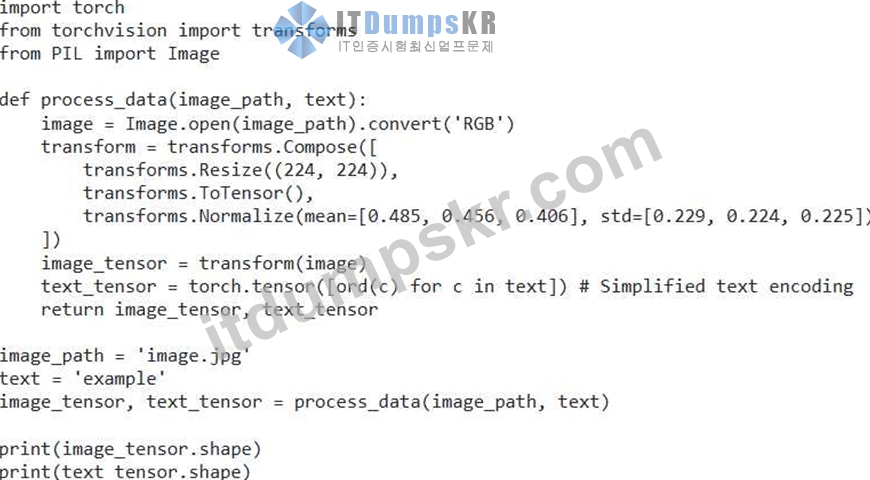
What is the primary limitation of the text encoding method used in this code, and how could it be improved for use in a real-world multimodal model?
정답:C
설명:
The code simply converts each character to its ASCII value, which loses semantic meaning and doesn't handle variable-length sequences or word relationships. Real-world models use tokenizers and embeddings to capture the nuances of language. BERT and SentencePiece are common tools for this. Option B accurately describes this limitation and suggests a practical solution.
질문 # 28
In a Generative Adversarial Network (GAN), what is the role of the discriminator?
정답:D
설명:
A GAN's discriminator is a binary classifier trained to distinguish real samples (drawn from the actual training data) from fake samples (produced by the generator), outputting a probability that a given input is real rather than generated. This is the discriminator's entire function - it never generates data itself. The generator, by contrast, takes random noise as input and learns to produce increasingly realistic synthetic samples, with the explicit goal of fooling the discriminator into classifying its outputs as real.
Training proceeds as a minimax adversarial game: the discriminator's weights are updated to improve its ability to correctly classify real vs. fake, while the generator's weights are updated (using gradients that flow back through the discriminator) to make its outputs harder for the discriminator to detect as fake. As training progresses, both networks improve in tandem, ideally converging to a point where the generator produces samples statistically indistinguishable from real data and the discriminator can no longer reliably tell them apart (outputting close to 50% confidence either way).
Option A describes the generator's role, not the discriminator's - a common point of confusion this question is testing directly. Option C is too vague to describe either network's specific function precisely. Option D conflates the discriminator with the general backpropagation/optimization process; while the discriminator's output does supply the gradient signal used to update the generator, "calculating the loss function and updating the generator" overstates and mischaracterizes the discriminator's role as a classifier.
Reference: Core Machine Learning and AI Knowledge domain - GAN architecture, discriminator vs.
generator roles.
질문 # 29
You are building a multimodal generative A1 system that creates 3D models from text descriptions. The system produces accurate shapes but struggles to generate realistic textures and surface details. What approach would BEST address this limitation?
정답:B
설명:
Training a separate texture generation network allows for specialization in generating realistic surface details. This approach decouples the shape generation from the texture generation, allowing each component to be optimized independently. The other options are less targeted at improving texture realism. Increasing text encoder parameters (A) improves text understanding, not texture quality. Reducing resolution (C) degrades the final output. Increasing batch size (D) affects training speed, not texture quality. Adding layers to the shape decoder (E) may improve shape accuracy, but not texture realism.
질문 # 30
You are tasked with generating realistic images of human faces using a GAN. However, you notice that the generated images often contain artifacts, such as distorted facial features or unrealistic textures. Which of the following techniques would be most effective in improving the realism and quality of the generated faces?
정답:D
설명:
StyleGAN architecture, with its AdalN and mapping network, is specifically designed to control and manipulate the style attributes of generated images, leading to more realistic and high-quality outputs, particularly for complex structures like human faces. AdalN helps in normalizing feature statistics based on style codes, enabling fine-grained control over the visual appearance.
질문 # 31
Explainable A1 (XAI) is crucial when deploying multimodal models, especially in high-stakes scenarios. Which technique is MOST appropriate for understanding the relative importance of different modalities (e.g., image vs. text) in a multimodal classification task?
정답:E
설명:
Ablation studies provide a direct measure of the importance of each modality by observing how the model's performance changes when that modality is removed. This allows you to quantify the contribution of each modality to the overall prediction.
질문 # 32
......
ITDumpsKR에서는 소프트웨어버전과 PDF버전 두가지버전으로 덤프를 제공해드립니다.PDF버전은 구매사이트에서 무료샘플을 다움받아 체험가능합니다. 소프트웨어버전은실력테스트용으로 PDF버전공부후 보조용으로 사용가능합니다. NVIDIA 인증NCA-GENM덤프 무료샘플을 다운받아 체험해보세요.
NCA-GENM최신 인증시험자료: https://www.itdumpskr.com/NCA-GENM-exam.html
BONUS!!! ITDumpsKR NCA-GENM 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=1bWq3Pl81vRnuMVGZYN0raJTf3ZTiBN2g