当社MicrosoftのAI-103試験トレントはPDF、ソフトウェア、オンライン3モードで利用できます。これにより、学習教材を紙、携帯電話、またはコンピューターで切り替え、AI-103の対応するバージョンでいつでもどこでも学習できます。 模擬試験。 システムを購入する前に、AI-103模擬テストにより無料の試用サービスが提供されるため、Developing AI Apps and Agents on Azure顧客は購入前にシステムを完全に理解できます。 オンライン支払いが成功した後、5〜10分でカスタマーサービスからメールを受信し、すぐにAI-103トレーニング準備を学び始めます。
| Section | Objectives |
|---|---|
| Topic 1: Plan and Manage Azure AI Solutions | - Azure AI resource provisioning and configuration - Model selection and lifecycle management - Responsible AI principles and governance |
| Topic 2: Develop Generative AI Applications and Agents | - AI agents architecture
|
| Topic 3: Knowledge Mining and Information Retrieval | - Indexing and semantic search - RAG (Retrieval Augmented Generation) patterns - Azure AI Search configuration |
| Topic 4: Implement Computer Vision Solutions | - Image classification and object detection - OCR and document intelligence |
| Topic 5: Implement Natural Language Processing Solutions | - Translation and multilingual support - Text analytics and summarization - Language understanding and intent recognition |
多くの人々は高い難度のMicrosoft認証AI-103試験に合格するのは専門の知識が必要だと思います。それは確かにそうですが、その知識を身につけることは難しくないとといわれています。Microsoft業界ではさらに強くなるために強い専門知識が必要です。
質問 # 151
You have a Microsoft Foundry project that contains an agent.
The agent uses Azure AI Search as the retriever.
You plan to ingest PDF into an Azure AI Search index to ensure that the agent can ground responses in texts in both documents and embedded images.
Users require citations that link to the source files.
You need to ensure that during indexing, the images are extracted into a structure that can be used as input for the built-in optical character recognition (OCR) skill.
Which indexing approach should you use?
正解:B
解説:
The best configuration step an indexer to extract image data into a normalized_images collection.
Cracking Foundation: In Azure AI Search, document cracking automatically separates textual data from visual content. To make embedded images available to image-processing skills like OCR, the indexer must be explicitly configured with an imageAction configuration property (such as generateNormalizedImages or generateNormalizedImagePerPage).
Input Structure for OCR: This indexer step extracts embedded images from the PDF and restructures them into an internal normalized_images array (accessed via the path
/document/normalized_images/*). The built-in OCR skill strictly requires this normalized image collection format as its input payload.
Incorrect:
[Not C]
Content Field Limitations: The /document/content field generated during document cracking holds only the raw text extracted from the file. It does not contain the binary data or structural properties of embedded images.
Targeting Errors: Pointing an OCR skill directly at the raw text content field would fail to analyze the actual images, leaving the agent unable to ground answers in visual elements like diagrams or embedded infographics.
Reference:
https://docs.azure.cn/en-us/search/tutorial-skillset
質問 # 152
You are building a speech processing solution in Microsoft Foundry for a customer support platform.
The platform will transcribe live phone calls, so that supervisors at your company can view call transcripts and detect issues while the calls are in progress. The call audio will arrive as a continuous stream from the telephony system.
You need to ensure that the call transcripts appear within only a few seconds of the audio stream.
What should you do?
正解:A
質問 # 153
You have a Microsoft Foundry project that contains an agent.
You need to enable long-term memory to ensure that the agent can recall user preferences across separate conversations. Stored memories must be isolated per authenticated user without the client application manually generating user IDs.
How should you complete the Python code? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all.
NOTE: Each correct selection is worth one point.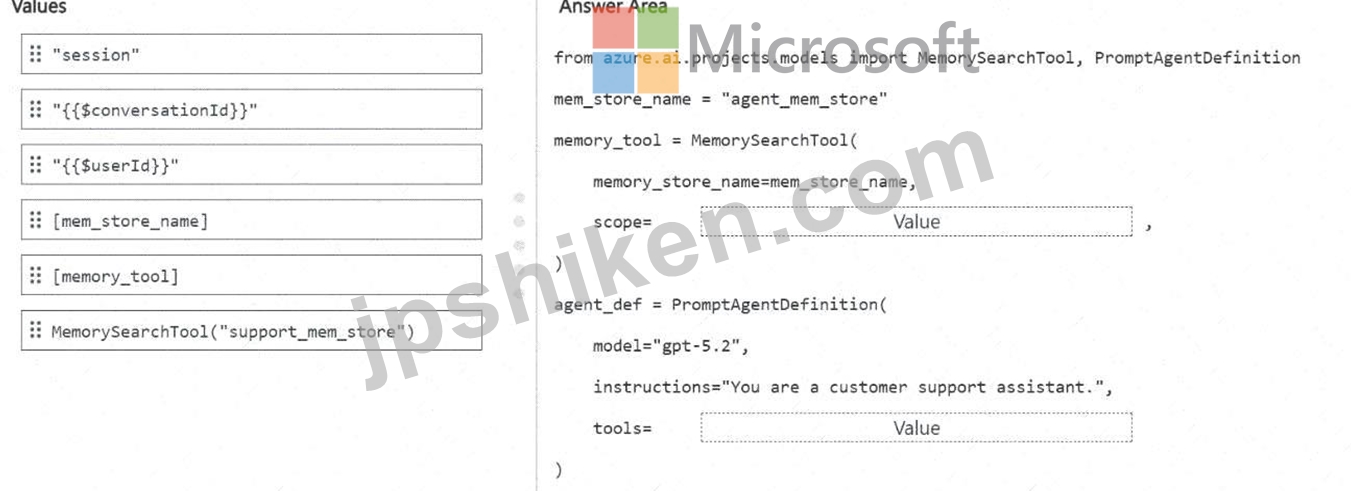
正解:
解説: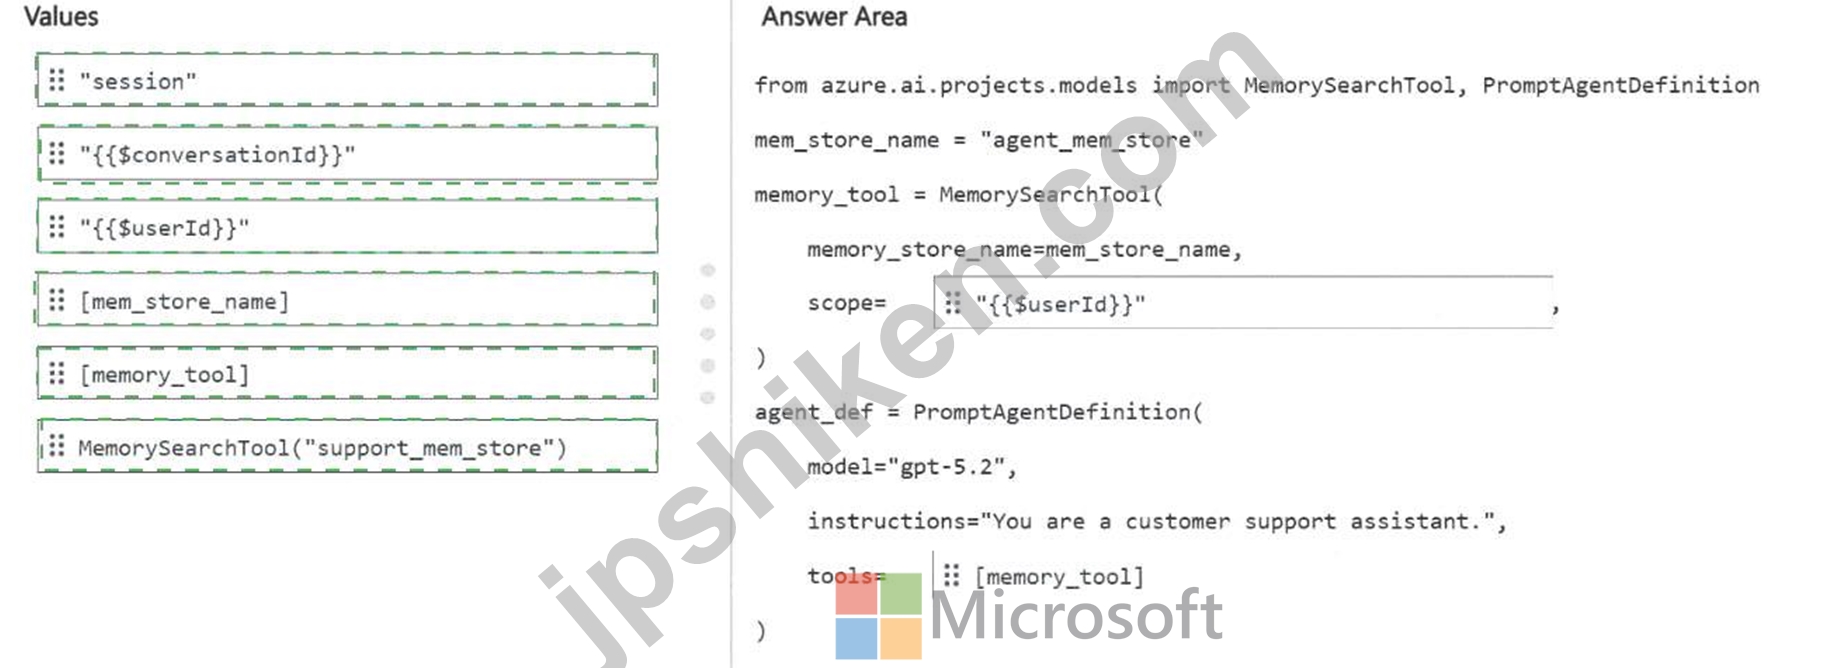
Explanation:
scope = " {{userId}} "
tools = [memory_tool]
The correct scope value is {{userId}} because the requirement is per-authenticated-user memory isolation without the client application manually generating user identifiers. In Microsoft Foundry Agent Service memory, the scope parameter partitions memory items inside the memory store. The official guidance states that when the memory search tool is attached to an agent, setting scope to the user identity template enables per-user memory isolation; the service resolves the end-user identity from the request header when provided, or falls back to the Microsoft Entra tenant ID and object ID of the caller. This matches the requirement to isolate stored preferences by authenticated user automatically.
The tools property must be [memory_tool] because the MemorySearchTool instance is created earlier and must be attached to the PromptAgentDefinition. Foundry guidance shows the memory search tool being passed in the agent definition as tools=[tool] , allowing the agent to read from and write to the configured memory store during conversations.
" session " and {{conversationId}} would limit continuity to a session or conversation instead of enabling long-term recall across separate conversations. [mem_store_name] is a list containing the store name, not a tool definition. Reference topics: Foundry Agent Service memory, memory stores, memory search tools, scope, and per-user isolation.
質問 # 154
Hotspot Question
You have a Microsoft Foundry project that contains an agent.
The agent uses a stored access key to retrieve secrets from an Azure key vault, which violates a keyless-credentials requirement.
You need to ensure that the agent can retrieve the secrets. The solution must follow the principle of least privilege.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.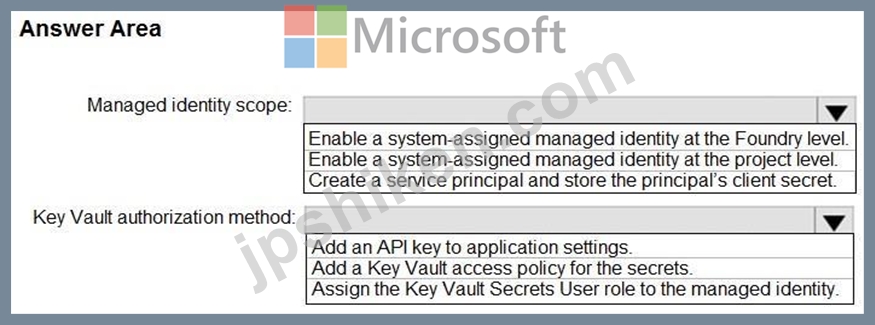
正解:
解説: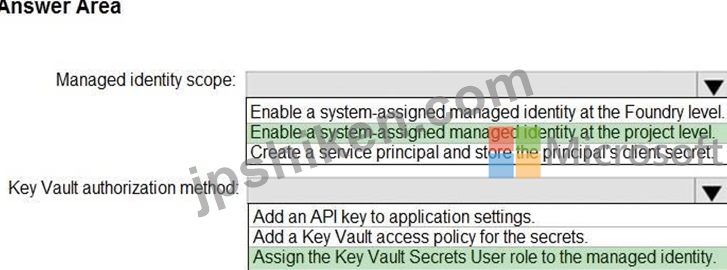
Explanation:
Box 1: Enable a system-assigned managed identity at the project level
The correct configuration is to enable a system-assigned managed identity at the project level.
This is the correct approach. Azure AI Foundry (formerly Azure Machine Learning) allows you to enable a system-assigned managed identity directly at the project level. This identity acts as a keyless credential native to Azure. To follow the principle of least privilege, you then assign this project-level identity a specific role (such as Key Vault Secrets User) restricted only to the required Azure Key Vault. This ensures that the agent can retrieve secrets securely without exposing credentials to other projects or resources Box 2: Assign the Key Vault Secrets User role to the managed identity To comply with the keyless-credentials requirement and follow the principle of least privilege, you should configure the Key Vault authorization method to assign the Key Vault Secrets User role to the managed identity using Azure Role-Based Access Control (Azure RBAC).
Reference:
https://learn.microsoft.com/en-us/azure/foundry/agents/how-to/ai-gateway
https://learn.microsoft.com/en-us/azure/app-service/app-service-key-vault-references
質問 # 155
You are building a voice agent for a pharmacy. It must accept spoken questions, reply with synthesised speech, and accurately recognise specialised medicine names that a general speech model often mishears. Which capability should you configure?
正解:B
解説:
A custom speech model improves recognition of specialised vocabulary, such as medicine names, by adapting speech-to-text (STT) to your domain, and AI-103 covers integrating speech, including custom speech models, as an agent modality. This directly addresses the accuracy problem in the scenario.
質問 # 156
......
AI-103試験トレントの3つのバージョンを提供しており、PDFバージョン、PCバージョン、APPオンラインバージョンが含まれています。各バージョンの機能と使用方法は異なり、実際の状況に適した最も便利なバージョンを選択できます。たとえば、PDFバージョンは、AI-103テストトレントをダウンロードして印刷するのに便利で、学習の閲覧に適しています。 PDFバージョンを使用している場合は、ペーパーで急流AI-103ガイドを印刷できます。 AI-103試験問題のPCバージョンは、Developing AI Apps and Agents on Azure実際の試験環境を刺激します。
AI-103日本語独学書籍: https://www.jpshiken.com/AI-103_shiken.html