Itexamdump 의 학습가이드에는Microsoft AI-103인증시험의 예상문제, 시험문제와 답입니다. 그리고 중요한 건 시험과 매우 유사한 시험문제와 답도 제공해드립니다. Itexamdump 을 선택하면 Itexamdump 는 여러분을 빠른시일내에 시험관련지식을 터득하게 할 것이고Microsoft AI-103인증시험도 고득점으로 패스하게 해드릴 것입니다.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement information extraction and knowledge mining | 10–15% | - Build knowledge bases and search solutions
|
| Topic 2: Plan and manage Azure AI solutions | 25–30% | - Manage AI solution development lifecycle
|
| Topic 3: Implement computer vision solutions | 10–15% | - Build multimodal solutions
|
| Topic 4: Implement text and speech analysis solutions | 10–15% | - Implement speech capabilities
|
| Topic 5: Implement generative AI and agentic solutions | 30–35% | - Build generative AI applications
|
Itexamdump의 Microsoft AI-103덤프를 공부하면 100% Microsoft AI-103 시험패스를 보장해드립니다. 만약 Microsoft AI-103 덤프자료를 구매하여 공부한후 시험에 탈락할시 불합격성적표와 주문번호를 메일로 보내오시면 덤프비용을 바로 환불해드립니다. 저희 Itexamdump Microsoft AI-103덤프로 자격증부자되세요.
질문 # 18
Drag and Drop Question
You have a Microsoft Foundry project that contains a deployed ticket-triage agent.
You discover that sometimes the agent responds without calling any tools, even when a tool is required.
You need to ensure that the agent calls a tool during execution.
How should you complete the Python code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.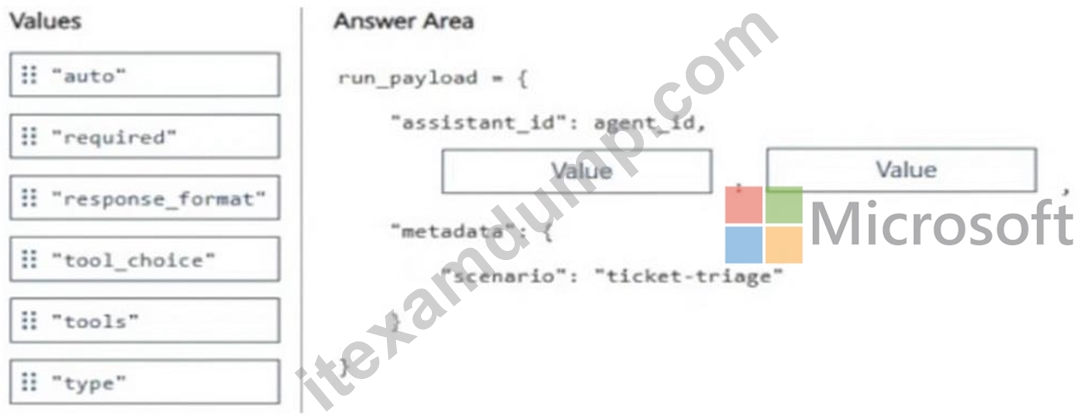
정답:
설명: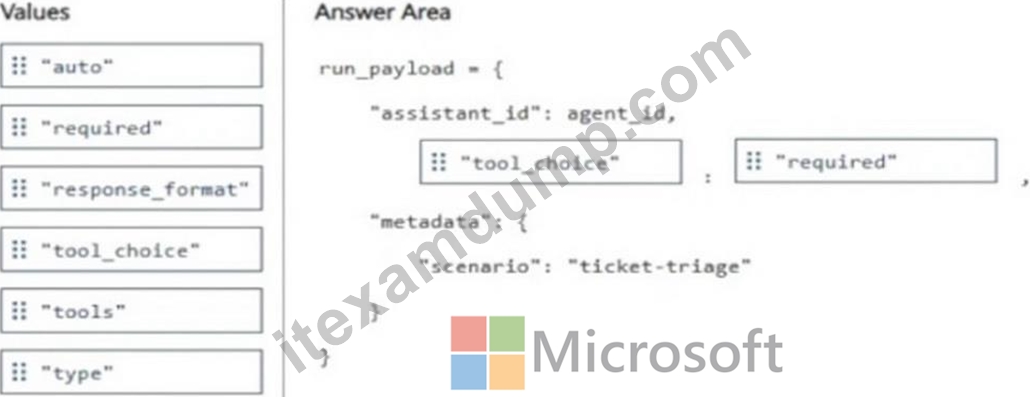
질문 # 19
You have a Microsoft Foundry project that contains an agent.
You need to process mixed-format documents that contain scanned text, tables, and multicolumn layouts. The extracted content must preserve the document structure and be converted into the Markdown format for downstream reasoning.
What should you configure first?
정답:A
설명:
The first step should be an Azure Content Understanding analyzer within Microsoft Foundry Tools.
This specific tool is designed to handle the complexities in this scenario--scanned text, complex tables, and multi-column layouts--by converting unstructured documents into a structured Markdown format. This preserves the document's original hierarchy and structural relationships, which is critical for accurate downstream reasoning by an agent.
Incorrect:
[Not A]
Azure Language is designed for text-based natural language processing (NLP) like sentiment analysis or PII redaction on raw text strings. It cannot parse scanned images, optical character recognition (OCR), tables, or complex multi-column visual layouts.
[Not C]
The first step in this specific Microsoft Foundry agent configuration should not be an Azure OpenAI Responses API call.While multimodal models can read images, they frequently hallucinate data, fail to capture complex multi-column reading orders, and degrade table structures when processing dense, mixed-format documents.
Reference:
https://learn.microsoft.com/en-us/azure/ai-services/content-understanding/document/elements
질문 # 20
You have an app that uses Azure Al Custom Vision and a custom trained classifier to identify products in images. You need to add new products to the classifier. The solution must meet the following requirements:
* Minimize how long it takes to add the products.
* Minimize development effort.
Which five actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.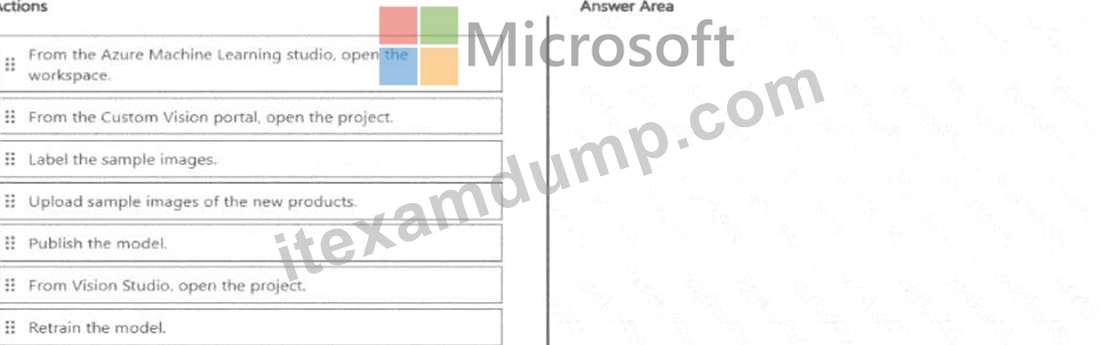
정답:
설명: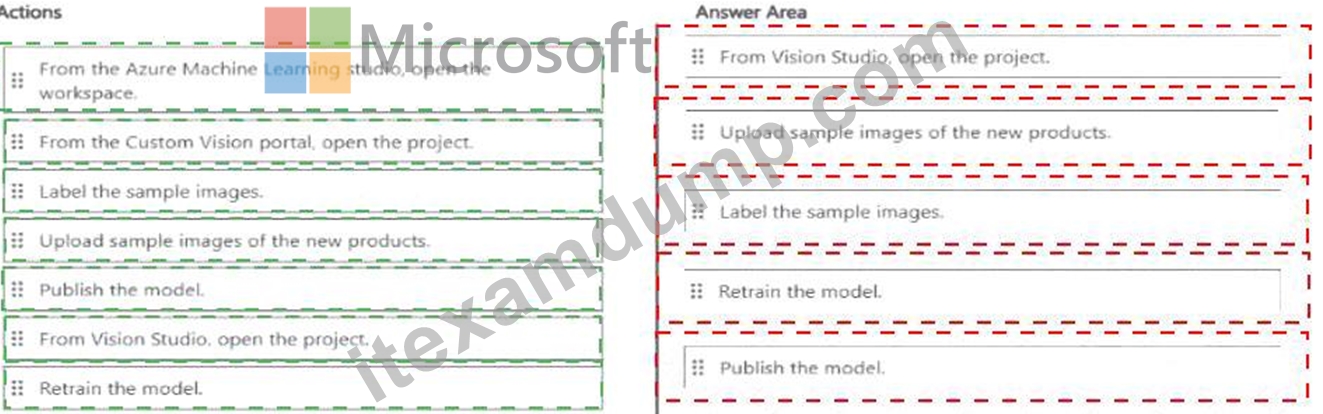
Explanation: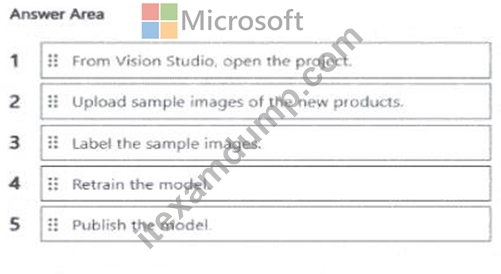
Because the existing classifier is an Azure AI Custom Vision project, the lowest-effort workflow is performed directly in the Custom Vision portal , not Azure Machine Learning studio or Vision Studio. Open the existing project so that the new product classes can be incorporated into its current training dataset.
Next, upload representative sample images of each new product. The images should include sufficient variation in viewing angle, lighting, background, size, and presentation to support reliable classification.
Label each image with the appropriate new product tag. Custom Vision uses these tags as the target classes during supervised training. Microsoft's portal workflow explicitly supports uploading and manually tagging images without requiring application code.
Retrain the classifier after the labeled images have been added. Training creates a new iteration based on all current training images and tags, including the newly introduced product categories.
Finally, publish the trained iteration to the prediction resource. Publishing makes that iteration available through the Custom Vision Prediction API used by the application.
Study Guide alignment: create, train, evaluate, retrain, publish, and consume custom image- classification models .
질문 # 21
You have a Microsoft Foundry project that contains a customer support agent. The agent calls an internal knowledge API tool before generating responses.
Users report the following issues:
* Some requests take more than 15 seconds to complete.
* Some responses are incorrect, even when the knowledge API returns the expected data.
You need to inspect individual agent runs to view the ordered sequence of large language model (LLM) calls, tool invocations, and timing information.
Which observability capability should you use?
정답:C
설명:
The correct capability is tracing because the requirement is to inspect the execution path of an individual agent run. Microsoft Foundry tracing captures detailed telemetry for agent behavior, including LLM calls, tool invocations, agent decision flows, inputs, outputs, tool results, token consumption, duration, and latency.
This is the appropriate observability mechanism when you need to determine which step introduced a delay, whether the agent called the internal knowledge API, what data the tool returned, and how the model used that data before producing the final response. Microsoft's Foundry observability guidance describes distributed tracing as the mechanism that provides visibility into LLM calls, tool invocations, agent decisions, and inter-service dependencies.
Token usage is useful for cost analysis and prompt optimization, but it does not show ordered run steps or tool-call sequencing. Safety metrics evaluate risk-related output behavior, not latency or tool execution.
General monitoring provides aggregate health, latency, success-rate, and dashboard views, but the question asks for per-run sequence inspection and timing breakdowns. Foundry agent tracing specifically supports debugging unexpected behavior and monitoring latency across requests. Reference topics: Microsoft Foundry observability, agent tracing, OpenTelemetry-based traces, tool invocations, LLM call inspection, and latency diagnostics.
질문 # 22
You process vendor onboarding PDFs containing tables and hyperlinks. The extracted content is indexed and supplied to an agent in Markdown.
You need Markdown with layout and semantic structure optimized for RAG.
정답:D
설명:
Comprehensive and Detailed 150 to 250 words of Explanation From Azure AI Apps and Agents Developer/Course Guide/topics:
Use prebuilt-documentSearch . Microsoft ' s current Content Understanding documentation explicitly classifies prebuilt-documentSearch as a Retrieval Augmented Generation analyzer .
RAG analyzers extract content with layout represented as Markdown and perform semantic analysis to enhance retrieval quality for downstream applications. prebuilt- documentSearch extracts document elements including paragraphs, tables, and figures and produces layout-preserving structured Markdown optimized for indexing and retrieval. Microsoft Learn prebuilt-layout is useful when the principal requirement is document-layout extraction, but the question explicitly requires both layout and semantic structure optimized for RAG . That wording maps directly to the RAG analyzer rather than the base layout analyzer.
prebuilt-read primarily addresses basic textual extraction, while prebuilt-documentFieldSchema serves field
/schema-oriented scenarios rather than producing RAG-optimized document representations.
Therefore, although the supplied file displays C (prebuilt-layout) , the verified current Microsoft Learn answer is B (prebuilt-documentSearch) . Microsoft ' s SDK documentation also describes prebuilt- documentSearch as preserving layout, detecting tables and figures, and generating structured Markdown specifically for RAG. Microsoft Learn
질문 # 23
......
Microsoft 인증AI-103인증시험공부자료는Itexamdump에서 제공해드리는Microsoft 인증AI-103덤프가 가장 좋은 선택입니다. Itexamdump에서는 시험문제가 업데이트되면 덤프도 업데이트 진행하도록 최선을 다하여 업데이트서비스를 제공해드려 고객님께서소유하신 덤프가 시장에서 가장 최신버전덤프로 되도록 보장하여 시험을 맞이할수 있게 도와드립니다.
AI-103인증덤프문제: https://www.itexamdump.com/AI-103.html