What's more, part of that VCE4Dumps DP-100 dumps now are free: https://drive.google.com/open?id=1iGjMBd9elIJx1O47IXkNmLgHFq6yADBz
In addition to the PDF questions VCE4Dumps offers desktop DP-100 practice exam software and web-based Designing and Implementing a Data Science Solution on Azure (DP-100) practice exam, to help you cope with Designing and Implementing a Data Science Solution on Azure (DP-100) exam anxiety. These Microsoft DP-100 Practice Exams simulate the actual Microsoft DP-100 exam conditions and provide you with an accurate assessment of your readiness for the DP-100 exam.
| Section | Objectives |
|---|---|
| Optimize and manage models | - Track experiments and manage model lifecycle - Improve model performance |
| Design and prepare a machine learning solution | - Plan and configure Azure Machine Learning workspace - Select appropriate Azure services for machine learning workloads - Manage compute and data assets |
| Explore and analyze data | - Perform exploratory data analysis - Ingest and prepare data for modeling |
| Deploy and consume models | - Deploy models to endpoints - Monitor deployed models and endpoints |
| Train machine learning models | - Tune hyperparameters and evaluate models - Train models using Azure Machine Learning |
>> Exam Microsoft DP-100 Passing Score <<
The Designing and Implementing a Data Science Solution on Azure (DP-100) practice tests have customizable time and Designing and Implementing a Data Science Solution on Azure (DP-100) exam questions feature so that the students can set the time and Designing and Implementing a Data Science Solution on Azure (DP-100) exam questions according to their needs. The Designing and Implementing a Data Science Solution on Azure (DP-100) practice test questions are getting updated on the daily basis and there are also up to 1 year of free updates. Earning the Designing and Implementing a Data Science Solution on Azure (DP-100) certification exam is the way to grow in the modern era with high-paying jobs.
NEW QUESTION # 10
A biomedical research company plans to enroll people in an experimental medical treatment trial.
You create and train a binary classification model to support selection and admission of patients to the trial.
The model includes the following features: Age, Gender, and Ethnicity.
The model returns different performance metrics for people from different ethnic groups.
You need to use Fairlearn to mitigate and minimize disparities for each category in the Ethnicity feature.
Which technique and constraint should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.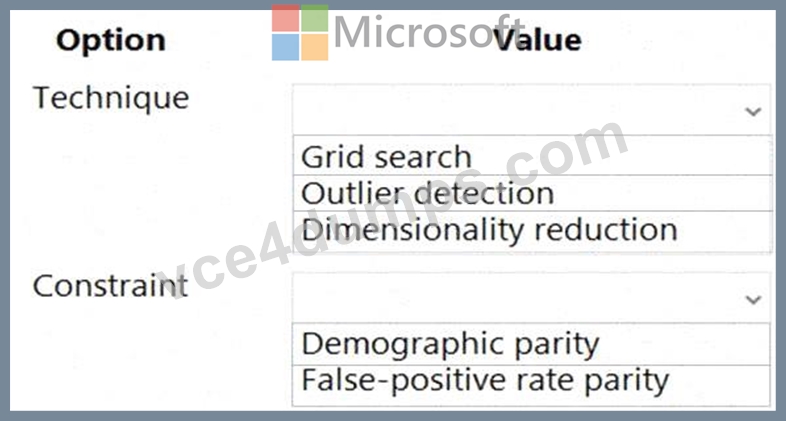
Answer:
Explanation: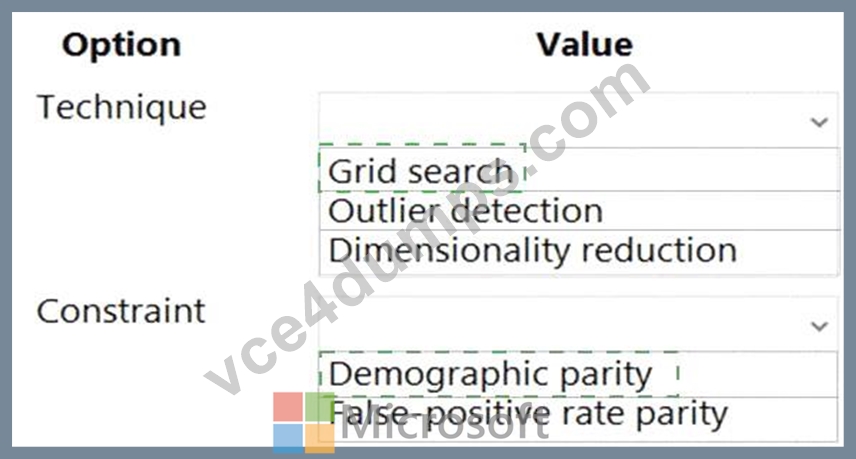
Explanation: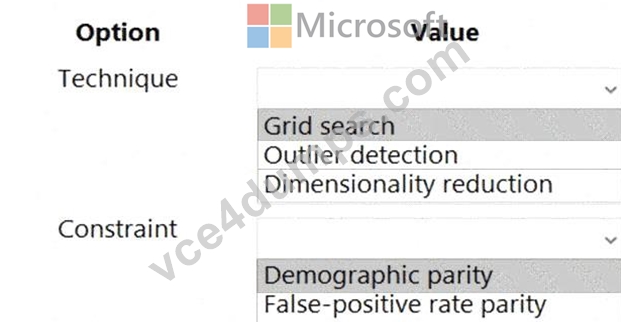
Box 1: Grid Search
Fairlearn open-source package provides postprocessing and reduction unfairness mitigation algorithms:
ExponentiatedGradient, GridSearch, and ThresholdOptimizer.
Note: The Fairlearn open-source package provides postprocessing and reduction unfairness mitigation algorithms types:
Reduction: These algorithms take a standard black-box machine learning estimator (e.g., a LightGBM model) and generate a set of retrained models using a sequence of re-weighted training datasets.
Post-processing: These algorithms take an existing classifier and the sensitive feature as input.
Box 2: Demographic parity
The Fairlearn open-source package supports the following types of parity constraints: Demographic parity, Equalized odds, Equal opportunity, and Bounded group loss.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/concept-fairness-ml
NEW QUESTION # 11
You have a dataset that includes home sales data for a city. The dataset includes the following columns.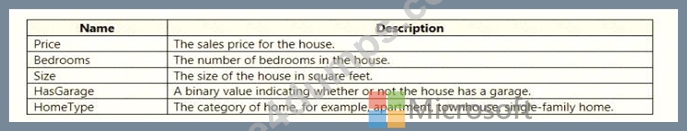
Each row in the dataset corresponds to an individual home sales transaction.
You need to use automated machine learning to generate the best model for predicting the sales price based on the features of the house.
Which values should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.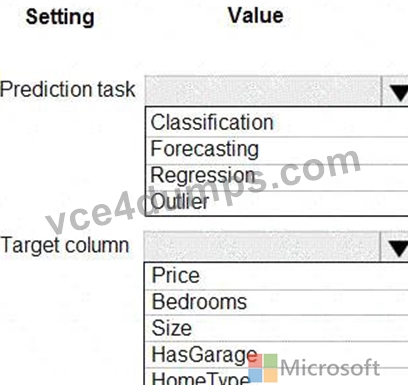
Answer:
Explanation: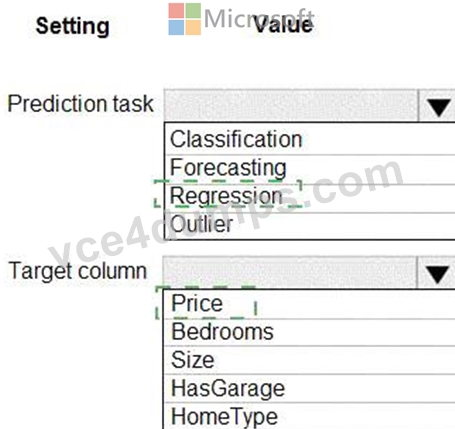
Explanation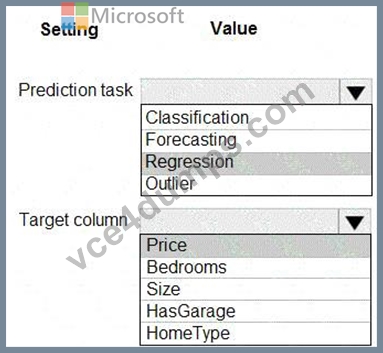
Box 1: Regression
Regression is a supervised machine learning technique used to predict numeric values.
Box 2: Price
Reference:
https://docs.microsoft.com/en-us/learn/modules/create-regression-model-azure-machine-learning-designer
NEW QUESTION # 12
You run an experiment that uses an AutoMLConfig class to define an automated machine learning task with a maximum of ten model training iterations. The task will attempt to find the best performing model based on a metric named accuracy.
You submit the experiment with the following code:
You need to create Python code that returns the best model that is generated by the automated machine learning task. Which code segment should you use?
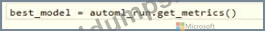

Answer: C
Explanation:
The get_output method returns the best run and the fitted model.
Reference:
https://notebooks.azure.com/azureml/projects/azureml-getting-started/html/how-to-use-azureml/automated- machine-learning/classification/auto-ml-classification.ipynb
NEW QUESTION # 13
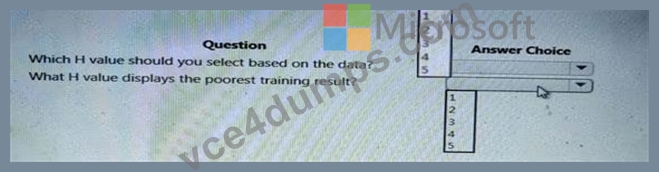
You are tuning a hyperparameter for an algorithm. The following table shows a data set with different hyperparameter, training error, and validation errors.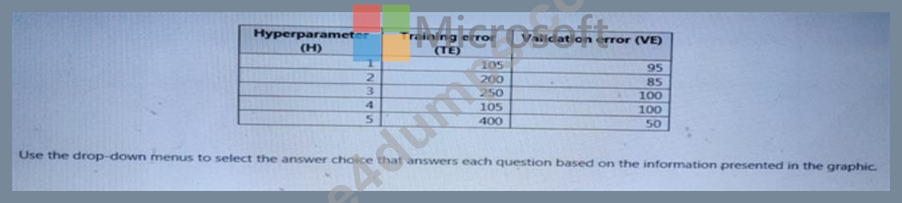
Answer:
Explanation: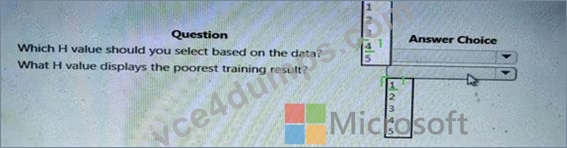
NEW QUESTION # 14
You create an experiment in Azure Machine Learning Studio. You add a training dataset that contains 10,000 rows. The first 9,000 rows represent class 0 (90 percent).
The remaining 1,000 rows represent class 1 (10 percent).
The training set is imbalances between two classes. You must increase the number of training examples for class 1 to 4,000 by using 5 data rows. You add the Synthetic Minority Oversampling Technique (SMOTE) module to the experiment.
You need to configure the module.
Which values should you use? To answer, select the appropriate options in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.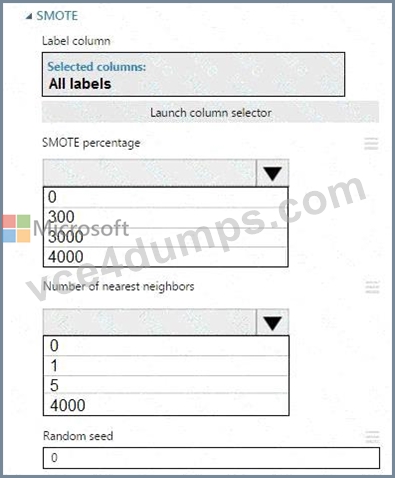
Answer:
Explanation: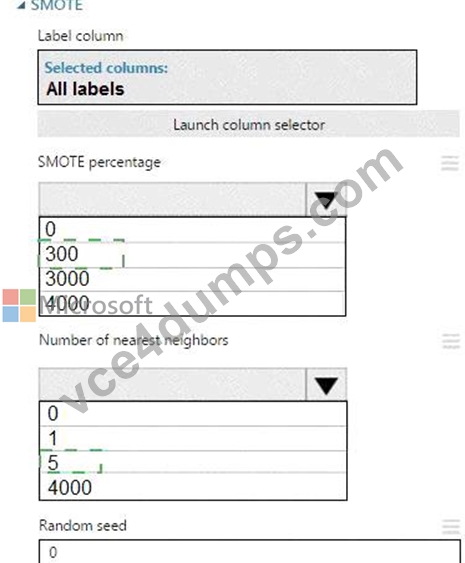
Explanation: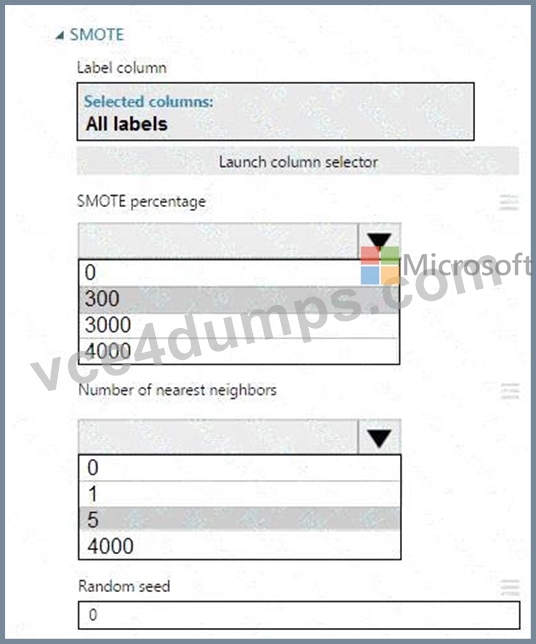
Box 1: 300
You type 300 (%), the module triples the percentage of minority cases (3000) compared to the original dataset (1000).
Box 2: 5
We should use 5 data rows.
Use the Number of nearest neighbors option to determine the size of the feature space that the SMOTE algorithm uses when in building new cases. A nearest neighbor is a row of data (a case) that is very similar to some target case. The distance between any two cases is measured by combining the weighted vectors of all features.
By increasing the number of nearest neighbors, you get features from more cases.
By keeping the number of nearest neighbors low, you use features that are more like those in the original sample.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/smote
NEW QUESTION # 15
......
For candidates who buy DP-100 test materials online, they may care more about the privacy protection. We can ensure you that your personal information such as your name and email address will be protected well if you choose us. Once the order finishes, your personal information will be concealed. Furthermore, DP-100 exam braindumps are high-quality, and we can help you pass the exam just one time. We promise that if you fail to pass the exam, we will give you full refund. If you have any questions for DP-100 Exam Test materials, you can contact with us online or by email, we will give you reply as quickly as we can.
DP-100 Certificate Exam: https://www.vce4dumps.com/DP-100-valid-torrent.html
BONUS!!! Download part of VCE4Dumps DP-100 dumps for free: https://drive.google.com/open?id=1iGjMBd9elIJx1O47IXkNmLgHFq6yADBz