BTW, DOWNLOAD part of DumpsTorrent SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1Z_9HX4yQBbbQQytnN6TYOucbQp1n5QV1
The web-based SPS-C01 practice test can be taken via any operating system without the need to install additional software. Also, this SPS-C01 web-based practice exam is compatible with all browsers. Both Snowflake SPS-C01 Practice Tests of DumpsTorrent keep result of your attempts and assist you in fixing errors. Moreover, you can alter settings of these SPS-C01 practice exams to suit your learning requirements.
| Section | Objectives |
|---|---|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Testing, Debugging, and Deployment | - Production readiness
|
| Data Engineering with Snowpark | - Pipeline development
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
>> Valid SPS-C01 Test Topics <<
DumpsTorrent has been designing and offering real Snowflake Snowflake Certified SnowPro Specialty - Snowpark exam dumps for many years. We regularly update our valid Snowflake SPS-C01 certification test preparation material to keep them in line with the current Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam content and industry standards. Professionals from different countries give us their valuable feedback to refine SPS-C01 actual dumps even more.
NEW QUESTION # 138
You have a Snowpark DataFrame containing sales data with columns 'sale_date', and 'sale_amount'. You need to calculate the cumulative sales amount for each product over time, ordered by 'sale_date'. Which of the following Snowpark code snippets correctly implements this using window functions?





Answer: E
Explanation:
Option A is correct. It correctly uses to group by 'product_id' and 'order_by' to sort by 'sale_date' within each product group. It then calculates the cumulative sum using Options B, C, D and E contain typos or incorrect function usage or order of arguments. 'cumulative_surn' is not a standard function provided.
NEW QUESTION # 139
You have a DataFrame 'df in Snowpark representing customer data'. One of the columns, 'customer_details', contains JSON objects with varying structures. Some objects contain 'address' and 'phone' fields, while others only contain 'email'. You need to write a Snowpark query to extract the 'city' from the 'address' field if it exists; otherwise, return NULL. What is the most efficient way to achieve this using the function?





Answer: E
Explanation:
Option B is the most efficient way to extract the 'city' using and 'coalesce'. gracefully handles the case where the 'address' or 'city' field is missing, returning NULL without raising an error. 'coalesce' then replaces the NULL value with None. Options A and D are possible but less concise. Option C and E doesn't handle missing address gracefully.
NEW QUESTION # 140
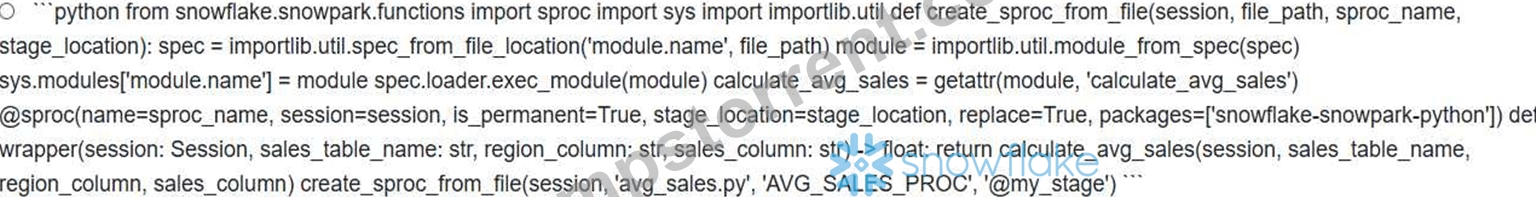
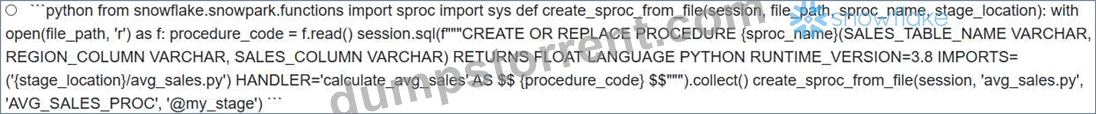
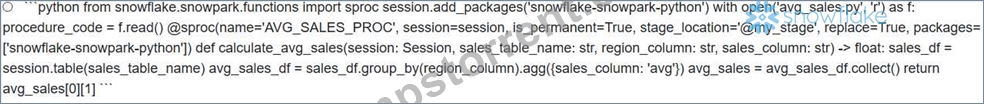
You have developed a Snowpark Python stored procedure that calculates the average sales per region from a large sales data table. The procedure is currently defined inline within your Snowflake notebook. You want to operationalize this by creating the stored procedure from a local Python file named The file contains the following code: "'python from snowflake.snowpark.session import Session def calculate_avg_sales(session: Session, sales_table_name: str, region_column: str, sales_column: str) -> float: sales df = session.table(sales table name) avg_sales df = sales_df.group_by(region_column).agg({sales_column: 'avg'}) avg_sales = avg_sales_df.collect() return avg_sales[0][1] Which of the following code snippets correctly creates the stored procedure 'AVG SALES PROC in Snowflake, referencing the Python file, and handles potential dependency issues? Assume you have already established a Snowpark session named 'session' and that the stage 'my_stage' already exists.


Answer: C
Explanation:
Option D is the most appropriate because it correctly reads the Python file's content, constructs the CREATE PROCEDURE SQL statement dynamically, and uses the correct HANDLER syntax. It also correctly specifies the imports from the stage. It uses f-strings to create the SQL command in the code and make it dynamic. Option A would attempt to define the stored procedure inline, negating the purpose of creating it from an external file. Option B fails to correctly point to the handler function within the imported file, causing errors when the procedure executes. The entire file contents are being injected in to an SQL command instead of using the module import feature. Option C is incomplete. The handler attribute in the 'CREATE PROCEDURE' command needs to be explicitly defined for stored procedures created from files on a stage. Option C is also unnecessarily complex with dynamic module loading. Snowflake can handle loading from the stage directly using the HANDLER attribute correctly. There is no need to import the module yourself using importlib and then wrapping it in another sproc. Option E attempts to create the stored procedure in the current session but load the code from local. This will cause issues. It has to load code locally or stage.
NEW QUESTION # 141
You are developing a Snowpark application that uses a Python UDF to perform geocoding operations. This UDF relies on a third-party geocoding library and a large dataset of geographical data stored in a file named 'geodata.db'. The UDF needs to be operationalized with minimal latency. Which of the following strategies will result in the FASTEST execution of the UDF and optimal resource utilization?
Answer: E
Explanation:
Option E is the most efficient strategy. Packaging the library and data file in a ZIP, referencing it with 'imports' , and using a global variable with caching within the UDF minimizes latency by loading the data only once per worker. It also benefits from utilizing the parallel processing capabilities of Snowpark. Using Java UDF's (C) is less efficient, unless it is highly optimized since java conversion can happen and adds overhead . Relying on external geocoding services (D) introduces network latency and is not ideal for performance. While a custom Anaconda channel (B) can simplify dependency management, it does not address the issue of loading the large 'geodata.db' file efficiently. Option A addresses the dependency managment but performance is not addressed.
NEW QUESTION # 142
You are developing a Snowpark Python application that reads data from a Snowflake table, performs several transformations including filtering, aggregation, and joining with another DataFrame, and then writes the results back to a new table. You want to optimize the execution plan to minimize data movement and processing time. Which of the following strategies would be MOST effective in leveraging Snowpark's lazy evaluation capabilities to achieve this optimization?
Answer: C
Explanation:
Chaining transformations and delaying execution until the final action allows Snowpark to optimize the entire query plan. Caching the initial DataFrame might improve performance in some cases, but it can also introduce unnecessary materialization. Defining transformations in a single SQL query string bypasses Snowpark's optimization capabilities. Calling 'collect()' after each transformation defeats the purpose of lazy evaluation. Python multiprocessing does not directly interact with Snowpark's query optimization.
NEW QUESTION # 143
......
You can know what knowledge points you do not master. By the report from our SPS-C01 study questions. Then it will be very easy for you to make your own learning plan. We believe that the learning plan based on the report of our SPS-C01 preparation exam will be very useful for you. So if you buy our SPS-C01 Practice Engine, it will help you pass your exam and get the certification in a short time, and you will find that our study materials are good value for money.
Latest SPS-C01 Exam Preparation: https://www.dumpstorrent.com/SPS-C01-exam-dumps-torrent.html
BTW, DOWNLOAD part of DumpsTorrent SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1Z_9HX4yQBbbQQytnN6TYOucbQp1n5QV1