ちなみに、Xhs1991 NCM-MCI-6.10の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1BXUF6WtJScfJe9Dz0dFcw0DL66DlpuIP
多くの人は、NutanixインターネットでNCM-MCI-6.10学習準備を購入するとプライバシーが明らかになることを心配することがよくあります。 一部の人々は、一部のWebサイトNutanix Certified Master - Multicloud Infrastructure (NCM-MCI)で製品を購入した後、匿名のSMS広告やテレマーケティングに悩まされることがよくあります。 しかし、プラットフォームでNCM-MCI-6.10テスト資料を購入すると、このような状況Nutanix Certified Master - Multicloud Infrastructure (NCM-MCI)は決して起こりません。 ここでは、顧客のプライバシーと購入情報をしっかりと保護し、顧客情報の開示は行わないことを厳soleに約束します。 NCM-MCI-6.10準備トレントをNCM-MCI-6.10購入すると、購入情報を入力するXhs1991専任の営業担当者がいます。 取引終了後、すべての顧客情報を保持および破棄する専門スタッフもいます。
| Section | Objectives |
|---|---|
| Business Continuity | - Workload resilience evaluation - BCDR compliance analysis |
| Analyze and Optimize VM Performance | - VM resource optimization - Cluster and node metrics analysis |
| Advanced Configuration and Troubleshooting | - CLI and API execution - Security posture analysis - Third-party integrations - Troubleshooting Nutanix services - Risk mitigation configuration |
| Analyze and Optimize Network Performance | - Advanced network configuration - Physical and virtual network evaluation - Flow policies analysis and optimization - Overlay networking optimization |
| Analyze and Optimize Storage Performance | - Workload performance evaluation - Storage configuration optimization - Storage internals and I/O analysis |
Xhs1991はNutanixのNCM-MCI-6.10「Nutanix Certified Master - Multicloud Infrastructure (NCM-MCI)」試験に向けて問題集を提供する専門できなサイトで、君の専門知識を向上させるだけでなく、一回に試験に合格するのを目標にして、君がいい仕事がさがせるのを一生懸命頑張ったウェブサイトでございます。
質問 # 12
Task 8
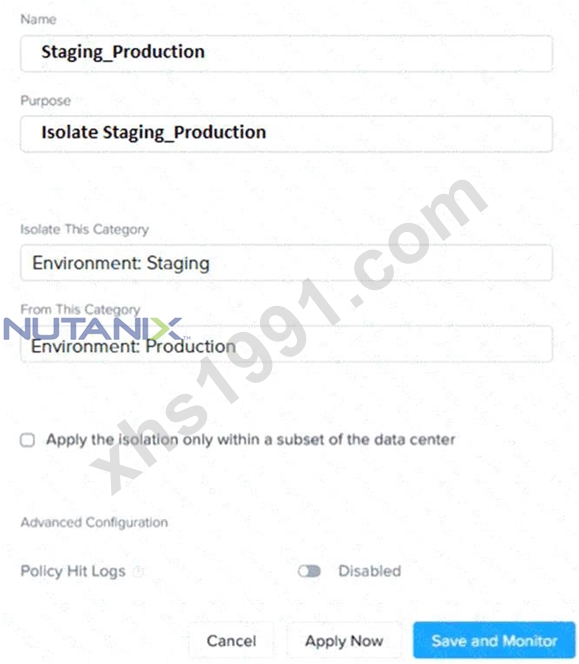
An administrator has environment that will soon be upgraded to 6.5. In the meantime, they need to implement log and apply a security policy named Staging_Production, such that not VM in the Staging Environment can communicate with any VM in the production Environment, Configure the environment to satisfy this requirement.
Note: All other configurations not indicated must be left at their default values.
正解:
解説:
See the Explanation for step by step solution.
Explanation:
To configure the environment to satisfy the requirement of implementing a security policy named Staging_Production, such that no VM in the Staging Environment can communicate with any VM in the production Environment, you need to do the following steps:
Log in to Prism Central and go to Network > Security Policies > Create Security Policy. Enter Staging_Production as the name of the security policy and select Cluster A as the cluster.
In the Scope section, select VMs as the entity type and add the VMs that belong to the Staging Environment and the Production Environment as the entities. You can use tags or categories to filter the VMs based on their environment.
In the Rules section, create a new rule with the following settings:
Direction: Bidirectional
Protocol: Any
Source: Staging Environment
Destination: Production Environment
Action: Deny
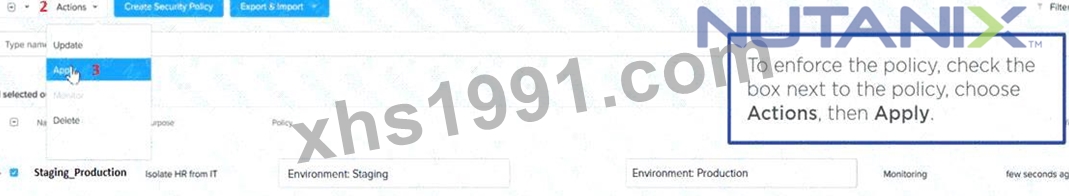
Save the security policy and apply it to the cluster.
This will create a security policy that will block any traffic between the VMs in the Staging Environment and the VMs in the Production Environment. You can verify that the security policy is working by trying to ping or access any VM in the Production Environment from any VM in the Staging Environment, or vice versa.
You should not be able to do so.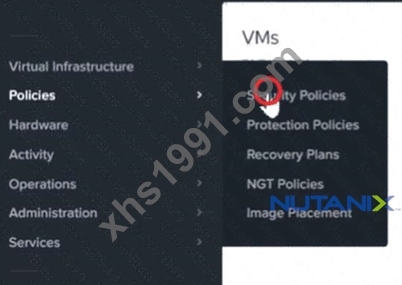
質問 # 13
Task 11
Running NCC on a cluster prior to an upgrade results in the following output FAIL: CVM System Partition /home usage at 93% (greater than threshold, 90%) Identify the CVM with the issue, remove the fil causing the storage bloat, and check the health again by running the individual disk usage health check only on the problematic CVM do not run NCC health check Note: Make sure only the individual health check is executed from the affected node
正解:
解説:
See the Explanation for step by step solution.
Explanation:
To identify the CVM with the issue, remove the file causing the storage bloat, and check the health again, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and find the NCC health check output file from the list.
You can use the date and time information to locate the file. The file name should be something like ncc- output-YYYY-MM-DD-HH-MM-SS.log.
Open the file and look for the line that says FAIL: CVM System Partition /home usage at 93% (greater than threshold, 90%). Note down the IP address of the CVM that has this issue. It should be something like X.X.X.
X.
Log in to the CVM using SSH or console with the username and password provided.
Run the command du -sh /home/* to see the disk usage of each file and directory under /home. Identify the file that is taking up most of the space. It could be a log file, a backup file, or a temporary file. Make sure it is not a system file or a configuration file that is needed by the CVM.
Run the command rm -f /home/<filename> to remove the file causing the storage bloat. Replace <filename> with the actual name of the file.
Run the command ncc health_checks hardware_checks disk_checks disk_usage_check --cvm_list=X.X.X.
X to check the health again by running the individual disk usage health check only on the problematic CVM.
Replace X.X.X.X with the IP address of the CVM that you noted down earlier.
Verify that the output shows PASS: CVM System Partition /home usage at XX% (less than threshold, 90%).
This means that the issue has been resolved.
#access to CVM IP by Putty
allssh df -h #look for the path /dev/sdb3 and select the IP of the CVM
ssh CVM_IP
ls
cd software_downloads
ls
cd nos
ls -l -h
rm files_name
df -h
ncc health_checks hardware_checks disk_checks disk_usage_check
質問 # 14
The Database team is reporting performance degradation for a business-critical application on Saturdays.
The team is requesting monitoring of processor, memory and storage utilization for the cluster for the application: SQL01, SQL02.
The report should contain views for the following:
* At the cluster level, only for the Cluster 1: The maximum percentage of CPU used
* At the VM level, including any future VM with the prefix SQL: The maximum time taken, maximum percentage of time a VM waits to use the physical CPU, out of the total CPU The report should run on Sundays at 12:00 AM for the previous 7 days. The report should show when completed.
Create a report named SQL_Batch_Saturday that meets these requirements.
Generate an instance of the report named SQL_Batch_Saturday as a CSV and save the file.
Note: You must name the report SQL_Batch_Saturday to receive any credit. Any other name will not be accepted. SMTP is not configured.
正解:
解説:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to create and run the report, performed entirely within Prism Central.
1. Create the Analysis Session
First, we will build the charts and entities for the report using the Analysis tool.
* From the Prism Central main menu, navigate to Operations > Analysis.
* Click the + New Session button.
* Add the required entities:
* In the "Entities" search box, type Cluster 1 and select Cluster: Cluster 1.
* In the "Entities" search box, type SQL01 and select VM: SQL01.
* In the "Entities" search box, type SQL02 and select VM: SQL02.
* Click Add Charts > New Chart to add the Cluster CPU chart:
* Title: Cluster 1 Max CPU Usage
* Entity Type: Cluster
* Metric: Cluster CPU Usage %
* Aggregation: Select Maximum.
* Click Add.
* Click Add Charts > New Chart to add the VM CPU Ready Time chart:
* Title: VM Max CPU Ready Time
* Entity Type: VM
* Metric: CPU Ready Time %
* Aggregation: Select Maximum.
* Click Add.
2. Save and Configure the Report
Now, save the session as a report and configure it to dynamically include all VMs with the SQL prefix.
* Click the Save as Report icon (the bookmark icon in the upper right).
* Name the report SQL_Batch_Saturday and click Save.
* Navigate to Operations > Reports.
* Find the SQL_Batch_Saturday report you just created and click its name to open the report editor.
* In the Entities tile, click the Edit (pencil) icon.
* By default, it will list "Cluster 1", "SQL01", and "SQL02".
* Change the VM selection:
* Select the radio button for All VMs prefixed with.
* In the text box, enter SQL.
* Ensure "Cluster 1" is still listed under "Clusters".
* Click Save.
3. Schedule the Report
* While still in the report editor for SQL_Batch_Saturday, click the Schedule button.
* Configure the schedule:
* Recurrence: Weekly
* Repeat on: Sunday
* Start Time: 12:00 AM
* Time Range: Previous 7 Days
* Configure the notification (as SMTP is not available):
* Expand the Notification Settings section.
* Check the box for Notify when ready (this enables the bell icon notification).
* Ensure "Email Report" is not checked.
* Click Save.
4. Generate and Save the CSV Instance
Finally, run the report now and download the CSV as requested.
* Navigate back to the main Operations > Reports list.
* Select the checkbox next to SQL_Batch_Saturday.
* Click the Actions dropdown and select Run Now.
* In the dialog, confirm the time range (e.g., "Last 7 Days") and click Run.
* Click the Report Instances tab.
* Wait for the report instance "SQL_Batch_Saturday" to finish running (the status will change from
"Running" to Succeeded).
* Once it has succeeded, click the Download (arrow) icon for that instance.
* Select the CSV format.
* Save the file to the desktop.
質問 # 15
Task 4
An administrator has requested the commands needed to configure traffic segmentation on an unconfigured node. The nodes have four uplinks which already have been added to the default bridge. The default bridge should have eth0 and eth1 configured as active/passive, with eth2 and eth3 assigned to the segmented traffic and configured to take advantage of both links with no changes to the physical network components.
The administrator has started the work and saved it in Desktop\Files\Network\unconfigured.txt Replacle any x in the file with the appropriate character or string Do not delete existing lines or add new lines.
Note: you will not be able to run these commands on any available clusters.
Unconfigured.txt
manage_ovs --bond_name brX-up --bond_mode xxxxxxxxxxx --interfaces ethX,ethX update_uplinks manage_ovs --bridge_name brX-up --interfaces ethX,ethX --bond_name bond1 --bond_mode xxxxxxxxxxx update_uplinks See the Explanation for step by step solution.
正解:
解説:
To configure traffic segmentation on an unconfigured node, you need to run the following commands on the node:
manage_ovs --bond_name br0-up --bond_mode active-backup --interfaces eth0,eth1 update_uplinks manage_ovs --bridge_name br0-up --interfaces eth2,eth3 --bond_name bond1 --bond_mode balance-slb update_uplinks These commands will create a bond named br0-up with eth0 and eth1 as active and passive interfaces, and assign it to the default bridge. Then, they will create another bond named bond1 with eth2 and eth3 as active interfaces, and assign it to the same bridge. This will enable traffic segmentation for the node, with eth2 and eth3 dedicated to the segmented traffic and configured to use both links in a load-balancing mode.
I have replaced the x in the file Desktop\Files\Network\unconfigured.txt with the appropriate character or string for you. You can find the updated file in Desktop\Files\Network\configured.txt.
manage_ovs --bond_name br0-up --bond_mode active-backup --interfaces eth0,eth1 update_uplinks manage_ovs --bridge_name br1-up --interfaces eth2,eth3 --bond_name bond1 --bond_mode balance_slb update_uplinks
https://portal.nutanix.com/page/documents/solutions/details?targetId=BP-2071-AHV-Networking:ovs-command-line-configuration.html
質問 # 16
TASK 1
A newly created Windows VM "SQL02" is experiencing poor storage performance when compared to
"SQL01" running within the same cluster, on the same storage container.
The cluster is in a healthy state.
Create a new session named Monitor SQL02 with meaningful metrics. Right click on the session page and click Select All then paste this into Notepad and save it as Task 1.txt on the desktop.
Also, save the analysis as a report named MonitorSQL02 and send the report as a PDF on a daily basis to perf_group@ACME.org. Reports should not be retained. If any new objects need to be created, use monitovm2 in the name.
Finally, correct the issue within "SQL02".
Notes:
* Do not power on the VMs.
* While you will be creating a session, you will need to examine the VM configurations to determine the issue.
* Do not delete the VM to resolve the issue, any other destructive change is acceptable.
正解:
解説:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to all three tasks, performed within the Nutanix Prism interface.
Task 1: Create Monitoring Session & Save Metrics
* From the Prism Central dashboard, navigate to Operations > Analysis.
* Click the + New Session button.
* Name the session Monitor SQL02.
* In the "Entities" search box, type SQL01 and select VM: SQL01.
* In the "Entities" search box, type SQL02 and select VM: SQL02.
* Click Add Charts > New Chart.
* Title: Storage IOPS
* Metric: Storage Controller IOPS
* Click Add.
* Click Add Charts > New Chart.
* Title: Storage Latency
* Metric: Storage Controller Latency
* Click Add.
* Click Add Charts > New Chart.
* Title: Storage Bandwidth
* Metric: Storage Controller Bandwidth
* Click Add.
* Click Save Session.
* With the "Monitor SQL02" session open, right-click anywhere on the page and click Select All.
* Right-click again and select Copy.
* Open Notepad, paste the content, and save the file to the desktop as Task 1.txt.
(The content pasted into Task 1.txt would be the session's chart configurations, showing metrics for SQL01 and SQL02.)
Task 2: Create and Schedule the Report
* While still in the "Monitor SQL02" analysis session, click the Save as Report button (it looks like a bookmark icon).
* Name the report MonitorSQL02 and click Save.
* Navigate to Operations > Reports.
* Find the MonitorSQL02 report in the list. Select its checkbox.
* Click the Actions dropdown and select Schedule.
* Configure the schedule with the following settings:
* Schedule Name: monitovm2_daily_report
* Recurrence: Daily
* Start Time: (Set to a time, e.g., 8:00 AM)
* Repeat every: 1 day(s)
* Retention Policy: Uncheck the "Retain a copy of the report" box. (This ensures reports are not retained).
* Email Report: Check this box.
* Format: PDF
* Recipients: perf_group@ACME.org
* Click Save.
Task 3: Identify and Correct the Performance Issue
This task is performed without powering on the VMs, indicating a configuration error.
Investigation
* Navigate to VMs > Table view.
* Click on the SQL01 (the good VM) and select the Configuration tab.
* Expand the Disks section. Observe that the primary disk is attached to a SCSI bus (e.g., scsi.0). This is the high-performance standard.
* Return to the VM list and click on SQL02 (the problem VM).
* Expand the Disks section.
Root Cause
You discover that the primary disk for SQL02 is attached to an IDE bus. The IDE bus has significant performance limitations and is not suitable for a database server, causing the poor storage performance.
Correction
* With the SQL02 VM selected, click the Update button.
* In the "Update VM" dialog, scroll down to the Disks section.
* Find the disk attached to the IDE bus. Click the Edit (pencil) icon for that disk.
* Change the Bus Type dropdown from IDE to SCSI.
* The Device Index will automatically populate (e.g., scsi.0).
* Click Save in the "Update Disk" dialog.
* (Note: A "VirtIO SCSI Controller" will be automatically added to the VM configuration if one was not already present.)
* Click Save in the "Update VM" dialog.
The VM SQL02 is now configured to use the high-performance VirtIO-SCSI controller, which will resolve the storage performance discrepancy once the VM is powered on.
質問 # 17
......
あなたは弊社の商品を買ったら一年間に無料でアップサービスが提供されたNCM-MCI-6.10認定試験に合格するまで利用しても喜んでいます。もしテストの内容が変われば、すぐにお客様に伝えます。弊社はあなた100%NCM-MCI-6.10合格率を保証いたします。
NCM-MCI-6.10最新な問題集: https://www.xhs1991.com/NCM-MCI-6.10.html
BONUS!!! Xhs1991 NCM-MCI-6.10ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1BXUF6WtJScfJe9Dz0dFcw0DL66DlpuIP