Außerdem sind jetzt einige Teile dieser ITZert NCM-MCI-6.10 Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1IVF1GksVOspUI-YyGf1X1ZR0gACmPpjG
Während andere Leute noch überall die Prüfungsunterlagen für Nutanix NCM-MCI-6.10 suchen, üben Sie schon verschiedene Prüfungsaufgaben. Sie können im Vorbereitungsphase schon ganz vorne liegen. Wir ITZert bieten Ihnen Nutanix NCM-MCI-6.10 Prüfungsunterlagen mit reichliche Ressourcen. Sie dürfen auch die ganz realistische Prüfungsumwelt der Nutanix NCM-MCI-6.10 Prüfung damit erfahren.
| Section | Objectives |
|---|---|
| Topic 1: Analyze and Optimize VM Performance | - Cluster and node metrics analysis - VM resource optimization |
| Topic 2: Analyze and Optimize Storage Performance | - Workload performance evaluation - Storage configuration optimization - Storage internals and I/O analysis |
| Topic 3: Advanced Configuration and Troubleshooting | - Third-party integrations - Risk mitigation configuration - CLI and API execution - Troubleshooting Nutanix services - Security posture analysis |
| Topic 4: Analyze and Optimize Network Performance | - Flow policies analysis and optimization - Overlay networking optimization - Physical and virtual network evaluation - Advanced network configuration |
| Topic 5: Business Continuity | - Workload resilience evaluation - BCDR compliance analysis |
>> Nutanix NCM-MCI-6.10 Deutsche <<
Was Wir Ihnen bieten sind, die neuesten und die umfassendesten Test-Bank von Nutanix NCM-MCI-6.10, die risikolose Kaufgarantie und die rechtzeitige Aktualisierung der Nutanix NCM-MCI-6.10. Sie werden sich beim Kauf unbesorgt fühlen, indem Sie die Demo unserer Software kostenlos zu probieren. Die einjährige kostenfreie Aktualisierung der Nutanix NCM-MCI-6.10 erleichtern Ihre Sorgen bei der Prüfungsvorbereitung. Was wir am meisten garantieren ist, dass unsere Software vielen Prüfungsteilnehmern bei der Zertifizierung der Nutanix NCM-MCI-6.10 geholfen hat.
28. Frage
Task 5
An administrator has noticed that after a host failure, the SQL03 VM was not powered back on from another host within the cluster. The Other SQL VMs (SQL01, SQL02) have recovered properly in the past.
Resolve the issue and configure the environment to ensure any single host failure affects a minimal number os SQL VMs.
Note: Do not power on any VMs
Antwort:
Begründung:
See the Explanation for step by step solution.
Explanation:
One possible reason why the SQL03 VM was not powered back on after a host failure is that the cluster was configured with the default (best effort) VM high availability mode, which does not guarantee the availability of VMs in case of insufficient resources on the remaining hosts. To resolve this issue, I suggest changing the VM high availability mode to guarantee (reserved segments), which reserves some memory on each host for failover of VMs from a failed host. This way, the SQL03 VM will have a higher chance of being restarted on another host in case of a host failure.
To change the VM high availability mode to guarantee (reserved segments), you can follow these steps:
Log in to Prism Central and select the cluster where the SQL VMs are running.
Click on the gear icon on the top right corner and select Cluster Settings.
Under Cluster Services, click on Virtual Machine High Availability.
Select Guarantee (Reserved Segments) from the drop-down menu and click Save.
To configure the environment to ensure any single host failure affects a minimal number of SQL VMs, I suggest using anti-affinity rules, which prevent VMs that belong to the same group from running on the same host. This way, if one host fails, only one SQL VM will be affected and the other SQL VMs will continue running on different hosts.
To create an anti-affinity rule for the SQL VMs, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and click on Create Group.
Enter a name for the group, such as SQL Group, and click Next.
Select the SQL VMs (SQL01, SQL02, SQL03) from the list and click Next.
Select Anti-Affinity from the drop-down menu and click Next.
Review the group details and click Finish.
I hope this helps. How else can I help?
https://portal.nutanix.com/page/documents/details?targetId=AHV-Admin-Guide-v6_5:ahv-affinity-policies-c.html
A screenshot of a computer Description automatically generated with medium confidence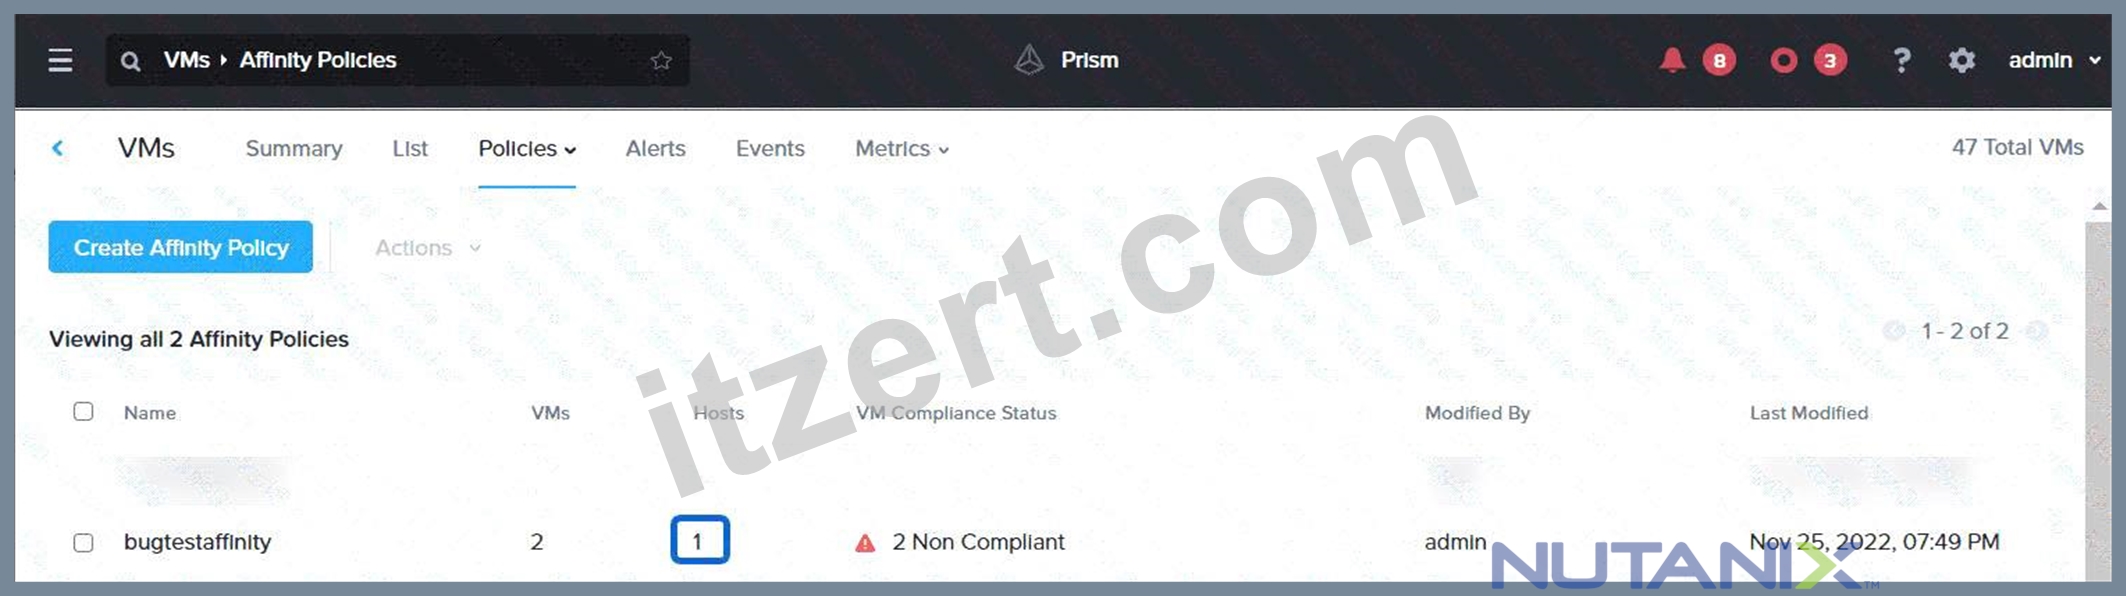
29. Frage
The DB team is requesting an SQL database instance and has requested it be configured for best performance.
This VM has been migrated from a 3 tier solution into Nutanix.
The database VM hosts 4 databases, each set to a 20 GB limit. Logs are expected to not grow beyond 20 GB and should be limited to within 25% to avoid runaway processes. Do not configure more storage than is needed.
The VM that has been migrated is identified as sql3532. Once the VM has been properly reconfigured, the DBA team will reconfigure the OS and database.
The VM should be configured as per KB-3532.
While this VM is being tested, make sure it is the first VM to power up in the event the node it is on goes down.
To maximize performance, ensure as much of the VM as possible will be kept on SSD drives.
Note: The VM does not need to be powered on. The VM should remain on the default container and should not be configured with a volume group. No network is required at this time.
Antwort:
Begründung:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to reconfigure the sql3532 virtual machine.
This task is performed from the Prism Element interface for the cluster the VM is on (e.g., Cluster 1).
1. Locate and Update the VM
* From the Prism Element main dashboard, navigate to the VM view.
* Find the VM named sql3532 in the VM table.
* Select the checkbox next to sql3532 and click the Update button.
2. Configure HA Priority and Flash Mode
In the "Update VM" dialog, configure the HA and SSD performance settings:
* HA Priority:
* Find the VM High Availability section.
* Select the High Priority radio button. This ensures it is one of the first VMs to power on during an HA event.
* Flash Mode (SSD Performance):
* Scroll down to the Flash Mode section.
* Check the box to Enable Flash Mode. This pins the VM's vDisks to the SSD tier, satisfying the requirement to keep as much of the VM as possible on SSDs, especially since it's on the default (hybrid) container.
3. Reconfigure Disks (per KB-3532)
While still in the "Update VM" dialog, scroll to the Disks section to add the new data and log disks. The key to "best performance" (KB-3532) is to place Data and Logs on separate vSCSI controllers.
* (The VM already has an OS disk, which we will assume is on scsi.0.)
* Add Data Disk:
* Click the + Add New Disk button.
* Storage Container: default (as required).
* Size: 80 GB (for the 4 x 20 GB databases).
* Bus Type: SCSI.
* Device Index: 1. (This creates a new vSCSI controller, scsi.1, for the data disk).
* Click Add.
* Add Log Disk:
* Click the + Add New Disk button.
* Storage Container: default (as required).
* Size: 20 GB.
* Bus Type: SCSI.
* Device Index: 2. (This creates a third vSCSI controller, scsi.2, for the log disk).
* Click Add.
4. Save Configuration
* After adding the disks and setting HA/Flash Mode, click the main Save button at the bottom of the
"Update VM" dialog.
The VM is now configured with high availability, its storage is pinned to SSD, and its disk layout follows performance best practices by separating the OS, Data, and Log I/O paths onto three different controllers.
30. Frage
Task 1
An administrator needs to configure storage for a Citrix-based Virtual Desktop infrastructure.
Two VDI pools will be created
Non-persistent pool names MCS_Pool for tasks users using MCS Microsoft Windows 10 virtual Delivery Agents (VDAs) Persistent pool named Persist_Pool with full-clone Microsoft Windows 10 VDAs for power users
20 GiB capacity must be guaranteed at the storage container level for all power user VDAs The power user container should not be able to use more than 100 GiB Storage capacity should be optimized for each desktop pool.
Configure the storage to meet these requirements. Any new object created should include the name of the pool (s) (MCS and/or Persist) that will use the object.
Do not include the pool name if the object will not be used by that pool.
Any additional licenses required by the solution will be added later.
Antwort:
Begründung:
See the Explanation for step by step solution.
Explanation:
To configure the storage for the Citrix-based VDI, you can follow these steps:
Log in to Prism Central using the credentials provided.
Go to Storage > Storage Pools and click on Create Storage Pool.
Enter a name for the new storage pool, such as VDI_Storage_Pool, and select the disks to include in the pool.
You can choose any combination of SSDs and HDDs, but for optimal performance, you may prefer to use more SSDs than HDDs.
Click Save to create the storage pool.
Go to Storage > Containers and click on Create Container.
Enter a name for the new container for the non-persistent pool, such as MCS_Pool_Container, and select the storage pool that you just created, VDI_Storage_Pool, as the source.
Under Advanced Settings, enable Deduplication and Compression to reduce the storage footprint of the non- persistent desktops. You can also enable Erasure Coding if you have enough nodes in your cluster and want to save more space. These settings will help you optimize the storage capacity for the non-persistent pool.
Click Save to create the container.
Go to Storage > Containers and click on Create Container again.
Enter a name for the new container for the persistent pool, such as Persist_Pool_Container, and select the same storage pool, VDI_Storage_Pool, as the source.
Under Advanced Settings, enable Capacity Reservation and enter 20 GiB as the reserved capacity. This will guarantee that 20 GiB of space is always available for the persistent desktops. You can also enter 100 GiB as the advertised capacity to limit the maximum space that this container can use. These settings will help you control the storage allocation for the persistent pool.
Click Save to create the container.
Go to Storage > Datastores and click on Create Datastore.
Enter a name for the new datastore for the non-persistent pool, such as MCS_Pool_Datastore, and select NFS as the datastore type. Select the container that you just created, MCS_Pool_Container, as the source.
Click Save to create the datastore.
Go to Storage > Datastores and click on Create Datastore again.
Enter a name for the new datastore for the persistent pool, such as Persist_Pool_Datastore, and select NFS as the datastore type. Select the container that you just created, Persist_Pool_Container, as the source.
Click Save to create the datastore.
The datastores will be automatically mounted on all nodes in the cluster. You can verify this by going to Storage > Datastores and clicking on each datastore. You should see all nodes listed under Hosts.
You can now use Citrix Studio to create your VDI pools using MCS or full clones on these datastores. For more information on how to use Citrix Studio with Nutanix Acropolis, see Citrix Virtual Apps and Desktops on Nutanix or Nutanix virtualization environments.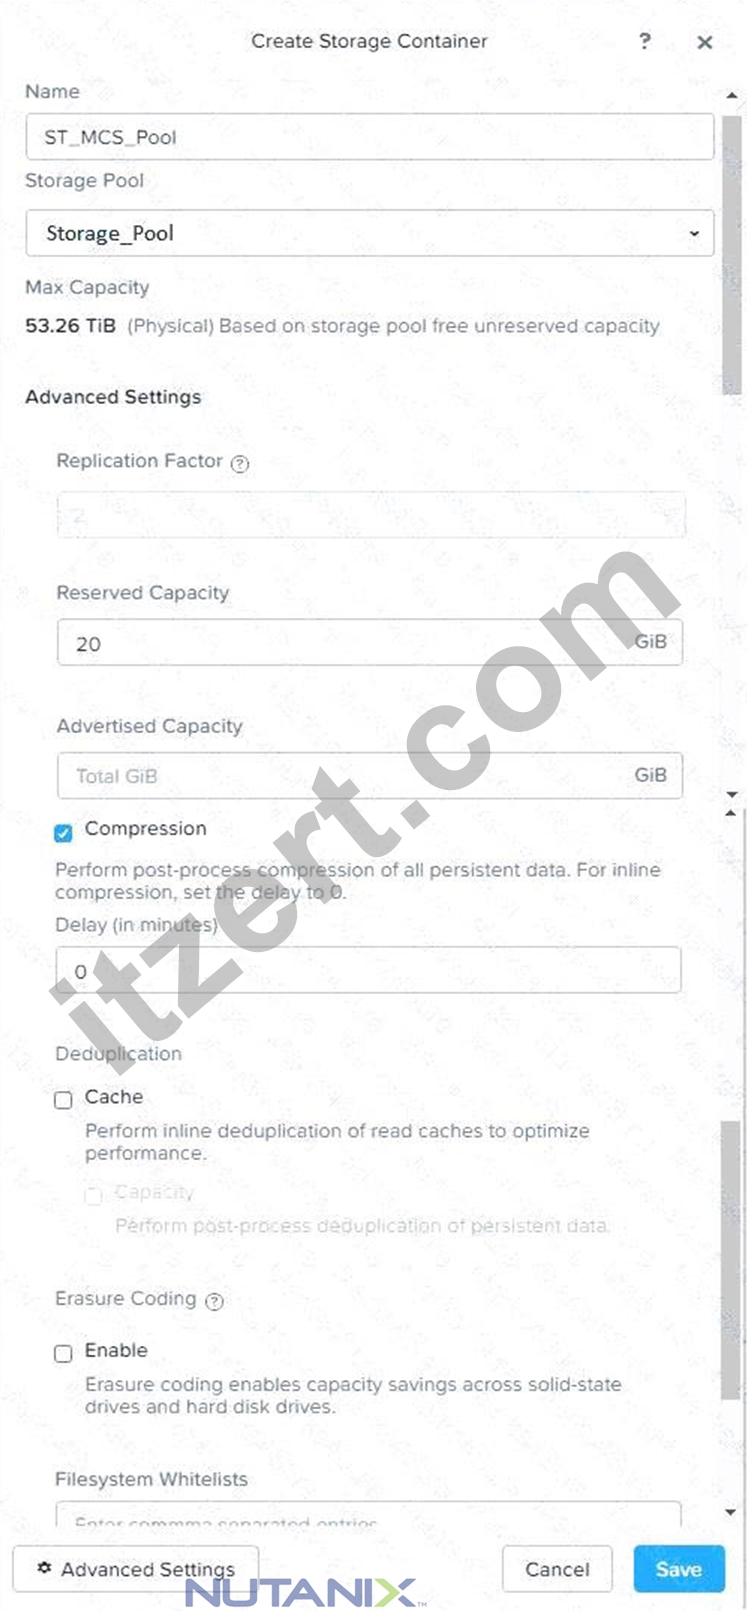
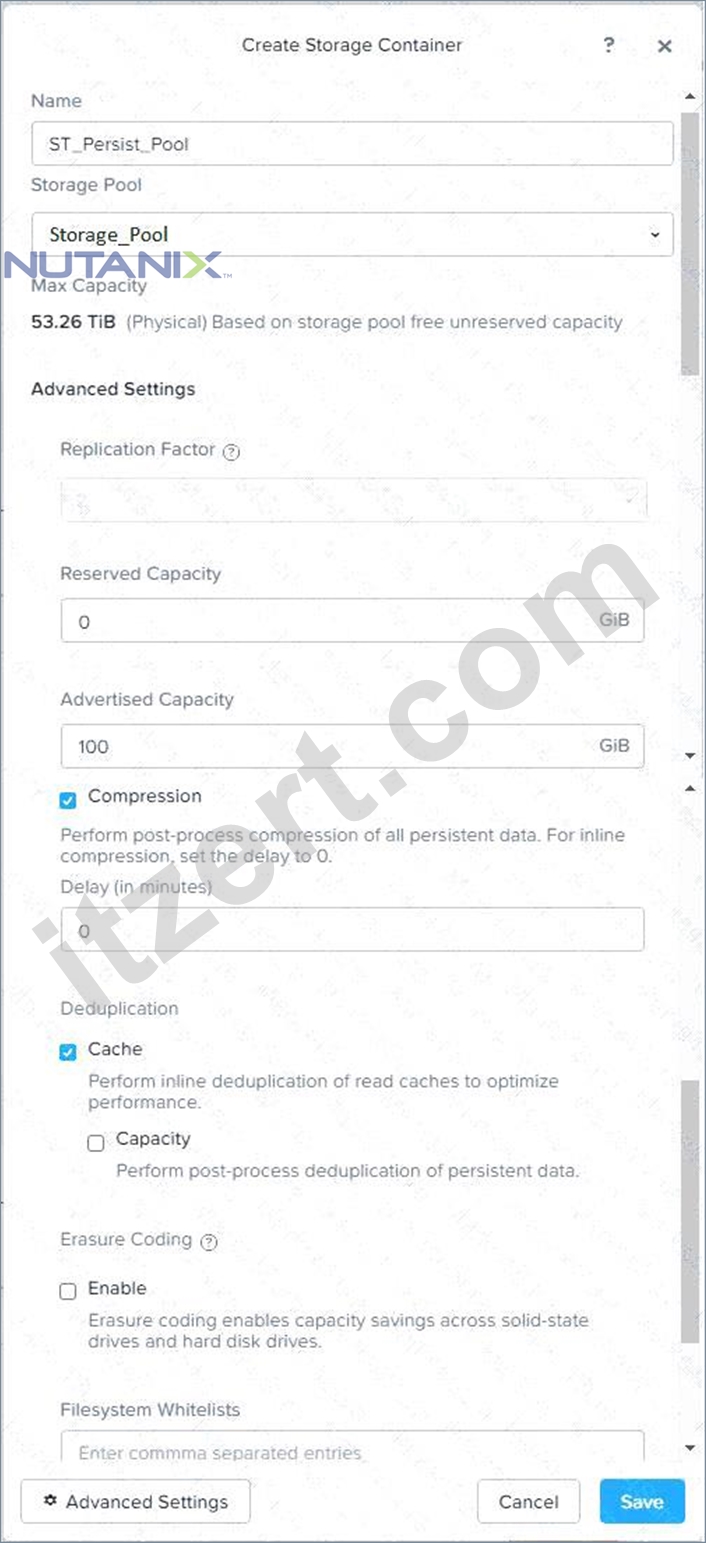
https://portal.nutanix.com/page/documents/solutions/details?targetId=BP-2079-Citrix-Virtual-Apps-and- Desktops:bp-nutanix-storage-configuration.html
31. Frage
The Database team is reporting performance degradation for a business-critical application on Saturdays.
The team is requesting monitoring of processor, memory and storage utilization for the cluster for the application: SQL01, SQL02.
The report should contain views for the following:
* At the cluster level, only for the Cluster 1: The maximum percentage of CPU used
* At the VM level, including any future VM with the prefix SQL: The maximum time taken, maximum percentage of time a VM waits to use the physical CPU, out of the total CPU The report should run on Sundays at 12:00 AM for the previous 7 days. The report should show when completed.
Create a report named SQL_Batch_Saturday that meets these requirements.
Generate an instance of the report named SQL_Batch_Saturday as a CSV and save the file.
Note: You must name the report SQL_Batch_Saturday to receive any credit. Any other name will not be accepted. SMTP is not configured.
Antwort:
Begründung:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to create and run the report, performed entirely within Prism Central.
1. Create the Analysis Session
First, we will build the charts and entities for the report using the Analysis tool.
* From the Prism Central main menu, navigate to Operations > Analysis.
* Click the + New Session button.
* Add the required entities:
* In the "Entities" search box, type Cluster 1 and select Cluster: Cluster 1.
* In the "Entities" search box, type SQL01 and select VM: SQL01.
* In the "Entities" search box, type SQL02 and select VM: SQL02.
* Click Add Charts > New Chart to add the Cluster CPU chart:
* Title: Cluster 1 Max CPU Usage
* Entity Type: Cluster
* Metric: Cluster CPU Usage %
* Aggregation: Select Maximum.
* Click Add.
* Click Add Charts > New Chart to add the VM CPU Ready Time chart:
* Title: VM Max CPU Ready Time
* Entity Type: VM
* Metric: CPU Ready Time %
* Aggregation: Select Maximum.
* Click Add.
2. Save and Configure the Report
Now, save the session as a report and configure it to dynamically include all VMs with the SQL prefix.
* Click the Save as Report icon (the bookmark icon in the upper right).
* Name the report SQL_Batch_Saturday and click Save.
* Navigate to Operations > Reports.
* Find the SQL_Batch_Saturday report you just created and click its name to open the report editor.
* In the Entities tile, click the Edit (pencil) icon.
* By default, it will list "Cluster 1", "SQL01", and "SQL02".
* Change the VM selection:
* Select the radio button for All VMs prefixed with.
* In the text box, enter SQL.
* Ensure "Cluster 1" is still listed under "Clusters".
* Click Save.
3. Schedule the Report
* While still in the report editor for SQL_Batch_Saturday, click the Schedule button.
* Configure the schedule:
* Recurrence: Weekly
* Repeat on: Sunday
* Start Time: 12:00 AM
* Time Range: Previous 7 Days
* Configure the notification (as SMTP is not available):
* Expand the Notification Settings section.
* Check the box for Notify when ready (this enables the bell icon notification).
* Ensure "Email Report" is not checked.
* Click Save.
4. Generate and Save the CSV Instance
Finally, run the report now and download the CSV as requested.
* Navigate back to the main Operations > Reports list.
* Select the checkbox next to SQL_Batch_Saturday.
* Click the Actions dropdown and select Run Now.
* In the dialog, confirm the time range (e.g., "Last 7 Days") and click Run.
* Click the Report Instances tab.
* Wait for the report instance "SQL_Batch_Saturday" to finish running (the status will change from
"Running" to Succeeded).
* Once it has succeeded, click the Download (arrow) icon for that instance.
* Select the CSV format.
* Save the file to the desktop.
32. Frage
An administrator is experiencing an unidentified issue which is causing inode exhaustion on CVMs in Cluster
1. The time between receiving alerts and exhaustion is too short; the administrator needs to lower the alert thresholds to allow more time to clean up inodes until the issue has been identified and resolution implemented.
From Prism Element, modify the appropriate alert policy setting critical threshold for Cluster 1 to 60% and warning threshold to 45%. Ensure the check runs every minute and is not resolved without administrator action.
Antwort:
Begründung:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to modify the alert policy from the Prism Element (PE) interface for Cluster 1.
1. Access Cluster 1 Prism Element
* From the main Prism Central dashboard, navigate to Hardware > Clusters.
* Find Cluster 1 in the list and click its name. This will open the specific Prism Element login page for that cluster.
* Log in to Cluster 1's Prism Element interface.
2. Modify the Alert Policy
* In the Cluster 1 PE interface, click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Alert Policies.
* In the search bar, type inode to find the correct policy.
* Select the checkbox for the policy named cvm_inode_usage_high.
* Click the Update button.
* In the "Update Alert Policy" dialog, configure the following settings:
* Warning Threshold (%): Change the value to 45.
* Critical Threshold (%): Change the value to 60.
* Check Interval (Secs): Change the value to 60 (to run the check every minute).
* Auto Resolve: Uncheck this box (to ensure the alert is not resolved without administrator action).
* Click Save.
33. Frage
......
Sorgen Sie noch um die Prüfungsunterlagen der Nutanix NCM-MCI-6.10? Jetzt brauchen Sie keine Sorgen! Weil uns zu finden bedeutet, dass Sie schon die Schlüssel zur Prüfungszertifizierung der Nutanix NCM-MCI-6.10 gefunden haben. Wir ITZert beschäftigen uns seit Jahren mit der Entwicklung der Software der IT-Zertifizierungsprüfung. Jetzt genießen wir einen guten Ruf weltweit. Wir bieten Ihnen die effektivsten Hilfe bei der Vorbereitung der Nutanix NCM-MCI-6.10.
NCM-MCI-6.10 Prüfung: https://www.itzert.com/NCM-MCI-6.10_valid-braindumps.html
Laden Sie die neuesten ITZert NCM-MCI-6.10 PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1IVF1GksVOspUI-YyGf1X1ZR0gACmPpjG