2026 Latest ExamDumpsVCE Databricks-Certified-Data-Analyst-Associate PDF Dumps and Databricks-Certified-Data-Analyst-Associate Exam Engine Free Share: https://drive.google.com/open?id=15TaIo0rwGfdV63b8eJYprhhUxnEjHoSQ
Databricks-Certified-Data-Analyst-Associate certification is more and more important for this area, but the exam is not easy for many candidates. Our Databricks-Certified-Data-Analyst-Associate practice materials make it easier to prepare exam with a variety of high quality functions. Their quality function is observably clear once you download them. We have three kinds of Databricks-Certified-Data-Analyst-Associate practice materials moderately priced for your reference. All these three types of Databricks-Certified-Data-Analyst-Associate practice materials win great support around the world and all popular according to their availability of goods, prices and other term you can think of. Just come and buy them!
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Data Analyst Associate Exam |
| Exam Number: | Databricks-Certified-Data-Analyst-Associate |
| Passing Score: | 70% |
| Related Certifications: | Databricks Certified Data Engineer Associate Databricks Certified Machine Learning Associate |
| Exam Format: | Multiple Choice |
| Certificate Validity Period: | 2 years |
| Exam Price: | $200 USD |
| Exam Duration: | 90 minutes |
| Available Languages: | English |
| Real Exam Qty: | 45 |
| Sample Questions: | Databricks Databricks-Certified-Data-Analyst-Associate Sample Questions |
| Exam Way: | Online proctored or test center proctored |
| Pre Condition: | No formal prerequisites. Databricks recommends 6+ months of hands-on experience with data analysis and Databricks SQL. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-analyst-associate |
>> Exam Databricks-Certified-Data-Analyst-Associate Cram <<
Our Databricks-Certified-Data-Analyst-Associate study practice guide takes full account of the needs of the real exam and conveniences for the clients. Our Databricks-Certified-Data-Analyst-Associate certification questions are close to the real exam and the questions and answers of the test bank cover the entire syllabus of the real exam and all the important information about the exam. Our Databricks-Certified-Data-Analyst-Associate Learning Materials can stimulate the real exam's environment to make the learners be personally on the scene and help the learners adjust the speed when they attend the real Databricks-Certified-Data-Analyst-Associate exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 58
A data analyst is using Databricks Unity Catalog. The datasets are tagged by sensitivity, and confidential data is marked with the tag key confidential. The data analyst needs to quickly find all tables tagged as confidential to review their access permissions in the Databricks workspace search bar.
Which search key text should the data analyst use to find these tables?
Answer: D
Explanation:
The correct answer is C because the tag key is confidential, and Databricks workspace search uses the syntax tag: < tag_key > to search by tag key. Therefore, the correct search text is tag:confidential. Option A uses a Boolean-style syntax that is not the documented Databricks tag search syntax. Option B uses an equals sign, and Option D is not valid workspace search syntax.
Official documentation extract used: Databricks states that to search by tag key alone, use the syntax tag: < tag_key > .
NEW QUESTION # 59
A data engineer has been using a Databricks SQL dashboard to monitor the cleanliness of the input data to a data analytics dashboard for a retail use case. The job has a Databricks SQL query that returns the number of store-level records where sales is equal to zero. The data engineer wants their entire team to be notified via a messaging webhook whenever this value is greater than 0.
Which of the following approaches can the data engineer use to notify their entire team via a messaging webhook whenever the number of stores with $0 in sales is greater than zero?
Answer: C
Explanation:
Option D is correct. Databricks SQL alerts run a query on a schedule, evaluate a condition, and notify destinations when the condition is met. Since the requirement is notification through a messaging webhook, the alert should use a webhook alert destination. Official Databricks extract: alerts "run queries on a schedule and notify you when a condition that you define is met." Databricks notification documentation also states that admins can configure alternate notification destinations using webhooks.
NEW QUESTION # 60
Consider the following two statements:
Statement 1: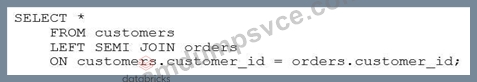
Statement 2:
Which of the following describes how the result sets will differ for each statement when they are run in Databricks SQL?
Answer: D
Explanation:
Based on the images you sent, the two statements are SQL queries for different types of joins between the customers and orders tables. A join is a way of combining the rows from two table references based on some criteria. The join type determines how the rows are matched and what kind of result set is returned. The first statement is a query for a LEFT SEMI JOIN, which returns only the rows from the left table reference (customers) that have a match with the right table reference (orders) on the join condition (customer_id). The second statement is a query for a LEFT ANTI JOIN, which returns only the rows from the left table reference (customers) that have no match with the right table reference (orders) on the join condition (customer_id).
Therefore, the result sets for the two statements will differ in the following way:
* The first statement will return a subset of the customers table that contains only the customers who have placed at least one order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT SEMI JOIN does not include any columns from the orders table.
* The second statement will return a subset of the customers table that contains only the customers who have not placed any order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have no orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT ANTI JOIN does not include any columns from the orders table.
The other options are not correct because:
* A. The first statement will not return all data from the customers table, as it will exclude the customers who have no orders. The second statement will not return all data from the orders table, as it will exclude the orders that have a matching customer. Neither statement will fill in any missing data with NULL, as they do not return any columns from the other table.
* C. There is a difference between the result sets for both statements, as explained above. The LEFT SEMI JOIN and the LEFT ANTI JOIN are not equivalent operations and will produce different outputs.
* D. Both statements will not fail, as Databricks SQL does support those join types. Databricks SQL supports various join types, including INNER, LEFT OUTER, RIGHT OUTER, FULL OUTER, LEFT SEMI, LEFT ANTI, and CROSS. You can also use NATURAL, USING, or LATERAL keywords to specify different join criteria.
* E. The first statement will not return only the customer_id from the orders table, as it will return all columns from the customers table. The second statement is correct, but it is not the only difference between the result sets.
References: JOIN | Databricks on AWS, JOIN - Azure Databricks - Databricks SQL | Microsoft Learn, array_join function | Databricks on AWS, Hints | Databricks on AWS
NEW QUESTION # 61
A data analysis team is working with the table_bronze SQL table as a source for one of its most complex projects. A stakeholder of the project notices that some of the downstream data is duplicative. The analysis team identifies table_bronze as the source of the duplication.
Which of the following queries can be used to deduplicate the data from table_bronze and write it to a new table table_silver?
A)
CREATE TABLE table_silver AS
SELECT DISTINCT *
FROM table_bronze;
B)
CREATE TABLE table_silver AS
INSERT *
FROM table_bronze;
C)
CREATE TABLE table_silver AS
MERGE DEDUPLICATE *
FROM table_bronze;
D)
INSERT INTO TABLE table_silver
SELECT * FROM table_bronze;
E)
INSERT OVERWRITE TABLE table_silver
SELECT * FROM table_bronze;
Answer: B
Explanation:
Option A uses the SELECT DISTINCT statement to remove duplicate rows from the table_bronze and create a new table table_silver with the deduplicated data. This is the correct way to deduplicate data using Spark SQL12. Option B simply inserts all the rows from table_bronze into table_silver, without removing any duplicates. Option C is not a valid syntax for Spark SQL, as there is no MERGE DEDUPLICATE statement.
Option D appends all the rows from table_bronze into table_silver, without removing any duplicates. Option E overwrites the existing data in table_silver with the data from table_bronze, without removing any duplicates. References: Delete Duplicate using SPARK SQL, Spark SQL - How to Remove Duplicate Rows
NEW QUESTION # 62
A data analyst has been asked to configure an alert for a query that returns the income in the accounts_receivable table for a date range. The date range is configurable using a Date query parameter.
The Alert does not work.
Which of the following describes why the Alert does not work?
Answer: E
Explanation:
According to the Databricks documentation1, queries that use query parameters cannot be used with Alerts. This is because Alerts do not support user input or dynamic values. Alerts leverage queries with parameters using the default value specified in the SQL editor for each parameter. Therefore, if the query uses a Date query parameter, the alert will always use the same date range as the default value, regardless of the actual date. This may cause the alert to not work as expected, or to not trigger at all. Reference:
Databricks SQL alerts: This is the official documentation for Databricks SQL alerts, where you can find information about how to create, configure, and monitor alerts, as well as the limitations and best practices for using alerts.
NEW QUESTION # 63
......
Databricks-Certified-Data-Analyst-Associate Authorized Certification: https://www.examdumpsvce.com/Databricks-Certified-Data-Analyst-Associate-valid-exam-dumps.html
DOWNLOAD the newest ExamDumpsVCE Databricks-Certified-Data-Analyst-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=15TaIo0rwGfdV63b8eJYprhhUxnEjHoSQ