Certified-Data-Engineer-Professional Latest Exam Labs - Valid Certified-Data-Engineer-Professional Exam Dumps

The Certified-Data-Engineer-Professional Certification Exam is one of the top-rated and career-oriented certificates that are designed to validate an Databricks professional's skills and knowledge level. These Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice questions have been inspiring those who want to prove their expertise with the industrial-recognized credential. By cracking it you can gain several personal and professional benefits.
| Section | Objectives |
|---|
| Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Identify the benefits of liquid clustering over partitioning and Z-Ordering
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Apply Change Data Feed to address streaming table limitations and improve latency
- 2. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 3. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 4. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 5. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
|
| Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use Query Profile and Spark UI to monitor workloads
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use system tables for observability of resource utilization, cost, auditing, and workloads
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 2. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 3. Create pipeline components using control flow operators such as if/else and foreach
- 4. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 5. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 6. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 7. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 8. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
|
>> Certified-Data-Engineer-Professional Latest Exam Labs <<
Valid Databricks Certified-Data-Engineer-Professional Exam Dumps & Certified-Data-Engineer-Professional Latest Test Fee
There is no exaggeration that you can be confident about your coming exam just after studying with our Certified-Data-Engineer-Professional preparation materials for 20 to 30 hours. Tens of thousands of our customers have benefited from our Certified-Data-Engineer-Professional Exam Dumps and passed their exams with ease. The data showed that our high pass rate is unbelievably 98% to 100%. Without doubt, your success is 100% guaranteed with our Certified-Data-Engineer-Professional training guide.
Databricks Certified Data Engineer Professional Sample Questions (Q232-Q237):
NEW QUESTION # 232
A data engineer has a Delta table orders with deletion vectors enabled. The engineer executes the following command:
DELETE FROM orders WHERE status = 'cancelled';
What should be the behavior of deletion vectors when the command is executed?
- A. Files are physically rewritten without the deleted rows.
- B. Delta automatically removes all cancelled orders permanently.
- C. Rows are marked as deleted in metadata, not in files.
- D. Rows are marked as deleted both in metadata and in files.
Answer: C
Explanation:
Deletion vectors (DVs) in Delta Lake optimize delete operations by marking deleted rows logically in metadata rather than rewriting Parquet files. When a DELETE statement is executed, affected rows are tracked by DVs in the transaction log. The data remains in the underlying files but is filtered out during query reads. This improves performance for frequent deletes and updates since file rewrites are deferred. Physical data removal only occurs when a VACUUM command is later executed. The Databricks documentation confirms: "With deletion vectors, deleted rows are marked in metadata and skipped at read time, avoiding file rewrites." Thus, rows are marked as deleted in metadata--not in files.
NEW QUESTION # 233
A data engineer is designing a secure data sharing strategy for their organization. The company needs to share sensitive customer analytics data with two different partners. Partner A uses Databricks with Unity Catalog enabled, while Partner B uses Apache Spark on AWS without Databricks. How should the company implement secure data sharing for these scenarios?
- A. Both partners should use the same Delta Sharing approach since security requirements are identical. You should create bearer tokens for both partners and use the open sharing protocol (D2O) for maximum compatibility.
- B. Open sharing protocol (D2O) should be used for both partners because it provides better security than D2D sharing. The bearer token approach is always more secure than Unity Catalog's native authentication.
- C. For Partner A, implement Databricks-to-Databricks sharing (D2D) with Unit Catalog integration and no-token exchange system. For Partner B, use open sharing protocol (D2O) with either bearer tokens or OIDC federation for authentication, ensuring both approaches maintain robust security and governance.
- D. Databricks-to-Databricks sharing (D2D) can only be used within the same cloud provider, so you must use open sharing (D2O) for any cross-cloud scenarios. Unit Catalog governance is not available when sharing with external platforms.
Answer: C
Explanation:
Databricks-to-Databricks sharing with Unity Catalog provides the most seamless and secure option for Partner A by enabling native governance, fine-grained access controls, and a no-token exchange model. For Partner B, which does not use Databricks, the open sharing protocol enables secure access from external Spark environments using standard authentication mechanisms such as bearer tokens or OIDC federation, while still enforcing sharing policies and protecting sensitive data.
NEW QUESTION # 234
A data engineer created a daily batch ingestion pipeline using a cluster with the latest DBR version to store banking transaction data, and persisted it in a MANAGED DELTA table called prod.gold.all_banking_transactions_daily. The data engineer is constantly receiving complaints from business users who query this table ad hoc through a SQL Serverless Warehouse about poor query performance. Upon analysis, the data engineer identified that these users frequently use high- cardinality columns as filters. The engineer now seeks to implement a data layout optimization technique that is incremental, easy to maintain, and can evolve over time. Which command should the data engineer implement?
- A. Alter the table to use Liquid Clustering and implement a periodic OPTIMIZE command.
- B. Alter the table to use Hive-Style Partitions and implement a periodic OPTIMIZE command.
- C. Alter the table to use Z-ORDER and implement a periodic OPTIMIZE command.
- D. Alter the table to use Hive-Style Partitions + Z-ORDER and implement a periodic OPTIMIZE command.
Answer: A
Explanation:
Databricks recommends Liquid Clustering for optimizing data layout in large Delta tables where query filters involve high-cardinality columns. Liquid Clustering automatically manages file organization and supports incremental maintenance without the need to rewrite data when clustering keys evolve. This is a key advantage over static partitioning or Z-ordering, which require costly file rewrites whenever optimization keys change. By combining Liquid Clustering with a periodic OPTIMIZE command, Databricks automatically compacts small files and maintains efficient data skipping performance. As stated in the Delta Lake optimization guide, Liquid Clustering is designed for scalability, minimal maintenance, and adaptability for analytical workloads with evolving query patterns--making B the correct answer.
NEW QUESTION # 235
An upstream source writes Parquet data as hourly batches to directories named with the current date. A nightly batch job runs the following code to ingest all data from the previous day as indicated by the date variable:
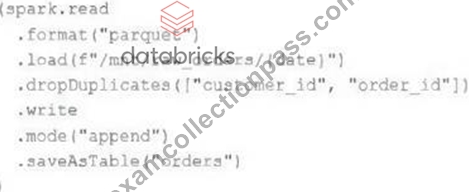
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order.
If the upstream system is known to occasionally produce duplicate entries for a single order hours apart, which statement is correct?
- A. Each write to the orders table will only contain unique records, but newly written records may have duplicates already present in the target table.
- B. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, the operation will tail.
- C. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, these records will be overwritten.
- D. Each write to the orders table will run deduplication over the union of new and existing records, ensuring no duplicate records are present.
- E. Each write to the orders table will only contain unique records, and only those records without duplicates in the target table will be written.
Answer: A
Explanation:
This is the correct answer because the code uses the dropDuplicates method to remove any duplicate records within each batch of data before writing to the orders table. However, this method does not check for duplicates across different batches or in the target table, so it is possible that newly written records may have duplicates already present in the target table. To avoid this, a better approach would be to use Delta Lake and perform an upsert operation using mergeInto.
NEW QUESTION # 236
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should have five workers, one driver of type i3.xlarge, and should use the '14.3.x- scala2.12' runtime. Which command should the data engineer use?
- A. databricks clusters create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster- name DataEngineer_cluster
- B. databricks clusters add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- C. databricks compute add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- D. databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster- name Data Engineer_cluster
Answer: A
Explanation:
The correct Databricks CLI command to create a new cluster is databricks clusters create. You specify the runtime with --spark-version (here '14.3.x-scala2.12'), the number of workers with -- num-workers, the node type with --node-type-id, and the cluster name with --cluster-name. This command properly initializes the cluster with the desired configuration.
NEW QUESTION # 237
......
If you do not quickly begin to improve your own strength, the next one facing the unemployment crisis is you. The time is very tight, and choosing our Certified-Data-Engineer-Professional study materials can save you a lot of time. And our Certified-Data-Engineer-Professional Exam Questions can really save you time and efforts. If you study with our Certified-Data-Engineer-Professional learning guide for 20 to 30 hours, then you will be able to pass the exam and get the certification.
Valid Certified-Data-Engineer-Professional Exam Dumps: https://www.examcollectionpass.com/Databricks/Certified-Data-Engineer-Professional-practice-exam-dumps.html
- Certified-Data-Engineer-Professional Test Cram Pdf 🔕 Certified-Data-Engineer-Professional Valid Exam Labs 🍙 Certified-Data-Engineer-Professional Detailed Answers 🛄 Search for ➥ Certified-Data-Engineer-Professional 🡄 and download it for free on ➠ www.examdiscuss.com 🠰 website 💮Reliable Certified-Data-Engineer-Professional Exam Book
- Certified-Data-Engineer-Professional Instant Download ✒ Certified-Data-Engineer-Professional Exam Book 🪐 Certified-Data-Engineer-Professional Boot Camp 🧫 Download 《 Certified-Data-Engineer-Professional 》 for free by simply entering ▛ www.pdfvce.com ▟ website 📿Certified-Data-Engineer-Professional Detailed Answers
- Certified-Data-Engineer-Professional Exam Brain Dumps 🌎 Certified-Data-Engineer-Professional Reliable Exam Tutorial 🔔 Certified-Data-Engineer-Professional Test Cram Pdf ☁ Open ➽ www.examdiscuss.com 🢪 and search for { Certified-Data-Engineer-Professional } to download exam materials for free 😴Certified-Data-Engineer-Professional Exam Tutorials
- Certified-Data-Engineer-Professional Reliable Test Notes ☁ New Certified-Data-Engineer-Professional Test Book 🏰 Certified-Data-Engineer-Professional Latest Real Test ⛴ Open ▶ www.pdfvce.com ◀ and search for ⮆ Certified-Data-Engineer-Professional ⮄ to download exam materials for free 💔Certified-Data-Engineer-Professional Exam Book
- 2026 Reliable Certified-Data-Engineer-Professional Latest Exam Labs | 100% Free Valid Databricks Certified Data Engineer Professional Exam Dumps 🎴 Search for 「 Certified-Data-Engineer-Professional 」 and obtain a free download on [ www.practicevce.com ] 🐫Certified-Data-Engineer-Professional Exam Book
- 2026 Certified-Data-Engineer-Professional Latest Exam Labs 100% Pass | Reliable Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional 100% Pass 🌱 Search for ➠ Certified-Data-Engineer-Professional 🠰 and download exam materials for free through ⇛ www.pdfvce.com ⇚ ♥Certified-Data-Engineer-Professional Reliable Dumps Free
- Dump Certified-Data-Engineer-Professional Collection 🍼 Certified-Data-Engineer-Professional Reliable Test Notes 📤 Certified-Data-Engineer-Professional Reliable Exam Cost 🪕 Simply search for ▶ Certified-Data-Engineer-Professional ◀ for free download on { www.examcollectionpass.com } 🧺Certified-Data-Engineer-Professional Exam Brain Dumps
- Certified-Data-Engineer-Professional Accurate Test 🛫 Certified-Data-Engineer-Professional Reliable Exam Tutorial 🎥 Certified-Data-Engineer-Professional Detailed Answers 🍯 Search for ☀ Certified-Data-Engineer-Professional ️☀️ and easily obtain a free download on ➡ www.pdfvce.com ️⬅️ ⚫New Certified-Data-Engineer-Professional Test Book
- Certified-Data-Engineer-Professional Instant Download 🗜 Certified-Data-Engineer-Professional Exam Tutorials 🎍 Certified-Data-Engineer-Professional Testking Exam Questions 🕳 Open website “ www.testkingpass.com ” and search for 「 Certified-Data-Engineer-Professional 」 for free download 🍯Certified-Data-Engineer-Professional Test Cram Pdf
- 100% Pass Quiz Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Pass-Sure Latest Exam Labs 💺 Copy URL ▷ www.pdfvce.com ◁ open and search for [ Certified-Data-Engineer-Professional ] to download for free 🎡Certified-Data-Engineer-Professional Exam Brain Dumps
- Certified-Data-Engineer-Professional Exam Tutorials 🐨 Certified-Data-Engineer-Professional Testking Exam Questions 📉 Dump Certified-Data-Engineer-Professional Collection 🧙 Simply search for “ Certified-Data-Engineer-Professional ” for free download on ▶ www.vce4dumps.com ◀ 🍜Certified-Data-Engineer-Professional Exam Brain Dumps
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes