P.S. Kostenlose und neue DP-100 Prüfungsfragen sind auf Google Drive freigegeben von EchteFrage verfügbar: https://drive.google.com/open?id=15BAtW3eOjthbxQ_4cc2GZxMOG4obPWXW
Gott ist gerecht, und jeder ist nicht perfekt. Wie wir alle wissen, ist der Wettbewerb in der IT-Branche sehr heftig.S o jeder will die IT-Zertifizierung erhalten, um einen Wert zu erhöhen. Ich denke auch so. Aber es ist zu schwierig für ich. Glücklicherweise habe ich die Dumps zur Microsoft DP-100 Zertifizierung von EchteFrage im Internet gesehen. Dann brauche ich mich keine Sorgen zu machen. Die Fragenkataloge zur Microsoft DP-100 Prüfung von EchteFrage sind wirklich gut. Sie sind umfassend und zielgerichtet. Wenn Sie auch ein Mitgleid der IT-Branche sind, fügen Sie schnell die Microsoft DP-100 Prüfung Fragenkataloge von EchteFrage in den Warenkorb hinzu. Zögern Sie nicht. Die Fragenkataloge zur Microsoft DP-100 Prüfung von EchteFrage sind Ihr bester Partner.
Die DP-100 Prüfung umfasst eine Reihe von Themen im Zusammenhang mit Datenwissenschaften, einschließlich Datenvorbereitung, Feature Engineering, Modelltraining und Bereitstellung. Kandidaten werden auf ihre Fähigkeit getestet, Azure-Services zu nutzen, um End-to-End-Maschinenlösungen zu erstellen, die im großen Maßstab bereitgestellt werden können.
>> DP-100 Simulationsfragen <<
Wenn Sie Microsoft DP-100 Zertifizierungsprüfung ablegen, ist es nötig für Sie, die richtigen Microsoft DP-100 Prüfungsunterlagen zu benutzen. Wenn Sie irgendwo die Unterlagen suchen, stoppen Sie jetzt bitte. Wenn Sie keine richtigen Unterlagen haben, probieren Sie bitte Microsoft DP-100 Dumps von EchteFrage. Die Hitrate der Dumps ist so hoch, dass sie Ihnen den einmaligen Erfolg garantieren. Im Verglich zu anderen Prüfungsunterlagen können diese Dumps die Prüfungsinhalte ganz richtig greifen. Damit können Sie Ihre Lerneffektivität erhöhen und sich besser auf Microsoft DP-100 Zertifizierungsprüfung vorbereiten.
Die Microsoft DP-100-Zertifizierungsprüfung ist ein wertvolles Zeugnis für Datenprofis, die mit Azure-Technologien arbeiten und ihre Fähigkeiten bei der Gestaltung und Umsetzung von Data-Science-Lösungen validieren möchten. Die Prüfung umfasst eine breite Palette von Themen im Zusammenhang mit Data Science und Azure-Services. Kandidaten können sich durch Absolvierung von Schulungskursen und Zugriff auf Online-Ressourcen darauf vorbereiten. Das Bestehen der DP-100-Prüfung ist eine bedeutende Leistung, die Datenprofis helfen kann, ihre Karriere voranzutreiben und ihre Expertise potenziellen Arbeitgebern zu demonstrieren.
Die DP-100-Prüfung umfasst verschiedene Themenbereiche im Zusammenhang mit Data Science, wie z.B. Datenexploration, Datenaufbereitung, Datamodellierung, Machine Learning und Datenvisualisierung. Die Prüfung testet auch das Wissen des Kandidaten über Azure-Dienste, die für Datenaufgaben verwendet werden, wie z.B. Azure Machine Learning, Azure Data Factory, Azure Stream Analytics und Azure Databricks. Das Prüfungsformat umfasst Multiple-Choice-Fragen, Fallstudien und praktische Übungen.
117. Frage
You need to implement a feature engineering strategy for the crowd sentiment local models.
What should you do?
Antwort: B
Begründung:
The linear discriminant analysis method works only on continuous variables, not categorical or ordinal variables.
Linear discriminant analysis is similar to analysis of variance (ANOVA) in that it works by comparing the means of the variables.
Scenario:
Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
Experiments for local crowd sentiment models must combine local penalty detection data.
All shared features for local models are continuous variables.
Incorrect Answers:
B: The Pearson correlation coefficient, sometimes called Pearson's R test, is a statistical value that measures the linear relationship between two variables. By examining the coefficient values, you can infer something about the strength of the relationship between the two variables, and whether they are positively correlated or negatively correlated.
C: Spearman's correlation coefficient is designed for use with non-parametric and non-normally distributed data. Spearman's coefficient is a nonparametric measure of statistical dependence between two variables, and is sometimes denoted by the Greek letter rho. The Spearman's coefficient expresses the degree to which two variables are monotonically related. It is also called Spearman rank correlation, because it can be used with ordinal variables.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/fisher-linear-discriminant- analysis
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/compute-linear-correlation Perform Feature Engineering Testlet 2 Case study This is a case study. Case studies are not timed separately. You can use as much exam time as you would like to complete each case. However, there may be additional case studies and sections on this exam. You must manage your time to ensure that you are able to complete all questions included on this exam in the time provided.
To answer the questions included in a case study, you will need to reference information that is provided in the case study. Case studies might contain exhibits and other resources that provide more information about the scenario that is described in the case study. Each question is independent of the other questions in this case study.
At the end of this case study, a review screen will appear. This screen allows you to review your answers and to make changes before you move to the next section of the exam. After you begin a new section, you cannot return to this section.
To start the case study
To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment, and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Overview
You are a data scientist for Fabrikam Residences, a company specializing in quality private and commercial property in the United States. Fabrikam Residences is considering expanding into Europe and has asked you to investigate prices for private residences in major European cities.
You use Azure Machine Learning Studio to measure the median value of properties. You produce a regression model to predict property prices by using the Linear Regression and Bayesian Linear Regression modules.
Datasets
There are two datasets in CSV format that contain property details for two cities, London and Paris. You add both files to Azure Machine Learning Studio as separate datasets to the starting point for an experiment. Both datasets contain the following columns:
An initial investigation shows that the datasets are identical in structure apart from the MedianValue column.
The smaller Paris dataset contains the MedianValue in text format, whereas the larger London dataset contains the MedianValue in numerical format.
Data issues
Missing values
The AccessibilityToHighway column in both datasets contains missing values. The missing data must be replaced with new data so that it is modeled conditionally using the other variables in the data before filling in the missing values.
Columns in each dataset contain missing and null values. The datasets also contain many outliers. The Age column has a high proportion of outliers. You need to remove the rows that have outliers in the Age column.
The MedianValue and AvgRoomsInHouse columns both hold data in numeric format. You need to select a feature selection algorithm to analyze the relationship between the two columns in more detail.
Model fit
The model shows signs of overfitting. You need to produce a more refined regression model that reduces the overfitting.
Experiment requirements
You must set up the experiment to cross-validate the Linear Regression and Bayesian Linear Regression modules to evaluate performance. In each case, the predictor of the dataset is the column named MedianValue. You must ensure that the datatype of the MedianValue column of the Paris dataset matches the structure of the London dataset.
You must prioritize the columns of data for predicting the outcome. You must use non-parametric statistics to measure relationships.
You must use a feature selection algorithm to analyze the relationship between the MedianValue and AvgRoomsInHouse columns.
Model training
Permutation Feature Importance
Given a trained model and a test dataset, you must compute the Permutation Feature Importance scores of feature variables. You must be determined the absolute fit for the model.
Hyperparameters
You must configure hyperparameters in the model learning process to speed the learning phase. In addition, this configuration should cancel the lowest performing runs at each evaluation interval, thereby directing effort and resources towards models that are more likely to be successful.
You are concerned that the model might not efficiently use compute resources in hyperparameter tuning. You also are concerned that the model might prevent an increase in the overall tuning time. Therefore, must implement an early stopping criterion on models that provides savings without terminating promising jobs.
Testing
You must produce multiple partitions of a dataset based on sampling using the Partition and Sample module in Azure Machine Learning Studio.
Cross-validation
You must create three equal partitions for cross-validation. You must also configure the cross-validation process so that the rows in the test and training datasets are divided evenly by properties that are near each city's main river. You must complete this task before the data goes through the sampling process.
Linear regression module
When you train a Linear Regression module, you must determine the best features to use in a model. You can choose standard metrics provided to measure performance before and after the feature importance process completes. The distribution of features across multiple training models must be consistent.
Data visualization
You need to provide the test results to the Fabrikam Residences team. You create data visualizations to aid in presenting the results.
You must produce a Receiver Operating Characteristic (ROC) curve to conduct a diagnostic test evaluation of the model. You need to select appropriate methods for producing the ROC curve in Azure Machine Learning Studio to compare the Two-Class Decision Forest and the Two-Class Decision Jungle modules with one another.
118. Frage
You manage an Azure Machine Learning won pace named workspace 1 by using the Python SDK v2. You create a Gene-al Purpose v2 Azure storage account named mlstorage1. The storage account includes a pulley accessible container name micOTtalnerl. The container stores 10 blobs with files in the CSV format.
You must develop Python SDK v2 code to create a data asset referencing all blobs in the container named mtcontamer1.
You need to complete the Python SDK v2 code.
How should you complete the code? To answer select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Antwort:
Begründung:
Explanation:
119. Frage
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
The default datastore of workspace1 contains a folder named sample_data. The folder structure contains the following content:
You write Python SDK v2 code to materialize the data from the files in the sample.data folder into a Pandas data frame. You need to complete the Python SDK v2 code to use the MLTaWe folder as the materialization blueprint. How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Antwort:
Begründung:
Explanation:
120. Frage
You have a Python data frame named salesData in the following format:
The data frame must be unpivoted to a long data format as follows:
You need to use the pandas.melt() function in Python to perform the transformation.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Antwort:
Begründung:
Explanation
Box 1: dataFrame
Syntax: pandas.melt(frame, id_vars=None, value_vars=None, var_name=None, value_name='value', col_level=None)[source] Where frame is a DataFrame Box 2: shop Paramter id_vars id_vars : tuple, list, or ndarray, optional Column(s) to use as identifier variables.
Box 3: ['2017','2018']
value_vars : tuple, list, or ndarray, optional
Column(s) to unpivot. If not specified, uses all columns that are not set as id_vars.
Example:
df = pd.DataFrame({'A': {0: 'a', 1: 'b', 2: 'c'},
'B': {0: 1, 1: 3, 2: 5},
'C': {0: 2, 1: 4, 2: 6}})
pd.melt(df, id_vars=['A'], value_vars=['B', 'C'])
A variable value
0 a B 1
1 b B 3
2 c B 5
3 a C 2
4 b C 4
5 c C 6
References:
https://pandas.pydata.org/pandas-docs/stable/reference/api/pandas.melt.html
121. Frage
The finance team asks you to train a model using data in an Azure Storage blob container named finance-data.
You need to register the container as a datastore in an Azure Machine Learning workspace and ensure that an error will be raised if the container does not exist.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Antwort:
Begründung: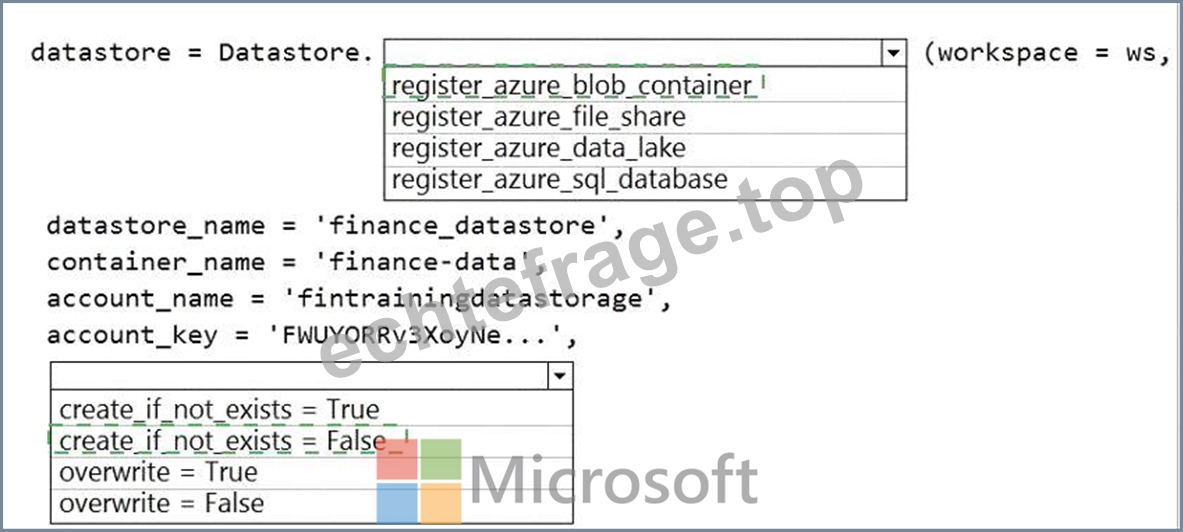
Explanation
Box 1: register_azure_blob_container
Register an Azure Blob Container to the datastore.
Box 2: create_if_not_exists = False
Create the file share if it does not exists, defaults to False.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-core/azureml.core.datastore.datastore
122. Frage
......
DP-100 Schulungsunterlagen: https://www.echtefrage.top/DP-100-deutsch-pruefungen.html
Außerdem sind jetzt einige Teile dieser EchteFrage DP-100 Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=15BAtW3eOjthbxQ_4cc2GZxMOG4obPWXW