P.S. Free & New DP-750 dumps are available on Google Drive shared by EduDump: https://drive.google.com/open?id=11W4exuY6Bd4xkseyUmIIPCMX-AS085Nx
The Practice Exam software is specially made for the students so they can feel real-based examination scenarios and feel some pressure on their brains and don't feel excessive issues while giving the final Microsoft exam. There are a lot of customers that are currently using Implementing Data Engineering Solutions Using Azure Databricks (DP-750) and are satisfied with it. EduDump has designed this product after getting positive feedback from professionals and is rated one of the best study materials for the preparation of the Microsoft DP-750 exam.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
>> Reliable DP-750 Test Prep <<
Nowadays passing the DP-750 test certification is extremely significant for you and can bring a lot of benefits to you. Passing the DP-750 test certification does not only prove that you are competent in some area but also can help you enter in the big company and double your wage. And our DP-750 Exam Questions are in good quality. As long as you study with our DP-750 learning guide, you will find that the content is easily to understand and the displays are enjoyable.
NEW QUESTION # 52
You have an Azure Databricks workspace.
You have an Apache Spark Structured Streaming job named Job! that processes data continuously and fails periodically due to transient errors You need to ensure that Job! meets the following requirements
* Resumes processing from the point that Job1 failed
* Minimizes how long it takes to restart Job!
* Minimizes the costs to restart Job!
What should you do?
Answer: D
Explanation:
The correct answer is B - implement checkpointing.
A checkpoint is a durable record of the streaming job's progress written to ADLS Gen2 or DBFS after each successfully committed micro-batch. When the job restarts after a transient failure, it reads the checkpoint to find the last committed offset and resumes from that exact point - no data is reprocessed, no data is lost.
This satisfies all three requirements directly: checkpointing enables resumption from the failure point (not from the beginning), restart is fast because there's no replay overhead, and costs are minimised because no compute is wasted reprocessing records already handled.
Option A (decrease retry interval) makes the job retry sooner but doesn't control where it resumes from.
Option C (alert and manual restart) adds human latency and doesn't prevent reprocessing without a checkpoint. Option D (increase minimum nodes) reduces the likelihood of resource-related failures but increases cost and doesn't address the recovery behaviour itself.
Reference: https://learn.microsoft.com/en-us/azure/databricks/structured-streaming/query-recovery
NEW QUESTION # 53
You have an Azure Databricks workspace that contains a Git folder and uses Azure Repos as the Git provider.
From the main branch, you create a branch named Branch1. You commit changes to Branch1.
You need to incorporate the changes from Branch1 into main The solution must preserve the commit history in the repository. Which command should you run?
Answer: C
Explanation:
The correct answer is A - merge.
A Git merge combines the histories of two branches by creating a merge commit that joins them. Every individual commit from Branch1 remains visible in the repository log - the full development history is preserved. This is the requirement: 'the solution must preserve the commit history in the repository.' Option C (rebase) moves Branch1's commits on top of main by replaying them as new commits with new hashes. The end result looks like a linear history, but the original commit hashes are rewritten - the prior history is not preserved in its original form. For a shared repository, rebase rewrites public history, which is considered problematic.
Option B (pull) fetches remote changes and merges or rebases them into the current branch - it's used to sync with a remote, not to incorporate a feature branch. Option D (push) sends local commits to the remote but doesn't incorporate any branch into another.
Reference: https://learn.microsoft.com/en-us/azure/databricks/repos/git-operations-with-repos
NEW QUESTION # 54
You have an Azure Databricks account that contains workspaces enabled for Unity Catalog.
You need to implement audit logging to meet the following requirements:
* Capture audit logs for all the workspaces in the account.
* Retain the audit logs for 90 days.
* Minimize storage and ingestion costs.
The logs will be reviewed only during security investigations and will NOT be queried regularly.
To where should you send the audit logs?
Answer: B
Explanation:
An Azure Storage account provides durable, comparatively low-cost retention for diagnostic and audit logs that are accessed infrequently. A lifecycle or retention policy can preserve the logs for 90 days and then remove them automatically. This matches an investigation-only access pattern without paying the ingestion and indexing charges associated with Log Analytics. Azure Monitor metrics stores numerical monitoring measurements, not the complete audit-event records required here. Azure Event Hubs is a streaming transport intended to forward events to consumers and is not the final long-term retention destination. Log Analytics is appropriate when teams need frequent querying, dashboards, and alerting, but those capabilities introduce unnecessary cost for logs reviewed only during occasional investigations. Storage therefore best satisfies centralized retention and cost requirements.
NEW QUESTION # 55
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.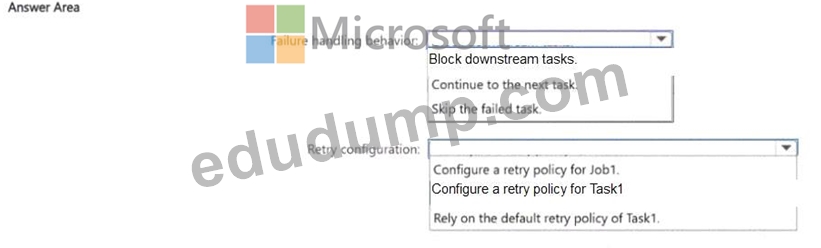
Answer:
Explanation: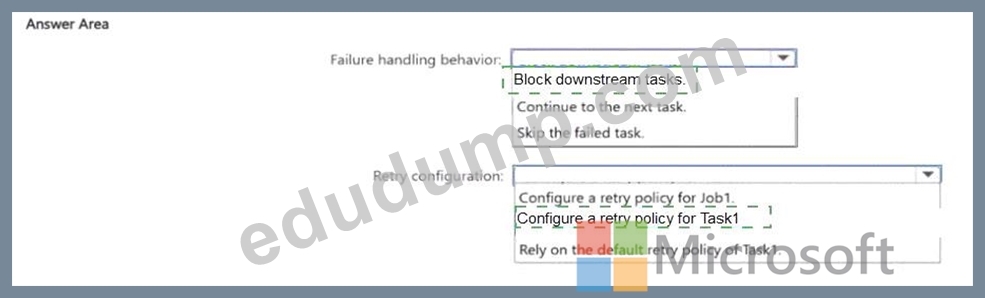
Explanation:
Two task-level settings solve this:
Task1 retry policy: configure Task1 with a maximum number of retries and a retry interval. When Task1 fails, Lakeflow Jobs automatically re-runs it up to the retry limit without any manual intervention. This handles transient infrastructure failures transparently.
Task2 run condition set to 'All succeeded' with Task1 as its dependency: this means Task2 only starts when Task1 has succeeded. If Task1 fails and exhausts all retries, Task2 remains blocked - it never runs on data from a failed upstream ingestion. The dependency is declared in Task2's 'Depends on' setting in the job configuration.
These two settings are independent and composable. Task1's retry policy gives it multiple chances to recover.
Task2's dependency and run condition ensure the downstream transformation only runs on clean, successfully ingested data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#task-retries
NEW QUESTION # 56
Hotspot Question
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.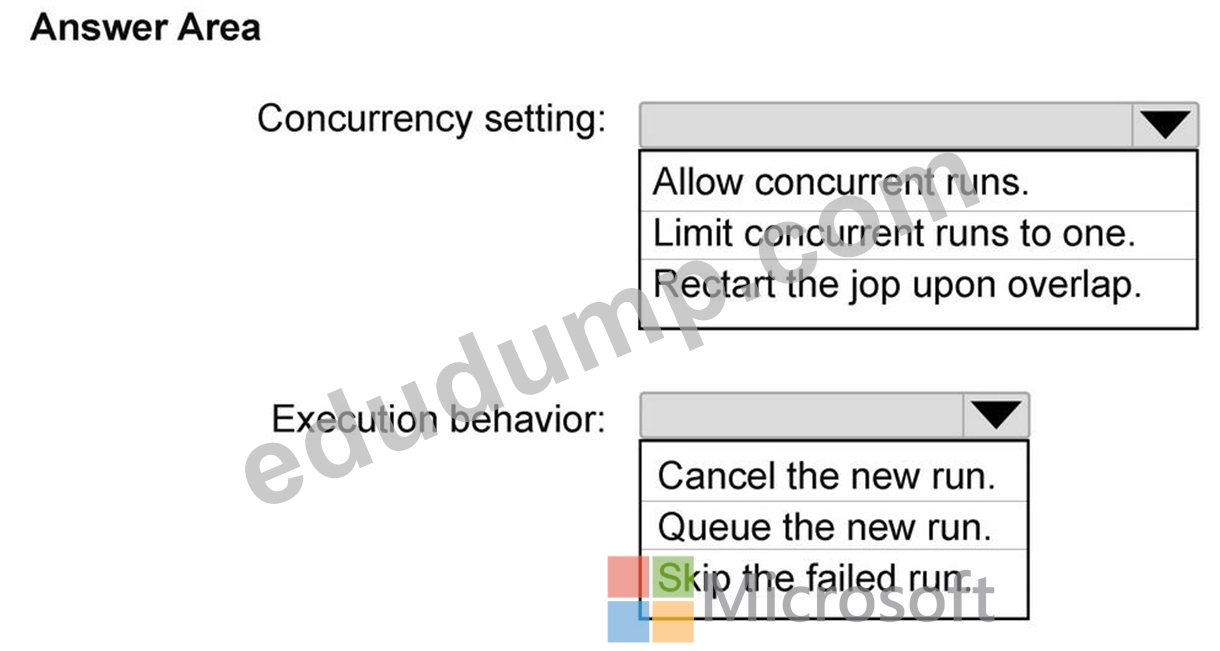
Answer:
Explanation: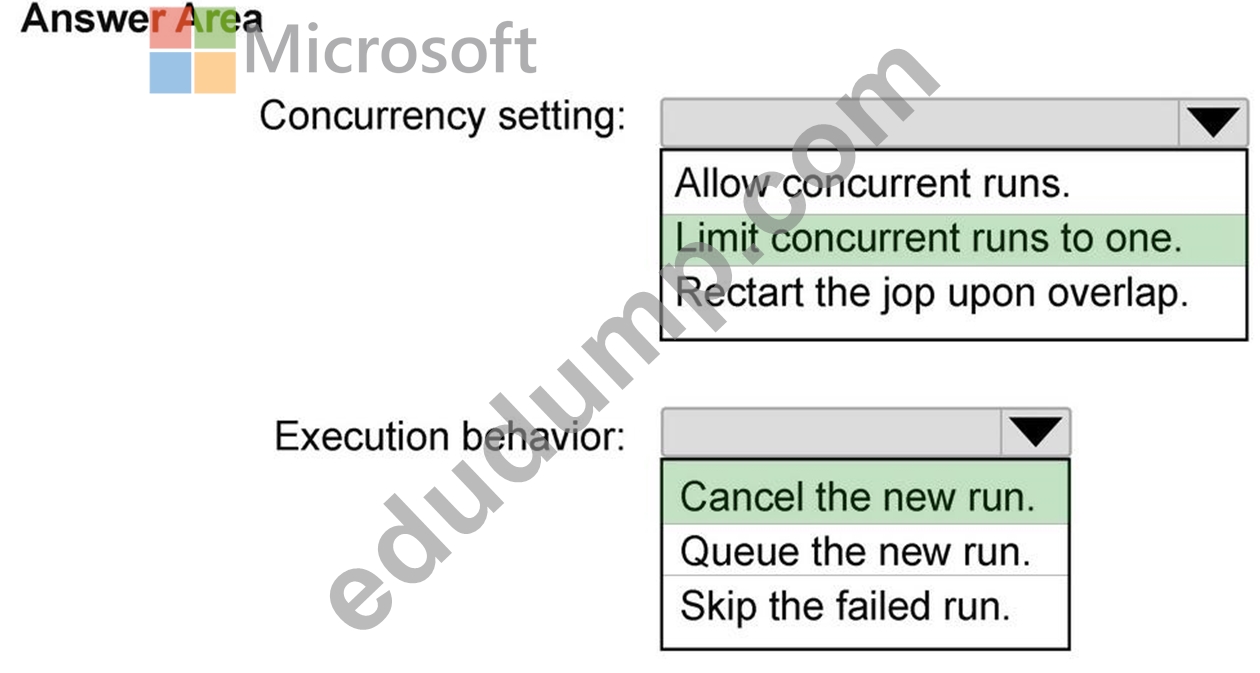
NEW QUESTION # 57
......
The DP-750 training vce offered by EduDump will be the best tool for you to pass your actual test. The DP-750 questions & answers are especially suitable for the candidates like you for the coming exam test. The contents of Microsoft study dumps are edited by our experts who have rich experience, and easy for all of you to understand. So, with the skills and knowledge you get from DP-750 practice pdf, you can 100% pass and get the certification you want.
Exam DP-750 Experience: https://www.edudump.com/exams/Microsoft/DP-750/
BTW, DOWNLOAD part of EduDump DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=11W4exuY6Bd4xkseyUmIIPCMX-AS085Nx