Certified-Data-Engineer-Professional Practice Test Online, Certified-Data-Engineer-Professional New Dumps Ebook

Our Certified-Data-Engineer-Professional practice engine boosts many merits and high passing rate. Our Certified-Data-Engineer-Professional exam questions have 3 versions and we provide free update of the Certified-Data-Engineer-Professional exam torrent to you. If you are the old client you can enjoy the discounts. Most important of all, as long as we have compiled a new version of the Certified-Data-Engineer-Professional Exam Questions, we will send the latest version of our Certified-Data-Engineer-Professional exam questions to our customers for free during the whole year after purchasing. Our Certified-Data-Engineer-Professional study guide can improve your stocks of knowledge and your abilities in some area and help you gain the success in your career.
| Section | Objectives |
|---|
| Topic 1: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Analyze errors and remediate failed job runs
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
|
| Topic 2: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
| Topic 3: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 2. Use APPLY CHANGES APIs for change data capture
- 3. Configure environments, dependencies, memory, and retry behavior
- 4. Develop unit and integration tests for data processing code
- 5. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 6. Compare streaming tables and materialized views
- 7. Use control flow operators in pipeline components
- 8. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
|
| Topic 4: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest data from message buses and cloud storage
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Topic 5: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Configure Databricks-to-Databricks Sharing
- 3. Share live Lakehouse data with external computing platforms
|
| Topic 6: Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Understand deletion vectors and liquid clustering
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
|
| Topic 7: Ensuring Data Security and Compliance | - Data Security
- 1. Use ACLs to secure workspace objects and enforce least privilege
- 2. Apply anonymization and pseudonymization techniques
- 3. Use row filters and column masks for sensitive data
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Topic 8: Monitoring and Alerting | - Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use system tables for resource, cost, audit, and workload monitoring
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
| Topic 9: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Design and implement scalable data models using Delta Lake
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
|
| Topic 10: Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
>> Certified-Data-Engineer-Professional Practice Test Online <<
Free Certified-Data-Engineer-Professional dumps torrent & Databricks Certified-Data-Engineer-Professional exam prep & Certified-Data-Engineer-Professional examcollection braindumps
Elaborately designed and developed Certified-Data-Engineer-Professional test guide as well as good learning support services are the key to assisting our customers to realize their dreams. Our Certified-Data-Engineer-Professional study braindumps have a variety of self-learning and self-assessment functions to detect learners’ study outcomes, and the statistical reporting function of our Certified-Data-Engineer-Professional test guide is designed for students to figure out their weaknesses and tackle the causes, thus seeking out specific methods dealing with them. Our Certified-Data-Engineer-Professional Exam Guide have also set a series of explanation about the complicated parts certificated by the syllabus and are based on the actual situation to stimulate exam circumstance in order to provide you a high-quality and high-efficiency user experience.
Databricks Certified Data Engineer Professional Sample Questions (Q186-Q191):
NEW QUESTION # 186
The Databricks workspace administrator has configured interactive clusters for each of the data engineering groups. To control costs, clusters are set to terminate after 30 minutes of inactivity.
Each user should be able to execute workloads against their assigned clusters at any time of the day.
Assuming users have been added to a workspace but not granted any permissions, which of the following describes the minimal permissions a user would need to start and attach to an already configured cluster.
- A. Workspace Admin privileges, cluster creation allowed. "Can Attach To" privileges on the required cluster
- B. "Can Restart" privileges on the required cluster
- C. Cluster creation allowed. "Can Attach To" privileges on the required cluster
- D. "Can Manage" privileges on the required cluster
- E. Cluster creation allowed. "Can Restart" privileges on the required cluster
Answer: B
Explanation:
https://learn.microsoft.com/en-us/azure/databricks/security/auth-authz/access-control/cluster-acl
https://docs.databricks.com/en/security/auth-authz/access-control/cluster-acl.html
NEW QUESTION # 187
A data engineer needs to provide access to a group named manufacturing-team. The team needs privileges to create tables in the quality schema. Which set of SQL commands will grant a group named manufacturing-team to create tables in a schema named production with the parent catalog named manufacturing with the least privileges?
- A. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- B. GRANT USE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- C. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- D. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
Answer: D
Explanation:
To create a table within a schema, a principal must have CREATE TABLE on the schema, USE SCHEMA on that schema, and USE CATALOG on the parent catalog. This combination ensures the group has just enough privileges to create objects in that schema without excessive permissions like CREATE SCHEMA or CREATE CATALOG.
NEW QUESTION # 188
The data engineering team maintains the following code:
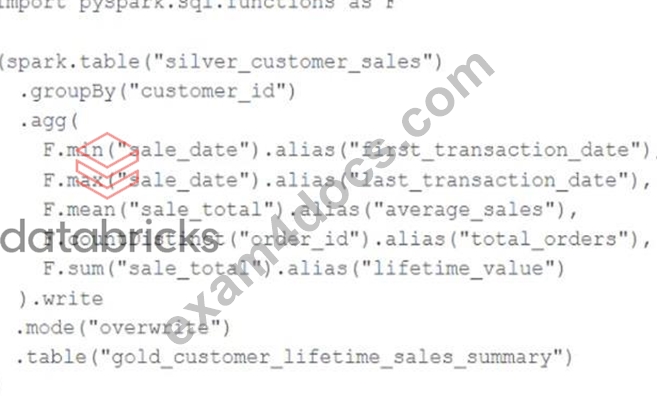
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. The gold_customer_lifetime_sales_summary table will be overwritten by aggregated values calculated from all records in the silver_customer_sales table as a batch job.
- B. A batch job will update the gold_customer_lifetime_sales_summary table, replacing only those rows that have different values than the current version of the table, using customer_id as the primary key.
- C. An incremental job will leverage running information in the state store to update aggregate values in the gold_customer_lifetime_sales_summary table.
- D. An incremental job will detect if new rows have been written to the silver_customer_sales table; if new rows are detected, all aggregates will be recalculated and used to overwrite the gold_customer_lifetime_sales_summary table.
- E. The silver_customer_sales table will be overwritten by aggregated values calculated from all records in the gold_customer_lifetime_sales_summary table as a batch job.
Answer: A
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids. The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed.
NEW QUESTION # 189
A Delta Lake table in the Lakehouse named customer_parsams is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
Immediately after each update succeeds, the data engineer team would like to determine the difference between the new version and the previous of the table. Given the current implementation, which method can be used?
- A. Execute DESCRIBE HISTORY customer_churn_params to obtain the full operation metrics for the update, including a log of all records that have been added or modified.
- B. Parse the Spark event logs to identify those rows that were updated, inserted, or deleted.
- C. Execute a query to calculate the difference between the new version and the previous version using Delta Lake's built-in versioning and time travel functionality.
- D. Parse the Delta Lake transaction log to identify all newly written data files.
Answer: C
Explanation:
Delta Lake provides built-in versioning and time travel capabilities, allowing users to query previous snapshots of a table. This feature is particularly useful for understanding changes between different versions of the table. In this scenario, where the table is overwritten nightly, you can use Delta Lake's time travel feature to execute a query comparing the latest version of the table (the current state) with its previous version. This approach effectively identifies the differences (such as new, updated, or deleted records) between the two versions. The other options do not provide a straightforward or efficient way to directly compare different versions of a Delta Lake table.
NEW QUESTION # 190
What statement is true regarding the retention of job run history?
- A. It is retained for 60 days, during which you can export notebook run results to HTML
- B. It is retained for 30 days, during which time you can deliver job run logs to DBFS or S3
- C. It is retained for 90 days or until the run-id is re-used through custom run configuration
- D. It is retained for 60 days, after which logs are archived
- E. It is retained until you export or delete job run logs
Answer: A
Explanation:
https://docs.databricks.com/en/workflows/jobs/monitor-job-runs.html
NEW QUESTION # 191
......
These real and updated Databricks Certified-Data-Engineer-Professional dumps are essential to pass the Certified-Data-Engineer-Professional exam on the first try. Don't waste further time and money, get real Databricks Certified-Data-Engineer-Professional pdf questions and practice test software, and start Certified-Data-Engineer-Professional Test Preparation today. Exam4Docs will also provide you with up to 365 days of free exam questions updates.
Certified-Data-Engineer-Professional New Dumps Ebook: https://www.exam4docs.com/Certified-Data-Engineer-Professional-study-questions.html
- Certified-Data-Engineer-Professional New APP Simulations 🔰 Certified-Data-Engineer-Professional New APP Simulations ☮ Certified-Data-Engineer-Professional Exam Sample Questions 🔟 ➽ www.practicevce.com 🢪 is best website to obtain ➡ Certified-Data-Engineer-Professional ️⬅️ for free download 🚺Practice Certified-Data-Engineer-Professional Test
- Databricks Certified-Data-Engineer-Professional Questions: Fosters Your Exam Passing Abilities [2026] 💋 Search on ➤ www.pdfvce.com ⮘ for ➡ Certified-Data-Engineer-Professional ️⬅️ to obtain exam materials for free download 🌷Latest Certified-Data-Engineer-Professional Test Materials
- www.prep4sures.top Certified-Data-Engineer-Professional: The Penetration Tester's Guide Test Engine 🦟 Open website ➡ www.prep4sures.top ️⬅️ and search for ☀ Certified-Data-Engineer-Professional ️☀️ for free download 🤨Reliable Certified-Data-Engineer-Professional Test Sims
- Exam Certified-Data-Engineer-Professional Simulations 🌰 Updated Certified-Data-Engineer-Professional Demo 📐 Certified-Data-Engineer-Professional Test Question 🐃 Search for 《 Certified-Data-Engineer-Professional 》 and download it for free immediately on 「 www.pdfvce.com 」 🥵Certified-Data-Engineer-Professional New APP Simulations
- Latest Certified-Data-Engineer-Professional Practice Test Online - Latest updated Certified-Data-Engineer-Professional New Dumps Ebook - Trustable Certification Certified-Data-Engineer-Professional Training 🐻 Download ⇛ Certified-Data-Engineer-Professional ⇚ for free by simply entering ➠ www.examdiscuss.com 🠰 website 🌁Certified-Data-Engineer-Professional Valid Test Vce Free
- Exam Certified-Data-Engineer-Professional Simulations 🤸 Latest Certified-Data-Engineer-Professional Test Materials 🔌 Certified-Data-Engineer-Professional Test Question ⭕ Simply search for 「 Certified-Data-Engineer-Professional 」 for free download on ➡ www.pdfvce.com ️⬅️ 🤷Certified-Data-Engineer-Professional Valid Exam Voucher
- Databricks Certified-Data-Engineer-Professional Questions: Fosters Your Exam Passing Abilities [2026] ❗ Immediately open ➤ www.troytecdumps.com ⮘ and search for ▶ Certified-Data-Engineer-Professional ◀ to obtain a free download 🕓Latest Certified-Data-Engineer-Professional Test Objectives
- Pass Guaranteed Quiz 2026 Certified-Data-Engineer-Professional: High-quality Databricks Certified Data Engineer Professional Practice Test Online 🍌 The page for free download of ( Certified-Data-Engineer-Professional ) on ➤ www.pdfvce.com ⮘ will open immediately 💯Updated Certified-Data-Engineer-Professional Demo
- Pass Guaranteed 2026 Authoritative Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Practice Test Online ⏫ Easily obtain free download of ➤ Certified-Data-Engineer-Professional ⮘ by searching on ⏩ www.practicevce.com ⏪ 🎷Certified-Data-Engineer-Professional New APP Simulations
- Certified-Data-Engineer-Professional New APP Simulations ⭐ Valid Certified-Data-Engineer-Professional Test Question 🏕 Certified-Data-Engineer-Professional Exam Objectives Pdf 🥠 Easily obtain [ Certified-Data-Engineer-Professional ] for free download through [ www.pdfvce.com ] 🚟Certified-Data-Engineer-Professional Valid Exam Voucher
- Certified-Data-Engineer-Professional Reliable Exam Dumps 🧺 Certified-Data-Engineer-Professional New APP Simulations 💛 Certified-Data-Engineer-Professional Valid Exam Voucher ♥ Easily obtain free download of ➠ Certified-Data-Engineer-Professional 🠰 by searching on ➥ www.validtorrent.com 🡄 ⚔Updated Certified-Data-Engineer-Professional Demo
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.blackhatprotools.info, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, forums.filatelija.lv, Disposable vapes