BONUS!!! Fast2test DP-600ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=172pxN2fw8KsWKiHmSqiwbnYkseJNege0
信頼できるDP-600の質問と回答は、その分野で豊富な経験を持つ専門家によって開発されました。 DP-600準備ガイドの絶え間ない更新により、試験問題の高い精度が維持されるため、DP-600試験をすばやく使用できます。試験中は、DP-600の質問と回答で練習した質問に精通しています。また、DP-600試験問題は非常に正確で有効であるため、合格率は99%〜100%です。それが、ほとんどのお客様が常にDP-600試験に簡単に合格する理由です。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
Fast2testはこの分野のリーダーであり、DP-600学習ガイドの高い合格率で有名です。認定試験に頭痛の種がある場合は、DP-600学習ガイドの資料が優れた救世主になります。 100%合格率の最も有効でプロフェッショナルなDP-600学習ガイド資料を提供するのは今がチャンスです。一度試験をクリアして成功を収めたい場合は、私たちを選ぶことが賢明です。あなたが私たちについてするならば、私たちの満足のいくサービスと高品質のDP-600ガイド急流について以下に注意を払ってください。
質問 # 198
You have a Microsoft Power Bl report named Report1 that uses a Fabric semantic model.
Users discover that Report1 renders slowly.
You open Performance analyzer and identify that a visual named Orders By Date is the slowest to render. The duration breakdown for Orders By Date is shown in the following table.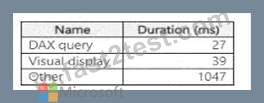
What will provide the greatest reduction in the rendering duration of Report1?
正解:A
解説:
Based on the duration breakdown provided, the major contributor to the rendering duration is categorized as
"Other," which is significantly higher than DAX Query and Visual display times. This suggests that the issue is less likely with the DAX calculation or visual rendering times and more likely related to model performance or the complexity of the visual. However, of the options provided, optimizing the DAX query can be a crucial step, even if "Other" factors are dominant. Using DAX Studio, you can analyze and optimize the DAX queries that power your visuals for performance improvements. Here's how you might proceed:
* Open DAX Studio and connect it to your Power BI report.
* Capture the DAX query generated by the Orders By Date visual.
* Use the Performance Analyzer feature within DAX Studio to analyze the query.
* Look for inefficiencies or long-running operations.
* Optimize the DAX query by simplifying measures, removing unnecessary calculations, or improving iterator functions.
* Test the optimized query to ensure it reduces the overall duration.
References: The use of DAX Studio for query optimization is a common best practice for improving Power BI report performance as outlined in the Power BI documentation.
質問 # 199
You have a Fabric tenant that contains a semantic model named Model1. Model1 uses Import mode. Model1 contains a table named Orders. Orders has 100 million rows and the following fields.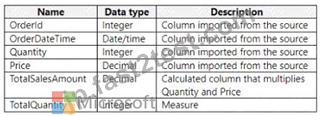
You need to reduce the memory used by Model! and the time it takes to refresh the model. Which two actions should you perform? Each correct answer presents part of the solution. NOTE: Each correct answer is worth one point.
正解:A、C
解説:
To reduce memory usage and refresh time, splitting the OrderDateTime into separate date and time columns (A) can help optimize the model because date/time data types can be more memory-intensive than separate date and time columns. Moreover, replacing TotalSalesAmount with a measure (D) instead of a calculated column ensures that the calculation is performed at query time, which can reduce the size of the model as the value is not stored but calculated on the fly. References = The best practices for optimizing Power BI models are detailed in the Power BI documentation, which recommends using measures for calculations that don't need to be stored and adjusting data types to improve performance.
質問 # 200
You have an Azure Data Lake Storage Gen2 account named storage! that contains a Parquet file named sales.
parquet.
You have a Fabric tenant that contains a workspace named Workspace1.
Using a notebook in Workspace1, you need to load the content of the file to the default lakehouse. The solution must ensure that the content will display automatically as a table named Sales in Lakehouse explorer.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.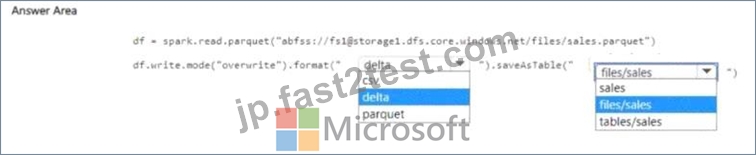
正解:
解説: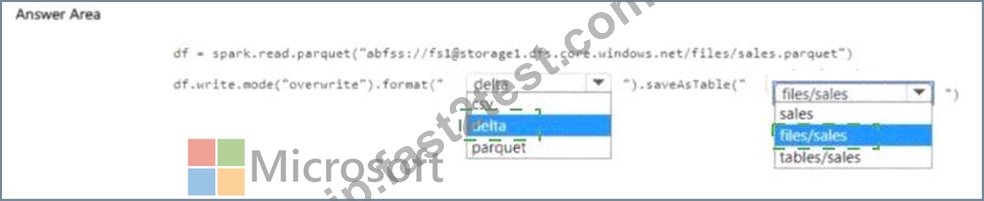
Explanation: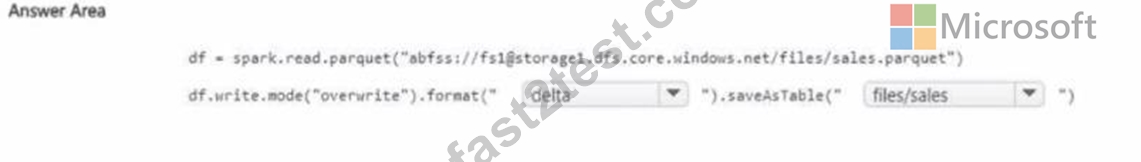
Step 1 - Read the Parquet file into a DataFrame
df = spark.read.parquet("abfss://fs1@storage1.dfs.core.windows.net/files/sales.parquet") This correctly loads the Parquet data into Spark.
Step 2 - Write into the Lakehouse as a managed table
If we want the result to be registered as a Lakehouse table and automatically appear in Lakehouse Explorer, we must:
Write the data in delta format (because Fabric Lakehouse tables are Delta tables).
Save the table under the tables folder, not files.
So the correct code is:
df.write.mode("overwrite").format("delta").saveAsTable("tables/sales")
Final Answer:
Format: delta
SaveAsTable Path: tables/sales
References:
Lakehouse tables in Microsoft Fabric
Save DataFrame as Delta Table in Spark
# Answer Selection:
First dropdown # delta
Second dropdown # tables/sales
質問 # 201
You have a Fabric tenant that contains a Microsoft Power Bl report named Report 1. Report1 includes a Python visual. Data displayed by the visual is grouped automatically and duplicate rows are NOT displayed. You need all rows to appear in the visual. What should you do?
正解:C
解説:
To ensure all rows appear in the Python visual within a Power BI report, option C, adding a unique field to each row, is the correct solution. This will prevent automatic grouping by unique values and allow for all instances of data to be represented in the visual. Reference = For more on Power BI Python visuals and how they handle data, please refer to the Power BI documentation.
質問 # 202
You have a Fabric tenant that contains a workspace named Workspace1. Workspace1 contains a lakehouse named Lakehouse1 and a warehouse named Warehouse1.
You need to create a new table in Warehouse1 named POSCustomers by querying the customer table in Lakehouse1.
How should you complete the T-SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.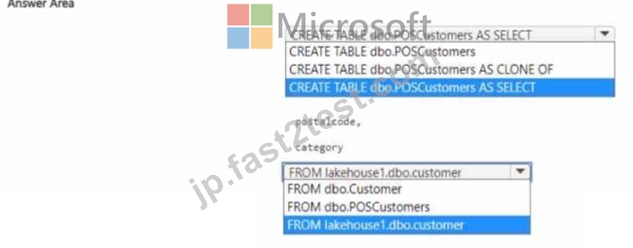
正解:
解説: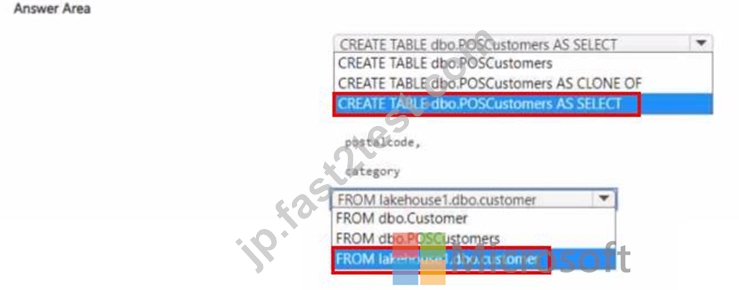
質問 # 203
......
DP-600試験はFast2testの教材を準備し、高品質で合格率が高く、実際のDP-600試験を十分に理解しており、DP-600学習教材を長年にわたって作成した専門家によって完了します。彼らは、DP-600試験の準備をするときに受験者が本当に必要とするものを非常によく知っています。また、実際のDP-600試験の状況を非常によく理解しています。実際の試験がどのようなものかをお知らせします。DP-600試験問題のソフトバージョンを試すことができます。これにより、実際の試験をシミュレートできます。
DP-600模擬問題集: https://jp.fast2test.com/DP-600-premium-file.html
無料でクラウドストレージから最新のFast2test DP-600 PDFダンプをダウンロードする:https://drive.google.com/open?id=172pxN2fw8KsWKiHmSqiwbnYkseJNege0