P.S. Free 2026 Amazon Data-Engineer-Associate dumps are available on Google Drive shared by ExamDumpsVCE: https://drive.google.com/open?id=1HqByPgFLICD_5kVLKfXUFJiTAFW2eCFa
So, do not ignore the significance of Amazon Data-Engineer-Associate practice exams. Take our Amazon Data-Engineer-Associate practice exams again and again till you are confident that you can nail the final Data-Engineer-Associate Certification test on the first chance. It is beneficial for our customers to download Amazon Data-Engineer-Associate dumps demo free of cost before buying.
| Section | Weight | Objectives |
|---|---|---|
| Data Operations and Support | 22% | - Monitor and maintain data pipelines - Troubleshoot data workflow issues |
| Data Ingestion and Transformation | 34% | - Ingest and transform data using AWS services - Build and manage data pipelines |
| Data Store Management | 26% | - Optimize storage performance and cost - Select appropriate data storage solutions |
| Data Security and Governance | 18% | - Implement data security controls - Apply governance and compliance best practices |
>> Data-Engineer-Associate Reliable Exam Simulator <<
Never stop challenging your limitations. If you want to dig out your potentials, just keep trying. Repeated attempts will sharpen your minds. Maybe our Data-Engineer-Associate learning quiz is suitable for you. We strongly advise you to have a brave attempt. You will own a wonderful experience after you learning our Data-Engineer-Associate Guide practice. As the leader in this career, we have been considered as the most popular exam materials provider. And our Data-Engineer-Associate practice questions will bring you 100% success on your exam.
NEW QUESTION # 223
A company plans to use Amazon Kinesis Data Firehose to store data in Amazon S3. The source data consists of 2 MB csv files. The company must convert the .csv files to JSON format. The company must store the files in Apache Parquet format.
Which solution will meet these requirements with the LEAST development effort?
Answer: D
Explanation:
The company wants to use Amazon Kinesis Data Firehose to transform CSV files into JSON format and store the files in Apache Parquet format with the least development effort.
Option B: Use Kinesis Data Firehose to convert the CSV files to JSON and to store the files in Parquet format.
Kinesis Data Firehose supports data format conversion natively, including converting incoming CSV data to JSON format and storing the resulting files in Parquet format in Amazon S3. This solution requires the least development effort because it uses built-in transformation features of Kinesis Data Firehose.
Other options (A, C, D) involve invoking AWS Lambda functions, which would introduce additional complexity and development effort compared to Kinesis Data Firehose's native format conversion capabilities.
References:
Amazon Kinesis Data Firehose Documentation
NEW QUESTION # 224
A company needs to load customer data that comes from a third party into an Amazon Redshift data warehouse. The company stores order data and product data in the same data warehouse. The company wants to use the combined dataset to identify potential new customers.
A data engineer notices that one of the fields in the source data includes values that are in JSON format.
How should the data engineer load the JSON data into the data warehouse with the LEAST effort?
Answer: C
Explanation:
In Amazon Redshift, the SUPER data type is designed specifically to handle semi-structured data like JSON, Parquet, ORC, and others. By using the SUPER data type, Redshift can ingest and query JSON data without requiring complex data flattening processes, thus reducing the amount of preprocessing required before loading the data. The SUPER data type also works seamlessly with Redshift Spectrum, enabling complex queries that can combine both structured and semi-structured datasets, which aligns with the company's need to use combined datasets to identify potential new customers.
Using the SUPER data type also allows for automatic parsing and query processing of nested data structures through Amazon Redshift's PARTITION BY and JSONPATH expressions, which makes this option the most efficient approach with the least effort involved. This reduces the overhead associated with using tools like AWS Glue or Lambda for data transformation.
Reference:
Amazon Redshift Documentation - SUPER Data Type
AWS Certified Data Engineer - Associate Training: Building Batch Data Analytics Solutions on AWS AWS Certified Data Engineer - Associate Study Guide By directly leveraging the capabilities of Redshift with the SUPER data type, the data engineer ensures streamlined JSON ingestion with minimal effort while maintaining query efficiency.
NEW QUESTION # 225
A company uses Amazon RDS for MySQL as the database for a critical application. The database workload is mostly writes, with a small number of reads.
A data engineer notices that the CPU utilization of the DB instance is very high. The high CPU utilization is slowing down the application. The data engineer must reduce the CPU utilization of the DB Instance.
Which actions should the data engineer take to meet this requirement? (Choose two.)
Answer: A,D
Explanation:
Amazon RDS is a fully managed service that provides relational databases in the cloud. Amazon RDS for MySQL is one of the supported database engines that you can use to run your applications. Amazon RDS provides various features and tools to monitor and optimize the performance of your DB instances, such as Performance Insights, Enhanced Monitoring, CloudWatch metrics and alarms, etc.
Using the Performance Insights feature of Amazon RDS to identify queries that have high CPU utilization and optimizing the problematic queries will help reduce the CPU utilization of the DB instance. Performance Insights is a feature that allows you to analyze the load on your DB instance and determine what is causing performance issues. Performance Insights collects, analyzes, and displays database performance data using an interactive dashboard. You can use Performance Insights to identify the top SQL statements, hosts, users, or processes that are consuming the most CPU resources. You can also drill down into the details of each query and see the execution plan, wait events, locks, etc. By using Performance Insights, you can pinpoint the root cause of the high CPU utilization and optimize the queries accordingly. For example, you can rewrite the queries to make them more efficient, add or remove indexes, use prepared statements, etc.
Implementing caching to reduce the database query load will also help reduce the CPU utilization of the DB instance. Caching is a technique that allows you to store frequently accessed data in a fast and scalable storage layer, such as Amazon ElastiCache. By using caching, you can reduce the number of requests that hit your database, which in turn reduces the CPU load on your DB instance. Caching also improves the performance and availability of your application, as it reduces the latency and increases the throughput of your data access.
You can use caching for various scenarios, such as storing session data, user preferences, application configuration, etc. You can also use caching for read-heavy workloads, such as displaying product details, recommendations, reviews, etc.
The other options are not as effective as using Performance Insights and caching. Modifying the database schema to include additional tables and indexes may or may not improve the CPU utilization, depending on the nature of the workload and the queries. Adding more tables and indexes may increase the complexity and overhead of the database, which may negatively affect the performance. Rebooting the RDS DB instance once each week will not reduce the CPU utilization, as it will not address the underlying cause of the high CPU load. Rebooting may also cause downtime and disruption to your application. Upgrading to a larger instance size may reduce the CPUutilization, but it will also increase the cost and complexity of your solution.
Upgrading may also not be necessary if you can optimize the queries and reduce the database load by using caching. References:
Amazon RDS
Performance Insights
Amazon ElastiCache
[AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide], Chapter 3: Data Storage and Management, Section 3.1: Amazon RDS
NEW QUESTION # 226
A data engineer needs to create an Amazon Athena table based on a subset of data from an existing Athena table named cities_world. The cities_world table contains cities that are located around the world. The data engineer must create a new table named cities_us to contain only the cities from cities_world that are located in the US.
Which SQL statement should the data engineer use to meet this requirement?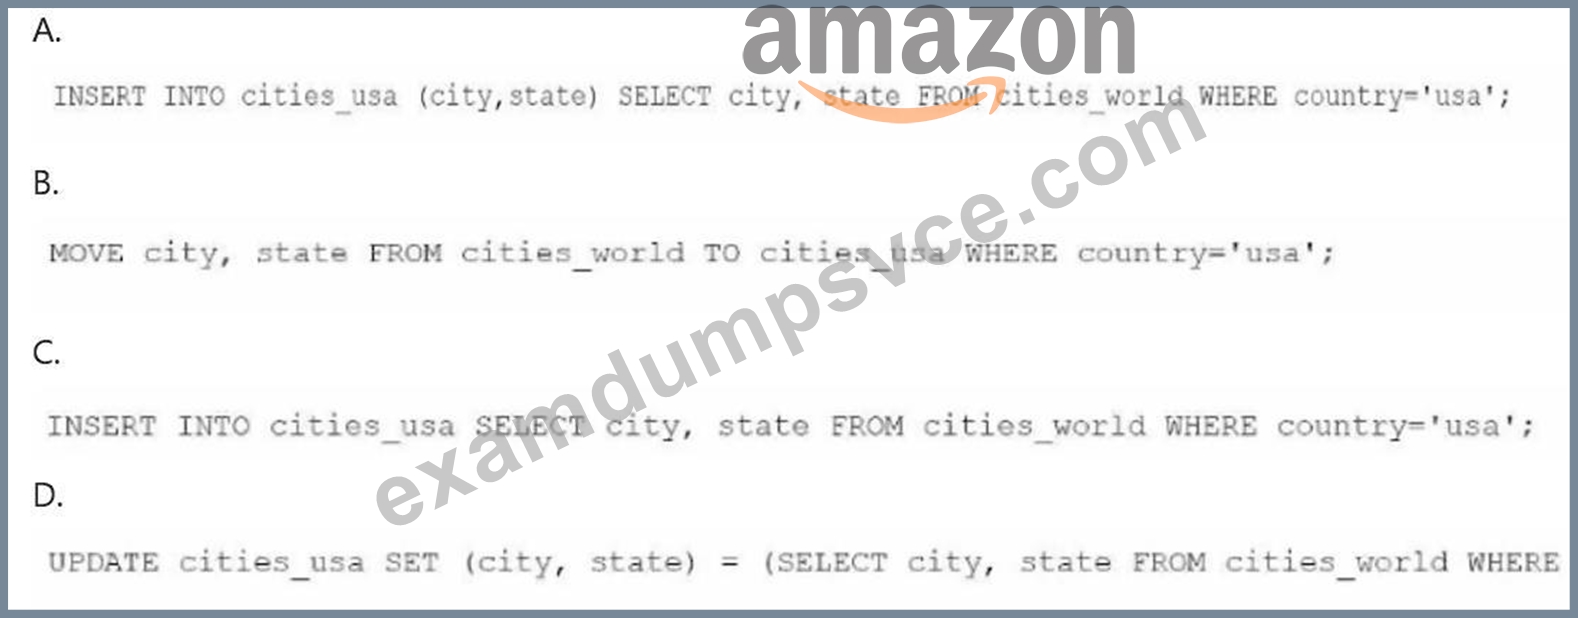
Answer: C
Explanation:
To create a new table named cities_usa in Amazon Athena based on a subset of data from the existing cities_world table, you should use anINSERT INTOstatement combined with aSELECTstatement to filter only the records where the country is 'usa'. The correct SQL syntax would be:
* Option A: INSERT INTO cities_usa (city, state) SELECT city, state FROM cities_world WHERE country='usa';This statement inserts only the cities and states where the country column has a value of
'usa' from the cities_world table into the cities_usa table. This is a correct approach to create a new table with data filtered from an existing table in Athena.
Options B, C, and Dare incorrect due to syntax errors or incorrect SQL usage (e.g., the MOVE command or the use of UPDATE in a non-relevant context).
References:
Amazon Athena SQL Reference
Creating Tables in Athena
NEW QUESTION # 227
A company uses an Amazon Redshift provisioned cluster as its database. The Redshift cluster has five reserved ra3.4xlarge nodes and uses key distribution.
A data engineer notices that one of the nodes frequently has a CPU load over 90%. SQL Queries that run on the node are queued. The other four nodes usually have a CPU load under 15% during daily operations.
The data engineer wants to maintain the current number of compute nodes. The data engineer also wants to balance the load more evenly across all five compute nodes.
Which solution will meet these requirements?
Answer: A
Explanation:
Changing the distribution key to the table column that has the largest dimension will help to balance the load more evenly across all five compute nodes. The distribution key determines how the rows of a table are distributed among the slices of the cluster. If the distribution key is not chosen wisely, it can cause data skew, meaning some slices will have more data than others, resulting in uneven CPU load and query performance.
By choosing the table column that has the largest dimension, meaning the column that has the most distinct values, as the distribution key, the data engineer can ensure that the rows are distributed more uniformly across the slices, reducing data skew and improving query performance.
The other options are not solutions that will meet the requirements. Option A, changing the sort key to be the data column that is most often used in a WHERE clause of the SQL SELECT statement, will not affect the data distribution or the CPU load. The sort key determines the order in which the rows of a table are stored on disk, which can improve the performance of range-restricted queries, but not the load balancing. Option C, upgrading the reserved node from ra3.4xlarge to ra3.16xlarge, will not maintain the current number of compute nodes, as it will increase the cost and the capacity of the cluster. Option D, changing the primary key to be the data column that is most often used in a WHERE clause of the SQL SELECT statement, will not affect the data distribution or the CPU load either. The primary key is a constraint that enforces the uniqueness of the rows in a table, but it does not influence the data layout or the query optimization. References:
Choosing a data distribution style
Choosing a data sort key
Working with primary keys
NEW QUESTION # 228
......
We believe that the greatest value of Data-Engineer-Associate study materials lies in whether it can help candidates pass the examination, other problems are secondary. And at this point, our Data-Engineer-Associate study materials do very well. We can proudly tell you that the passing rate of our Data-Engineer-Associate Study Materials is close to 100 %. That is to say, almost all the students who choose our products can finally pass the exam. We are not exaggerating because this conclusion comes from previous statistics.
Data-Engineer-Associate Test Torrent: https://www.examdumpsvce.com/Data-Engineer-Associate-valid-exam-dumps.html
BONUS!!! Download part of ExamDumpsVCE Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1HqByPgFLICD_5kVLKfXUFJiTAFW2eCFa