What's more, part of that PrepAwayExam DP-100 dumps now are free: https://drive.google.com/open?id=1wFqeyeEwgZxSGpKir0YnPy9E7J7Q8adg
Cracking the DP-100 examination requires smart, not hard work. You just have to study with valid and accurate Microsoft DP-100 practice material that is according to sections of the present Microsoft DP-100 Exam content. PrepAwayExam offers you the best Microsoft DP-100 Exam Dumps in the market that assures success on the first try.
| Section | Objectives |
|---|---|
| Topic 1: Design and prepare a machine learning solution | - Plan and configure Azure Machine Learning workspace - Select appropriate Azure services for machine learning workloads - Manage compute and data assets |
| Topic 2: Train machine learning models | - Train models using Azure Machine Learning - Tune hyperparameters and evaluate models |
| Topic 3: Deploy and consume models | - Monitor deployed models and endpoints - Deploy models to endpoints |
| Topic 4: Explore and analyze data | - Perform exploratory data analysis - Ingest and prepare data for modeling |
| Topic 5: Optimize and manage models | - Track experiments and manage model lifecycle - Improve model performance |
>> Guaranteed DP-100 Passing <<
In accordance with the actual exam, we provide the latest DP-100 exam dumps for your practices. With the latest DP-100 test questions, you can have a good experience in practicing the test. Moreover, you have no need to worry about the price, we provide free updating for one year and half price for further partnerships, which is really a big sale in this field. After your payment, we will send the updated DP-100 Exam to you immediately and if you have any question about updating, please leave us a message.
NEW QUESTION # 80
You create a batch inference pipeline by using the Azure ML SDK. You run the pipeline by using the following code:
from azureml.pipeline.core import Pipeline
from azureml.core.experiment import Experiment
pipeline = Pipeline(workspace=ws, steps=[parallelrun_step])
pipeline_run = Experiment(ws, 'batch_pipeline').submit(pipeline)
You need to monitor the progress of the pipeline execution.
What are two possible ways to achieve this goal? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.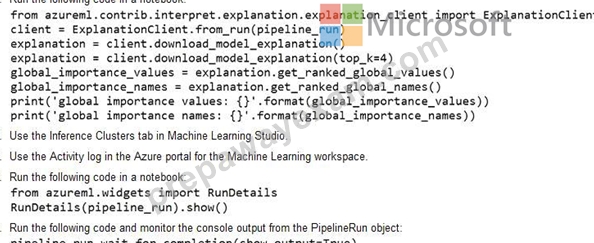
Answer: A,B
Explanation:
Explanation
A batch inference job can take a long time to finish. This example monitors progress by using a Jupyter widget. You can also manage the job's progress by using:
Azure Machine Learning Studio.
Console output from the PipelineRun object.
from azureml.widgets import RunDetails
RunDetails(pipeline_run).show()
pipeline_run.wait_for_completion(show_output=True)
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-use-parallel-run-step#monitor-the-parallel-run-
NEW QUESTION # 81
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You create an Azure Machine Learning service datastore in a workspace. The datastore contains the following files:
* /data/2018/Q1 .csv
* /data/2018/Q2.csv
* /data/2018/Q3.csv
* /data/2018/Q4.csv
* /data/2019/Q1.csv
All files store data in the following format:
id,f1,f2,l
1,1,2,0
2,1,1,1
3.2.1.0
You run the following code: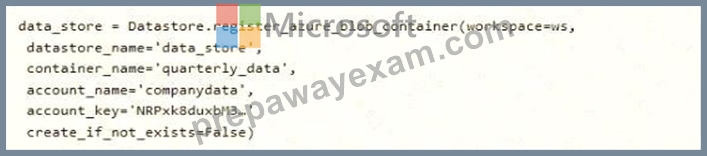
You need to create a dataset named training_data and load the data from all files into a single data frame by using the following code:
Solution: Run the following code: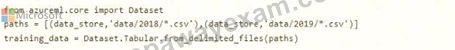
Does the solution meet the goal?
Answer: A
Explanation:
Use two file paths.
Use Dataset.Tabular_from_delimeted as the data isn't cleansed.
Note:
A TabularDataset represents data in a tabular format by parsing the provided file or list of files. This provides you with the ability to materialize the data into a pandas or Spark DataFrame so you can work with familiar data preparation and training libraries without having to leave your notebook. You can create a TabularDataset object from .csv, .tsv, .parquet, .jsonl files, and from SQL query results.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-create-register-datasets
NEW QUESTION # 82
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You train a classification model by using a logistic regression algorithm.
You must be able to explain the model's predictions by calculating the importance of each feature, both as an overall global relative importance value and as a measure of local importance for a specific set of predictions.
You need to create an explainer that you can use to retrieve the required global and local feature importance values.
Solution: Create a TabularExplainer.
Does the solution meet the goal?
Answer: B
Explanation:
Instead use Permutation Feature Importance Explainer (PFI).
Note 1: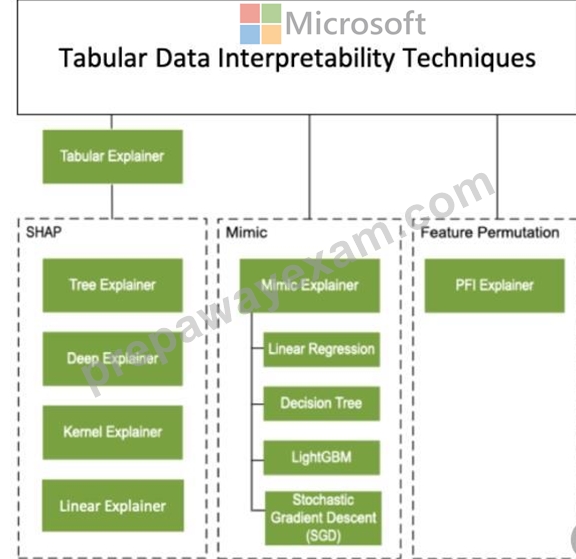
Note 2: Permutation Feature Importance Explainer (PFI): Permutation Feature Importance is a technique used to explain classification and regression models. At a high level, the way it works is by randomly shuffling data one feature at a time for the entire dataset and calculating how much the performance metric of interest changes. The larger the change, the more important that feature is. PFI can explain the overall behavior of any underlying model but does not explain individual predictions.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-machine-learning-interpretability
NEW QUESTION # 83
You are analyzing the asymmetry in a statistical distribution.
The following image contains two density curves that show the probability distribution of two datasets.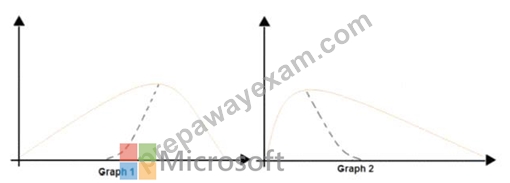
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.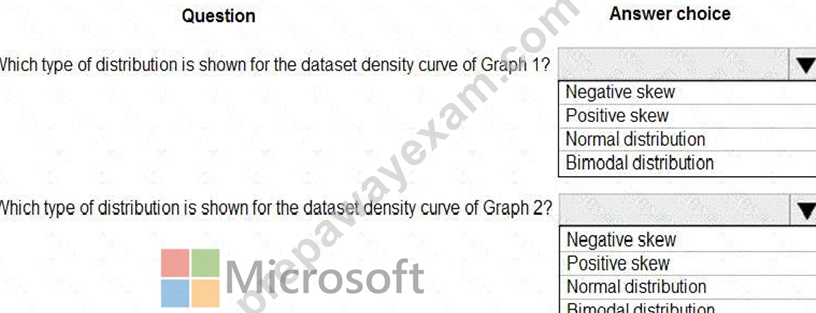
Answer:
Explanation: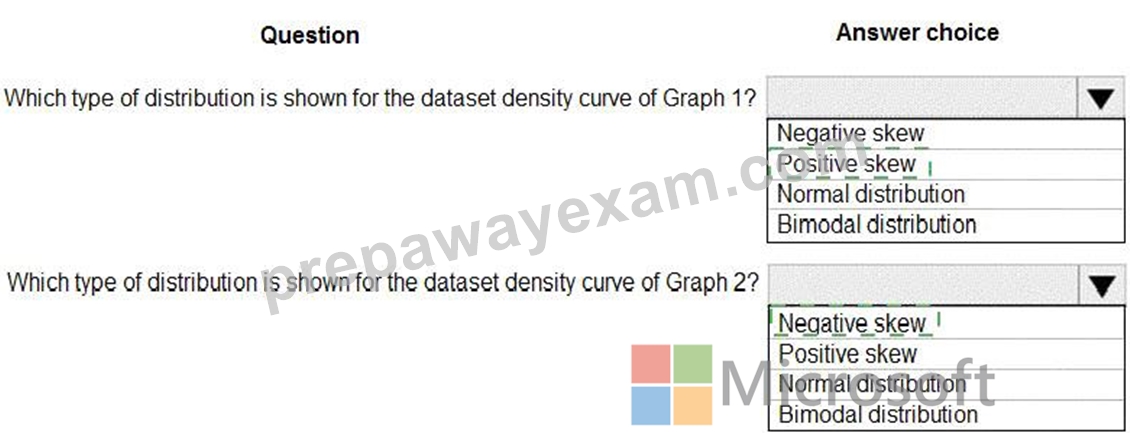
Explanation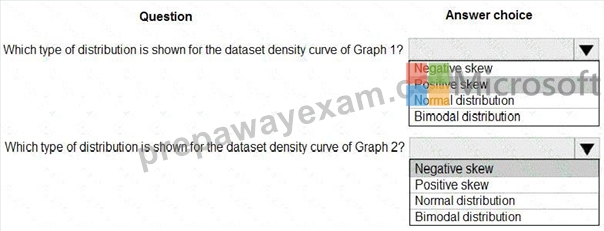
Box 1: Positive skew
Positive skew values means the distribution is skewed to the right.
Box 2: Negative skew
Negative skewness values mean the distribution is skewed to the left.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/compute-elementary-statistics
NEW QUESTION # 84
You use Azure Machine Learning to train and register a model.
You must deploy the model into production as a real-time web service to an inference cluster named service-compute that the IT department has created in the Azure Machine Learning workspace.
Client applications consuming the deployed web service must be authenticated based on their Azure Active Directory service principal.
You need to write a script that uses the Azure Machine Learning SDK to deploy the model. The necessary modules have been imported.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.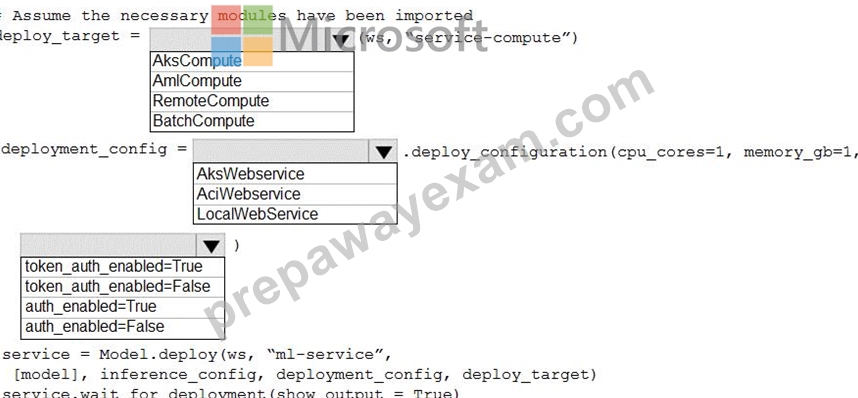
Answer:
Explanation: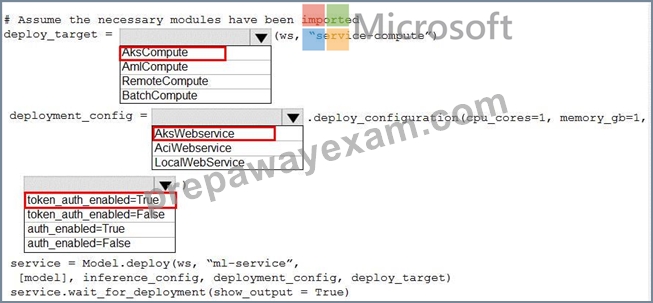
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-deploy-azure-kubernetes-service
https://docs.microsoft.com/en-us/azure/databricks/dev-tools/api/latest/aad/service-prin-aad-token
NEW QUESTION # 85
......
As we all know, a good DP-100 Exam Torrent can win the support and fond of the customers, DP-100 exam dumps of are just the product like this. With high pass rate and high quality, we have received good reputation in different countries in the world. We are a professional enterprise in this field, with rich experience and professional spirits, we have help many candidates pass the exam. What’s more, the free update is also provided.
DP-100 Latest Braindumps Ebook: https://www.prepawayexam.com/Microsoft/braindumps.DP-100.ete.file.html
P.S. Free 2026 Microsoft DP-100 dumps are available on Google Drive shared by PrepAwayExam: https://drive.google.com/open?id=1wFqeyeEwgZxSGpKir0YnPy9E7J7Q8adg