P.S. Free & New DP-600 dumps are available on Google Drive shared by ITExamDownload: https://drive.google.com/open?id=1AjcWCvFB6EBMcbHSlqoE_BUMcoYE55Rj
To attempt the Microsoft DP-600 exam optimally and ace it on the first attempt, proper exam planning is crucial. Since the Microsoft DP-600 exam demands a lot of time and effort, we designed the Implementing Analytics Solutions Using Microsoft Fabric (DP-600) exam dumps in such a way that you won't have to go through sleepless study nights or disturb your schedule. Before starting the Microsoft DP-600 Preparation, plan the amount of time you will allot to each topic, determine the topics that demand more effort and prioritize the components that possess more weightage in the Microsoft DP-600 exam.
| Section | Objectives |
|---|---|
| Topic 1: Implement analytics solutions | - Data warehousing and modeling
|
| Topic 2: Implement data engineering solutions | - Lakehouse architecture
|
| Topic 3: Get data into Microsoft Fabric | - Data ingestion and integration
|
| Topic 4: Real-time analytics | - Streaming and event processing
|
| Topic 5: Manage and secure Microsoft Fabric | - Governance and administration
|
ITExamDownload DP-600 exam braindumps is valid and cost-effective, which is the right resource you are looking for. What you get from the DP-600 practice torrent is not only just passing with high scores, but also enlarging your perspective and enriching your future. From the DP-600 free demo, you will have an overview about the complete exam dumps. The comprehensive questions together with correct answers are the guarantee for 100% pass.
NEW QUESTION # 69
You have a Fabric workspace that contains a Dataflow Gen2 query. The query returns the following data.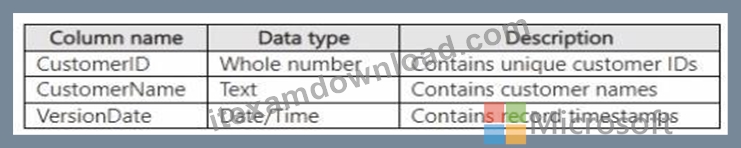
You need to filter the results to ensure that only the latest version of each customer's record is retained. The solution must ensure that no new columns are loaded to the semantic model.
Which four actions should you perform in sequence in Power Query Editor? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.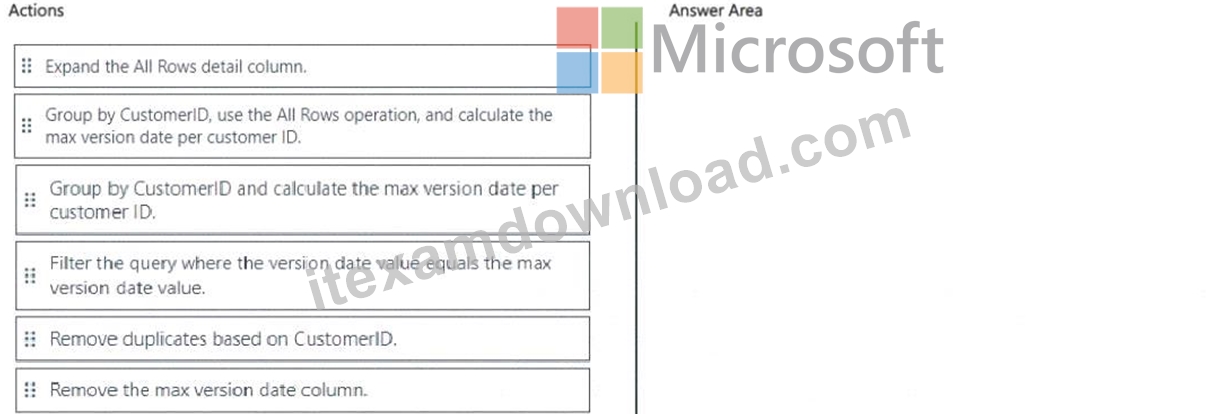
Answer:
Explanation: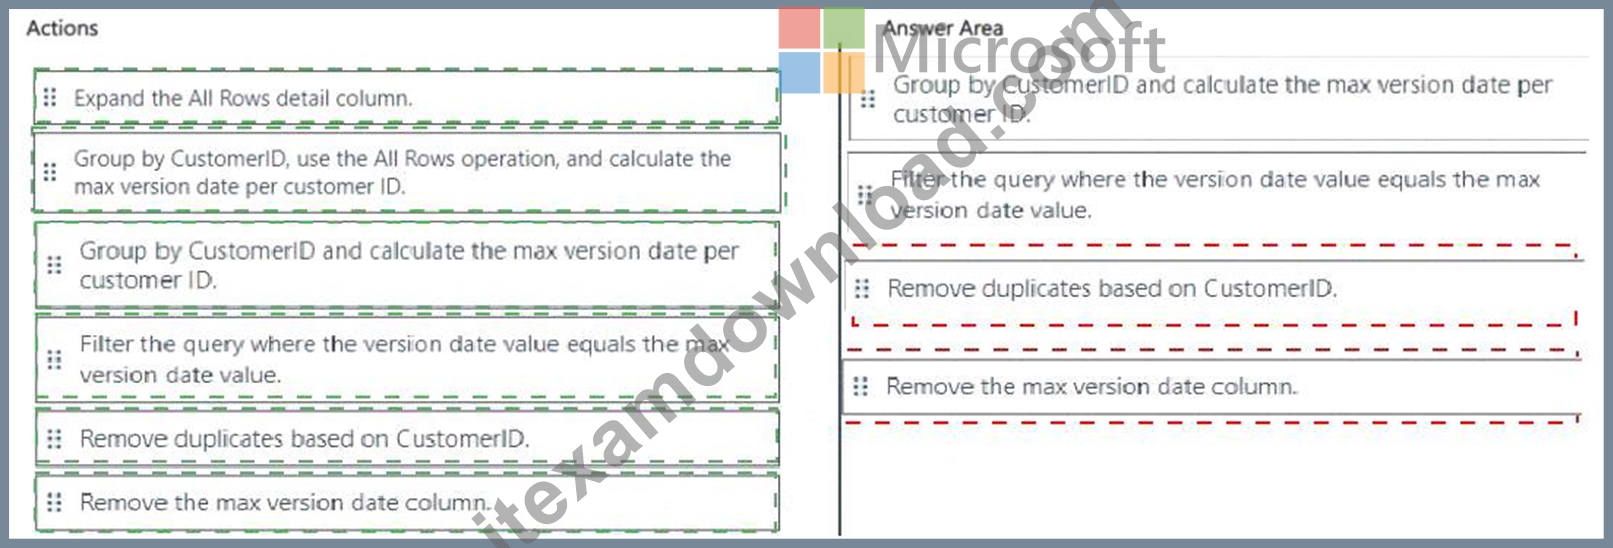
Explanation: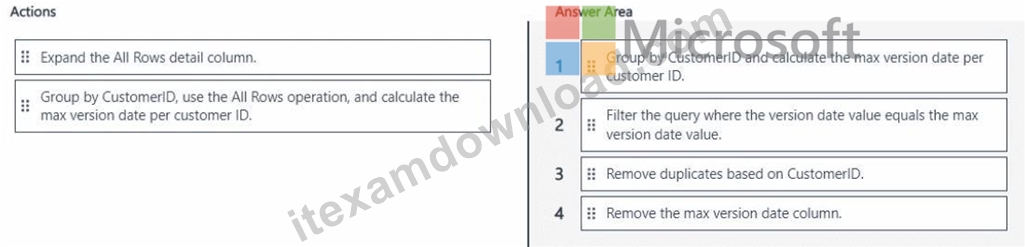
Comprehensive Detailed Explanation
We have a table with:
CustomerID # unique ID
CustomerName # customer's name
VersionDate # timestamp representing version history
The requirement:
Keep only the latest record per customer.
Ensure no new technical columns (like max version date) remain in the semantic model.
Step 1: Identify latest version per customer
We need to determine the latest VersionDate for each CustomerID.
Use Group By CustomerID and calculate Max of VersionDate.
This creates a mapping of CustomerID # latest VersionDate.
Step 2: Filter to keep only latest records
Join or filter original data so that only rows with VersionDate = Max(VersionDate) are retained.
This ensures that only the most recent record is kept per customer.
Step 3: Remove the helper column
The column holding Max VersionDate is only needed for filtering.
It must be removed because the requirement is that no new columns are loaded to the semantic model.
Step 4: Remove duplicates
As a final safeguard, remove duplicates by CustomerID, ensuring that each customer appears only once.
Final Ordered Actions
Group by CustomerID and calculate the max version date per customer ID.
Filter the query where the version date value equals the max version date value.
Remove the max version date column.
Remove duplicates based on CustomerID.
NEW QUESTION # 70
You have a Fabric tenant named Tenant! that contains a lakehouse named Lakehouse1.
You need to add data to Lakehouse1 from a CSV file in an Azure Storage account outside of Fabric. The solution must minimize development effort.
What should you use to add the data?
Answer: B
Explanation:
Comprehensive Detailed Explanation
Requirement
Tenant: Fabric tenant Tenant1
Data target: Lakehouse1
Data source: CSV file in an Azure Storage account (outside of Fabric)
Requirement: Minimize development effort
Step 1: Understand options
A). Dataflow Gen2
Used for ETL (transformations, cleansing, ingestion).
More effort because you need to build Power Query transformations.
Not minimal effort for simply exposing a file.
B). Shortcut
Fabric supports creating shortcuts to external data sources (OneLake, ADLS Gen2, Azure Blob, Dataverse, etc.).
Shortcut directly exposes external files/tables inside the lakehouse without copying or moving data.
This is the lowest-effort solution to access external CSV.
C). Copy job
Pipelines have a copy activity to physically copy data into Fabric.
Requires setup and execution. More development effort than a shortcut.
D). Pipeline
Used for orchestrating complex ETL workflows.
Overhead for this scenario.
Step 2: Correct Answer
Since the goal is simply to access a CSV in external storage with minimal development effort, the right solution is:
B). a shortcut
References
Shortcuts in Microsoft Fabric OneLake
Dataflow Gen2 overview
NEW QUESTION # 71
Case Study 1 - Contoso
Overview
Contoso, Ltd. is a US-based health supplements company. Contoso has two divisions named Sales and Research. The Sales division contains two departments named Online Sales and Retail Sales. The Research division assigns internally developed product lines to individual teams of researchers and analysts.
Existing Environment
Identity Environment
Contoso has a Microsoft Entra tenant named contoso.com. The tenant contains two groups named ResearchReviewersGroup1 and ResearchReviewersGroup2.
Data Environment
Contoso has the following data environment:
- The Sales division uses a Microsoft Power BI Premium capacity.
- The semantic model of the Online Sales department includes a fact table named Orders that uses Import made. In the system of origin, the OrderID value represents the sequence in which orders are created.
- The Research department uses an on-premises, third-party data warehousing product.
- Fabric is enabled for contoso.com.
- An Azure Data Lake Storage Gen2 storage account named storage1 contains Research division data for a product line named Productline1. - The data is in the delta format.
- A Data Lake Storage Gen2 storage account named storage2 contains Research division data for a product line named Productline2. The data is in the CSV format.
Requirements
Planned Changes
Contoso plans to make the following changes:
- Enable support for Fabric in the Power BI Premium capacity used by the Sales division.
- Make all the data for the Sales division and the Research division available in Fabric.
- For the Research division, create two Fabric workspaces named Productline1ws and Productine2ws.
- In Productline1ws, create a lakehouse named Lakehouse1.
- In Lakehouse1, create a shortcut to storage1 named ResearchProduct.
Data Analytics Requirements
Contoso identifies the following data analytics requirements:
- All the workspaces for the Sales division and the Research division must support all Fabric experiences.
- The Research division workspaces must use a dedicated, on-demand capacity that has per- minute billing.
- The Research division workspaces must be grouped together logically to support OneLake data hub filtering based on the department name.
- For the Research division workspaces, the members of ResearchReviewersGroup1 must be able to read lakehouse and warehouse data and shortcuts by using SQL endpoints.
- For the Research division workspaces, the members of ResearchReviewersGroup2 must be able to read lakehouse data by using Lakehouse explorer.
- All the semantic models and reports for the Research division must use version control that supports branching.
Data Preparation Requirements
Contoso identifies the following data preparation requirements:
- The Research division data for Productline1 must be retrieved from Lakehouse1 by using Fabric notebooks.
- All the Research division data in the lakehouses must be presented as managed tables in Lakehouse explorer.
Semantic Model Requirements
Contoso identifies the following requirements for implementing and managing semantic models:
- The number of rows added to the Orders table during refreshes must be minimized.
- The semantic models in the Research division workspaces must use Direct Lake mode.
General Requirements
Contoso identifies the following high-level requirements that must be considered for all solutions:
- Follow the principle of least privilege when applicable.
- Minimize implementation and maintenance effort when possible.
You need to refresh the Orders table of the Online Sales department. The solution must meet the semantic model requirements.
What should you include in the solution?
Answer: A
Explanation:
We need to retrieve the maximum OrderID in the destination table to minimize the number of rows added during refresh. this would be an incremental load. can be done with data flows.
NEW QUESTION # 72
You have a Fabric tenant that contains a lakehouse named Lakehouse1. Lakehouse1 contains a table named Nyctaxi_raw. Nyctaxi_raw contains the following columns.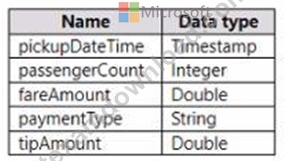
You create a Fabric notebook and attach it to lakehouse1.
You need to use PySpark code to transform the data. The solution must meet the following requirements:
* Add a column named pickupDate that will contain only the date portion of pickupDateTime.
* Filter the DataFrame to include only rows where fareAmount is a positive number that is less than 100.
How should you complete the code? To answer, select the appropriate options in the answer area. NOTE:
Each correct selection is worth one point.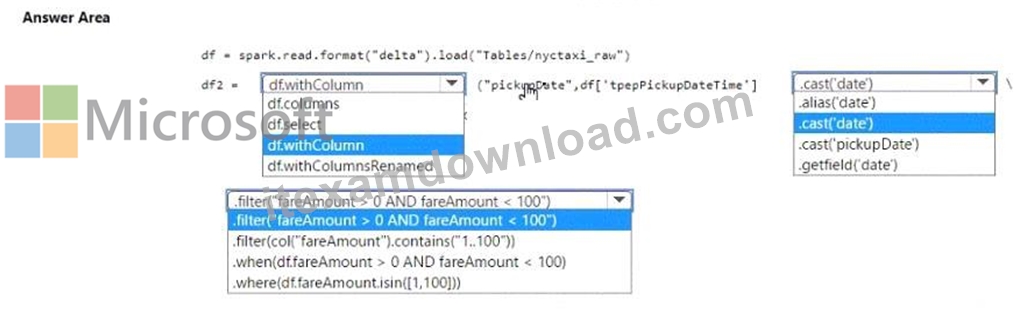
Answer:
Explanation: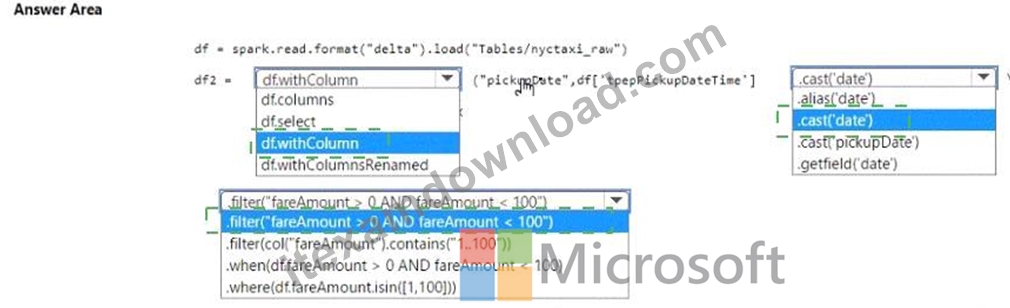
Explanation: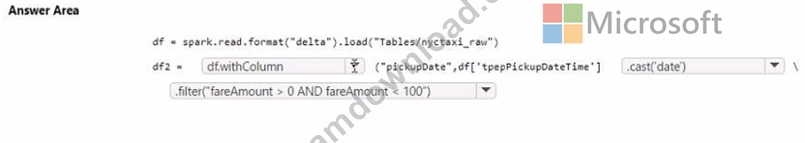
Add the pickupDate column: .withColumn("pickupDate", df["pickupDateTime"].cast("date")) Filter the DataFrame: .filter("fareAmount > 0 AND fareAmount < 100") In PySpark, you can add a new column to a DataFrame using the .withColumn method, where the first argument is the new column name and the second argument is the expression to generate the content of the new column. Here, we use the .cast("date") function to extract only the date part from a timestamp. To filter the DataFrame, you use the .filter method with a condition that selects rows where fareAmount is greater than 0 and less than 100, thus ensuring only positive values less than 100 are included.
NEW QUESTION # 73
You have a Fabric workspace named Workspace 1 that contains a dataflow named Dataflow1. Dataflow1 has a query that returns 2.000 rows. You view the query in Power Query as shown in the following exhibit.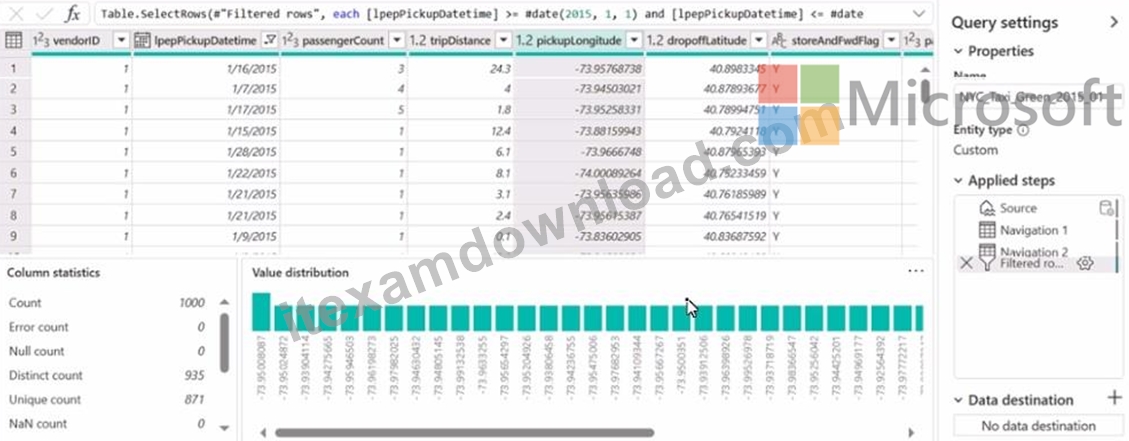
What can you identify about the pickupLongitude column?
Answer: C
Explanation:
The pickupLongitude column has duplicate values. This can be inferred because the 'Distinct count' is 935 while the 'Count' is 1000, indicating that there are repeated values within the column. References = Microsoft Power BI documentation on data profiling could provide further insights into understanding and interpreting column statistics like these.
NEW QUESTION # 74
......
Hence, if you want to sharpen your skills, and get the Implementing Analytics Solutions Using Microsoft Fabric (DP-600) certification done within the target period, it is important to get the best Implementing Analytics Solutions Using Microsoft Fabric (DP-600) exam questions. You must try DP-600 practice exam that will help you get the Microsoft DP-600 certification. ITExamDownload hires the top industry experts to draft the Implementing Analytics Solutions Using Microsoft Fabric (DP-600) exam dumps and help the candidates to clear their Implementing Analytics Solutions Using Microsoft Fabric (DP-600) exam easily. ITExamDownload plays a vital role in their journey to get the DP-600 certification.
Valid DP-600 Exam Duration: https://www.itexamdownload.com/DP-600-valid-questions.html
BTW, DOWNLOAD part of ITExamDownload DP-600 dumps from Cloud Storage: https://drive.google.com/open?id=1AjcWCvFB6EBMcbHSlqoE_BUMcoYE55Rj