Interactive Databricks-Machine-Learning-Professional Practice Exam | Latest Databricks-Machine-Learning-Professional Test Practice

P.S. Free 2026 Databricks Databricks-Machine-Learning-Professional dumps are available on Google Drive shared by Prep4away: https://drive.google.com/open?id=1kiyZnb1YVGrDSC00PR95Doohcz1Jsp-E
Revealing whether or not a man succeeded often reflect in the certificate he obtains, so it is in IT industry. Therefore there are many people wanting to take Databricks Databricks-Machine-Learning-Professional exam to prove their ability. However, want to pass Databricks Databricks-Machine-Learning-Professional Exam is not that simple. But as long as you get the right shortcut, it is easy to pass your exam. We have to commend Prep4away exam dumps that can avoid detours and save time to help you sail through the exam with no mistakes.
| Topic | Details |
|---|
| Topic 1 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 2 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 3 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 4 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 5 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 6 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| Topic 7 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 8 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
>> Interactive Databricks-Machine-Learning-Professional Practice Exam <<
Latest Databricks-Machine-Learning-Professional Test Practice & Latest Databricks-Machine-Learning-Professional Exam Book
For exam applicants Prep4away offers real Databricks Databricks-Machine-Learning-Professional exam questions. There are three formats of the Databricks Certified Machine Learning Professional (Databricks-Machine-Learning-Professional) practice material. These formats are PDF, desktop practice exam software, and web-based Databricks Certified Machine Learning Professional (Databricks-Machine-Learning-Professional) practice exam. With these questions, you can crack the Databricks Databricks-Machine-Learning-Professional certification exam and save your time and money.
Databricks Certified Machine Learning Professional Sample Questions (Q162-Q167):
NEW QUESTION # 162
A machine learning engineer wants to log and deploy a model as an MLflow pyfunc model. They have custom preprocessing that needs to be completed on feature variables prior to fitting the model or computing predictions using that model. They decide to wrap this preprocessing in a custom model class ModelWithPreprocess, where the preprocessing is performed when calling fit and when calling predict. They then log the fitted model of the ModelWithPreprocess class as a pyfunc model.
Which of the following is a benefit of this approach when loading the logged pyfunc model for downstream deployment?
- A. The pvfunc model can be used to deploy models in a parallelizable fashion
- B. The same preprocessing logic will automatically be applied when calling fit
- C. This approach has no impact when loading the logged Pvfunc model for downstream deployment
- D. There is no longer a need for pipeline-like machine learning objects
- E. The same preprocessing logic will automatically be applied when calling predict
Answer: D
NEW QUESTION # 163
Why is Apache Spark useful for machine learning training?
- A. Data visualization
- B. Distributed data processing
- C. GPU rendering
- D. Web serving
Answer: B
Explanation:
Spark processes large distributed datasets efficiently.
NEW QUESTION # 164
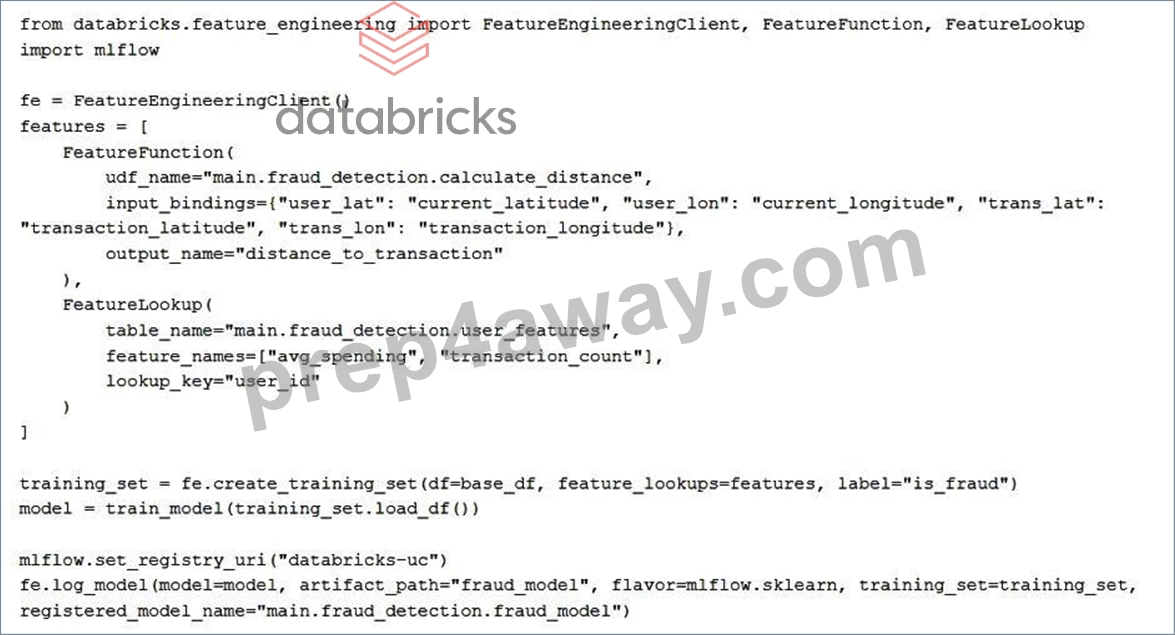
A Machine Learning Engineer is building a fraud detection model that needs to use both pre- computed features from a feature table and real-time calculated features based on user location data sent with each inference request. The engineer has created a Python UDF called calculate_distance in Unity Catalog at main.fraud_detection.calculate_distance that computes the distance between a transaction location and the user's current location. The feature table main.fraud_detection.user_features contains historical user spending patterns with primary key user_id.
The engineer has written the following code to implement this scenario:
Which benefit of this implementation approach makes it suited to the real-time fraud detection use case?
- A. The Unity Catalog registry automatically creates REST API endpoints for UDF functions used in feature computation.
- B. The FeatureLookup function avoids the need for joining the full table main.fraud_detection.user_features with training_set increasing efficiency.
- C. The FeatureFunction caches computed distance values in the online store to improve inference latency for location pairs.
- D. The model automatically performs feature lookup and computation during inference without additional serving code.
Answer: D
Explanation:
By defining both FeatureLookup and FeatureFunction objects in the training set and logging the model with the FeatureEngineeringClient, the feature logic is packaged with the model. During inference, Databricks automatically performs feature lookups from the feature table and computes the on-demand distance feature using request-time inputs, without requiring any additional custom serving or feature-joining code. This makes the approach well suited for real-time fraud detection.
NEW QUESTION # 165
A Data Scientist is developing a model training pipeline on Databricks and needs to track custom performance metrics during training. They want to log a custom evaluation score (team_score), a single hyperparameter, and a confusion matrix plot as part of their MLflow experiment. Which code snippet correctly logs all three types of information in MLflow?
- A. mlflow.log_param("max_depth", 5)
mlflow.log_metric("team_score", 0.92)
mlflow.log_artifact(open("confusion_matrix.png")) - B. mlflow.log_param("max_depth", 5)
mlflow.log_metric("team_score", 0.92)
mlflow.log_artifact("confusion_matrix.png") - C. mlflow.log_param("max_depth", "5")
mlflow.log_metric("team_score", "0.92")
mlflow.log_artifact("confusion_matrix.png") - D. mlflow.log_metric({"team_score": 0.92})
mlflow.log_param(["max_depth", 5])
mlflow.log_file("confusion_matrix.png")
Answer: B
Explanation:
This snippet correctly uses MLflow's APIs to log each item in its expected form: a single hyperparameter with log_param, a numeric custom metric with log_metric, and a file-based artifact such as a confusion matrix image by passing its file path to log_artifact. This is the standard and correct way to track parameters, metrics, and artifacts in an MLflow experiment.
NEW QUESTION # 166
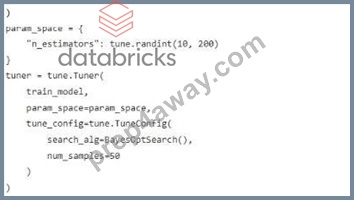
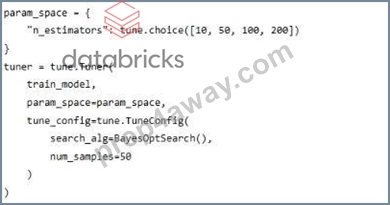
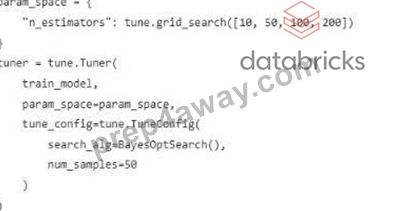
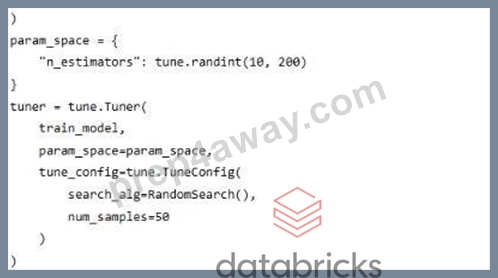
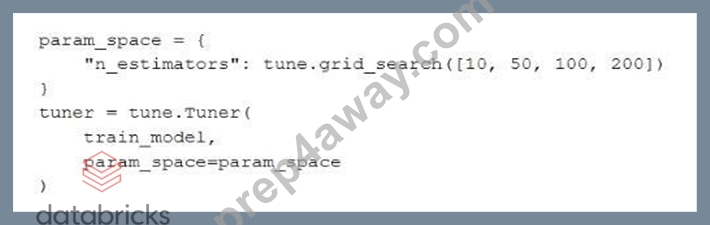
A Data Scientist has been performing hyperparameter tuning using Ray Tune with grid search.
After team discussions, they decide to switch to Bayesian optimization to more efficiently explore the parameter space.
Their current code is:
How can they implement this change?
Answer: A
Explanation:
Bayesian optimization in Ray Tune requires defining a continuous or discrete search space (such as tune.randint) and explicitly configuring a Bayesian search algorithm. Using tune.randint defines a probabilistic parameter domain, and setting search_alg to BayesOptSearch enables Bayesian optimization to efficiently explore the space based on past trial results, rather than exhaustively enumerating all values as in grid search.
NEW QUESTION # 167
......
There are great and plenty benefits after the clients pass the test. Because the knowledge that our Databricks-Machine-Learning-Professional study materials provide is conducive to enhancing the clients’ practical working abilities and stocks of knowledge, the clients will be easier to increase their wages and be promoted by their boss. Besides, they will be respected by their colleagues, friends and family members and be recognized as the elites among the industry. They will acquire more access to work abroad for further studies. So the clients must appreciate our Databricks-Machine-Learning-Professional Study Materials after they pass the test.
Latest Databricks-Machine-Learning-Professional Test Practice: https://www.prep4away.com/Databricks-certification/braindumps.Databricks-Machine-Learning-Professional.ete.file.html
- Online Databricks-Machine-Learning-Professional Training Materials 🪐 Examcollection Databricks-Machine-Learning-Professional Questions Answers 🤫 Best Databricks-Machine-Learning-Professional Vce ✈ Search on ➡ www.vceengine.com ️⬅️ for ✔ Databricks-Machine-Learning-Professional ️✔️ to obtain exam materials for free download 🥵New Databricks-Machine-Learning-Professional Exam Camp
- Databricks Databricks-Machine-Learning-Professional Exam Real and Updated Dumps are Ready for Download 📞 Search for ➠ Databricks-Machine-Learning-Professional 🠰 and download it for free on 【 www.pdfvce.com 】 website 😝Valid Databricks-Machine-Learning-Professional Exam Testking
- Databricks-Machine-Learning-Professional Exam Cram Questions 💇 Reliable Databricks-Machine-Learning-Professional Test Sample 🩺 Interactive Databricks-Machine-Learning-Professional EBook ⏫ Easily obtain free download of ➡ Databricks-Machine-Learning-Professional ️⬅️ by searching on ☀ www.dumpsmaterials.com ️☀️ 💚Practice Databricks-Machine-Learning-Professional Test Engine
- Databricks - Databricks-Machine-Learning-Professional - Latest Interactive Databricks Certified Machine Learning Professional Practice Exam 📙 { www.pdfvce.com } is best website to obtain ✔ Databricks-Machine-Learning-Professional ️✔️ for free download 🐒Online Databricks-Machine-Learning-Professional Training Materials
- Valid Databricks-Machine-Learning-Professional Exam Testking ⌚ Interactive Databricks-Machine-Learning-Professional EBook 💔 Reliable Databricks-Machine-Learning-Professional Test Sample 🔼 Easily obtain free download of ➥ Databricks-Machine-Learning-Professional 🡄 by searching on 「 www.dumpsmaterials.com 」 ‼Reliable Databricks-Machine-Learning-Professional Test Braindumps
- Valid Databricks-Machine-Learning-Professional Exam Testking ⬅ Databricks-Machine-Learning-Professional Practice Test Pdf 🦼 Examcollection Databricks-Machine-Learning-Professional Questions Answers 🐓 Immediately open ⏩ www.pdfvce.com ⏪ and search for ➽ Databricks-Machine-Learning-Professional 🢪 to obtain a free download 🛢Databricks-Machine-Learning-Professional Valid Test Format
- Top Interactive Databricks-Machine-Learning-Professional Practice Exam 100% Pass | Valid Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional 100% Pass 🥦 Copy URL “ www.practicevce.com ” open and search for ☀ Databricks-Machine-Learning-Professional ️☀️ to download for free 🚧Reliable Databricks-Machine-Learning-Professional Test Braindumps
- Top Interactive Databricks-Machine-Learning-Professional Practice Exam 100% Pass | Valid Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional 100% Pass 🍿 Download ⏩ Databricks-Machine-Learning-Professional ⏪ for free by simply entering 「 www.pdfvce.com 」 website 👯Practice Databricks-Machine-Learning-Professional Test Engine
- Top Interactive Databricks-Machine-Learning-Professional Practice Exam 100% Pass | Valid Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional 100% Pass 🕊 The page for free download of 【 Databricks-Machine-Learning-Professional 】 on ⮆ www.examcollectionpass.com ⮄ will open immediately 🌕Latest Databricks-Machine-Learning-Professional Training
- Test Databricks-Machine-Learning-Professional Centres 🧬 Latest Databricks-Machine-Learning-Professional Training ✌ Databricks-Machine-Learning-Professional Latest Dumps Book ⌨ Go to website ⏩ www.pdfvce.com ⏪ open and search for “ Databricks-Machine-Learning-Professional ” to download for free 🐁Databricks-Machine-Learning-Professional Valid Test Format
- Databricks Databricks-Machine-Learning-Professional Questions 2026 - All Subjects Covered 🚟 Search on 「 www.testkingpass.com 」 for ▷ Databricks-Machine-Learning-Professional ◁ to obtain exam materials for free download 🍹Databricks-Machine-Learning-Professional Practice Test Pdf
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BTW, DOWNLOAD part of Prep4away Databricks-Machine-Learning-Professional dumps from Cloud Storage: https://drive.google.com/open?id=1kiyZnb1YVGrDSC00PR95Doohcz1Jsp-E